Select-to-Act: Hierarchical Reinforcement Learning via Adaptive Language Guidance
Hanping Zhang, Adam Koziak, Yi Guo
· Lecture notes in computer sc... · 0 citations
Category
2,335 papers
This paper presents the Adaptive Biohybrid Neural Interface (ABNI) as a computational feasibility framework: a set of independently verifiable mathematical and computational sub-models for the major subsystems such an interface would require, rather than an integrated, biologically validated device. Its core contributi...
Abstract Controlling turbulent dynamics remains a major challenge because their chaotic, multiscale nature strongly affects many fluid systems. Here, we present REACT, an autonomous reinforcement learning framework for real-time, state-dependent control of turbulent wake dynamics in a wind tunnel. Deployed on an Ahmed-...
Reach audiences
Advertise in front of researchers, engineers, and readers.
A large literature builds physical structure into learned dynamics on the premise that models respecting the underlying physics predict better. This work tests that premise using exact polynomial invariants recovered from trajectories and canonicalised as reduced Gröbner bases over ℚ. On Acrobot, exactness provides lit...
A large literature builds physical structure into learned dynamics on the premise that models respecting the underlying physics predict better. This work tests that premise using exact polynomial invariants recovered from trajectories and canonicalised as reduced Gröbner bases over ℚ. On Acrobot, exactness provides lit...
Abstract Despite the growing application of large language models (LLMs) to theoretical physics, there has been little academic exploration of how domain-specific physics reasoning ability develops during training. To investigate this, we perform the first academic comparison of reinforcement learning and supervised fi...
The integration of reinforcement learning (RL) into the optimization of multi-agent collaboration for Large Language Models (LLMs) is an important combination of two advanced areas, Multi-Agent Systems (MAS) and LLMs. This paper thoroughly examines the main approaches, evaluation standards, recent progress and existing...
Artificial intelligence (AI) has become a significant force in the field of quantitative trading because it extends traditional rule-based systems to areas such as adaptive prediction, dynamic configuration and automated execution. At the same time, the widespread adoption of machine learning, reinforcement learning, a...
The research findings show that RL has gradually expanded from simply improving the accuracy of the final answer to optimizing queries, multi-round search, process decision-making and trustworthy screening, providing new ideas for enhancing the active retrieval ability of RAG and improving the credibility of informatio...
This paper investigates the development path of large language model preference alignment techniques, focusing on the training mechanism of Reinforcement Learning from Human Feedback and its three-stage process, including supervised fine-tuning, reward model training, and PPO-based policy optimization.
A new machine-learning approach broke records for weather forecasting for an important time frame in emergency planning.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
Learn more about our approach to safety and security for Gemini 4 Argon.
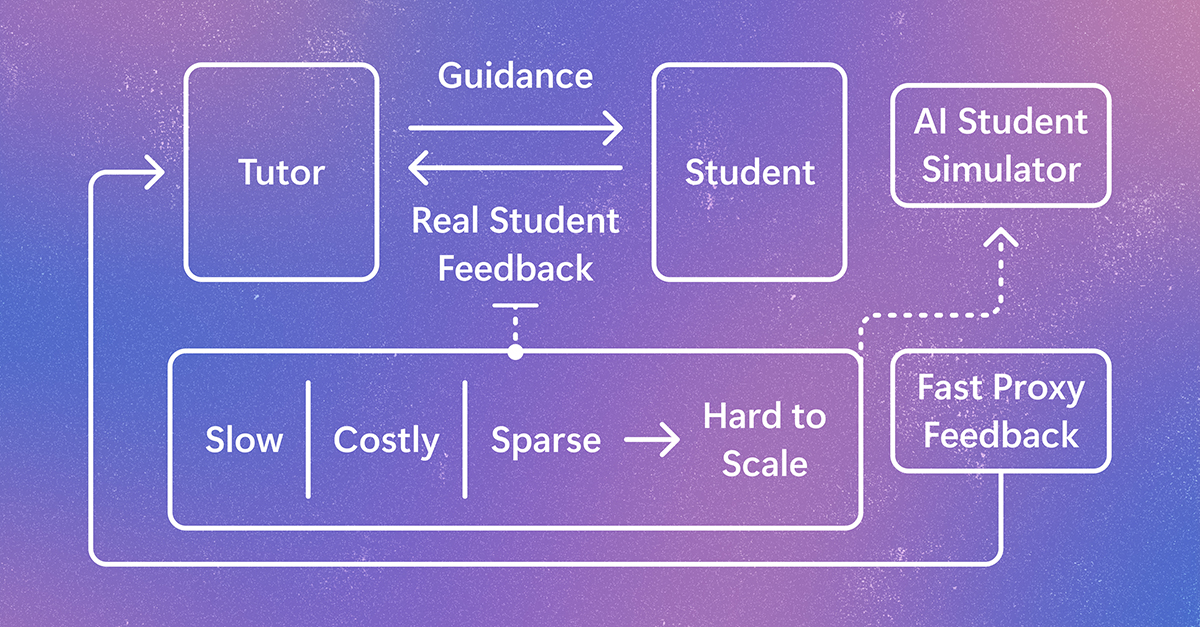
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.