Skip to content

Advances in Reinforcement Learning for Retrieval-Augmented Generation in Large Language Model

Sep 2026 · Applied and Computational Engineering · 0 citations
Topic Modeling

TL;DR

The research findings show that RL has gradually expanded from simply improving the accuracy of the final answer to optimizing queries, multi-round search, process decision-making and trustworthy screening, providing new ideas for enhancing the active retrieval ability of RAG and improving the credibility of information.


Abstract

Retrieval-augmented generation (RAG) enhances large language models (LLMs) by incorporating external information, but traditional fixed retrieval processes struggle to adapt to complex task requirements. In recent years, reinforcement learning (RL) has been increasingly applied to train LLMs to autonomously invoke search tools, driving RAG to evolve from the passive information acquisition of a fixed pipeline to a trustworthy retrieval system with autonomous decision-making capabilities. This paper reviews the representative studies on the combination of LLMs, RAG and RL in recent years. It focuses on analyzing the role of RL in dynamic retrieval, process rewards, query optimization, etc., and compares the connections and evolutionary relationships among different methods. The research findings show that RL has gradually expanded from simply improving the accuracy of the final answer to optimizing queries, multi-round search, process decision-making and trustworthy screening, providing new ideas for enhancing the active retrieval ability of RAG and improving the credibility of information.

Read PDF

Similar papers

Open access Aug 2026

A Framework for Adaptive Knowledge-Augmented Mizo Large Language Models Using Retrieval-Augmented Generation and Continual Learning

This paper presents an adaptive knowledge-augmented framework for Mizo Large Language Models by combining Retrieval-Augmented Generation (RAG) with continual learning that harnesses semantic retrieval with dense embeddings and FAISS indexing, adaptive evidence re-ranking, parameter-efficient fine-tuning, and incrementa...

Vanlalropuia Ralte, Abhisake Sinha · 0 citations
#reinforcement learning Book Open access Aug 2026

NaviRAG: Learning to Navigate Knowledge Graphs for Retrieval-Augmented Generation

Retrieval-Augmented Generation (RAG) has become a fundamental paradigm for enhancing Large Language Models (LLMs) with external knowledge. However, while recent structure-augmented approaches organize documents into graphs to improve information access, their retrieval strategies remain largely static, relying on simil...

Jinghong Lei, Wang Kun, Zhigang Chen et al. · 0 citations
Review Open access Aug 2026

Reinforcement Learning in the Era of Large Language Models: Challenges and Opportunities

A systematic literature review on how RL are adapted and scaled as a fundamental post-training tools and how innovations in the RL pipeline enhance the domain-specific LLMs is conducted.

Qianyue Hao, Lin Chen, Xiao-Qian Qi et al. · 1 citation
#artificial intelligence Preprint Aug 2026

Towards Reliable, Generalizable, and Specific In-Context Knowledge Editing via Multi-Objective Reinforcement Learning

Multi-Objective In-context Knowledge Editing (MO-IKE), a multi-objective RL algorithm that formulates prompt construction for in-context knowledge editing as a Constrained Markov Decision Process, enabling more balanced and globally coherent prompt construction.

Xu-Zhong Wang, Maiqi Jiang, Tejal Nair et al. · 1 citation
Book Open access Aug 2026

Retrieval-Augmented Generation (RAG)— From Modular to Agentic Systems

This tutorial provides an in-depth treatment of modern RAG based on AI-facilitated systematic analysis of ~2000 recent papers (2020--2026) and traces the RAG pipeline from its modular foundations through graph-enhanced reasoning to the latest RL-driven agentic architectures, covering each stage.

Xin Dong, Sanat Sharma, Kai Sun et al. · 0 citations

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 12, 2026

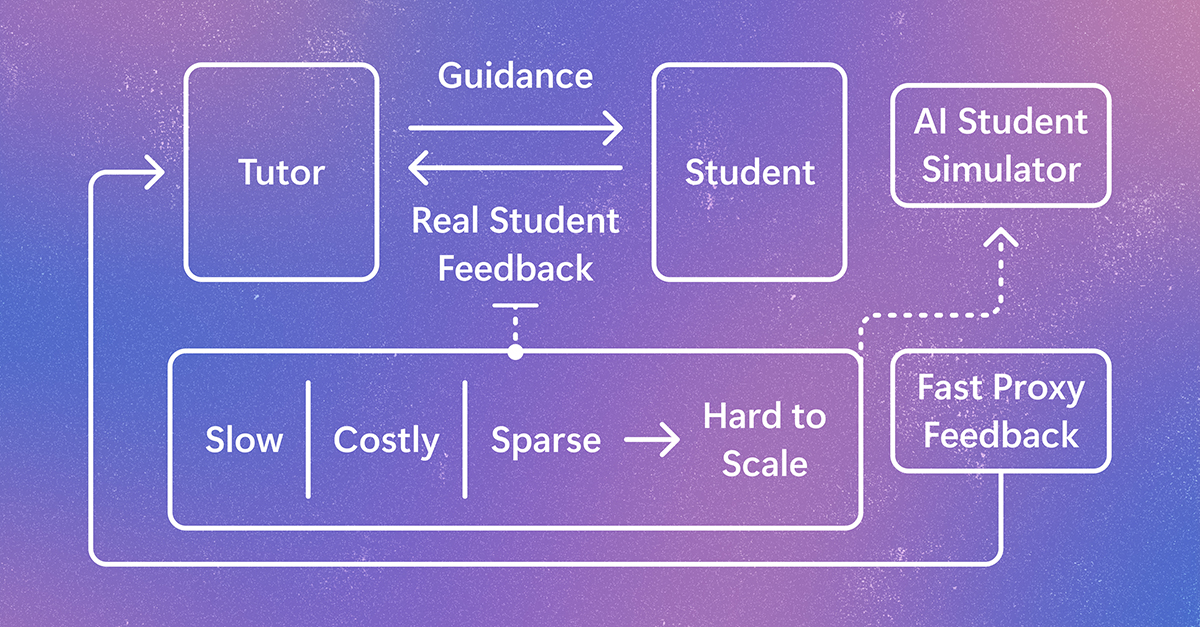
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.