Large Language Models (LLMs) have demonstrated remarkable fluency across many tasks but remain limited by their static, parameter-bound knowledge and their susceptibility to hallucinating information. Retrieval-Augmented Generation (RAG) addresses these issues by incorporating external retrieval into the generation process, grounding model outputs in verifiable and up-to-date sources. While prior surveys primarily focus on core RAG architectures and standard pipelines, recent research explores broader challenges and capabilities that extend beyond these foundational designs. This survey provides a consolidated and structured examination of contemporary RAG developments, organizing the field into a four-axis taxonomy: improving retrieval efficiency, strengthening robustness and security, supporting user-driven and interactive workflows, and enabling multi-step or complex reasoning. We formalize key components of the RAG framework and review methods spanning dense and sparse retrieval, fusion strategies, embedding optimizations, and reinforcement-learning–based retrieval policies, highlighting how these advances influence practical deployment and system design. We also synthesize evaluation practices, domain-specific applications, and architectural variants such as Naive, Advanced, and Modular RAG. Finally, we outline persistent challenges related to retrieval quality, reliability, domain adaptation, scalability, and explainability, and identify opportunities for building RAG systems that are more reliable, adaptable, and transparent.
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.
M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al.· e-Informatica Software Engin...· 157 citations· ⚡17
This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.
Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al.· Empirical Software Engineeri...· 127 citations· ⚡15
The comparison of adopter and non-adopter sample reveals three potential adoption inhibitor, security, data privacy, and portability, which underlines the importance of the technical and security perspectives for research investigating the adoption of technology.
Nattakarn Phaphoom, Xiaofeng Wang, S. Samuel et al.· Journal of Systems and Softw...· 111 citations· ⚡8
What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduAug 18, 2026
A new method for surgically removing training examples from a model reveals that as datasets grow, the link between what a model learns and what it produces dissolves.
Microsoft Research Blog· microsoft.comJul 30, 2026
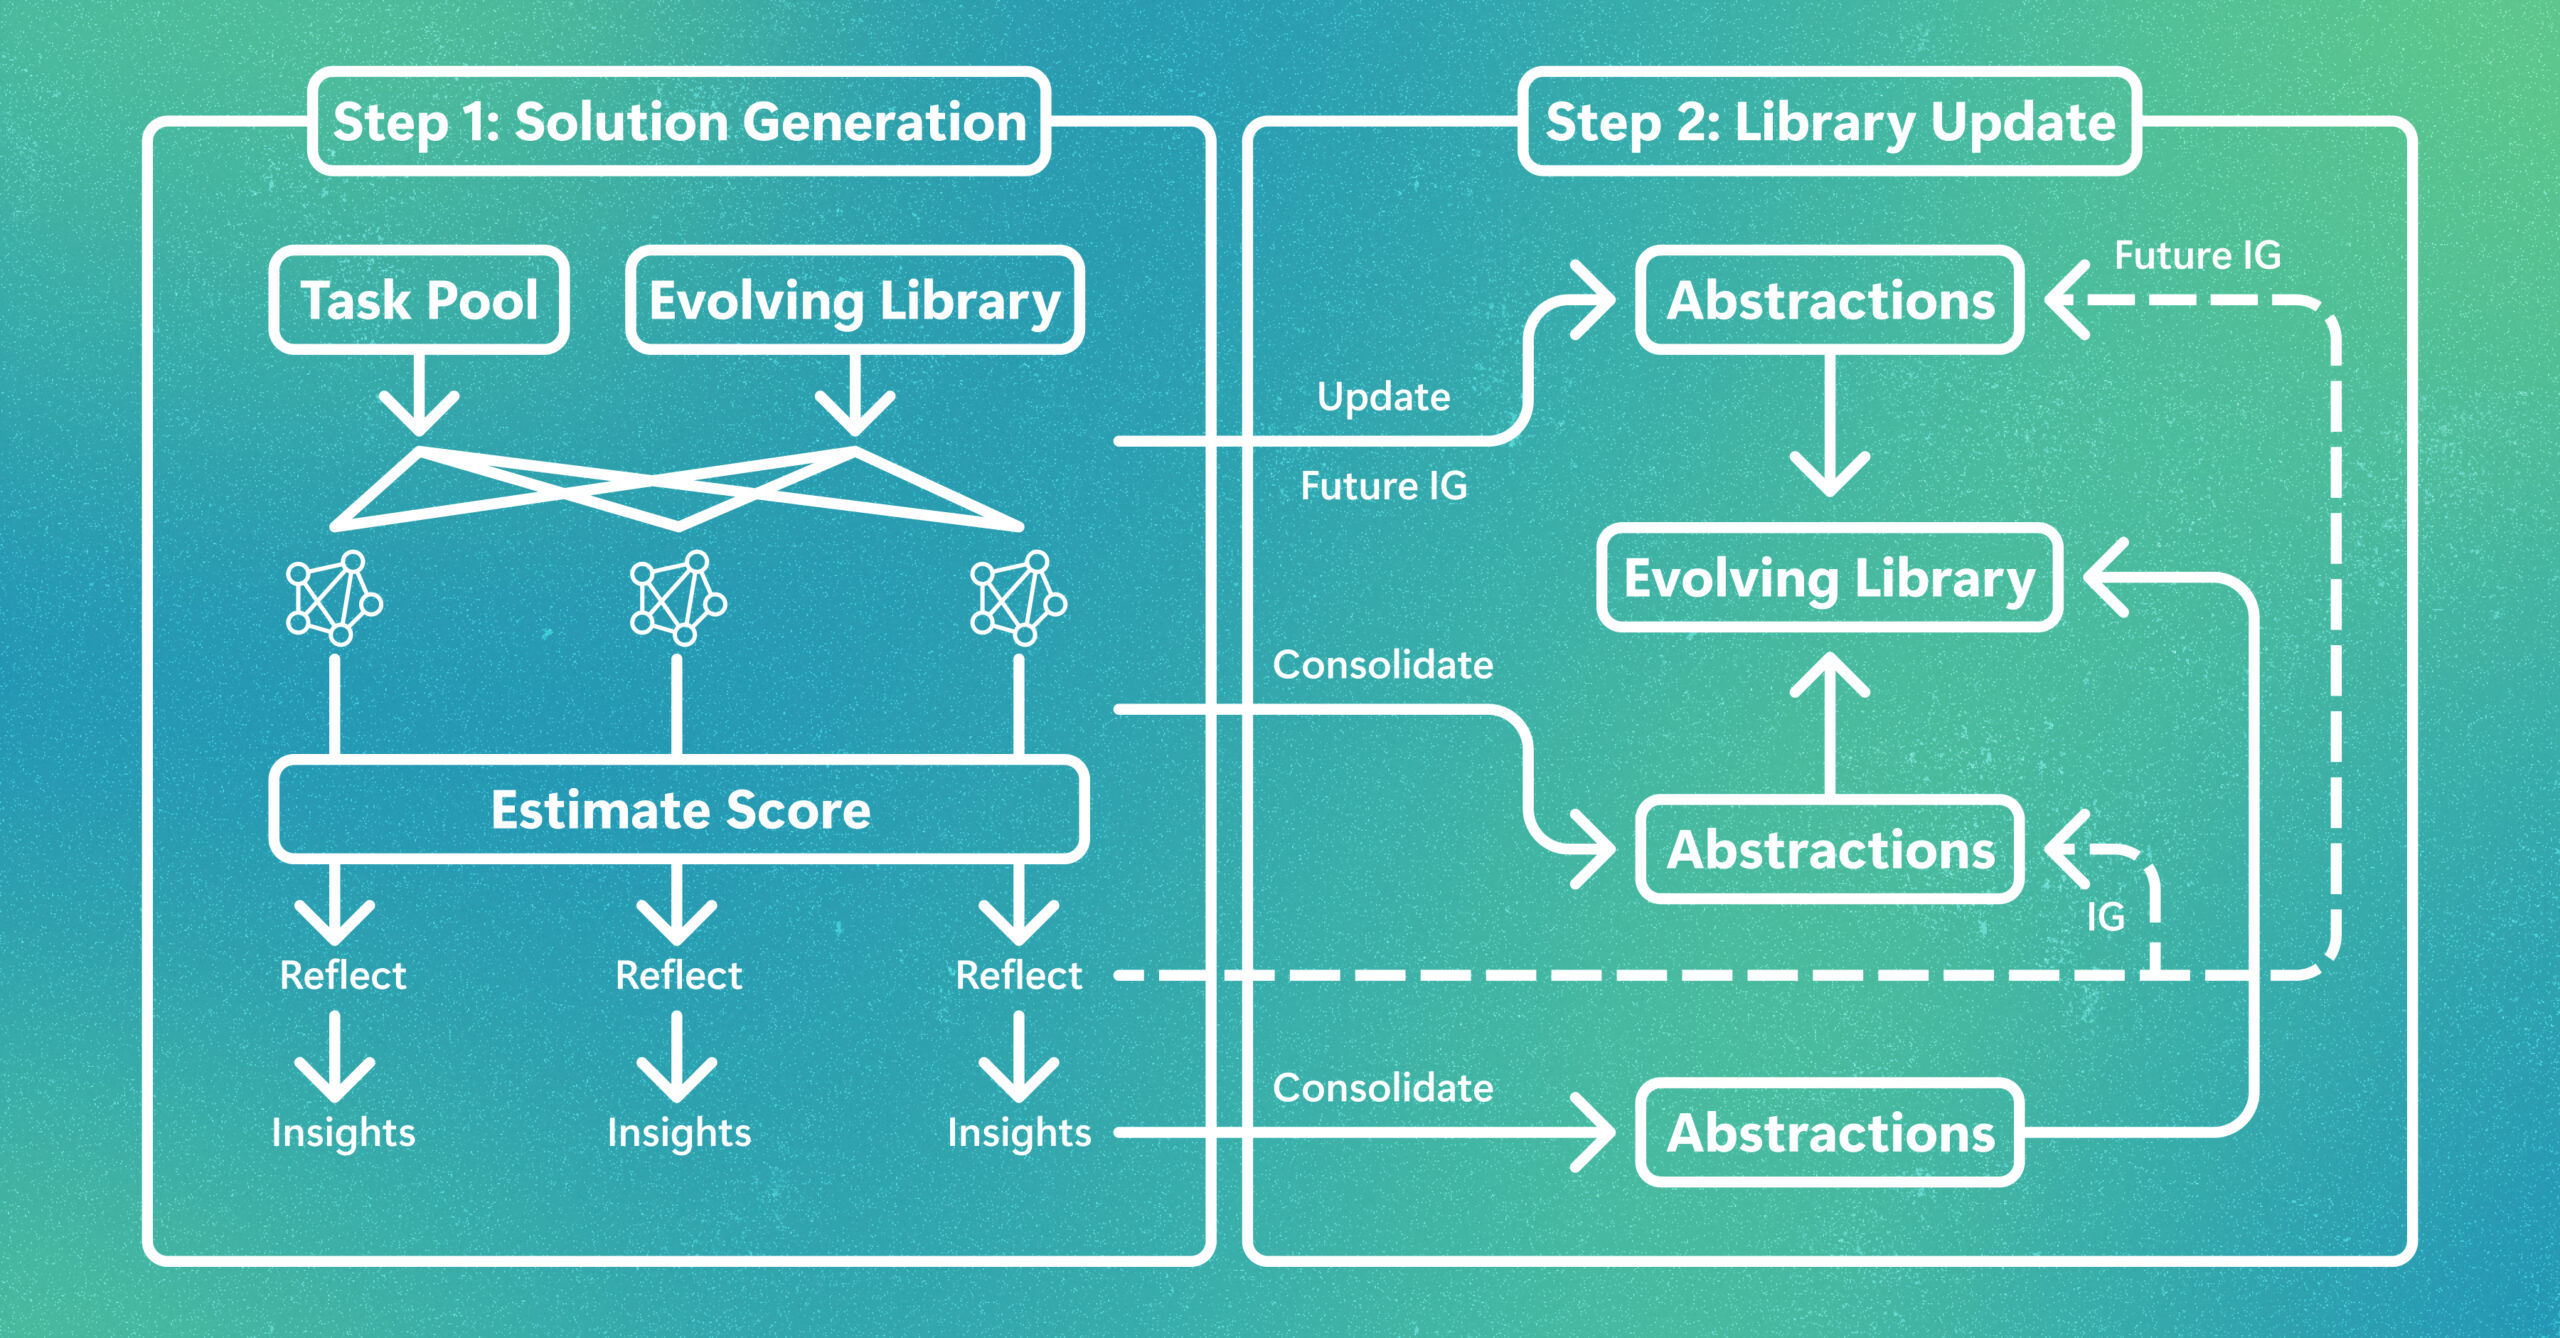
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduMay 20, 2026