Aug 2026· Data mining and knowledge discovery· Vol 40· 0 citations· 51 references
Advanced Graph Neural Networks
TL;DR
This study introduces a novel memory-augmented self-learning framework that extracts and provides diverse learning sources for adaptive knowledge distillation from the student model itself, resulting in a 2.5-6% increase in accuracy across various benchmark datasets compared to current GNN training and self-distillation methods.
This work proposes a student design based on simple, homogeneous blocks mirroring those of the teacher, distilling knowledge between corresponding blocks, showing that intermediate block-wise distillation, guided appropriately, is key to building compact data-efficient models without sacrificing accuracy.
Irene Trigueros-Lorca, Leonardo Concepción, Christian Wagner et al.· 0 citations
A multimodal model that combines two complementary ideas: a self-supervised method that enables a GNN encoder pretrained on one dataset to operate directly on another dataset with a different node-feature dimensionality, without rebuilding the model or realigning the data is investigated.
Fumiaki Kimino, Ryoma Sato Sokendai, National Institute of Informatics· 1 citation
Continual learning requires a model to retain knowledge of old tasks while sequentially learning new tasks, but standard neural networks typically suffer from catastrophic forgetting in this setting. To address this challenge, a new method is proposed based on a learnable knowledge transfer network. Specifically, a tra...
Han Ju· International Conference on...· 0 citations
This paper proposes a novel lightweight plastic-memory framework specifically designed for few-shot incremental learning on graphs, featuring an innovative evolving micro-clustering structure that dynamically updates representations of class prototypes, sub-prototypes, and their interaction weights.
Zi-Han Mei, Zhi-Li Qin, Tongze Zhang et al.· 0 citations
Curriculum Learning (CL) orders training samples from easy to hard, but its application to graphs remains limited: existing methods rely on architecture-specific signals such as training loss, or on hand-crafted structural heuristics that do not transfer across datasets. Standard Graph Neural Network (GNN) training sid...
Dulara Madhusanka, Sanka Mohottala, A. Lindamulage et al.· Moratuwa Engineering Researc...· 0 citations
Knowledge distillation aims to improve the performance of lightweight student models by transferring knowledge from larger and more powerful teacher models. However, a substantial size gap between teacher and student models often impedes effective knowledge transfer. Most existing approaches adopt a static, one-way tea...
Da-Wen Jiang, Zhi-Shu Shen, Ze-Yu Liu et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
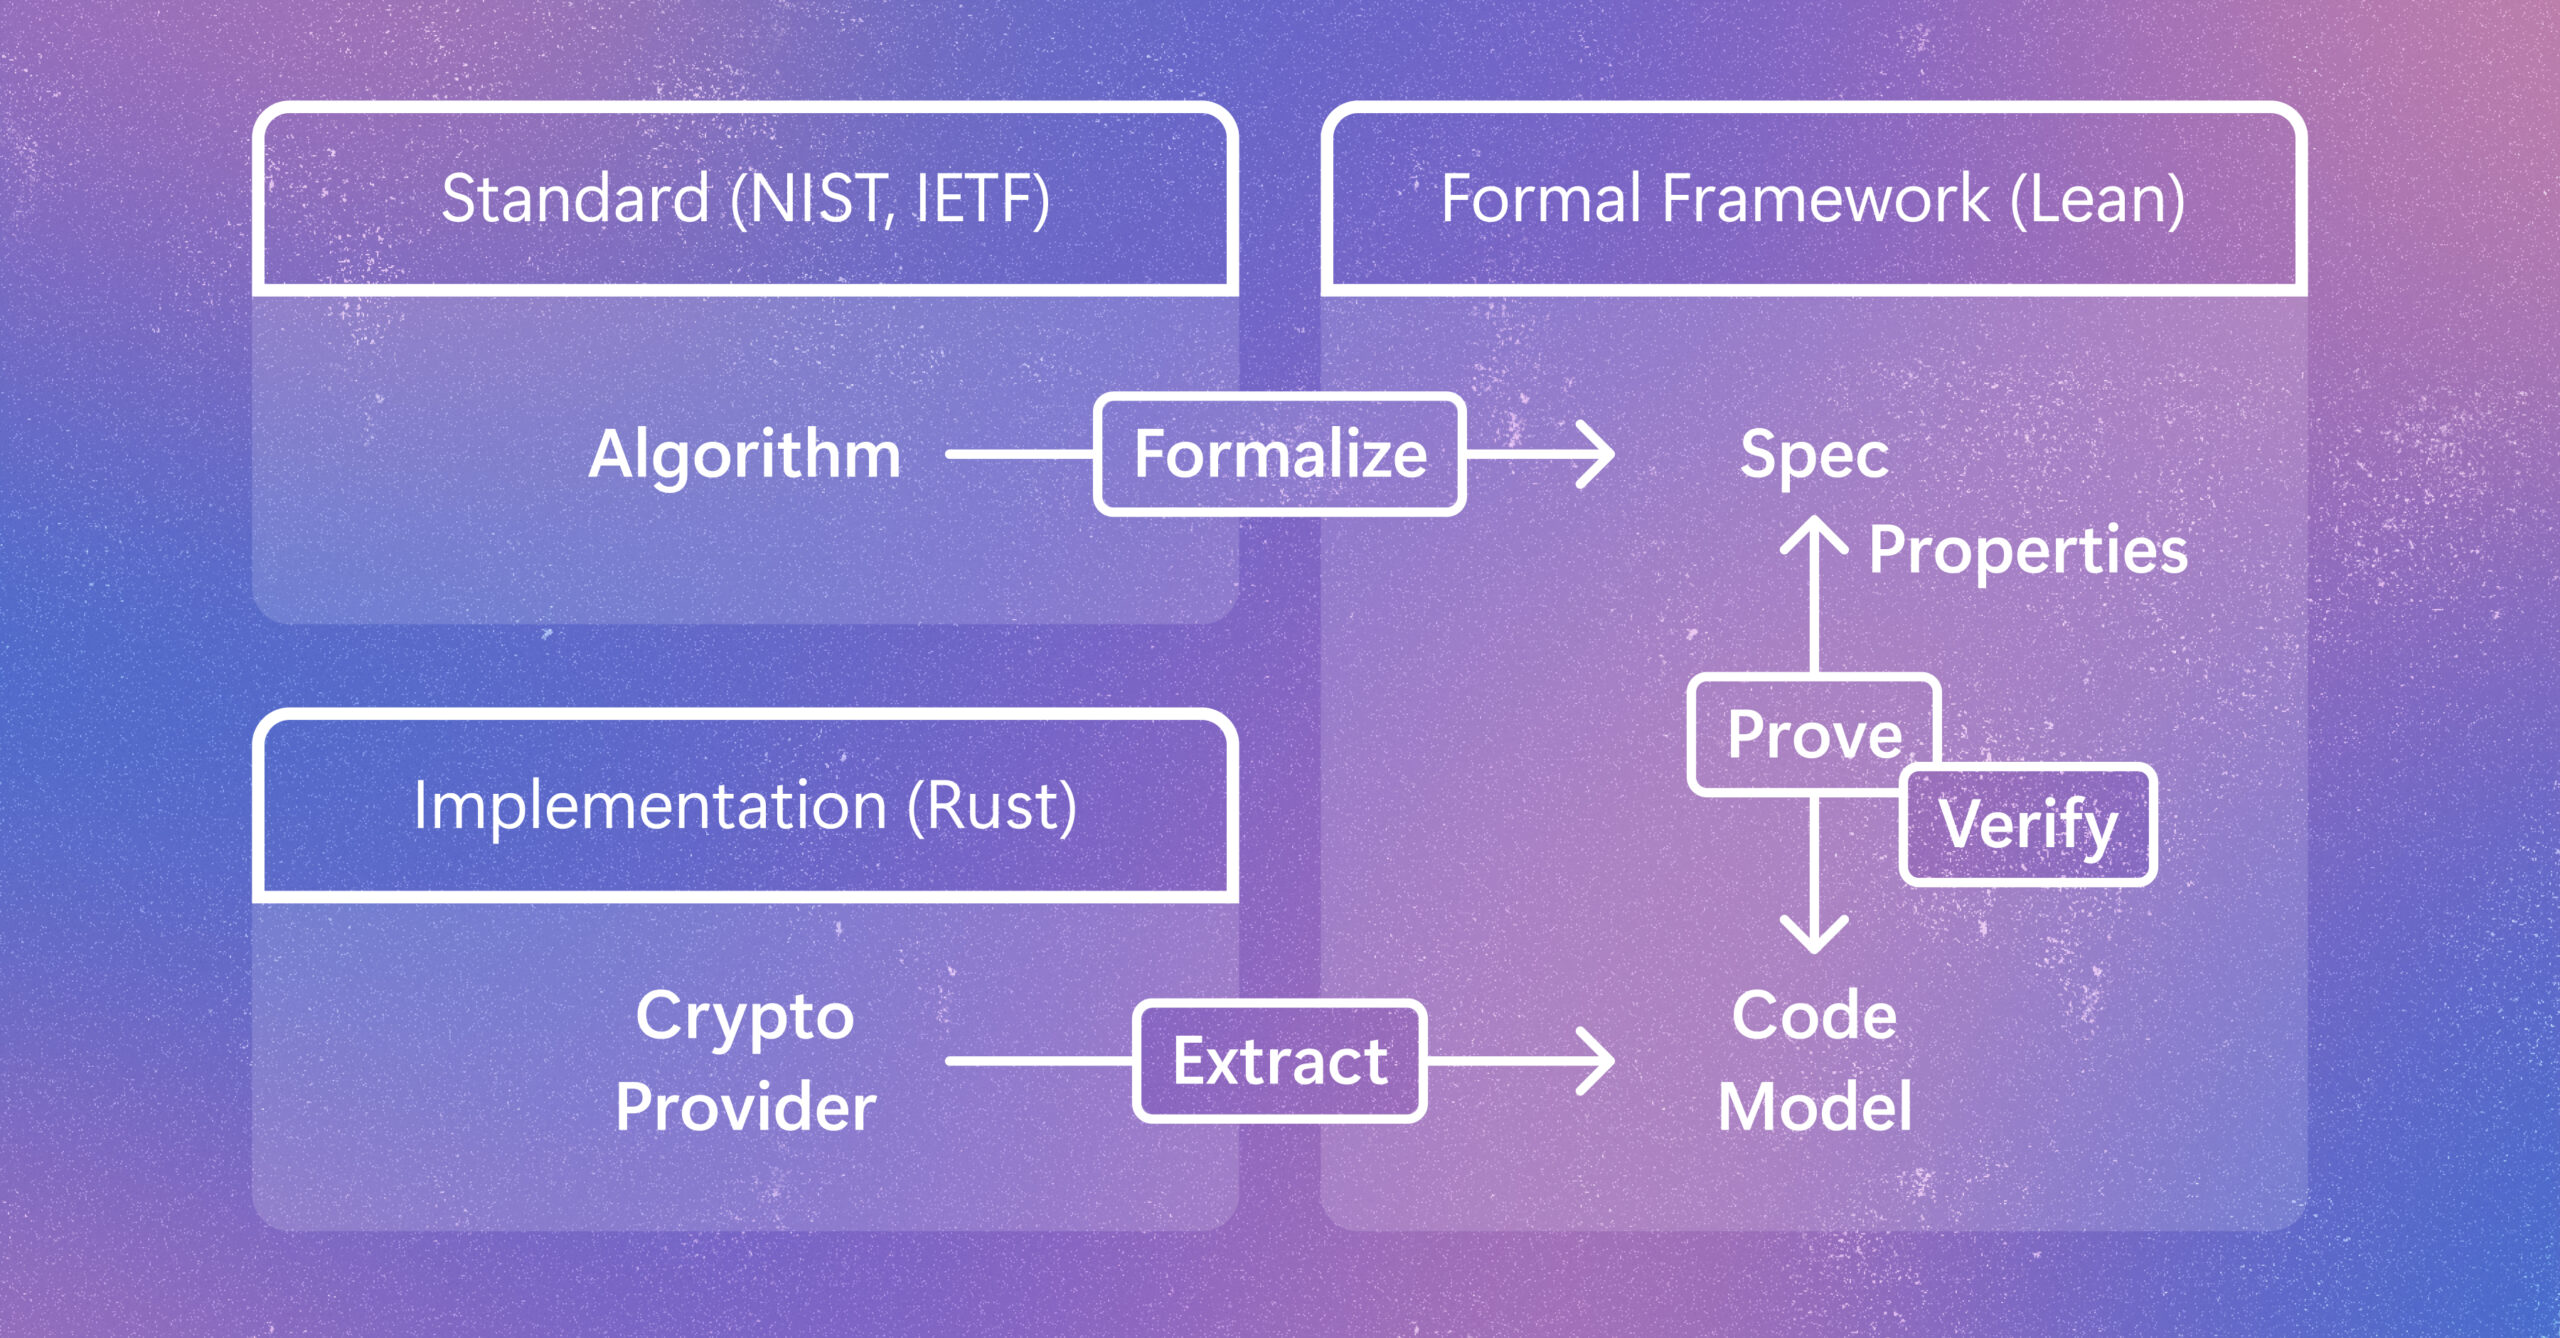
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.