Sep 2026· IEEE Journal of Solid-State Circuits· Vol 61, pp. 5125-5141· 0 citations· 64 references
Abstract
We present PROTEUS, an 18 mm2 programmable general-purpose digital compute-in-memory (GP-DCIM) accelerator integrating 4 Mb resistive random access memory (RRAM) and 2.6 Mb tensor static random access memory (SRAM) with a 32-bit hierarchical DCIM instruction set architecture (ISA). PROTEUS features fine-grained 1-D matrix tiling and a reconfigurable DCIM datapath/pipeline for near-100% memory utilization, supporting INT8/INT16/FP8/FP16 DCIM computations. PROTEUS unifies SRAM/RRAM dataflows and embeds nonvolatile micro-programs in RRAM to enable rapid switching among prestored kernels without incurring off-chip instruction feeds or RRAM rewrites. Fabricated in 40 nm ultra-low power (ULP) CMOS with foundry RRAM, PROTEUS delivers 702 GOPS throughput, 6.4 TOPS/W energy efficiency, and 0.039 TOPS/mm2 compute density. It is validated on ResNet-20, BERT-Tiny, MobileViT, GraphSAGE, and Vision Mamba, demonstrating versatility across CNN, Transformer, hybrid CNN-Transformer, graph neural network (GNN), and state-space model (SSM) workloads.
The rise in edge computing, and domain-specific workloads, necessitates the development of hardware acceleration with increased flexibility and lower latency that will be tightly coupled to open-source processor cores. In this paper, we explore the design and bare-metal implementation of a RISC-V SoC comprising a PicoR...
P.anuradha, Vulapala Tejashwi, Meenugu Venkateshwarlu et al.· 2026 7th International Confe...· 0 citations
Compute-in-Memory (CIM) based on resistive random access memory (RRAM) offers significant advantages in energy efficiency and parallelism, making it a promising solution for accelerating neural networks. However, the computational accuracy, energy efficiency, and flexibility of current CIM chips are still challenged by...
H. Ding, Yun-Fan Yang, Zongwei Wang et al.· IEEE Transactions on Circuit...· 0 citations
A systolic array-based accelerator prototype implemented on the Zynq-7000 SoC integrated directly into PyTorch, enabling dense linear algebra to be delegated to the FPGA chip while Cortex-A9 continues executing the software stack uninterrupted.
Omar Hernandez-Yañez, A. Juárez-Lora, J. Y. Montiel-Pérez et al.· Electronics· 0 citations
Three fundamental design principles are revealed that provide design-space guidance for architects designing the next generation of memory-accelerated LLM systems.
Corey Lammie, Hadjer Benmeziane, W. Simon et al.· 0 citations
This paper presents a novel memory controller architecture and a RISC-V instruction set extension to optimize MLC NVM write operations by balancing speed and retention time, and introduces a fast-store instruction in RISC-V to increasing write performance while addressing retention limitations.
Mina Ibrahim, M. Shokry, Lokesh Siddhu et al.· Journal of Circuits, Systems...· 0 citations
This work proposes a hybrid SRAM-TCAM memory-centric deep neural network (DNN) architecture that integrates three tightly coupled subsystems and provides O(1) parallel associative inference.
Vandana Thakur, V. More, Abhishek Bhatt· Journal of King Saud Univers...· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comJul 13, 2026
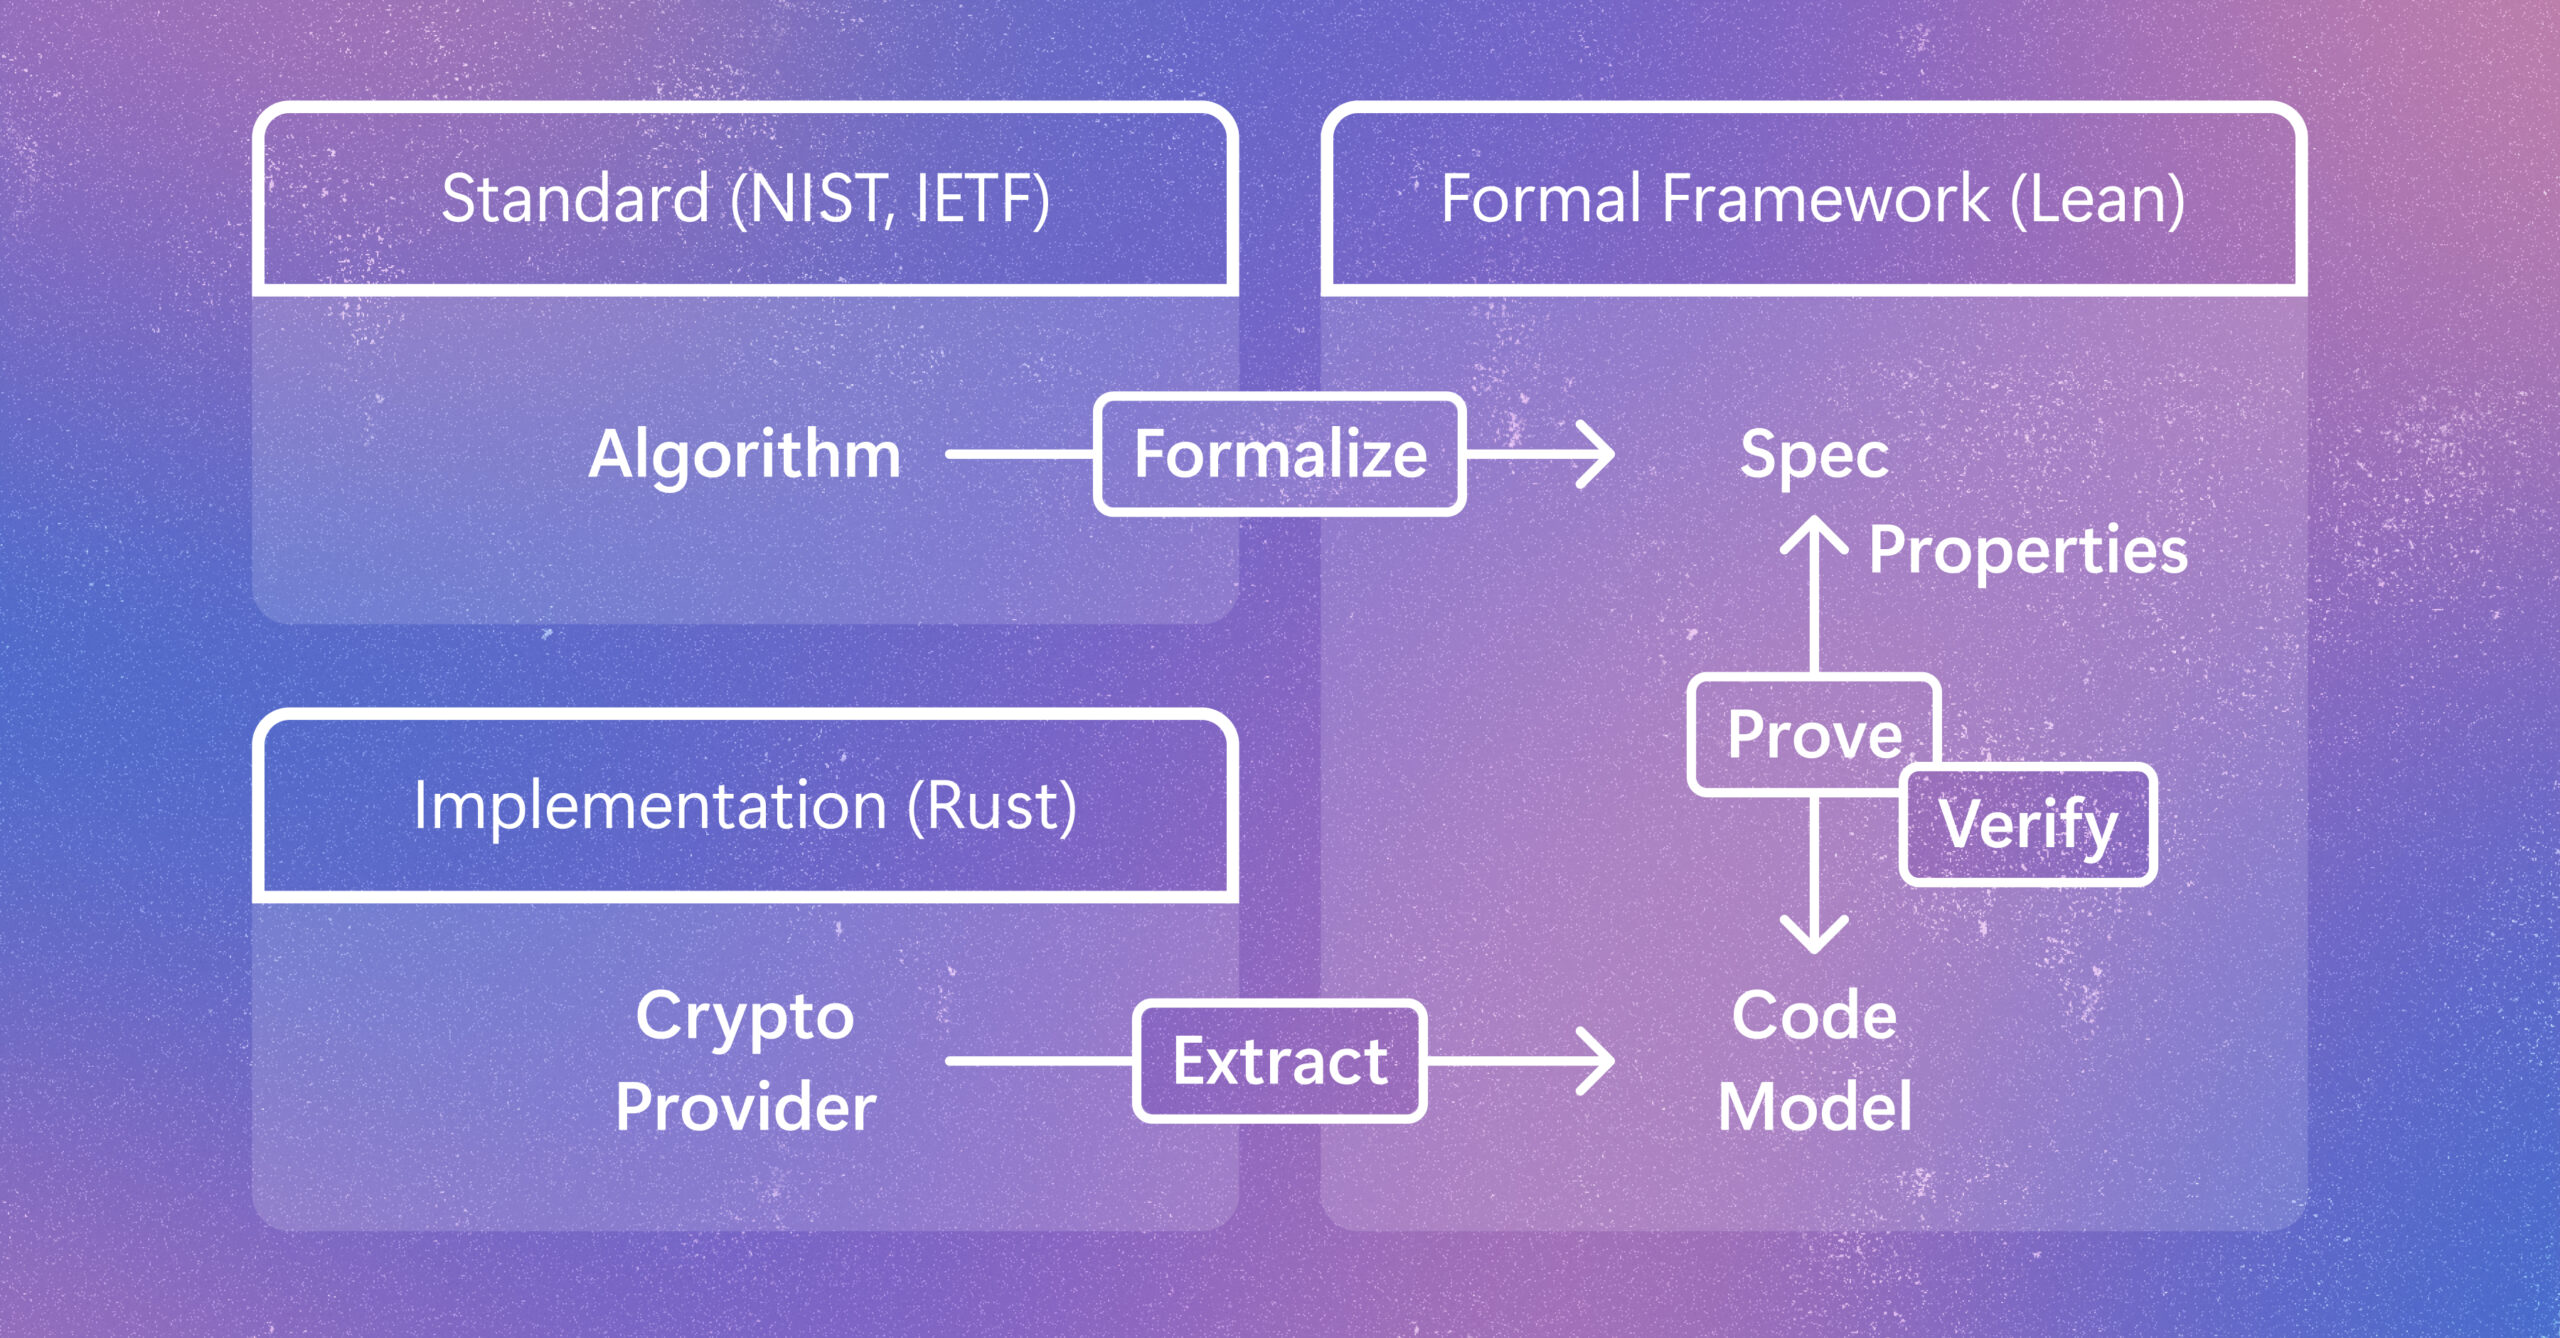
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
MIT News · Artificial Intelligence· news.mit.eduOct 15, 2026
A new computational approach reveals how cells communicate to assemble into tissues. This could accelerate stem cell engineering, improve disease models, and inform therapies.
Microsoft Research Blog· microsoft.comOct 15, 2026
Zero-knowledge proofs can verify computing results without rerunning workloads or exposing sensitive data. Magnetar helps bring them into the mainstream with support for standard programming languages, major speed gains, and quantum-resistant security. The post Proof-based general-purpose computing with Magnetar appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.