A data-driven reinforcement learning framework for optimal balance control and stabilization of a rotary inverted pendulum
Jim George, Madhav P S, Arni Prem et al.
· Systems Science & Control En... · 0 citations
Category
2,335 papers
We report an experimental implementation of deep reinforcement learning (RL) for optimizing the loading stage of a ⁶Li magneto-optical trap (MOT) in a high-dimensional continuous control space. An off-policy actor-critic agent observes in-situ fluorescence images at 111 ms intervals and updates seven experimental param...
The results show that pipelined fixed-point FPGA architectures are a good solution to speed up the reinforcement learning process in resource-limited embedded systems.
Reach audiences
Advertise in front of researchers, engineers, and readers.
Farmland in the hilly and mountainous regions of southern China is characterized by complex terrain and highly variable operating loads. Conventional diesel-powered tracked harvesters are constrained by high crop losses, excessive impurity rates, frequent blockages, and low overall energy-use efficiency. Distributed el...
H3C-BEACON is presented, a unified hierarchical framework for coordination and control in cooperative MARL that jointly integrates communication, probabilistic belief inference, adaptive coalition formation, and policy stabilisation and significantly improves reproducibility across random initialisations.
Optimizing a molecular generator against a single activity-model estimate can reward structures for which that estimate is unreliable. We extended our published ChemBERTa–reinforcement-learning (RL) workflow for human epidermal growth factor receptor (EGFR) with scaffold-separated activity modeling, empirically calibra...
This project investigates the informatics architecture required to realize a continuous Learning Health System (LHS) in intensive care using offline reinforcement learning. Using mixed shock hemodynamic management as a focal use case, this work aligns organizational needs, algorithmic constraints, and end-user workflow...
A multi-agent meta-reinforcement learning framework is developed using Contrastive Predictive Coding for traffic state representation that maintained emergency vehicle priority while keeping the effect on regular traffic within a comparatively limited range under the evaluated emergency conditions.
Against the prevalent social norm of treating conversational artificial intelligence with politeness, this paper explores the cognitive risks brought by human habitual politeness toward chatbots such as ChatGPT. Drawing on historical analogies, virtue ethics and the mechanism of Reinforcement Learning from Human Feedba...
A new machine-learning approach broke records for weather forecasting for an important time frame in emergency planning.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
Learn more about our approach to safety and security for Gemini 4 Argon.
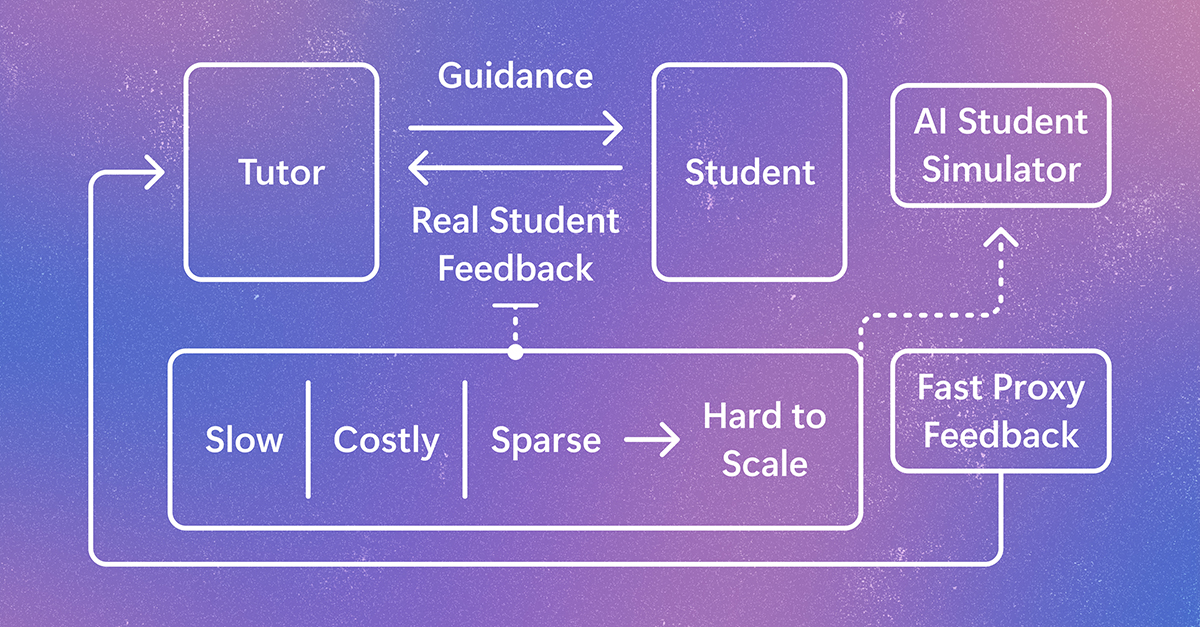
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.