This work proposes a geometry-informed distributed acoustic scene understanding framework that leverages distributed microphones and uses an audio spectrogram transformer and a topology-aware graph neural network to fuse spatio-temporal acoustic features.
Abstract
Acoustic scene understanding in multi-room environments is a difficult task. Most existing systems use a single centralized microphone array, and they often fail because walls and doors block sound signals. To address this challenge, we propose a geometry-informed distributed acoustic scene understanding framework. Our system leverages distributed microphones and uses an audio spectrogram transformer and a topology-aware graph neural network to fuse spatio-temporal acoustic features. Then, these features are decoded into discrete semantic triplets. Finally, a frozen large language model combines these symbolic observations with the environmental geometry. This allows the system to perform spatial understanding, infer plausible missing transitions, and generate a physically consistent narrative of the scene. Experiments on a custom multi-room simulator demonstrate that our framework outperforms centralized baselines and improves spatial consistency under simulated occlusion.
Embodied, ego-centric intelligence fundamentally requires the ability to comprehend spatial audio within complex environments. While large audio-language models excel at mono-channel reasoning, they lack spatial awareness, discarding critical spatial cues that enable sound localization and that can improve the disentan...
Sonal Kumar, Sinan Hersek, Artem Dementyev et al.· 0 citations
Text-conditioned general audio generation is moving beyond isolated speech, music, and sound-effect synthesis toward a single model that can compose them into controllable, coherent audio scenes. This unified setting is particularly challenging: heterogeneous components impose conflicting structural requirements on a s...
Yun-Rui Cai, Xu Li, Yucheng Zhou et al.· 0 citations
This study proposes sound scene-to-description (SS2D), a method that trains an audio encoder to map complex sound patterns into the semantic space of a large language model, which allows the model to generate coherent and detailed descriptions that reflect interactions among sounds and their evolution over time, moving...
Yong-Gai Zhuang, Teng Fei, Yun-Yan Du et al.· Journal of the Acoustical So...· 0 citations
Embodied artificial intelligence has historically very much relied on visual perception, leading to a proliferation of multiple vision-centric world models. However, this reliance fails to capture spatial understanding in its entirety and can even present vulnerabilities in environments with visual occlusions, low-ligh...
Text- and image-conditioned world generators can create visually rich 3D environments, yet these worlds often remain silent or rely on soundtracks synthesized solely from text or rendered video. Although such audio can convey what should be heard, it lacks an explicit representation of where sound sources are located a...
Duo-Wen Chen, Jin-Jin He, K. Gouthaman et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
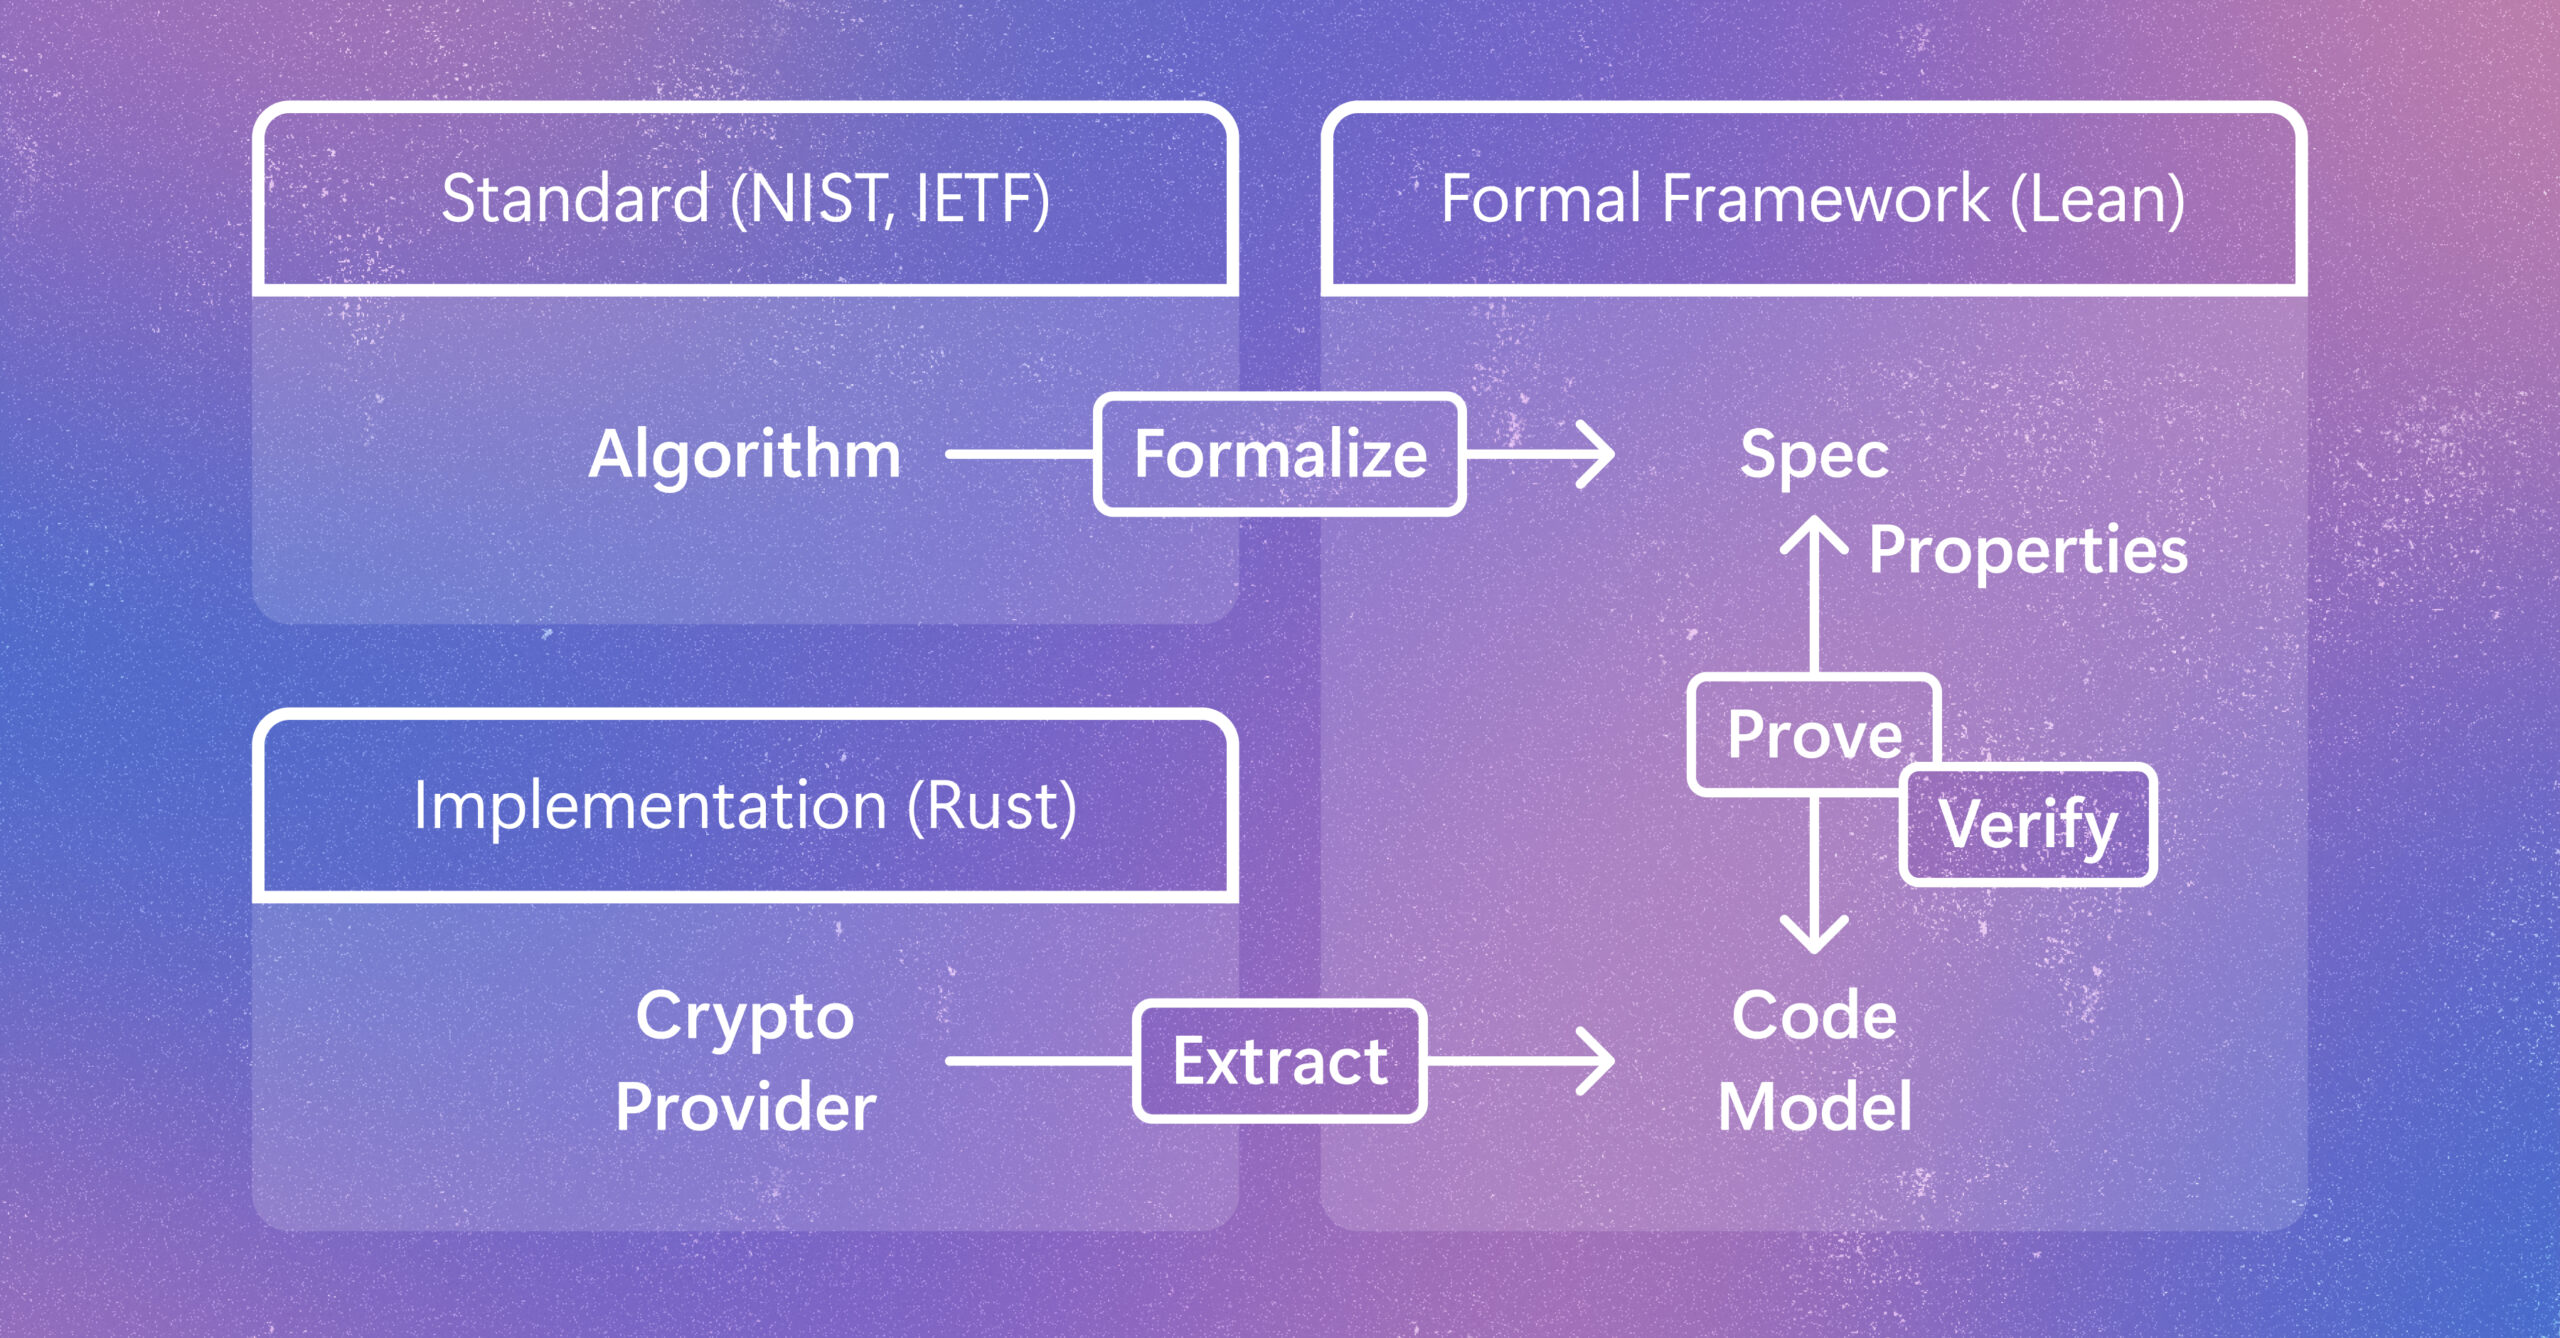
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.