Skip to content

HuRo: Robotizing Human Videos for Scalable VLA Pretraining

Sep 2026 · 2 citations · 44 references
Computer Science

TL;DR

A robotization pipeline is developed that converts heterogeneous human videos into robot-aligned observations and action trajectories while inferring missing intermediate signals across annotation levels and constructs the HuRo dataset, comprising about 630K robotized episodes and 142M processed frames from five human-video sources.

Abstract

Human video datasets offer an abundant and diverse source of interaction data that can complement expensive real-robot data. To bridge the human-to-robot embodiment gap, existing approaches either robotize videos in task-matched settings or address observation and action alignment separately. In this work, we systematically examine whether robotized human videos can serve as an effective and scalable source of robot-aligned supervision. To this end, we develop a robotization pipeline that converts heterogeneous human videos into robot-aligned observations and action trajectories while inferring missing intermediate signals across annotation levels. Using this pipeline, we construct the HuRo dataset, comprising about 630K robotized episodes and 142M processed frames from five human-video sources. Across four real-world manipulation tasks, pretraining a VLA policy on increasing amounts of robotized human-video data improves overall completion from 51.5% to 80.3% and OOD completion under spatial and visual shifts from 34.9% to 72.2%. Ablations further show that visual robotization improves OOD robustness and that end-to-end pretraining with retargeted actions outperforms visual-only transfer. Project website: https://3587jjh.github.io/HuRo.


View source

Similar papers

Preprint Aug 2026

RoboEdit: Turning Human Manipulation Videos into Scalable Robot Experience

RoboEdit is presented, a human-to-robot video editing suite that transforms human manipulation videos into action-consistent, physically plausible robot videos with aligned 3D hand states, providing scalable, high-fidelity visual and 3D motion supervision for generalizable robot learning.

Yaowei Guo, Zeng Tao, Yuxin Jiang et al. · 2 citations
Preprint Sep 2026

H2RBench: A Real-to-Sim Benchmark for Evaluating Human-to-Robot Transfer

Learning robot manipulation policies from human video demonstrations constitutes a promising avenue for scalable robot learning. However, comparing different human-to-robot (H2R) transfer methods remains challenging, as existing approaches are evaluated under different settings, including differing task suites, scene l...

Chu-Yang Xiao, Hao-Tian Zhan, Sriram Krishna et al. · 0 citations
Preprint Sep 2026

IronMind: Scaling Humanoid Dexterous Manipulation via Camera-Space Ego-Centric Pretraining

Egocentric human video offers a scalable data source for dexterous manipulation, yet using it to train humanoid robots presents two challenges: (1) an embodiment gap, as human hands differ structurally from robot end-effectors and low-cost egocentric recordings lack the torso kinematics required by conventional retarge...

Hui-Min Pan, Y. Ren, Kun-Peng Song et al. · 0 citations
Preprint Sep 2026

Ego4WAM: What Matters When Scaling Egocentric Human Data for Robot Learning?

Egocentric human data provides a scalable source of experience for robot learning, but varies substantially in human-robot alignment, behavioral coverage, and available supervision. Existing work shows favorable scaling with increasing human data, but it remains unclear which data properties drive downstream robot gain...

Zhi-Hao Sun, Liu Liu, Xin-Jiang Wang et al. · 0 citations
Preprint Aug 2026

LD4WAM: Learning Latent Dynamics from Human Videos for World Action Models

LD4WAM is presented, which pairs a Latent Dynamics Model trained with semantic reconstruction and real motion alignment with a World Dynamics Action Model built as a mixture-of-transformers (MoT), which preserves full future-video generation and uses learnable queries to distill these latent dynamics from generated fut...

Zhen Shen, Jia-Qi Liang, Jasper Lu et al. · 3 citations
Preprint Aug 2026

TemporalFlow-VLA: Learning Physically Grounded Execution History for Long-Horizon Robot Manipulation

TemporalFlow-VLA provides a compact, physically grounded interface for exploiting ordered execution history without explicit motion estimation or geometric processing at deployment, and shows its clearest advantage over prior methods on longer-horizon, multi-stage manipulation.

Jia-Rui Yang, Ye-Hao Lu, Yu-Ning Su et al. · 2 citations

Related blog posts

MIT News · Artificial Intelligence Oct 28, 2026

Making machines that can listen

Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.

Microsoft Research Blog Aug 11, 2026

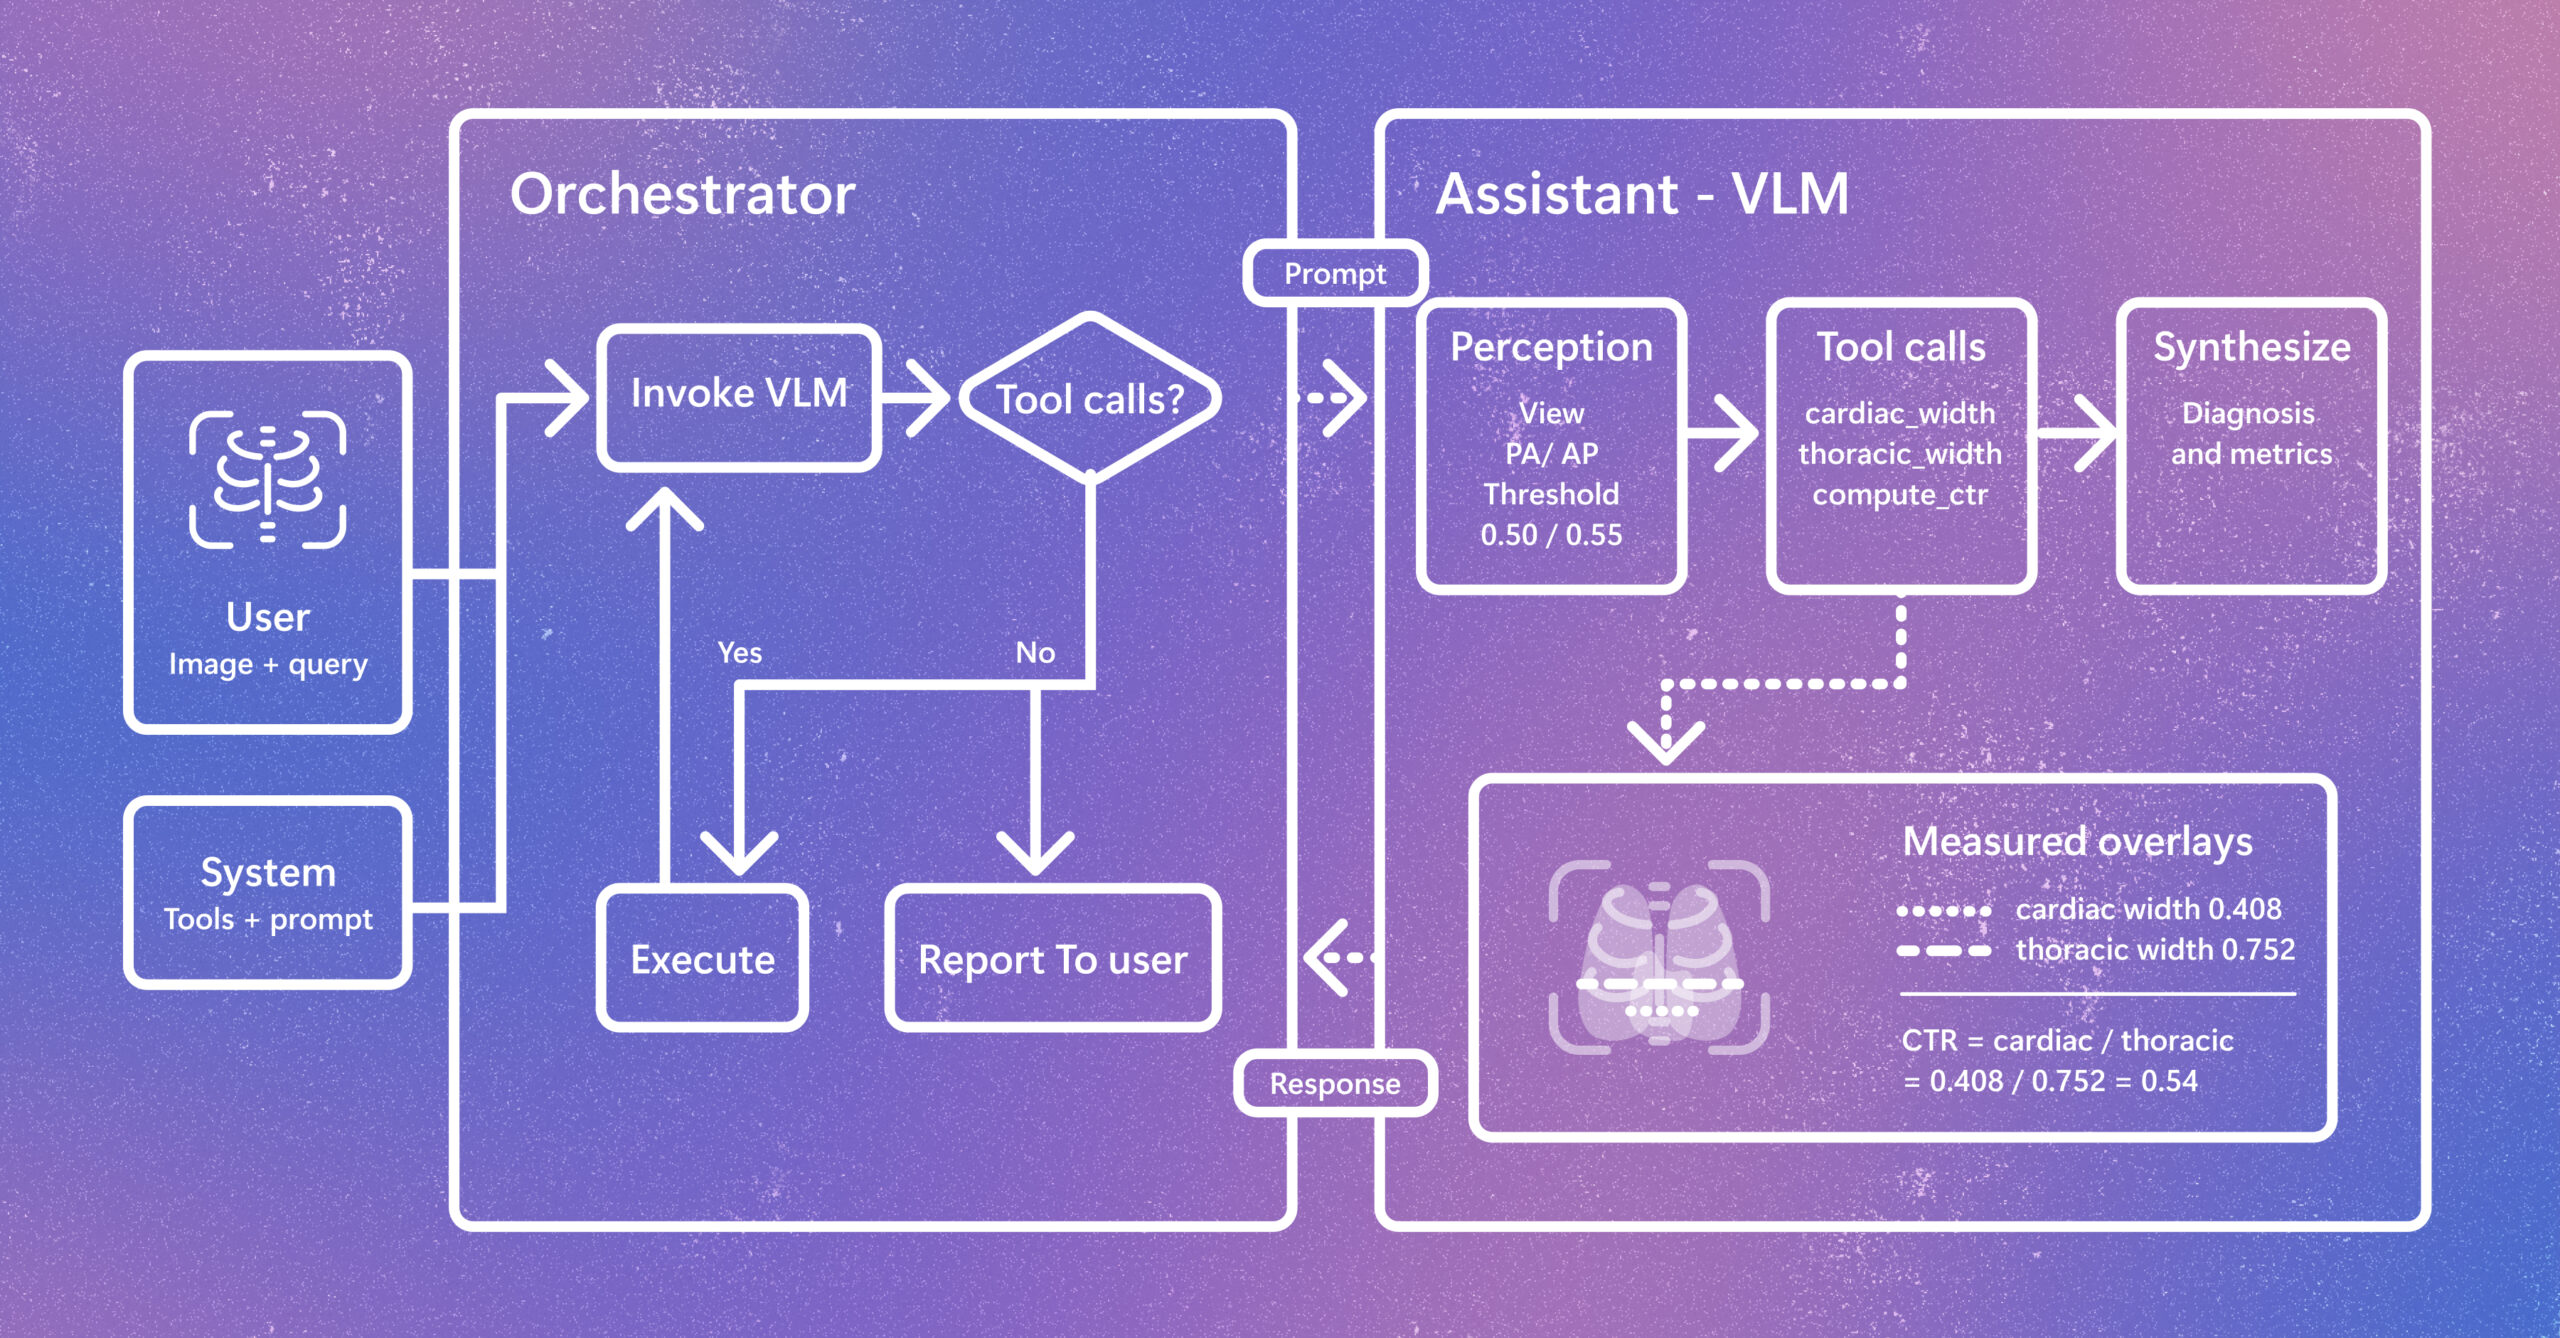
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.