Skip to content

Synergizing large and small models in cloud-edge continuum: a spatiotemporal hypergraph approach for dynamic offloading

Sep 2026 · Journal of Cloud Computing · 0 citations

TL;DR

This paper proposes a spatiotemporal hypergraph-driven framework integrating high-order topological feature extraction with dynamic resource modeling, and introduces dynamic hypergraph sequences to naturally encompass local conflict domains, mitigating the topological blind spots and “over-smoothing” issues inherent in traditional pairwise graphs.

Abstract

Cloud-edge collaborative inference, particularly the synergy between edge-deployed small models and cloud-based large models, demonstrates extensive application value in meeting the high-accuracy and low-latency demands of emerging artificial intelligence. However, existing dynamic offloading methods exhibit limitations in modeling the “many-to-many” high-order resource competition that arises when numerous small models concurrently access shared large model interfaces. They lack a unified representation capable of adapting to time-varying network congestion and often ignore the spatial exclusivity of concurrent tasks when sharing bandwidth and large model interfaces. To overcome these limitations, this paper proposes a spatiotemporal hypergraph-driven framework integrating high-order topological feature extraction with dynamic resource modeling. This framework introduces dynamic hypergraph sequences to naturally encompass local conflict domains, mitigating the topological blind spots and “over-smoothing” issues inherent in traditional pairwise graphs. In the first stage, a spatiotemporal hypergraph neural network (ST-HGNN) encodes complex spatial dependencies and predicts temporal resource bottlenecks. Subsequently, a weighted multi-dimensional hypergraph matching (WTHM) strategy transforms the NP-hard mixed-integer nonlinear programming problem into an efficient heuristic search. Trace-driven simulation results based on real-world urban trajectories (EUA and T-Drive) demonstrate that the proposed framework achieves a robust normalized VCI score of 0.64 even during extreme congestion peaks. By consistently achieving an absolute VCI improvement of 0.17 to 0.38 over traditional bipartite-graph and proximity-based baselines, the framework significantly mitigates cascading queuing failures. Moreover, the developed dual-timescale asynchronous architecture strictly confines online execution to the millisecond scale, validating its capability to balance inference accuracy and latency across dynamic cloud-edge environments.

Read PDF

Similar papers

Review Open access Aug 2026

Data Replication and Placement in the Cloud–Edge–Terminal Framework: A Systematic Review of AI-Driven, Multi-Objective Strategies

Efficient data replication approaches are essential to address the critical latency-cost trade-offs due to rapid growth in data-intensive applications. Centralized solutions based on traditional cloud models often suffer from high transmission delays, while static heuristic models struggle to manage multi-dimensional u...

Maqsood Ul Haq, Nor Asilah Wati Abdul Hamid, Shamala K. Subramaniam et al. · 0 citations
#small language model Book Open access Sep 2026

Edge-Cloud Collaborative RAG with Multi-State Semantic Caching

A Multi-State Semantic Cache (MSSC) framework that dynamically maps knowledge chunks into three mutually exclusive states: zero cache, index cache, and full cache is proposed that reduces average service latency by over 40% in dynamic scenarios and suppresses backhaul reconfiguration traffic by up to 38% compared to co...

Kang Liu, Guang-Ping Xu, Ya-Ru Fu et al. · 0 citations
Open access 2026

DABO: Difficulty-Aware Binary Offloading for Collaborative Large-Small Model Inference

DABO is proposed, a calibration-aware binary offloading method for collaborative large–small model inference that maintains competitive end-to-end accuracy while processing an average of 83.72% of requests at the edge.

Chen Zhu, Yi-Ming Su, Chenwenjie Mao et al. · 0 citations
#edge computing Nov 2026

Collaborative Large Model Caching and Inference Offloading With Parameter Sharing in MEC

Pretrained Foundation Models (PFMs) enable highaccuracy inference services but are typically deployed in remote datacenters, resulting in prohibitively high inference delay. Mobile Edge Computing (MEC) can mitigate such high delays by caching PFMs or their fine-tuned variants on cloudlets located close to end users. Ho...

Li-Zhe Zhou, Qiu-Fen Xia, Zi-Chuan Xu et al. · 0 citations
Oct 2026

Hierarchical Reinforcement Learning-Based Dual-Objective Caching Optimization for Dynamic–Static Metaverse Scenes

As Metaverse scenarios grow increasingly complex, users place higher demands on real-time rendering and interactive experiences for static and dynamic resources. Existing research largely focuses on static scene transmission, which is inadequate for joint rendering with dynamic Non-Player Characters (NPC). Moreover, ce...

Sheng-Lu Zhao, Zheng Wan, Yan-Ping Yu et al. · 0 citations
Preprint Sep 2026

WCCS: Efficient Wedge Conductance Community Search over Large Temporal Bipartite Graphs (Full Paper)

An online priority-driven filter-and-expand framework with several effective pruning techniques and a powerful geometric slope optimization for rapid temporal wedge conductance calculation is developed and a novel temporal wedge conductance metric is proposed that explicitly balances internal density and external spars...

Long-Long Lin, Wei Chen, Ping-Peng Yuan et al. · 0 citations

Related blog posts

Microsoft Research Blog Jul 13, 2026

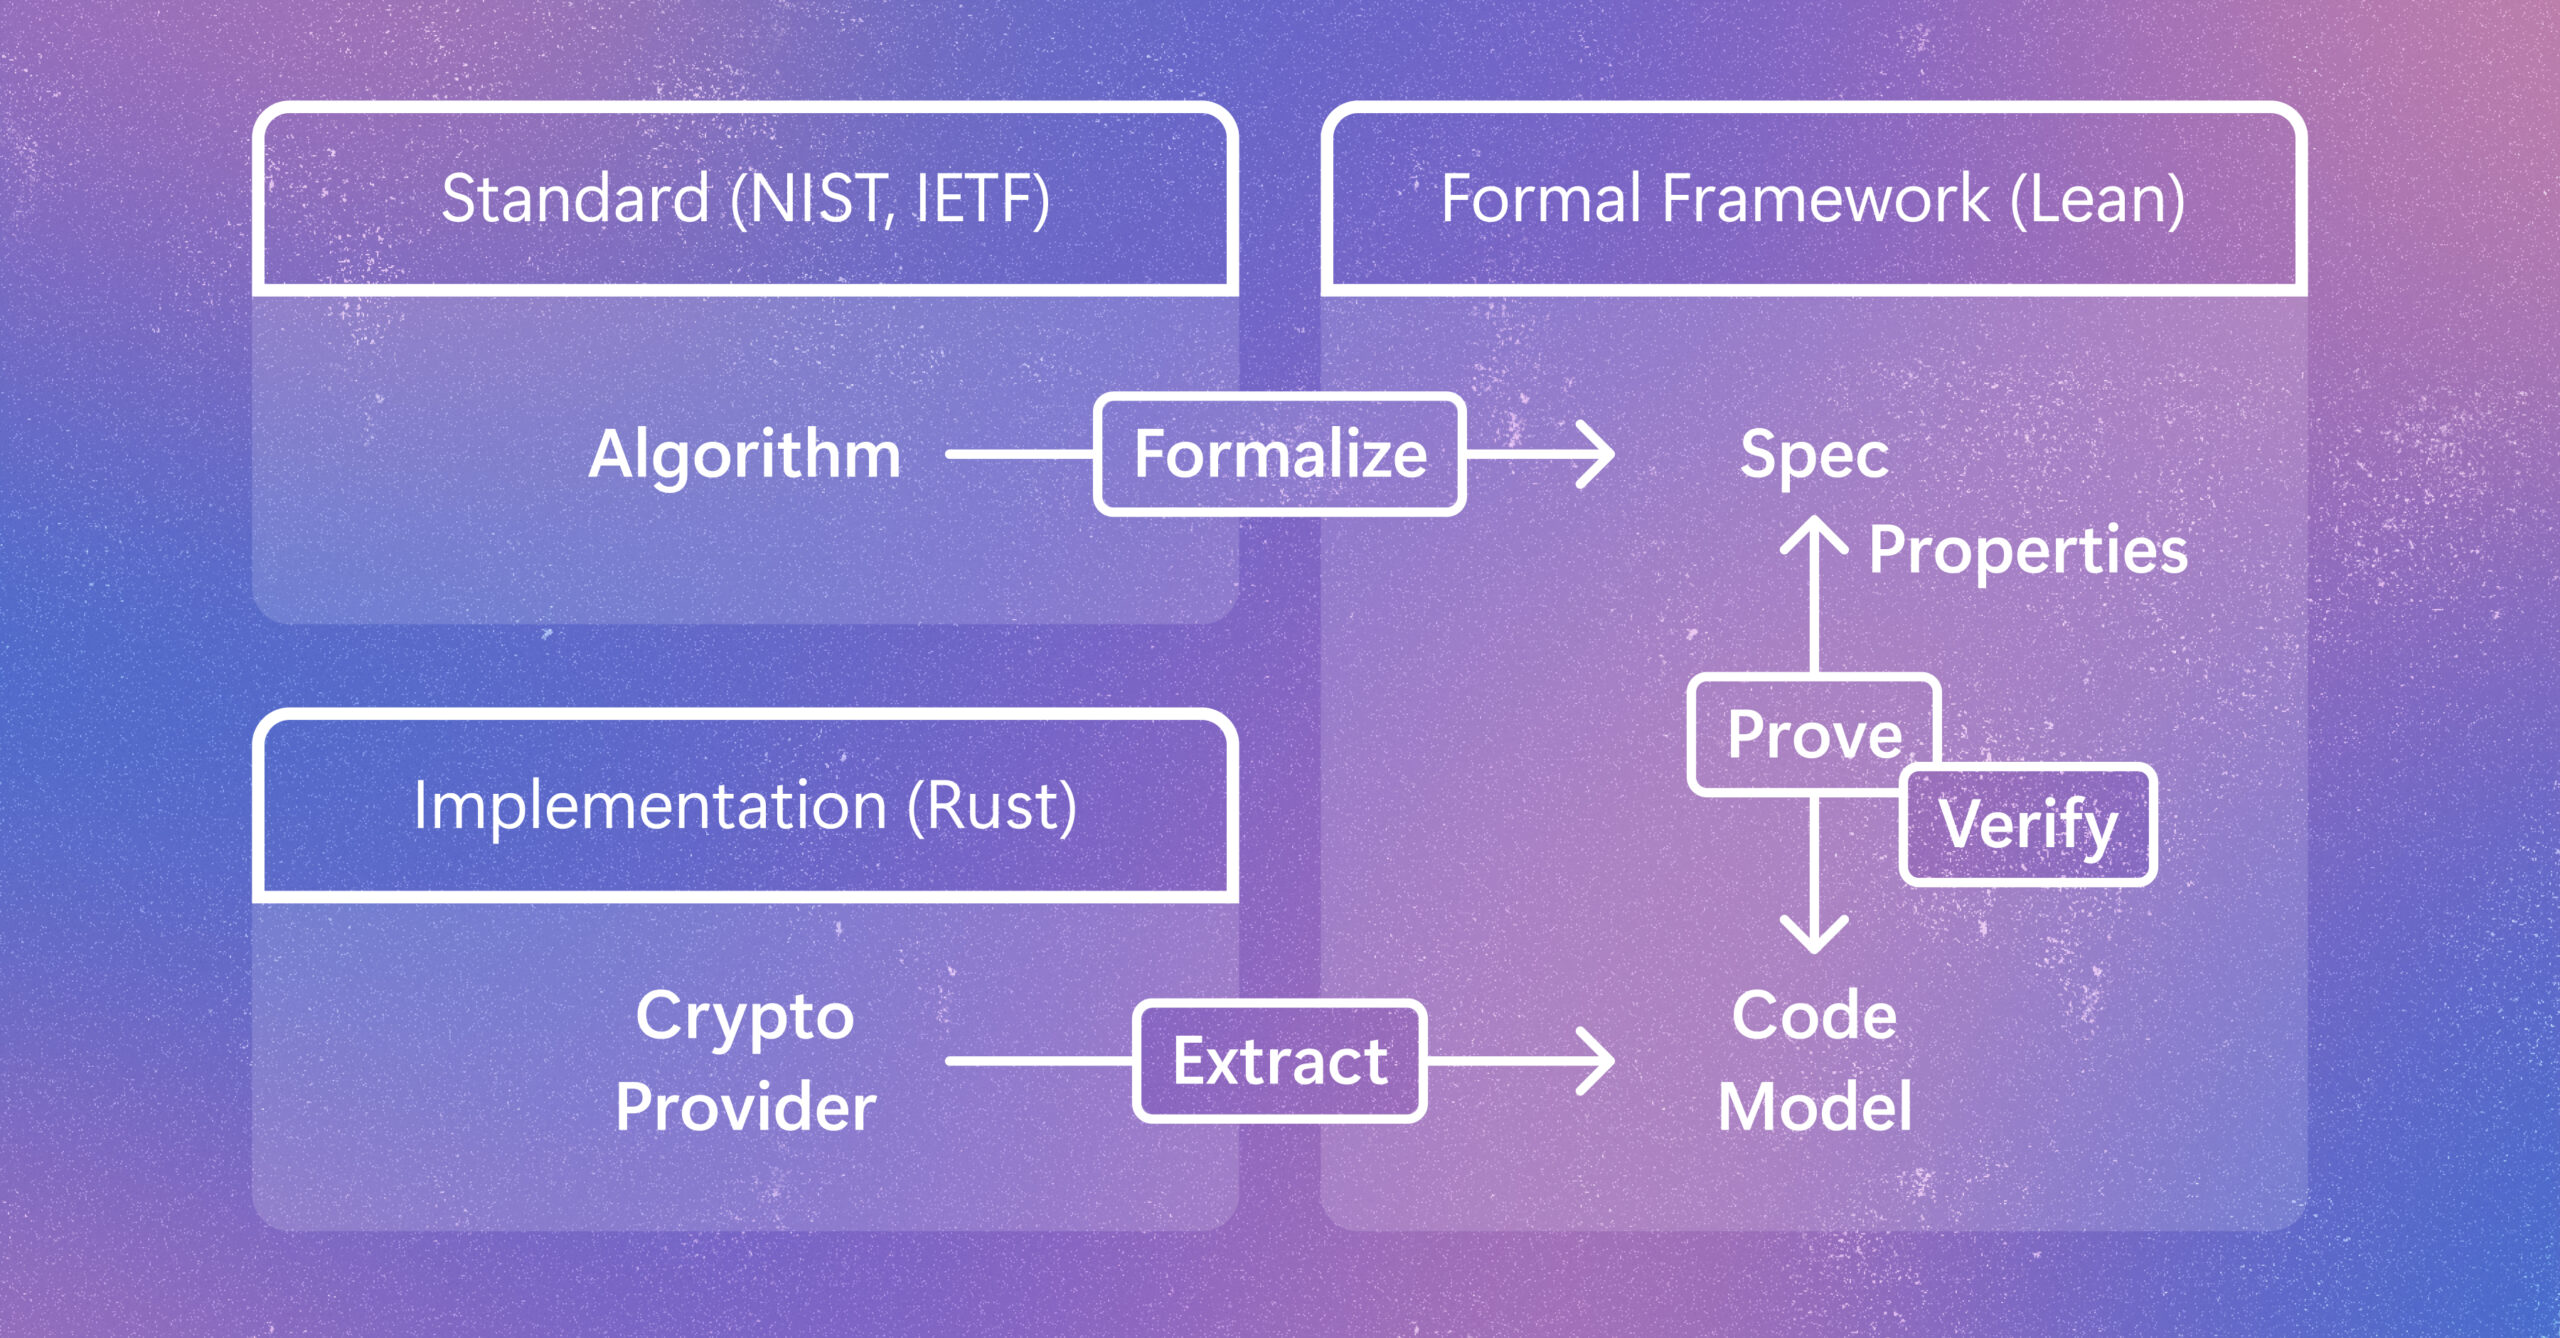
Verifying Rust cryptography in SymCrypt, from standards to code

Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.