Large Language Models (LLMs) memorize vast amounts of training data, raising concerns regarding privacy, copyright infringement, and safety. Machine unlearning seeks to remove the influence of a targeted forget set while preserving model performance, ideally approximating a model retrained from scratch without it. Once...
Vin\'icius Conte Turani, Ot\'avio Parraga, Jo\~ao Vitor Boer Abitante et al.· 0 citations
Solving optimal transport (OT) on random minibatches is a common surrogate for exact OT in large-scale learning. In flow matching (FM), this surrogate is used to obtain OT-like couplings that can straighten probability paths and reduce numerical integration cost. Yet, the population-level coupling induced by repeated m...
Samuel Bo\"it\'e, Julie Delon, Kimia Nadjahi· 0 citations
Rotary Positional Encoding (RoPE) is widely used in modern large language models. However, when sequences are extended beyond the range seen during training, rotary phases can enter out-of-distribution regimes, leading to spurious long-range alignments, diffuse attention, and degraded retrieval. Existing remedies only...
Riccardo Ali, Alessio Borgi, Mario Severino et al.· 0 citations
CUTS-GPR enables Bayesian modelling of high-dimensional PESs - a longstanding challenge in computational chemistry by running full GPR calculations, including hyperparameter optimization, on synthetic datasets with up to 447 data points and 500 dimensions.
Mads Greisen Ho̷jlund, August Lykke-Møller, Henry B. Moss et al.· arXiv.org· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Second-order calibration error quantifies how closely a higher-order predictor's epistemic-uncertainty estimate matches the conditional variance of the label probability on its level sets. We characterize the minimax rate of estimating the second-order calibration error for binary classification in the regime where a s...
Kamil Ciosek, Banafsheh Rafiee, Sina Ghiassian et al.· 0 citations
Deep neural networks exhibit periodic loss spikes during unregularized long-term training, a phenomenon known as the "Slingshot Mechanism." Existing work usually attributes this to intrinsic optimization dynamics, but its triggering mechanism remains unclear. This paper proves that this phenomenon is a result of floati...
Hanqing Liu, Jianjun Cao, Yuanze Li et al.· 0 citations
Current transformers discard their rich latent residual stream between positions, reconstructing latent reasoning context at each new position and leaving potential reasoning capacity untapped. The State Stream Transformer (SST) V2 enables parameter-efficient reasoning in continuous latent space through an FFN-driven n...
Motivation: Multi-omics integration can improve cancer subtyping, but modality informativeness and noise vary across cancer types and patients. Most graph methods for multi-omics data learn modality contributions within the downstream classification objective, leaving predictive reliability for each patient implicit. A...
Boyang Fan, Hengchuang Yin, Siyu Yi et al.· 0 citations
We study value adaptation in offline-to-online reinforcement learning under general function approximation. Starting from an imperfect offline pretrained $Q$-function, the learner aims to adapt it to the target environment using only a limited amount of online interaction. We first characterize the difficulty of this s...
Federated learning (FL) enables multiple clients to collaboratively train a global model by aggregating local updates without sharing private data. In this work, we focus on cross-silo FL, where each client typically represents an independent organization. However, cross-silo FL can face the challenge of free-riders, c...
The linear representation hypothesis states that neural network activations encode high-level concepts as linear mixtures. However, under superposition, this encoding is a projection from a higher-dimensional concept space into a lower-dimensional activation space, and a linear decision boundary in the concept space ne...
Vit\'oria Barin-Pacela, Shruti Joshi, Isabela Camacho et al.· 0 citations
Diffusion models generalize well in practice. Paradoxically, an optimal diffusion model fully memorizes the training data and therefore fails to generalize, raising the question of what induces generalization in a real diffusion model. We show that diffusion models progressively overfit the denoising training objective...
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
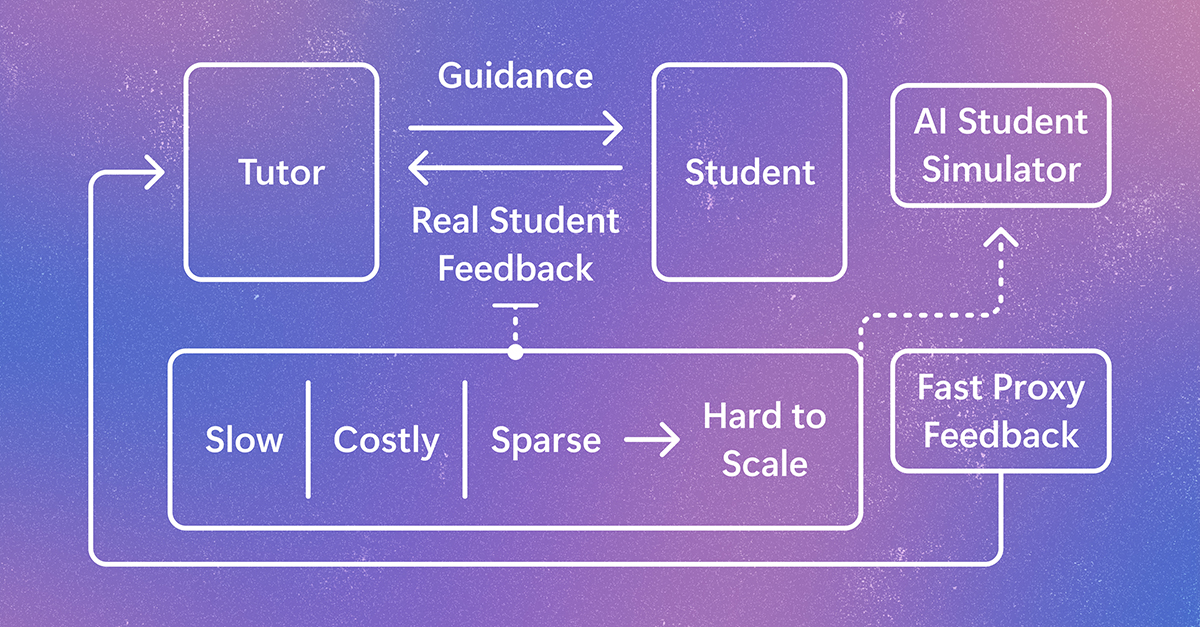
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.