FAST is presented, a holistic framework that accelerates end-to-end TGNN training by jointly optimizing sampling, memory I/O, and computation and designs thread-efficient graph operators tailored to sparse temporal subgraphs, improving GPU cache locality and reducing the latency of aggregation and edge softmax.
Abstract
Temporal Graph Neural Networks (TGNNs) are widely used for learning from dynamic graphs in applications such as recommendation, social network analysis, and traffic forecasting. However, scaling TGNN training to large dynamic graphs remains challenging due to three intertwined bottlenecks: memory I/O, irregular computation, and temporal neighbor sampling. Existing systems often optimize these stages in isolation, leaving substantial performance headroom on the table. We present FAST, a holistic framework that accelerates end-to-end TGNN training by jointly optimizing sampling, memory I/O, and computation. FAST introduces SlimCache, which exploits within-batch compression and cross-batch caching to reduce host-device data movement under limited GPU memory budgets. It further designs thread-efficient graph operators tailored to sparse temporal subgraphs, improving GPU cache locality and reducing the latency of aggregation and edge softmax. In addition, FAST employs a topology-aware sampling strategy that improves CPU cache locality and accelerates temporal neighbor sampling. Extensive experiments on real-world large dynamic graphs show that FAST achieves an average of 2.1x (up to 4.7x) speedup over state-of-the-art systems without sacrificing model accuracy.
This work introduces a tile-aware scheduling framework for efficient sparse Vision Transformer execution on GPUs and introduces a training-aware extension that reuses the inference tile schedule and augments it with backward computation and activation-memory strategies.
Changxin Li· IEEE International Symposium...· 0 citations
Deep neural networks (DNNs) with billions of parameters power many important applications, but their training is fundamentally constrained by the limited on-chip memory of GPUs. This memory wall forces training to rely on distributed execution or memory offloading, both of which introduce substantial inefficiencies. Ex...
Xiaoyang Sun, Jie Xu, Zheng Wang· IEEE Transactions on Paralle...· 0 citations
This work proposes Turbo, a first-of-its-kind in-network aggregation system that accelerates long-context inference by offloading query broadcast and attention aggregation to switches and introduces a rolling forward scheme that propagates states to enable cross-stage updates.
Ying Wan, Yuchen Xu, Chuwen Zhang et al.· Conference on Applications,...· 0 citations
This paper introduces a novel chunk-based graph representation model, featuring classified and hierarchical vertex storage and chunk layout optimization, to improve I/O utilization and presents a latency-optimized access mechanism featuring user-space asynchronous I/O execution and hotness-aware chunk caching managemen...
Rui Wang, Weixu Zong, Shuibing He et al.· ACM Transactions on Storage· 0 citations
A time-varying integer program to minimize the long-term total cost of the edge AI inference system, including the inference latency, the inference error rate, the query-dispatching communication cost, and the energy consumption, subject to resource and workload constraints is proposed.
Ming-Tao Ji, Hehan Zhao, Lei Jiao et al.· Science China Information Sc...· 0 citations
This work highlights the need for NUNA-aware routing (NAR), choosing optimized, spatially-aware inter-GPU paths in large scale-up network topologies and introduces NUNA-aware placement (NAP), placing threadblocks and data near I/O to optimize the inter-GPU traffic.
C. Green, William Won, Ta Tuan et al.· 1 citation
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
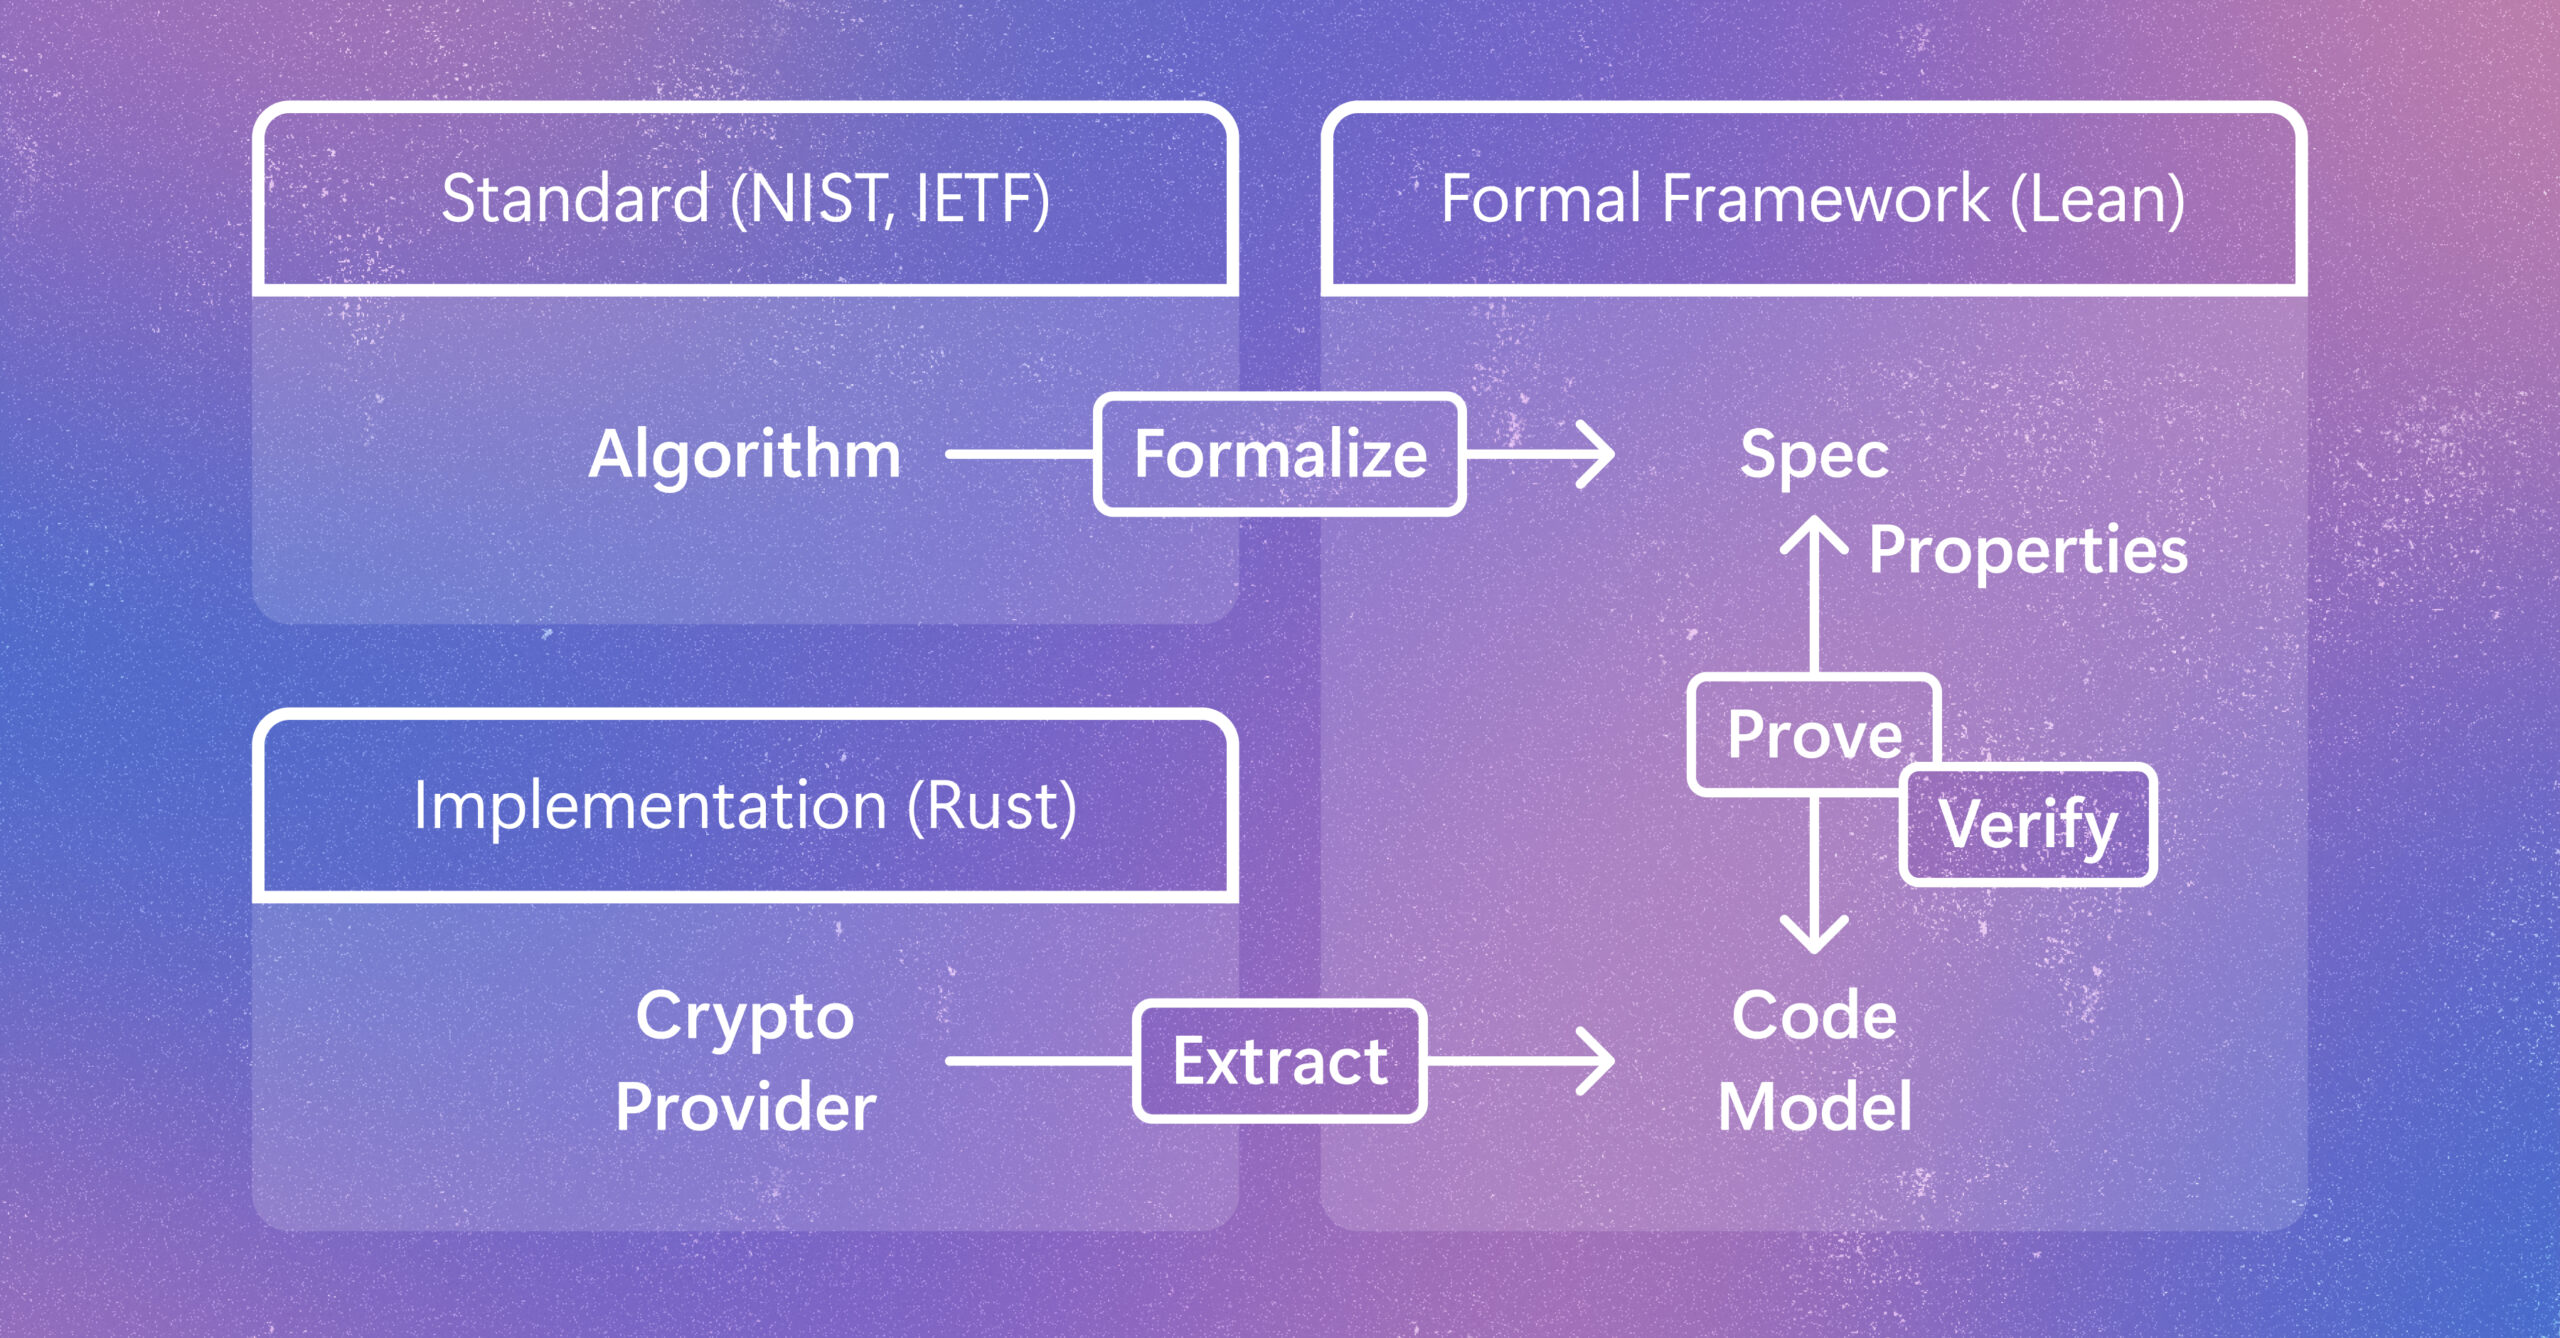
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.