Skip to content

VietLegalLM: Progressive Legal Expertise Through Synthetic Comprehension and Reinforcement Learning

Sep 2026 · ACM Transactions on Asian and Low-Resource Language Information Processing · Vol 25, pp. 1 - 22 · 0 citations · 30 references
Topic Modeling

TL;DR

This work presents vilaw-bench, a novel evaluation benchmark tailored for Vietnamese statute-based legal reasoning that assesses cognitive abilities from basic knowledge retrieval to complex legal interpretation, and proposes a multi-stage training framework that progressively builds legal expertise through four phases.

Abstract

Legal AI systems require accuracy and verifiable reasoning, yet under-resourced languages lack the specialized models needed to meet these standards. This challenge is particularly acute for statute-based civil law systems like Vietnam’s, where the core task is interpreting and applying codified statutes rather than matching legal precedents. We address this gap by introducing a comprehensive framework for developing reliable legal AI under resource constraints. First, we present vilaw-bench, a novel evaluation benchmark tailored for Vietnamese statute-based legal reasoning that assesses cognitive abilities from basic knowledge retrieval to complex legal interpretation. Second, we propose a multi-stage training framework that progressively builds legal expertise through four phases: focused foundational learning on core legal texts, intensive comprehension practice using large-scale synthetic question-answer data, targeted skill acquisition through supervised fine-tuning, and response quality refinement using Group Relative Policy Optimization (GRPO). We implement this framework to develop VietLegalLM, training on Qwen3-1.7B-Base and Qwen3-4B-Base models. Our systematic evaluation reveals that synthetic comprehension practice produces the largest single-phase improvements in legal reasoning capabilities, while GRPO efficiently refines reasoning structure with minimal training steps. The complete sequential training approach achieves significant performance gains on vilaw-bench compared with baseline models. Our ablation studies demonstrate that practitioners can make informed tradeoffs between comprehensive training and computational efficiency: direct GRPO after pre-training offers a viable alternative to full instruction tuning when resources are limited. We release vilaw-bench, VietLegalLM, and our training framework as open-source resources, providing a reproducible roadmap for developing legal AI in other under-resourced, statute-based legal systems.


Read PDF

Similar papers

#natural language process... Preprint Oct 2026

LawCompass: Navigating from Legal QA to Multi-Agent Deep Research with Grounded Evidence

Evaluation results demonstrate that LawCompass provides a practical and scalable paradigm for transforming conversational AI into trustworthy and evidence-grounded legal research assistance, and maintains explicit citation links across all modules.

Xiaoxia Cheng, Lin-Nan Wang, Jia-Hao Ma et al. · 0 citations
#natural language process... Preprint Sep 2026

LexReward: A Taxonomy-Driven Reward Framework for Legal Language Models

Experiments show that the rubric-based rewards reliably distinguish legal responses of different quality and that DPO training on the preference data improves performance across all three dimensions, and Dimension-wise analyses further support the effectiveness of the proposed taxonomy and reward construction.

Yi-Da Cai, Xin Dai, Bing-Xiang He et al. · 0 citations
Open access 2026

Diagnosing Chinese Legal LLMs Across Memorization, Understanding, and Application: The Newtouch-LawBench Benchmark

With the emergence of large language models (LLMs) as strong performers across diverse natural language tasks, high-stakes and knowledge-intensive domains such as law impose stricter requirements on factual reliability, norm-conformant application, and verifiable reasoning. Although existing Chinese legal evaluation be...

Ruo-Chen Lin, Le-Kang Zhang, Hao Wang et al. · 0 citations
#natural language process... Preprint Oct 2026

Legal-R1: Agentic Retrieval for Evidence-Based Legal Reasoning

Legal question answering requires answers that are not only plausible, but also grounded in legally valid and citable evidence. Standard retrieval-augmented generation often relies on one-shot semantic matching, which is insufficient when legal evidence must be selected according to authority, applicability, and divers...

Huai-Wen Pang, Jiale Han, Junying Chen et al. · 0 citations
#artificial intelligence Preprint Sep 2026

Self-Play Search Distillation for Large Language Model Reasoning

Self-Play Search Distillation (SPSD), a framework for generating superhuman synthetic data via self-play of MuZero-like networks trained on board games, offers an annotation-efficient way to create high-quality synthetic data for improving LLM performance in reasoning tasks.

Lorenzo Molfetta, Wai-Chung Kwan, Giacomo Frisoni et al. · 0 citations
#artificial intelligence Preprint Sep 2026

Beyond Verified Answers: Solver-Informed Self-Distillation for Bootstrapping Operations Research Language Models

SOLID is proposed, a novel framework for self-improving OR language models without verified answers or external evaluators that improves solution accuracy for both general-purpose and OR-tuned models over outcome-only group-relative training.

Rui-Chen Zhu, Ming-Long Cao, Chen-Yu Zhou et al. · 0 citations

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 12, 2026

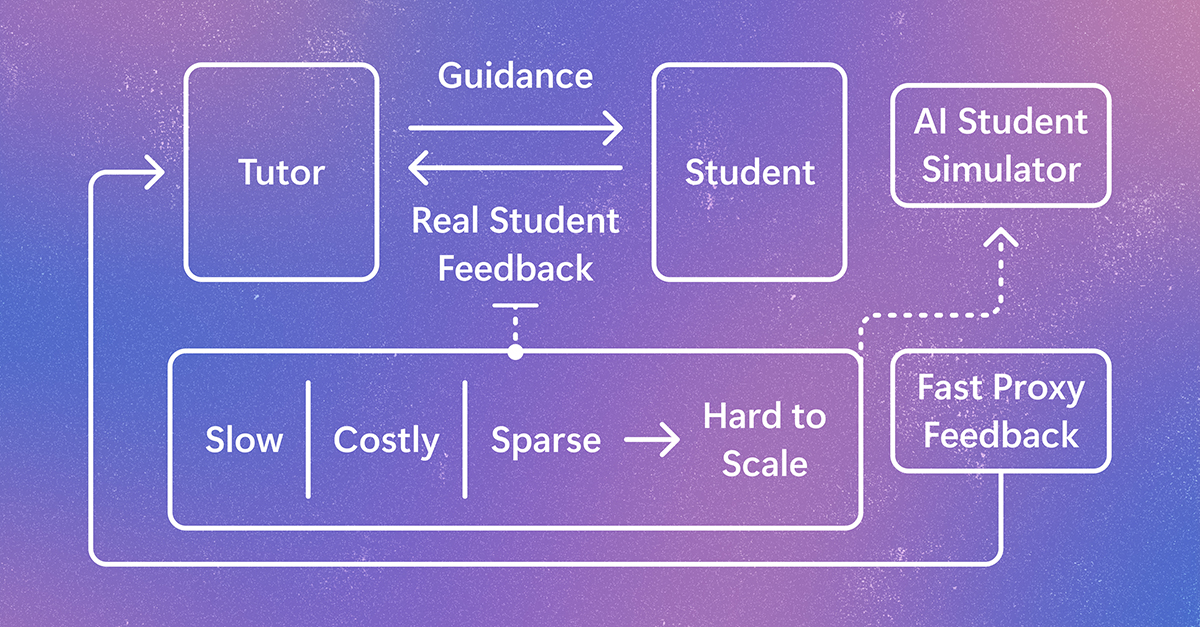
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.