Skip to content

A Survey on Self-Improving Test-Time Intelligence: Feedback-Driven Adapting, Learning, and Scaling at Inference

Sep 2026 · 2 citations
Computer Science

Abstract

The ability of AI systems to improve their behavior during deployment is becoming increasingly important. As inference moves beyond the static execution of a fixed trained model, a growing body of work studies how models can refine their behavior on the fly by exploiting test-time information and additional computation. These developments have largely evolved along two directions: methods that modify the model's state using test-time signals, and methods that improve predictions through extra inference-time resources such as more sampling and tool use. However, these directions are often studied in separate communities with different terminology, making their connections harder to see. In this survey, we present feedback-driven Test-Time Intelligence (TTI) as a unified perspective for understanding such deployment-time improvement. We use this view to relate test-time adaptation, test-time learning, and test-time scaling, highlighting both their distinctions and their growing overlap in hybrid systems. This unified framework helps connect previously fragmented ideas and provides a clearer conceptual foundation for studying inference-time self-improvement. We review major methodological paradigms, representative applications, and open challenges across vision, language, multimodal learning, generative models, robotics, and healthcare. Our goal is to provide a coherent foundation and research roadmap for the study of self-improving AI systems at test time.


View source

Similar papers

#artificial intelligence Conference Open access Jun 2018

Gibson Env: Real-World Perception for Embodied Agents

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.

F. Xia, Amir Zamir, Zhi-Yang He et al. · 1,069 citations · ⚡112
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60

KTO: Model Alignment as Prospect Theoretic Optimization

This work proposes a HALO that directly maximizes the utility of generations instead of maximizing the log-likelihood of preferences, and suggests that the best loss depends on the inductive biases most appropriate for a given setting, an oft-overlooked consideration.

Kawin Ethayarajh, Winnie Xu, Niklas Muennighoff et al. · 195 citations · ⚡28

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 12, 2026

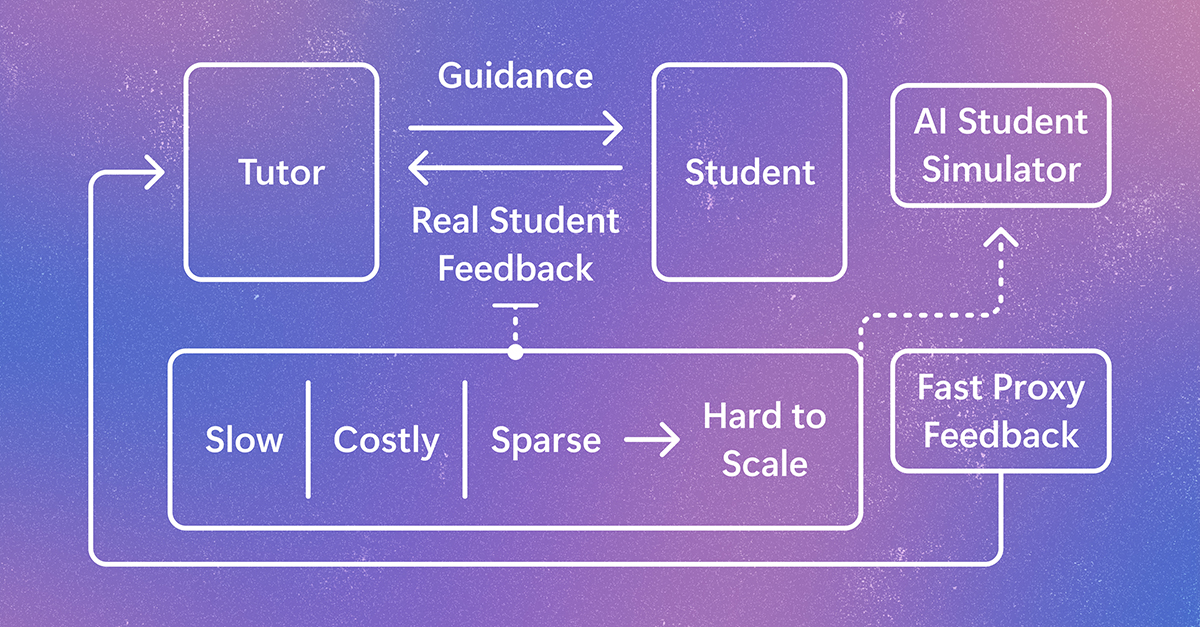
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.