Skip to content

Automated Structured Reporting of Neurodegenerative Imaging Markers Using Quantitative MRI and Large Language Models.

Oct 2026 · Academic Radiology · 0 citations · 37 references
Medicine

TL;DR

The authors' quantitative MRI-to-structured reporting pipeline, integrating quantitative MRI software with large language models with LLM-based conclusion generation, might be feasible for automated structured drafting of neurodegenerative imaging markers.
Abstract

Rationale

AND

Objectives

To evaluate the feasibility of a quantitative magnetic resonance imaging (MRI)-to-structured reporting pipeline that integrates quantitative MRI software with large language models (LLMs) for structured drafting of neurodegenerative imaging markers and generating clinician-facing report conclusions.

Materials And Methods

A total of 192 patients with 3D T1 and 2D or 3D FLAIR MRI images from the Alzheimer's Disease Neuroimaging Initiative database were randomly selected. A deep-learning model generated structured report findings based on nine indices related to brain atrophy, white matter hyperintensities, and cerebrospinal fluid (CSF) space abnormalities, and compared with neuroradiologist-generated reference reports. Four LLMs (GPT-OSS 20B, MedGemma 4B, Phi-3, and Llama 3.1 8B) generated clinician-facing conclusions from the structured findings. Generated conclusions were evaluated using a five-point Likert scale across four metrics (accuracy, relevance, clarity, and satisfaction). Output errors were assessed across four categories: language, omission, addition, and numeric errors.

Results

Structured report findings demonstrated high accuracy for CSF space analysis (77.6%-97.9%). Performance for ordinal visual scales was lower under strict matching (27.1%-57.8%) but improved with a one-grade tolerance (91.7%-97.4%). Among LLMs, GPT achieved the highest scores across most metrics (median score 5) and exhibited the lowest output error rates. Smaller models (Phi-3 and Llama 3.1 8B) showed overall lower performance, with more language, omission, and addition errors. MedGemma demonstrated intermediate performance, but the highest rate of numeric errors.

Conclusion

Our quantitative MRI-to-structured reporting pipeline, integrating quantitative MRI software with LLM-based conclusion generation, might be feasible for automated structured drafting of neurodegenerative imaging markers.
View source

Similar papers

#small language model Dataset Open access Oct 2026

Socratic guiding questions in synthetic arithmetic data: matched LoRA runs (revision v2)

Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...

O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al. · 465 citations
#computer vision Open access Jun 2016

Software Development in Startup Companies: The Greenfield Startup Model

The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.

Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al. · 178 citations · ⚡14
#computer vision Open access Oct 2016

Software Startups - A Research Agenda

Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.

M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al. · 157 citations · ⚡17
#machine learning Review Open access Oct 2016

“Failures” to be celebrated: an analysis of major pivots of software startups

This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.

Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al. · 127 citations · ⚡15
#computer vision Review Open access May 2015

A survey study on major technical barriers affecting the decision to adopt cloud services

The comparison of adopter and non-adopter sample reveals three potential adoption inhibitor, security, data privacy, and portability, which underlines the importance of the technical and security perspectives for research investigating the adoption of technology.

Nattakarn Phaphoom, Xiaofeng Wang, S. Samuel et al. · 111 citations · ⚡8
#computer vision Open access Feb 2018

Lean Internal Startups for Software Product Innovation in Large Companies: Enablers and Inhibitors

This study investigates how Lean internal startup facilitates software product innovation in large companies and identifies its enablers and inhibitors, and shows the potential of the method-in-action framework to investigate the Lean startup approach in non-startup context.

Henry Edison, Nina M. Smørsgård, Xiaofeng Wang et al. · 78 citations · ⚡6

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 22, 2026

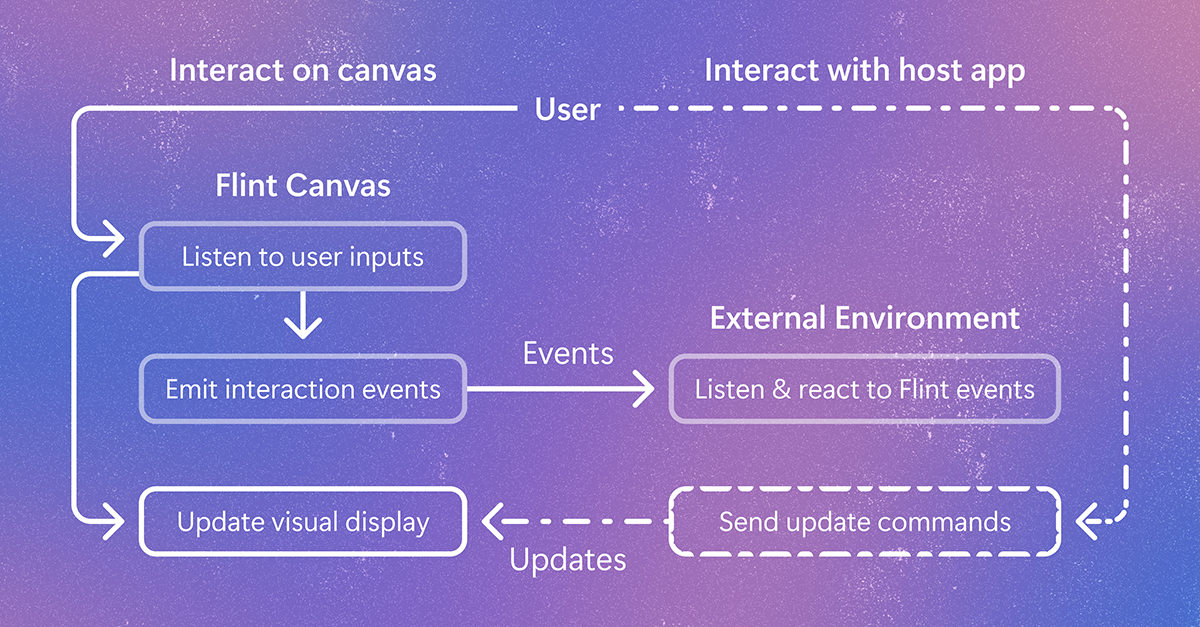
Flint-interactive: A language for creating interactive data visualizations

Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.