Skip to content

How Should Teachers Be Prepared? RL on Student-Induced States for On-Policy Distillation

Oct 2026 · 0 citations · 34 references
Computer Science

Abstract

On-policy distillation (OPD) improves the reasoning capabilities of small language models through token-level teacher supervision on student-generated trajectories. Yet can teachers that excel at solving problems independently also guide student reasoning effectively? Prior work shows that when student prefixes follow reasoning paths that differ from the teacher's own or contain errors, teachers can be less accurate when continuing from these prefixes than when solving problems independently. To this end, we propose Prep-OPD, which uses reinforcement learning (RL) before distillation to train the teacher to adapt to the student's existing reasoning state and correct course when errors arise. Training optimizes teacher continuations from fixed student prefixes using final-answer correctness as the reward. The prepared teacher then trains the student through trajectory guidance and token-level supervision. We evaluate Prep-OPD on eight mathematical reasoning benchmarks, using Qwen3-4B-Instruct-2507 as the teacher and Qwen3-0.6B and Qwen3-1.7B as students. With the 4B teacher and 1.7B student, Prep-OPD improves average accuracy over standard OPD and the strongest baseline, Relay-OPD, by 8.28 and 2.30 percentage points, respectively. Controlled experiments further show that teacher RL conditioned on student-generated prefixes yields higher student accuracy than problem-start teacher RL with and without handoff on Qwen3-1.7B. Reusing the same prepared teacher also improves Qwen3-0.6B.
View source

Similar papers

#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60
#computer vision Open access Jun 2016

Software Development in Startup Companies: The Greenfield Startup Model

The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.

Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al. · 178 citations · ⚡14
#machine learning Review Open access Jun 2014

Why Early-Stage Software Startups Fail: A Behavioral Framework

This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.

Carmine Giardino, Xiaofeng Wang, P. Abrahamsson · 175 citations · ⚡19
#computer vision Open access Oct 2016

Software Startups - A Research Agenda

Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.

M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al. · 157 citations · ⚡17

Related blog posts

GPT-Lab Sep 3, 2026

Adaptive AI Agents in Construction Workflows

Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.

GPT-Lab Aug 28, 2026

We built an AI factory for HVAC control

What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.

Microsoft Research Blog Jul 30, 2026

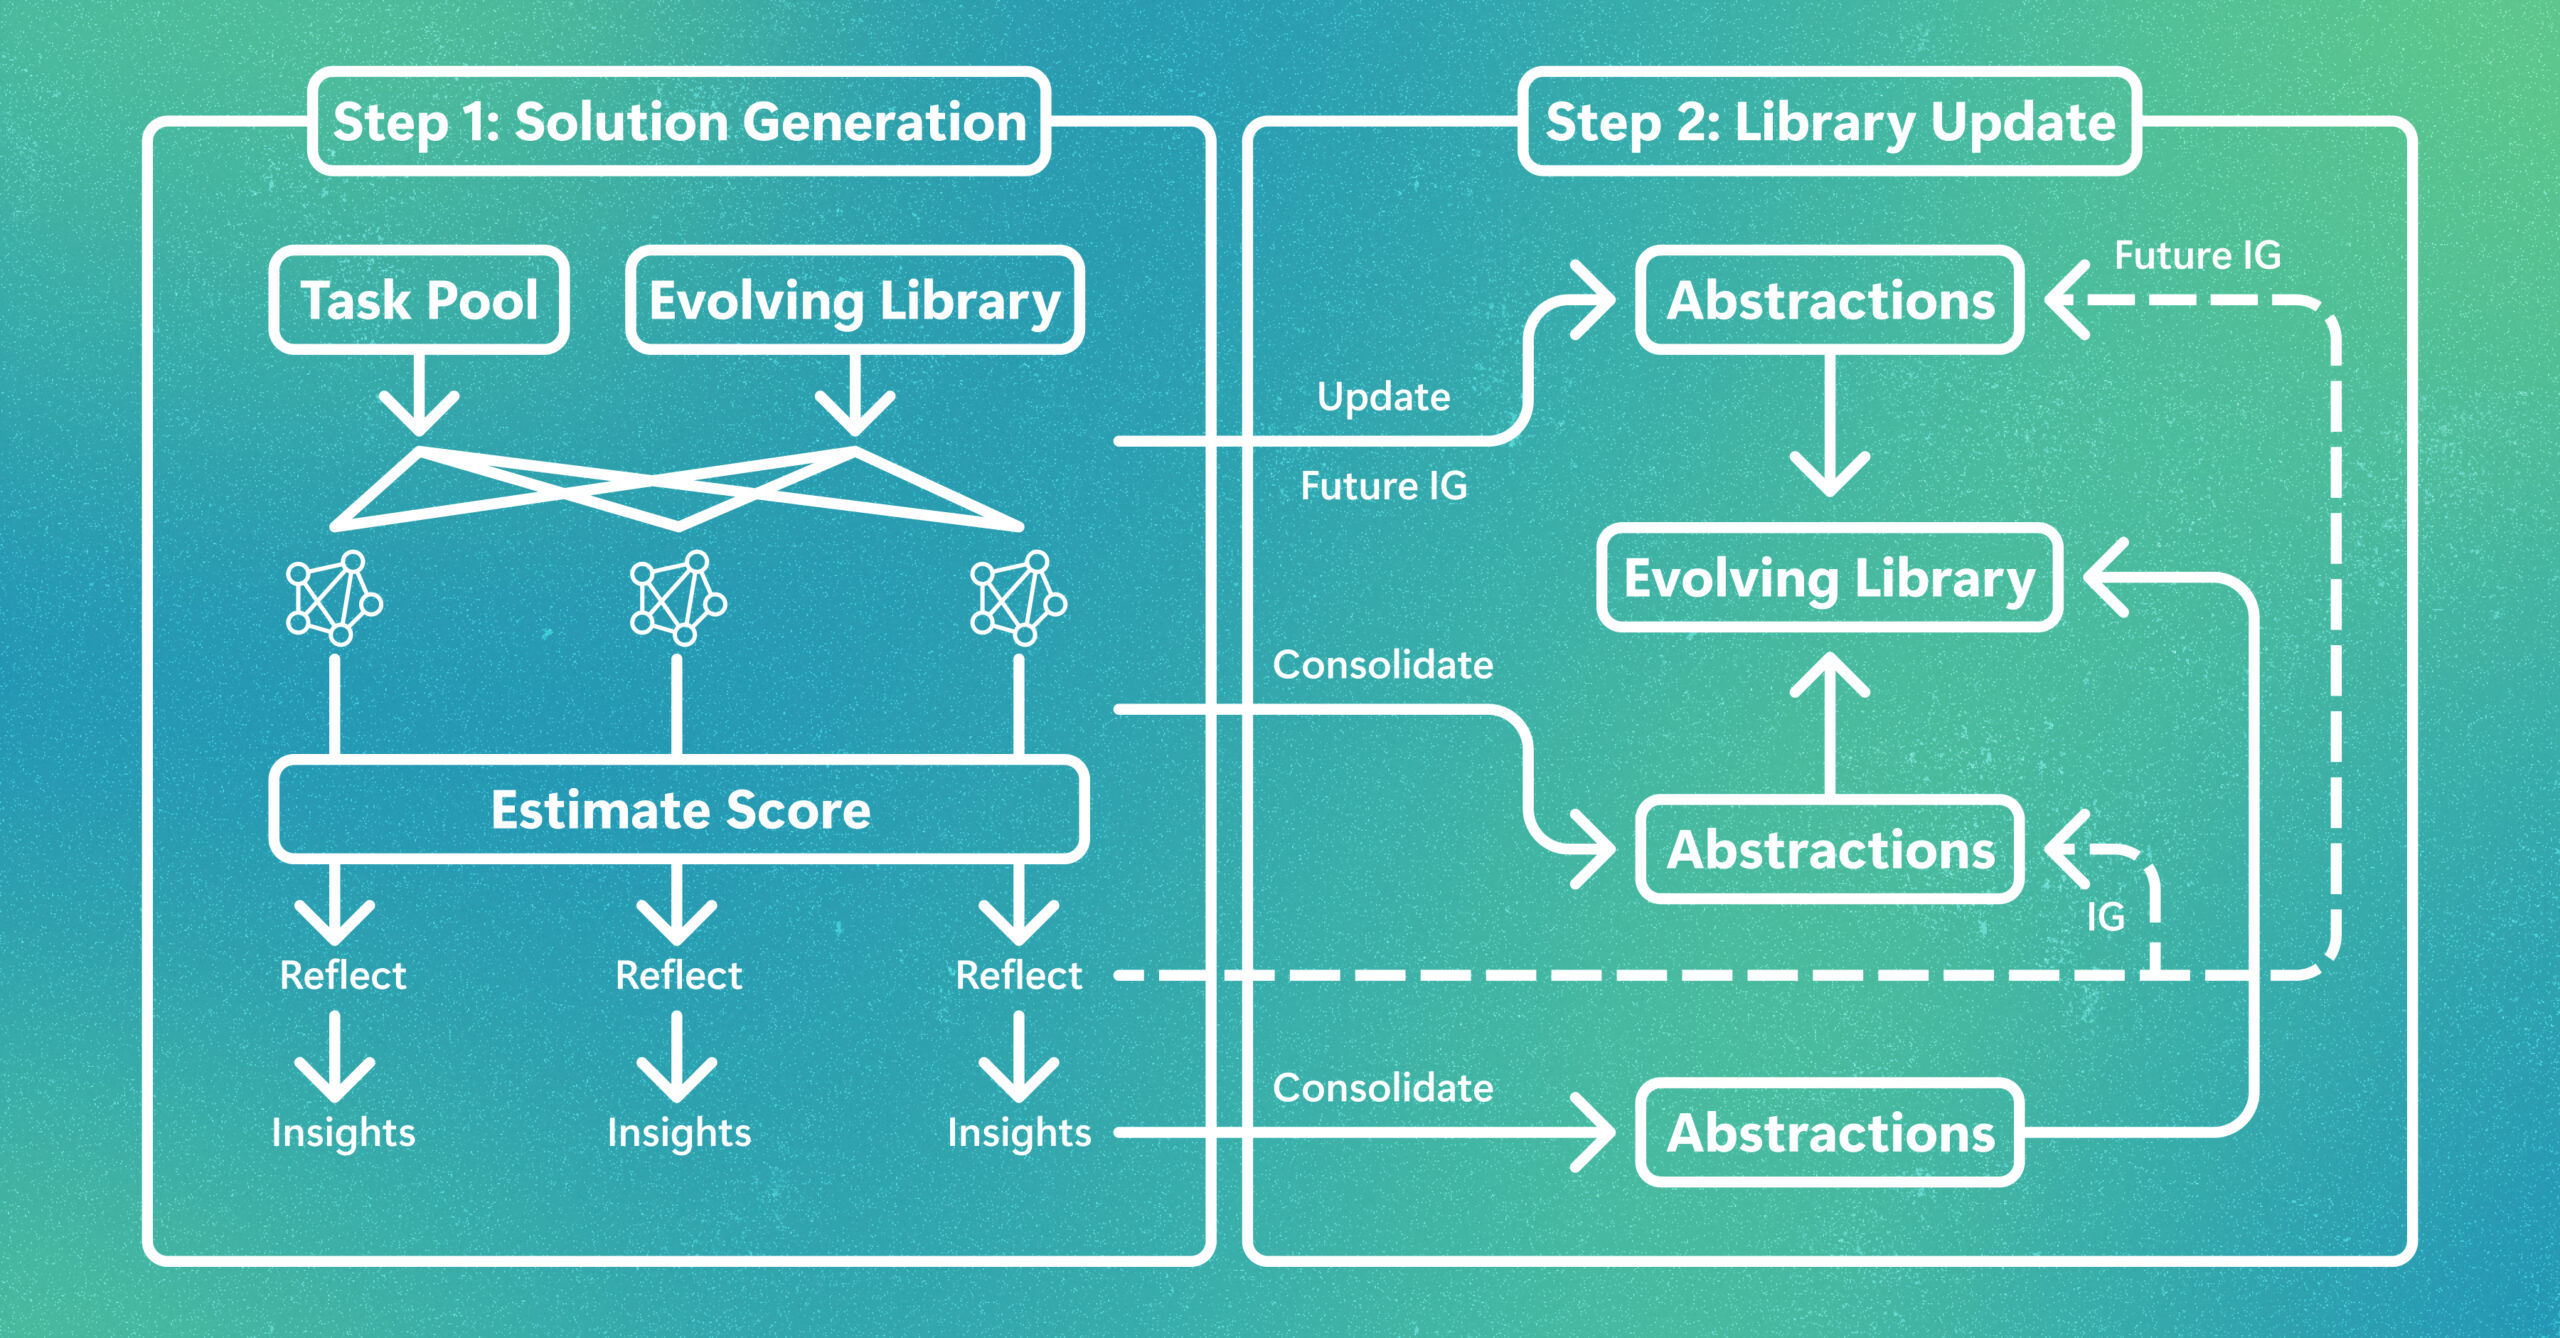
EvoLib: Turning experience into evolving knowledge

LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.