A medical model's benchmark score does not establish that the same conclusion holds under a different evaluation. This study tests whether claims about model ranking, score reliability and screening performance survive changes in cohort, prompt, negative spectrum, specified prevalence and operating threshold. We audit three medical vision-language models (BioMedCLIP, CheXficient, and MedSigLIP) and a general-domain OpenCLIP comparator on 12,200 chest radiograph records from four datasets (Montgomery, Shenzhen, TBX11K, and VinDr-CXR). Five fixed prompt families yield 244,000 model--image--prompt scores. No model leads every cohort and reliability criterion. Prompt-family changes alter AUROC in 21 of 48 multiplicity-controlled comparisons. Replacing healthy controls with sick non-tuberculosis controls reduces AUROC by 0.075--0.306 across all four models. On VinDr-CXR, the three medical models distinguish tuberculosis from no-finding controls substantially better than from pneumonia or lung tumor; their AUROC point estimates for both named diseases fall below 0.5. CheXficient has documented VinDr-CXR pretraining exposure, which limits the interpretation of its results. Thresholds chosen for 95\% sensitivity on TBX11K training retain that constraint by point estimate in only four of sixteen target evaluations. A five-seed supervised source model reaches 0.999 AUROC on TBX11K validation but 0.629 on each of two external cohorts. Conservative exclusion of perceptual-overlap candidates narrows this gap without closing it. These retrospective, single-task results show that discrimination, score reliability and threshold retention support different portability claims. Evidence for chest X-ray tuberculosis screening should identify the complete evaluation specification rather than attribute clinical portability to a checkpoint alone.
Open tuberculosis (TB) chest X-ray benchmarks can reward acquisition-source recognition instead of disease recognition: the same model can look excellent or weak depending only on the evaluation split. Models routinely report AUROC above 0.95 on these benchmarks yet degrade at deployment sites. We audit five widely use...
This work introduces Multi-Context Chest X-ray (MC-CXR), a benchmark of 240 cases expanded into 2,522 instances that isolates context-induced disruption through paired perturbation and evaluates ten VLMs spanning open-source general, medical-domain, and closed-source systems.
Junhyeok Lee, Songsoo Kim, Kyu Sung Choi· 0 citations
Medical image foundation models can predict clinical phenotypes from computed tomography (CT), but strong performance leaves open whether they read disease-specific findings or shortcuts that correlate with the diagnosis. We tested this in 221 electronic-health-record (EHR) phenotypes using Auditable CT phenotyping (AC...
Riga Wu, W. Witschey, Yi-Cheng Li et al.· 0 citations
Foundation models have recently demonstrated strong capabilities across a wide range of medical imaging tasks. However, their performance in structured clinical interpretation settings remains insufficiently explored. In lung cancer screening, interpretative variability persists despite standardized frameworks such as...
B. Renoust, P. Baudot, T. Foriel et al.· 0 citations
Biomedical machine learning papers often compress model performance into one headline number. That number can look like a property of the model even when it depends strongly on how the benchmark was evaluated. We study this problem on the widely used Kermany pediatric chest radiograph dataset using nine image classifie...
Bhanu Prakash Vangala, S. Guda, Latha Peddi et al.· 0 citations
VITA's advantages in accuracy and completeness persisted under the neutral judge; its communication scores were lower, and this results indicate that a purpose-built clinical RAG system remains competitive with frontier LLMs on an open benchmark, consistent with corpus specificity as a design variable that improves gro...
P. Reddy, C. Mandke, Suvrankar Datta et al.· 0 citations
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
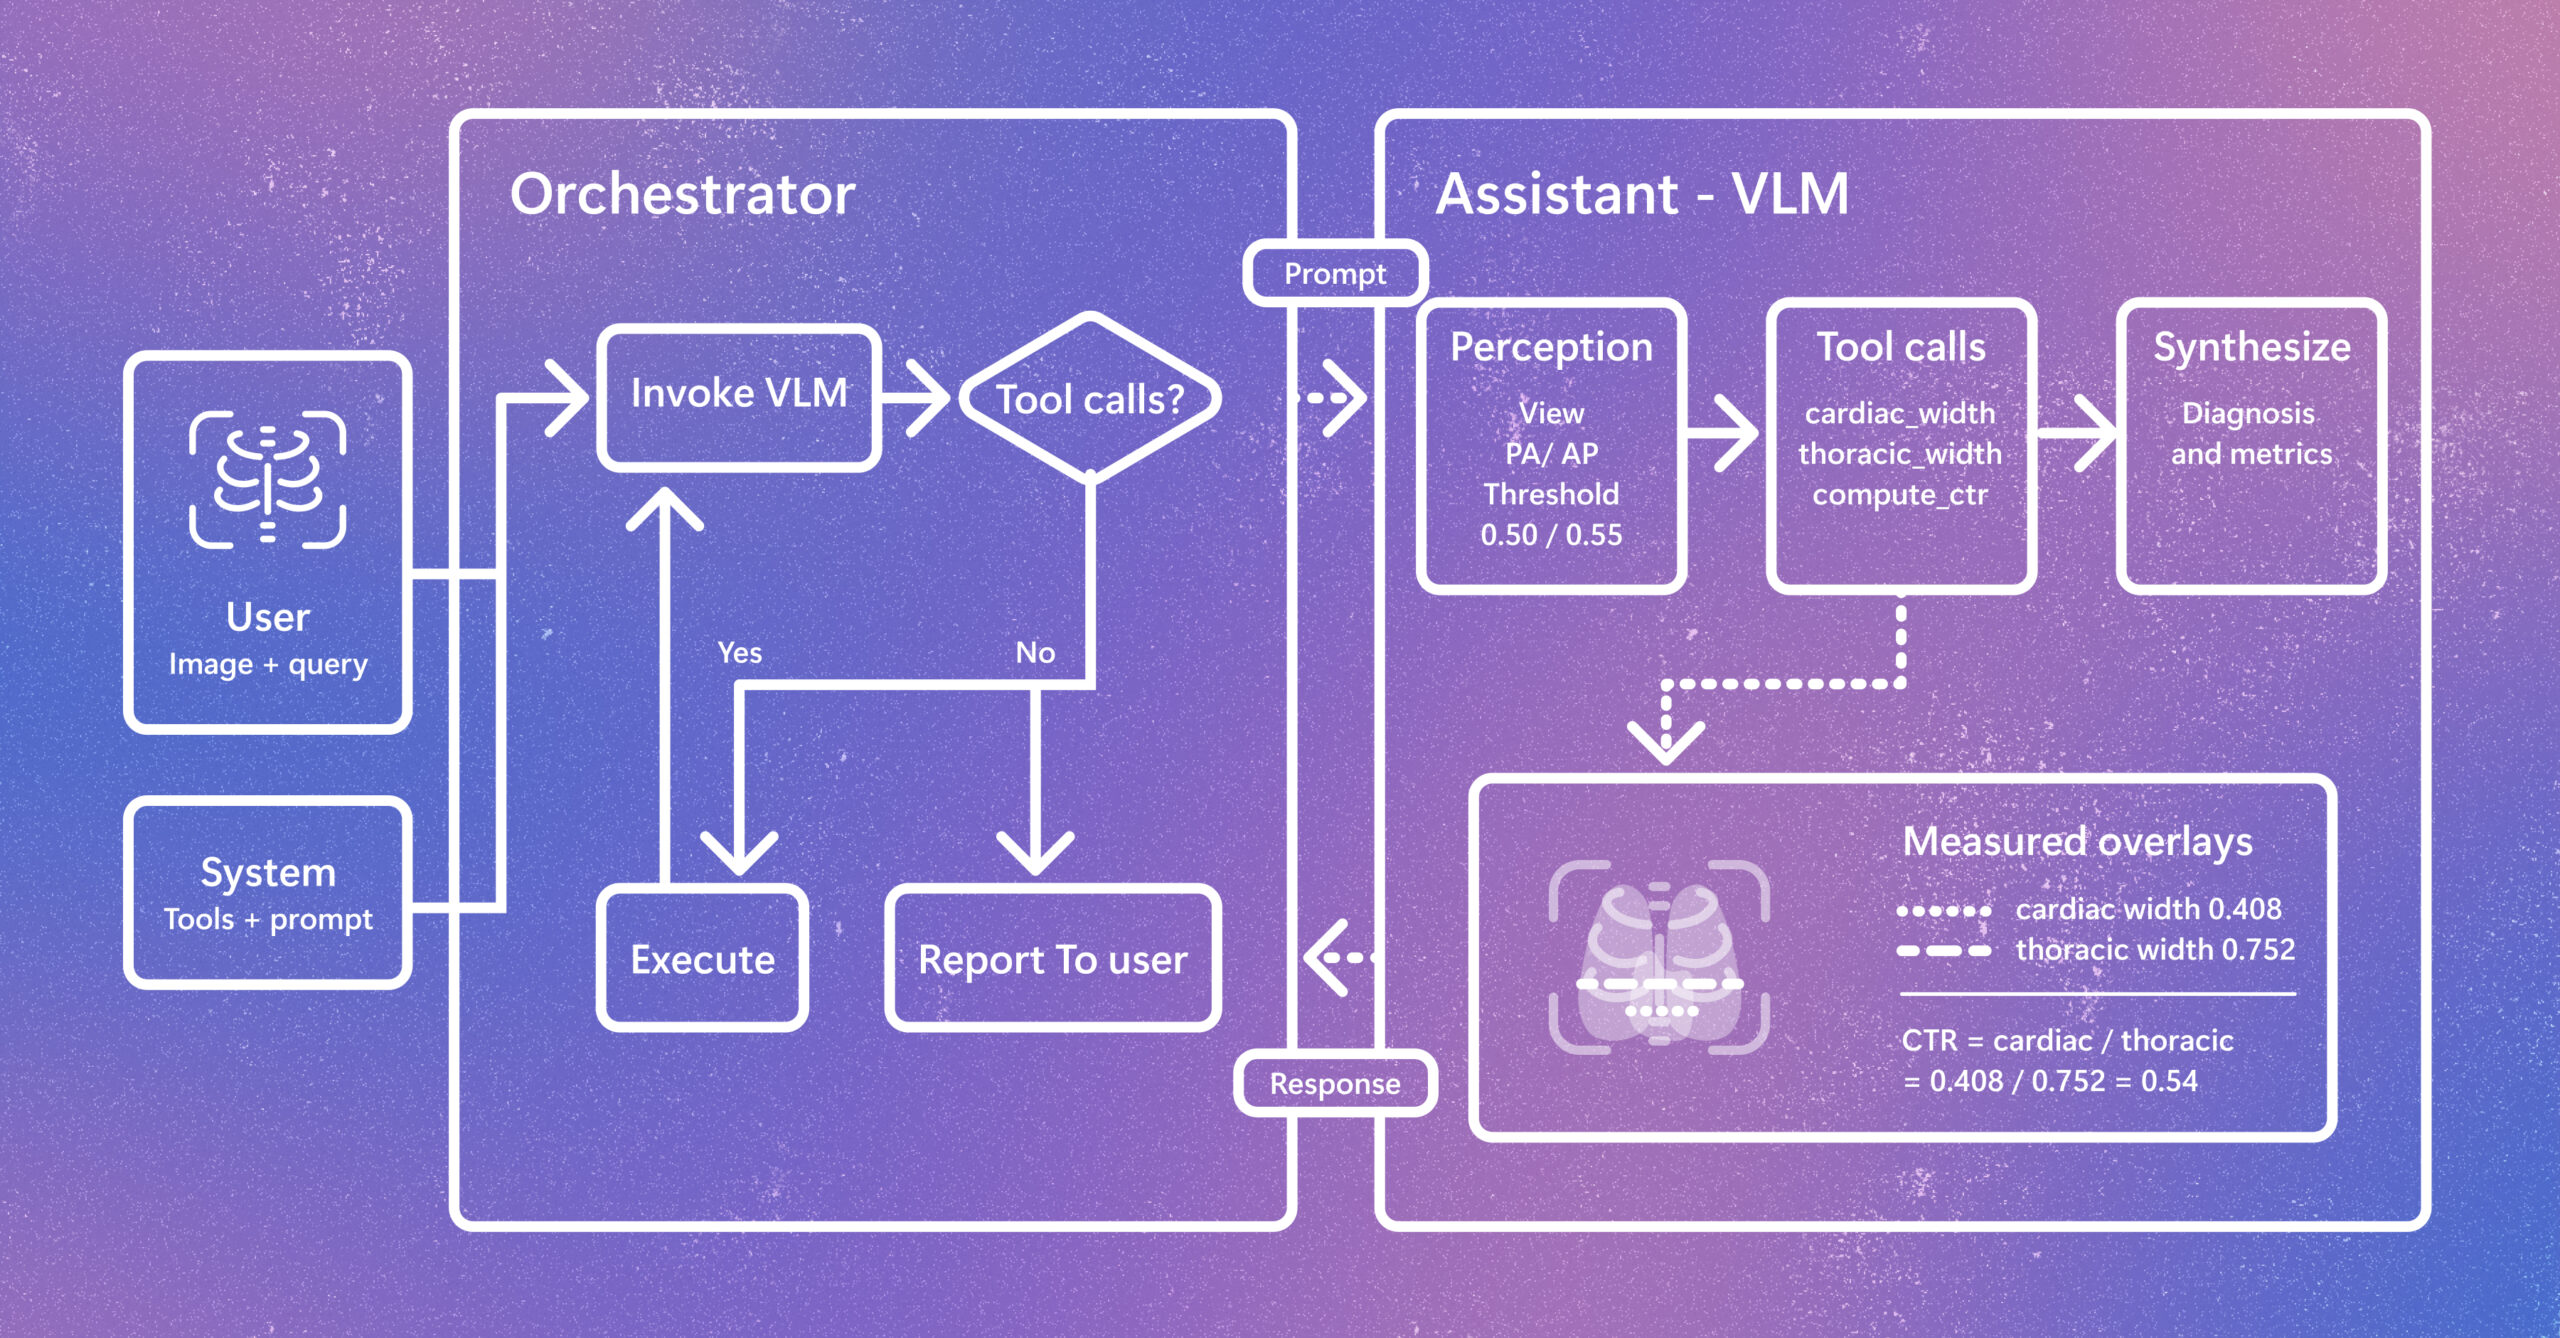
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.