Biomedical machine learning papers often compress model performance into one headline number. That number can look like a property of the model even when it depends strongly on how the benchmark was evaluated. We study this problem on the widely used Kermany pediatric chest radiograph dataset using nine image classifiers and a controlled evaluation protocol. Under the same protocol, the eight pretrained backbones differ by only 0.026 AUROC. In contrast, changing whether the backbone is frozen or fine-tuned changes AUROC by 0.044 on average, and changing the decision threshold changes balanced accuracy by 0.090 on average. The official test split is also measurably different from the training pool: a partition classifier distinguishes them at AUC 0.697, rising to 0.898 for normal radiographs. Most strikingly, a classifier using only file properties, with no image anatomy, reaches 0.992 balanced accuracy within the training pool but falls to 0.496 on the official test split. Validation-fitted thresholds and calibration also transfer imperfectly. These results show that a high benchmark score can support different conclusions when the split, training policy, threshold, metric, calibration, and uncertainty are not communicated with it. We end with a seven-item reporting recommendation in which each item is tied to an effect measured in the study
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
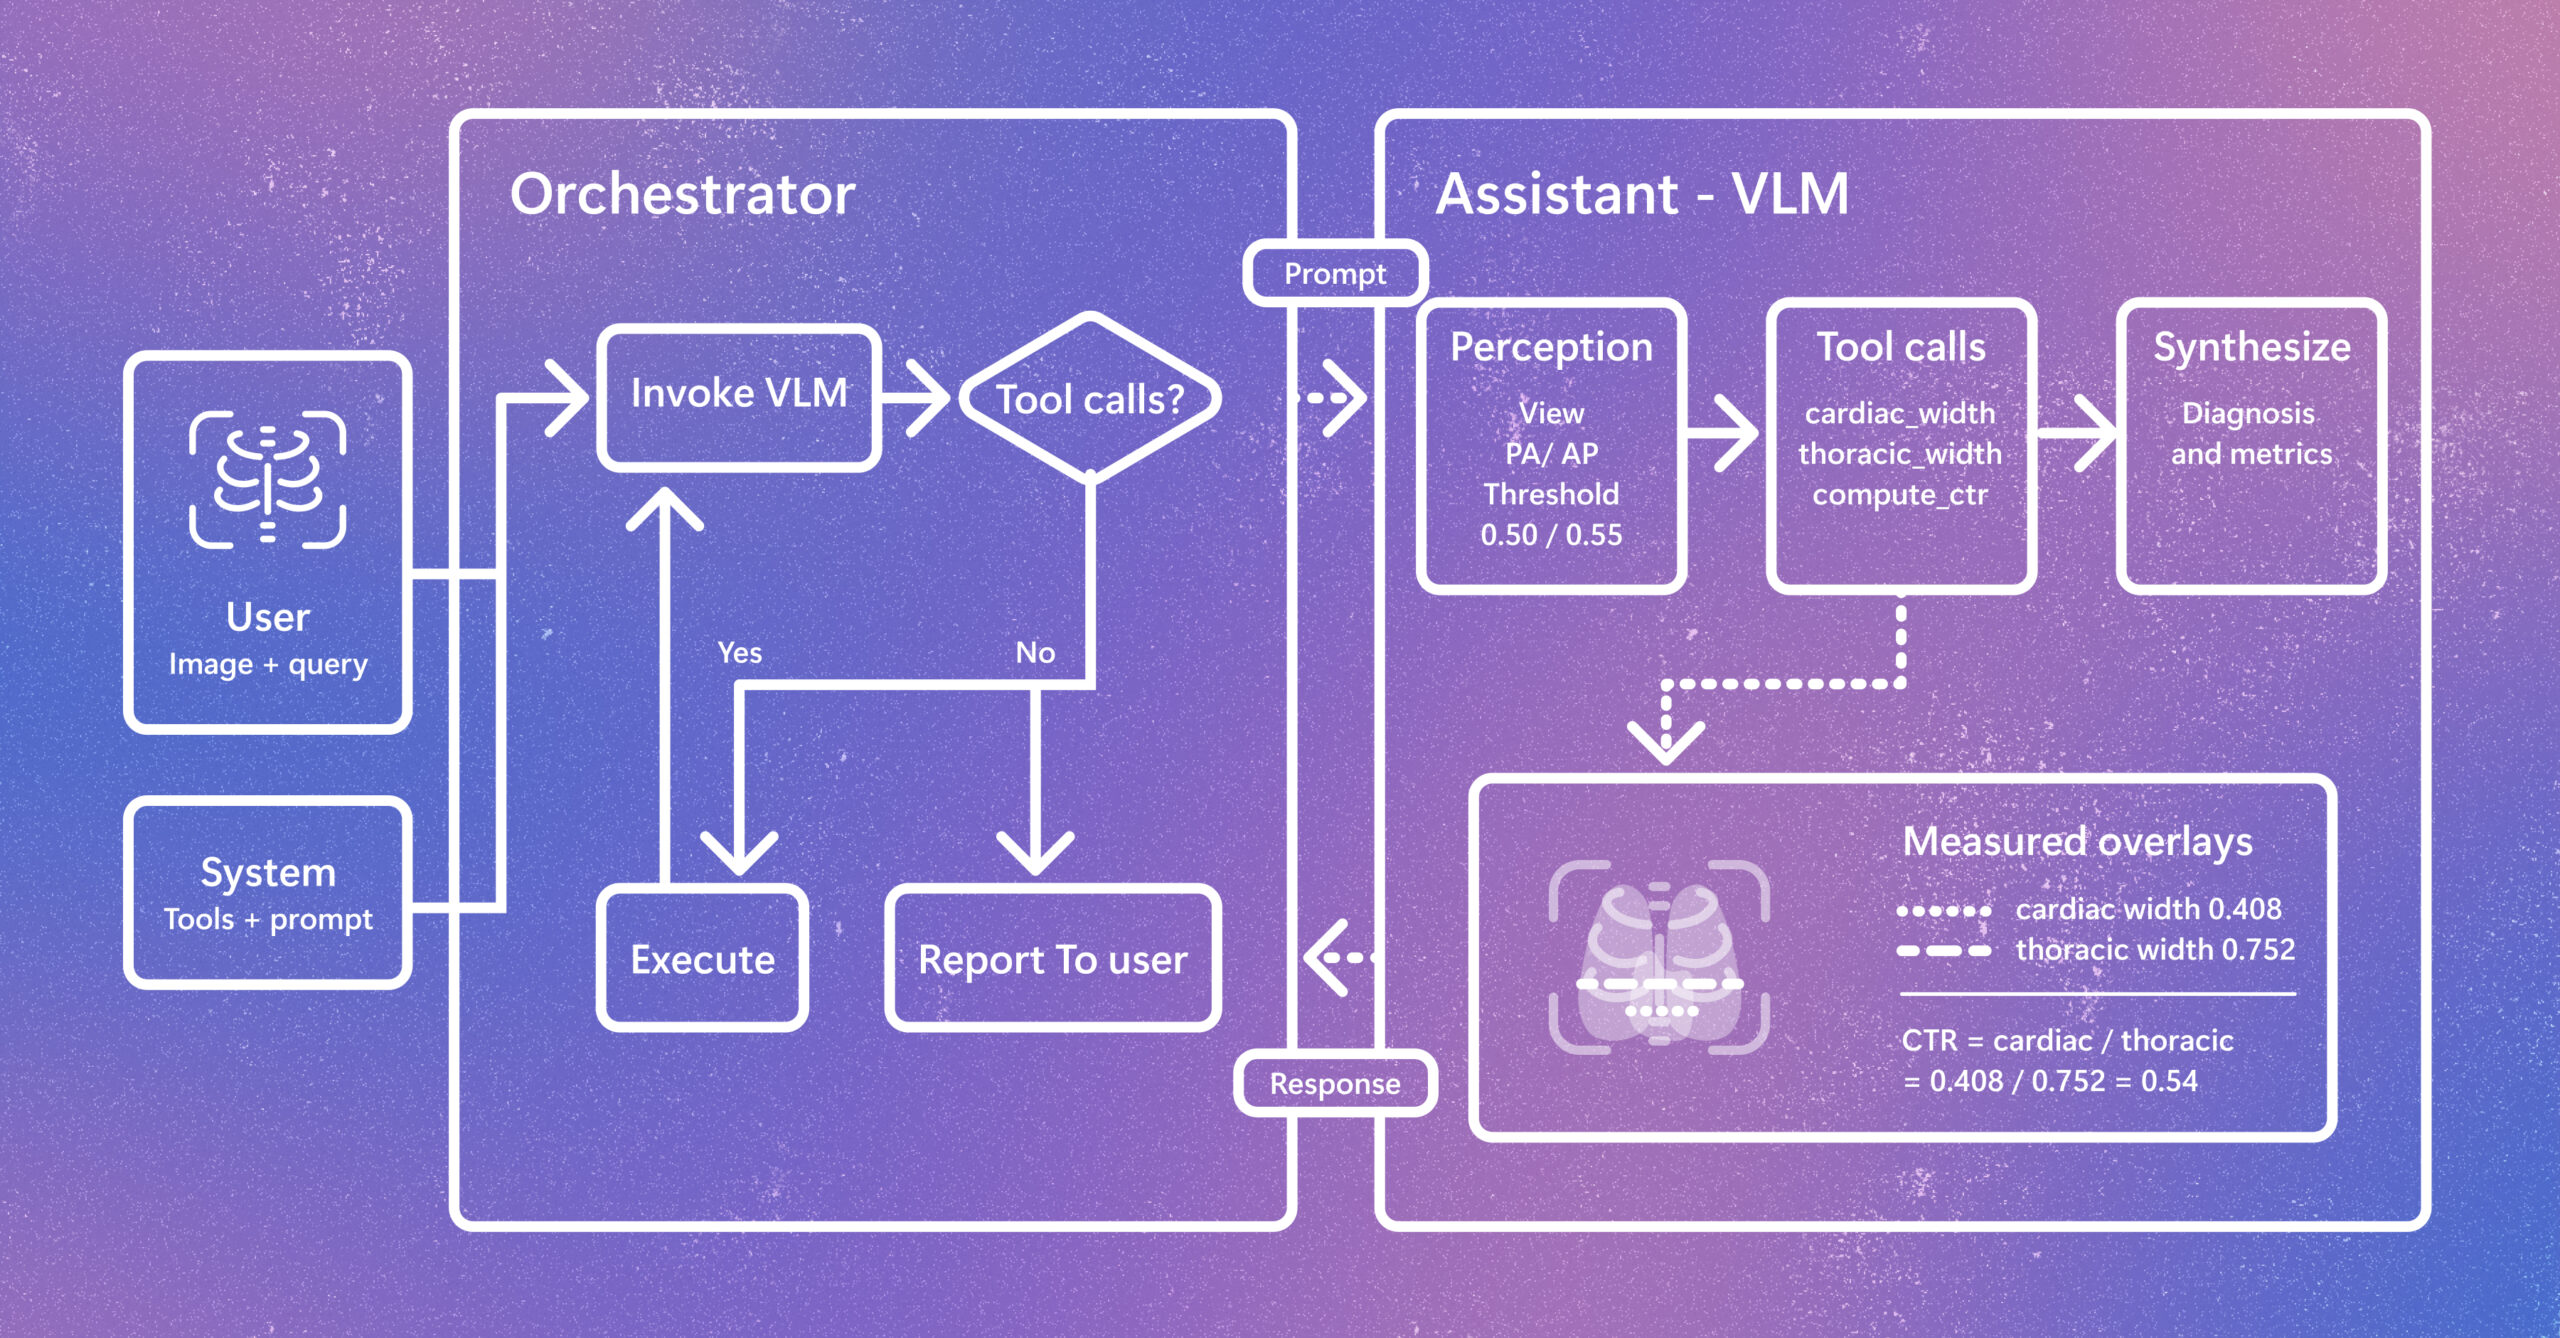
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.