Oct 2026· ACM Transactions on Architecture and Code Optimization (TACO)· 0 citations· 31 references
Advanced Graph Neural Networks
TL;DR
PipeGNN is proposed, a bandwidth-efficient GNN accelerator whose streaming microarchitecture sustains this dataflow as a fully concurrent pipeline within a fixed on-chip buffer budget, and resolves four coupled microarchitectural barriers through coordinated mechanisms.
Abstract
Graph Neural Networks (GNNs) have become a fundamental tool for learning over graph-structured data. Under the message-passing framework, mainstream GNN models alternate between feature transformation and neighborhood aggregation. Fusing these two phases into a node-level pipelined push dataflow, in which each node’s transformed feature streams directly into aggregation, establishes a single-pass I/O target that reads each input tensor exactly once per layer. No existing hardware sustains this dataflow at full concurrency. Prior fusion accelerators fall short of this target in three ways: designs that gather the raw input features for aggregation or write transformed features off-chip incur redundant traffic, designs that stream transformed features on-chip still keep the two phases as separate matrix kernels without a unified execution granularity, and the designs that aggregate at message granularity serialize per-destination aggregation or allocate state that does not scale to large graphs. We propose PipeGNN, a bandwidth-efficient GNN accelerator whose streaming microarchitecture sustains this dataflow as a fully concurrent pipeline within a fixed on-chip buffer budget. PipeGNN decouples execution from topological boundaries by aligning execution granularity with both memory burst size and aggregation compute throughput, and resolves four coupled microarchitectural barriers through coordinated mechanisms: compute-aligned edge batching, contention-aware message reduction, adaptive cross-batch scheduling, and tiered state residency. Evaluated across diverse GNN workloads, PipeGNN achieves geometric mean speedups of 10.1 × over AWB-GCN and 12.2 × over FlowGNN, and 2.4 × to 46.9 × over a GPU baseline across graph scales, reduces off-chip traffic by 2.69 × over AWB-GCN and 5.93 × over FlowGNN, and improves energy efficiency by 56.81 × over AWB-GCN and 1.53 × over FlowGNN, with a 154 × traffic reduction and a 116.81 × energy reduction against HyGCN.
This work proposes FIBER, a new architecture that extends the GPU SIMT (single instruction, multiple thread) model, and extends the ISA, microarchitecture, and compiler to realize shared-register addressing, conflict-free operand delivery, and fiber-based program mapping.
Zi-Han Liu, Jingwen Leng, Yang-Jie Zhou et al.· 0 citations
Tiga is presented, a just-in-time compiler that separates the definition of a message-passing program from how its interactions are traversed, computed, and stored, enabling traversal specialization, fusion of relation generation with aggregation, and reverse-mode automatic differentiation.
SemaCredit is presented, a receiver controller that admits each remote-memory operation against a vector of target-resource demands and returns each component when its corresponding HBM, Atomic, or response stage completes, reducing small-operation P99 latency by 52.4% under Atomic contention and 10.2% under response i...
Fan Yang, Jiaqi Liu, Tao Jiang et al.· 0 citations
Graph Neural Network (GNN) inference involves two successive matrix operations per layer: a sparse neighbor aggregation (SpMM) followed by a dense linear transformation (GeMM). The conventional two-step execution materializes a large intermediate matrix Z in main memory, incurring significant memory traffic that domina...
Xiao Yan, Haodong Bian, Xiao-Ying Wang et al.· International Conference on...· 0 citations
Communication has become a bottleneck in distributed training and inference of large models. Overlapping communication with computation at the granularity of kernels, on separate streams, reduces only part of this communication cost. Fused kernels often have better performance by transmitting each output tile as soon a...
Zi-Ming Mao, Yi-Han Zhang, S. W. Chew et al.· 1 citation
DCSR-GCN, a high-performance GCN accelerator based on dynamic compression and sparsity reordering based on dynamic compression and sparsity reordering, is presented and a two-phase reordering algorithm that combines conflict-aware row scheduling with reuse-aware column grouping is proposed, thereby mitigating RAW confl...
Jun-Sheng Chang, Yi-Min Zhao, Yu-Xin Huang et al.· ACM Transactions on Design A...· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comJul 13, 2026
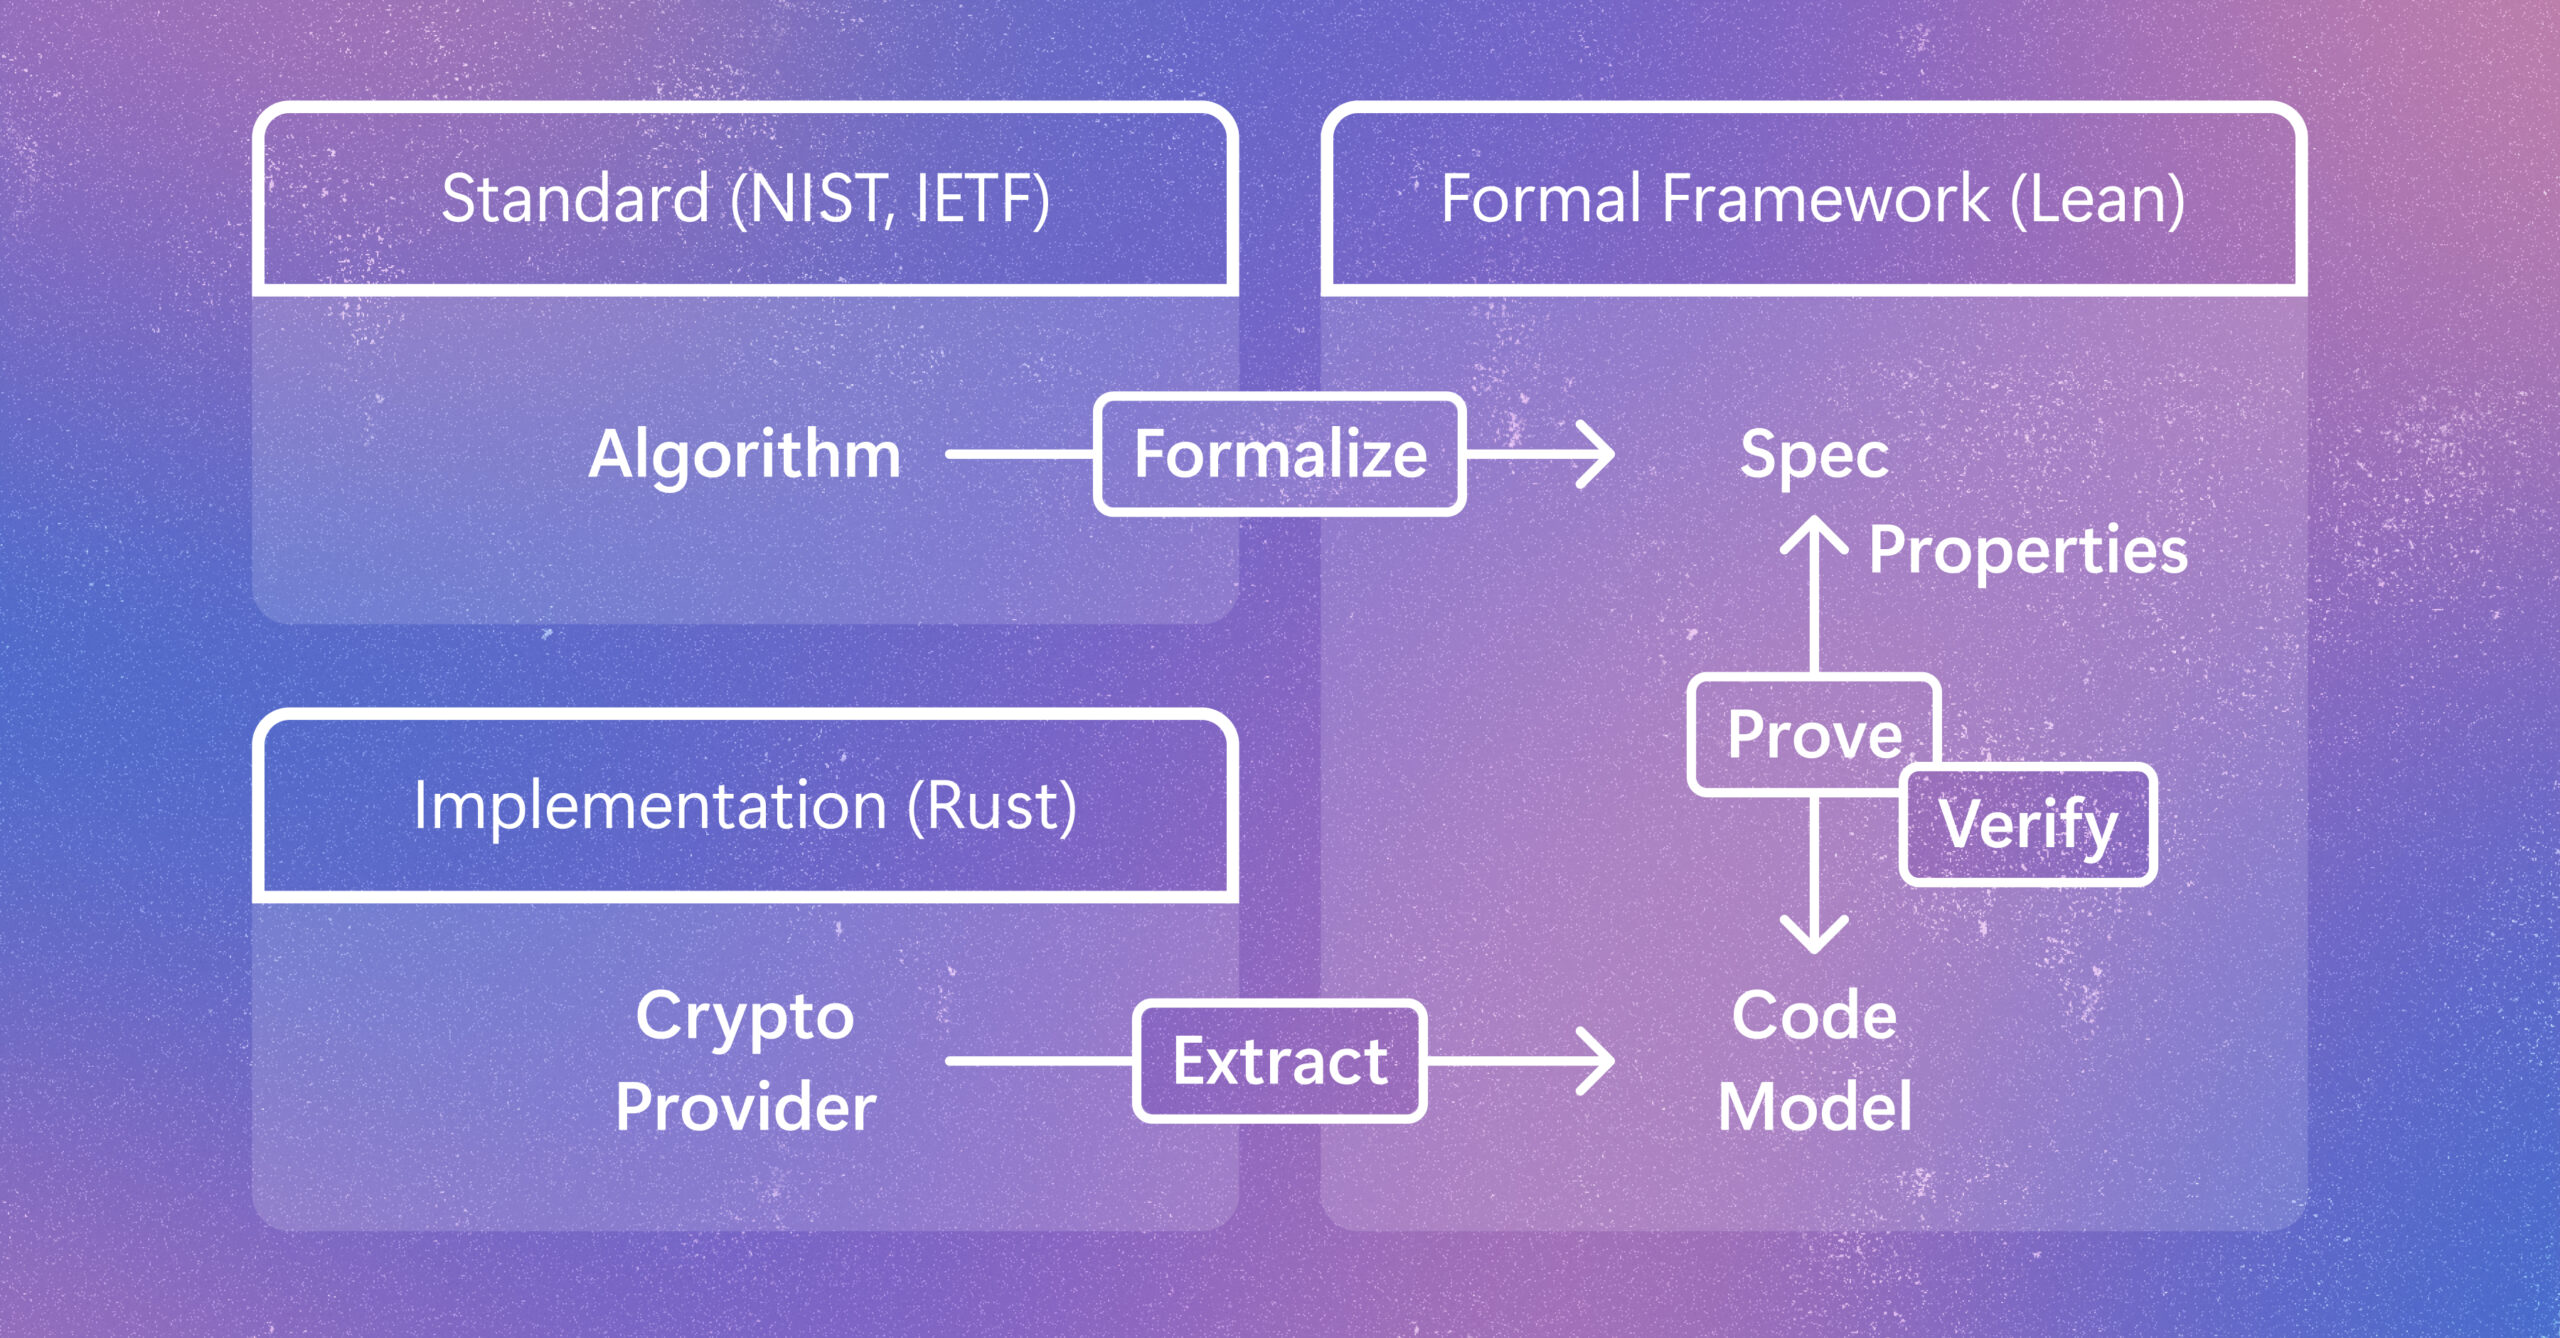
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.