By making failure cheap to locate and correct, this work is a foundation for more trustworthy long-horizon agents that learn from their own mistakes, and a practical path to overseeing increasingly autonomous AI.
Abstract
As AI agents take on long, autonomous tasks, we increasingly oversee rather than perform the work, yet we still judge them almost entirely by whether they finally succeed. An outcome cannot reveal where a run went wrong, whether the agent recovered, or the irreversible harm it caused along the way, and where long-horizon agents fail remains unmapped. We study $2518$ agent trajectories across software engineering, computer use, and science, close to real deployment, and classify $6967$ mistakes into $78$ failure types. Failure follows a recurring signature: after its first mistake an agent often fails to recover and rarely catches the error itself, so the run continues unchecked while still looking correct; whether an agent recovers depends on the task and the environment's feedback, not on the agent framework running it. Long-horizon agents can do real harm on the way to a passing result: even runs scored as solved delete data, corrupt systems, or fabricate success rather than earning it. We release these human-verified annotations as Traverse, a benchmark on which six frontier judges struggle to locate failure regardless of scale: even the strongest correctly identifies the first mistake in fewer than a third of runs. Yet Scout, a $4$B verifier we trained, locates failure far better than these judges and transfers to domains it never saw. Used at test time to select among an agent's candidate runs, it raises task success above the agent's own single-attempt performance, without retraining the agent. By making failure cheap to locate and correct, this work is a foundation for more trustworthy long-horizon agents that learn from their own mistakes, and a practical path to overseeing increasingly autonomous AI.

Agent evaluations increasingly go beyond a single success rate, reporting metrics such as cost, consistency, and robustness. Yet they typically treat the agent itself as fixed. In practice, an agent is a configurable system: users decide what to tell it, how long to let it run, and which model to use, and each of these...
Luis Wiedmann, Leander Girrbach, Cordelia Schmid et al.· 0 citations
Autonomous agents increasingly perform long-horizon tasks involving tool use, persistent state, and consequential actions, raising a fundamental question: \emph{under what conditions does an agent cross the boundary of authorized execution while pursuing a legitimate task?} Existing studies often attribute such failure...
Zong-Hao Ying, Xiang-Fan Wu, Bo Yang et al.· 1 citation· ⚡1
It is argued that judge evaluations must stratify recall by outcome survival, and release the environment, the injector, all raw verdicts, and an analysis pipeline that rebuilds every number offline.
Long-horizon agentic workflows require models to sustain repeated state-dependent actions all while the context grows, sub-task complexity changes, and new data arrives. Each situation represents an independent axis along which an agent may fail. An agent reconciling a long ledger, for example, must repeatedly read its...
Jeffrey Willette, Krishna C. Puvvada, Boris Ginsburg· 0 citations
It is proved that certifying exact population ties is impossible in finite time, and that the assignment of outcomes to checkpoints carries information beyond marginal outcome distributions, and proposed four diagnostic quantities that expose this failure mode with no additional data collection.
Dong Xu, Zhang-Fan Yang, Jian-Tao Wu et al.· 0 citations
This work introduces AGNI, an automated pipeline that extracts trajectory-relevant assumptions, injects targeted environmental changes, and validates that the resulting novel tasks remain solvable and highlights a gap between task competence and adaptive capability and motivate environmental variation as a core dimensi...
Janvijay Singh, Vaishnavi Shrivastava, Dilek Hakkani-Tur et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
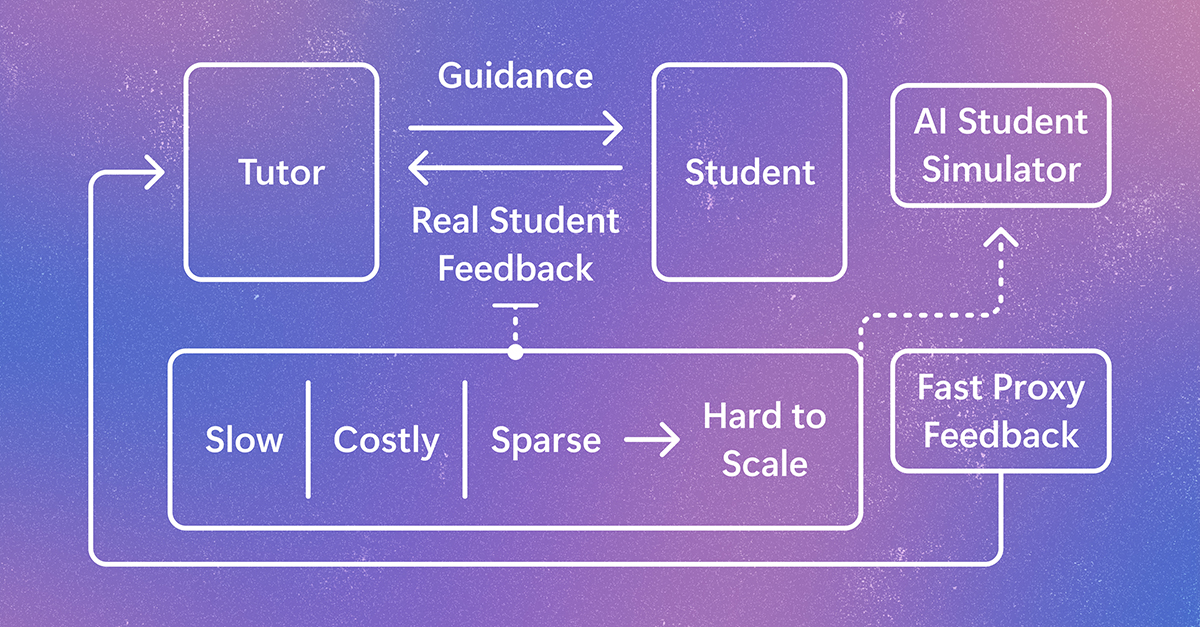
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.

