This work systematically sparsify SparseTalk's semantic embeddings, including the previously underexplored regime below a single image-equivalent block down to 8 visual tokens, and introduces an object-based sparsification method that distributes the token budget across detected object instances while retaining background context.
Abstract
3D Gaussian language fields provide an explicit, spatially grounded representation for 3D visual question answering (VQA), but their dense semantic features can require tens of thousands of embeddings per scene, resulting in substantial storage, memory, and inference costs. We investigate how much of this representation is actually necessary for downstream reasoning. Starting from a full embedding representation, we systematically sparsify its semantic embeddings, including the previously underexplored regime below a single image-equivalent block down to 8 visual tokens. We compare random, geometric, semantic, and joint spatial-semantic selection strategies and introduce an object-based sparsification method that distributes the token budget across detected object instances while retaining background context. Experiments on ScanQA and MV-ScanQA reveal substantial redundancy in dense Gaussian language fields. Strong VQA performance is retained with only a few hundred semantic embeddings, corresponding to less than 1% of the original representation. Object-based selection performs well relative to others, with only modest observed changes down to 256 tokens. At this budget, SparseTalk retains 0.80% of SplatTalk's 32,076-token inference input and 0.332% of the mean 77,207-Gaussian dense field, increasing inference throughput while reducing decoded-feature memory 125-fold.
This work proposes a segmentation framework guided by Contrastive Language–Image Pre-training (CLIP) that enriches sparse 3D tokens with vision–language semantic priors and introduces a decoupled CLIP-induced semantic residual that forms semantic-geometric attention biases for local window attention.
It is shown that spatial coverage is associated with 3D reasoning performance and CoVeR, a deterministic, training-free selector that uses only token coordinates, with no learned signals is introduced, which outperforms prior SOTAs on all three 3D reasoning benchmarks and generalizes as a plug-and-play module tested ac...
The results show that format-valid responses can mask failures to recover the spatial structure required for verifiable visual inference, and that format-valid responses can mask failures to recover the spatial structure required for verifiable visual inference.
Pretrained 3D encoders are typically developed on globally reconstructed scenes expressed in a consistent world coordinate frame, whereas embodied systems must reason from partial, viewpoint-dependent observations in camera coordinates. We show that this shift from globally learned 3D feature spaces to realistic partia...
Akira-Miranda Adeyomi Adeniran-Lowe, B. Singh, Lars Arnold Dethlefsen et al.· 0 citations
Reasoning about the 3D world from multi-view images remains a fundamental challenge for Multimodal Large Language Models (MLLMs). While modern MLLMs handle single-image inputs effectively, they struggle to integrate evidence across viewpoints into a coherent 3D understanding. A growing body of work attempts to close th...
Jaewoo Jung, Hyeonseo Yu, Honggyu An et al.· 0 citations
EviSplat is introduced, which preserves individual observation features as evidence for later text queries within class-agnostic 3D instances that represent objects, object parts, or background regions and learns a distribution describing which visual appearances its observations support.
Sung-Ho Moon, Kota Shimomura, Junwoo Park et al.· 0 citations
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
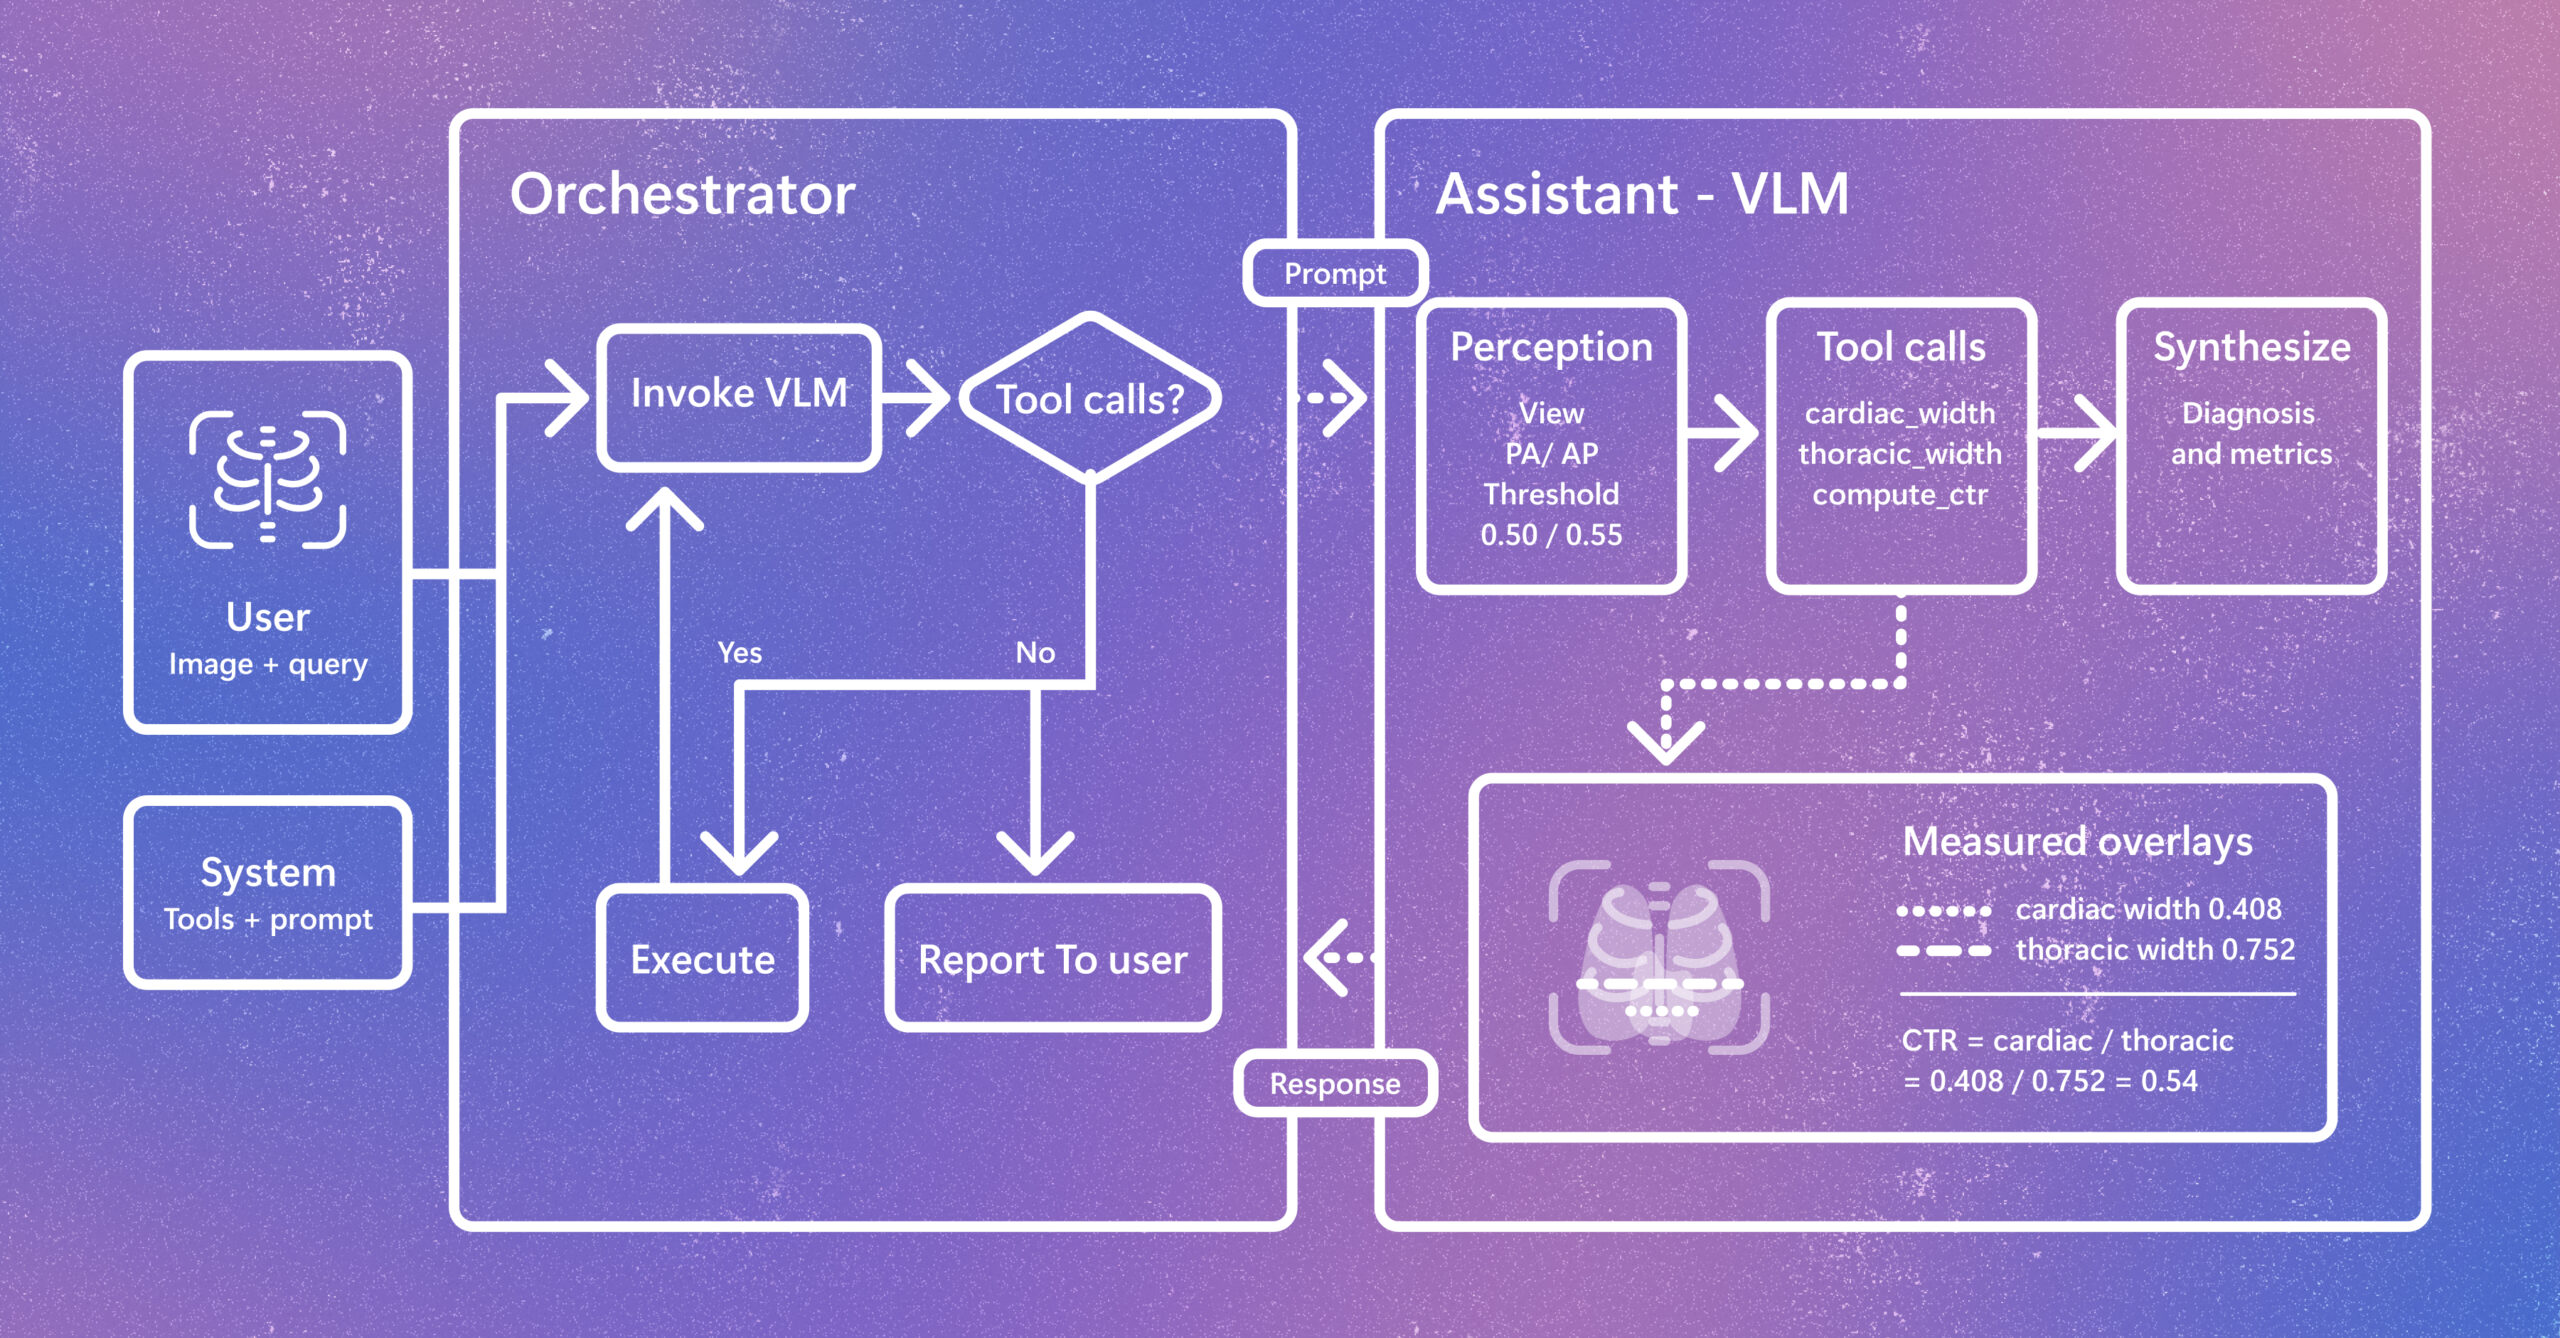
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.