It is shown that spatial coverage is associated with 3D reasoning performance and CoVeR, a deterministic, training-free selector that uses only token coordinates, with no learned signals is introduced, which outperforms prior SOTAs on all three 3D reasoning benchmarks and generalizes as a plug-and-play module tested across four VLMs.
Abstract
Representing a 3D scene as multi-view images allows 2D VLMs to reason in 3D by reusing priors from pre-training, sidestepping the scarcity of annotated 3D data. However, it produces thousands of redundant visual tokens whose cost grows with every view. Existing visual token pruners fall into two families, each limited in the 3D multi-view setting. Learned importance methods rank tokens by attention or encoder features; because redundancy here is fundamentally spatial, they keep near-duplicate tokens from a few prominent regions and leave most of the scene unrepresented. Voxelization methods improve spatial coverage but cannot enforce an exact token budget and saturate as multi-view observations overlap in 3D, capping retention well below the target. We show that spatial coverage is associated with 3D reasoning performance and introduce CoVeR, a deterministic, training-free selector that uses only token coordinates, with no learned signals. CoVeR selects tokens that collectively cover every region of the scene, and solves the limitations of both families: it enforces an exact per-scene budget, breaks the voxelization saturation plateau, and avoids the near-duplicate selections of learned importance. Extensive experiments show CoVeR outperforms prior SOTAs on all three 3D reasoning benchmarks and generalizes as a plug-and-play module tested across four VLMs. Notably, with only $\approx$8% of visual tokens, it preserves 93.5% of full-token performance, surpassing SOTA by 3.9 percentage points on average across benchmarks.

CoverPrune is introduced, a training-free framework that formulates inference-time token pruning as an Optimal Transport (OT) problem, and the Feature-Spatial-Temporal (FST) transport cost and target capacity, along with an efficient Spatial-Guided Greedy Selection (SGS) algorithm to approximate the OT objective.
Peng Ling, Ying-Da Yin, Ling-Ting Zhu et al.· 0 citations
Illusory matches between distinct yet visually similar 3D surfaces--doppelgangers--remain a fundamental obstacle for large-scale, in-the-wild 3D reconstruction and visual localization. Prior work mitigates this issue with pairwise classifiers, but this design limits multi-view contextual reasoning and incurs O(n^2) inf...
Han-Yuan Xiao, Gong-Lin Chen, Hao-Lin Xiong et al.· 0 citations
Feed-forward 3D vision models such as VGGT have achieved remarkable progress, unifying camera estimation and dense scene reconstruction in a single pass. However, their quadratic global attention makes long image sequences expensive, while existing sparse methods may favor highly attended yet value-redundant regions. T...
Jun-Yi Wu, Fan-Qing Kong, Le-Yang Chen et al.· 0 citations
This work systematically sparsify SparseTalk's semantic embeddings, including the previously underexplored regime below a single image-equivalent block down to 8 visual tokens, and introduces an object-based sparsification method that distributes the token budget across detected object instances while retaining backgro...
Davit Soselia, J. Jaja, Amitabh Varshney· 0 citations
Recent zero-shot 3D visual grounding methods leverage vision-language models (VLMs) to localize objects in 3D scenes from natural language queries. However, these methods typically rely on heuristic rules to select which camera views are provided to the VLM, often prioritizing object visibility rather than grounding re...
Tsung-Chih Chiang, Hsuan-Kung Yang, Jou-Min Liu et al.· 0 citations
Feed-forward 3D Gaussian Splatting reconstructs an explicit Gaussian representation from multiple input images in one network execution, making 3D reconstruction increasingly accessible for casual captures. However, such captures frequently contain transient objects that appear in only a subset of the views. Such conte...
Kangmin Seo, Jae-Pil Heo· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
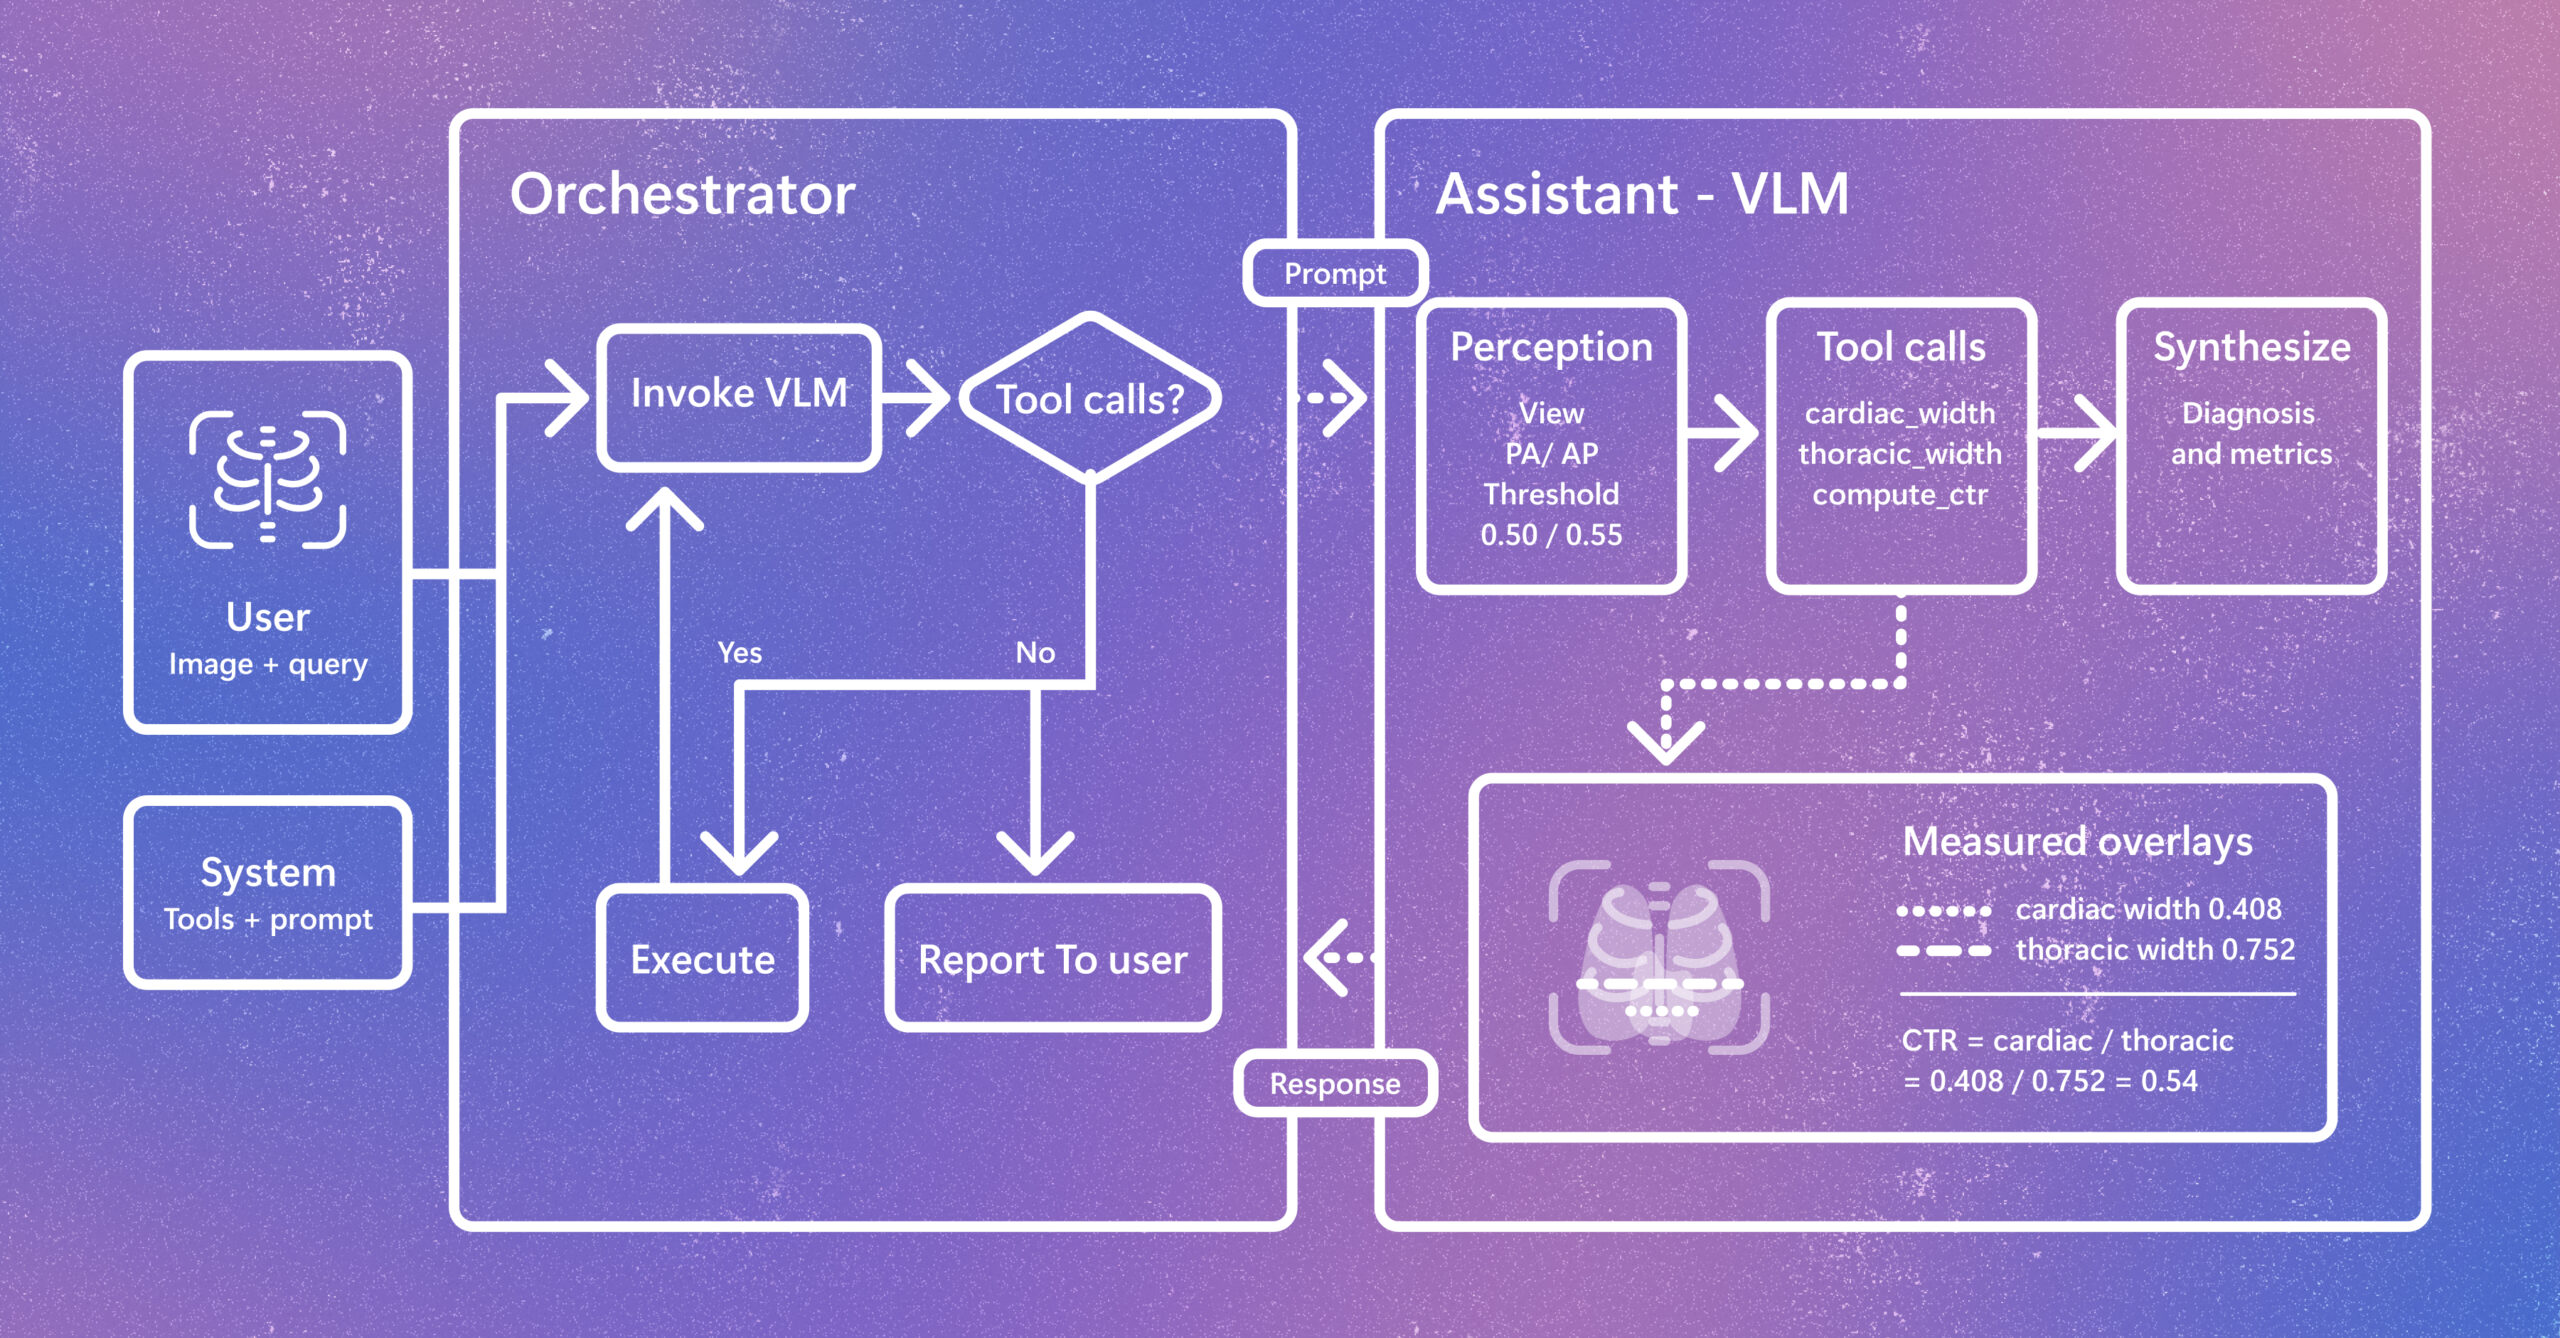
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.