RiVaT-Fuse is proposed, a reliability-calibrated variational tensor fusion framework that defines fusion as sample-wise latent-state estimation and achieves the strongest overall predictive rank among direct representation-level baselines while improving probability and label stability under perturbation.

Abstract
Image-metadata prediction requires fusing heterogeneous evidence whose reliability can vary across samples and latent factors. Existing representation-level fusion methods typically choose an aggregation architecture, such as concatenation, gating, conditional modulation, or attention, without explicitly defining what the fused representation should mean under modality uncertainty. We propose RiVaT-Fuse, a reliability-calibrated variational tensor fusion framework that defines fusion as sample-wise latent-state estimation. Rather than producing a fused vector by direct aggregation, RiVaT-Fuse estimates a consensus latent state through a variational objective that balances image evidence, metadata evidence, structured cross-modal interaction, and stability. The resulting framework replaces scalar modality confidence with matrix-valued trust geometry, decomposes interaction into additive, multiplicative, and relational components, and couples the latent state with conditional robustness and structured multi-task prediction. We provide well-posedness and stability interpretations of the latent solve and instantiate the framework with efficient low-rank-plus-diagonal trust operators. On an image-level image-metadata prediction benchmark, RiVaT-Fuse achieves the strongest overall predictive rank among direct representation-level baselines while improving probability and label stability under perturbation.

This work introduces a framework that applies contrastive or masked objectives at intermediate layers, coupled with source-wise invertible normalizing flows and a supervised, low-rank latent variable model, offering a practical latent-variable lens for characterizing continuous multimodal interactions.
Modality-Conditioned Conformal Fusion is, to the authors' knowledge, the first method with formal coverage guarantees under arbitrary modality availability through architectural integration rather than post-hoc recalibration, and the evidential decomposition yields per-modality vacuity scores that localise uncertainty...
Multi-modal image fusion (MMIF) aims to form a single image by integrating shared information, preserving complementary cues, and coordinating cross-modal conflicts across modalities. However, due to the absence of ground-truth fused images, existing MMIF supervision commonly uses spatial-domain sources or gradient var...
Ze-Yu Wang, Ming-Yu Ge, Hai-Yu Song et al.· 0 citations
Recent pre-trained foundation models provide rich multi-modal priors for downstream 3D vision tasks. However, the effectiveness of these representations in few-shot scenarios is limited by two fundamental challenges: High-dimensional features often contain substantial channel redundancy and task-irrelevant noise, while...
Hang Cheng, Yan Chen, Ming-Yu Fan et al.· 0 citations
A unified latent diffusion framework that addresses both limitations simultaneously, indicating that adaptive modality weighting outperforms fixed conditioning strategies and that modality-dropout training provides an effective partial-conditioning robustness mechanism.
S. Remya, Manu J. Pillai, Laveena Herman et al.· Frontiers in Artificial Inte...· 0 citations
This work proposes Adaptive Evidential Multimodal Representation Learning (AEMRL), a framework aligned with this multi-level view of uncertainty that consistently enhances task accuracy, reduces calibration error, and improves robustness to noise, semantic conflict, and missing modalities.
Yu-Peng Han, Kai Zhang, Xian-Quan Wang et al.· Proceedings of the Thirty-Fi...· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
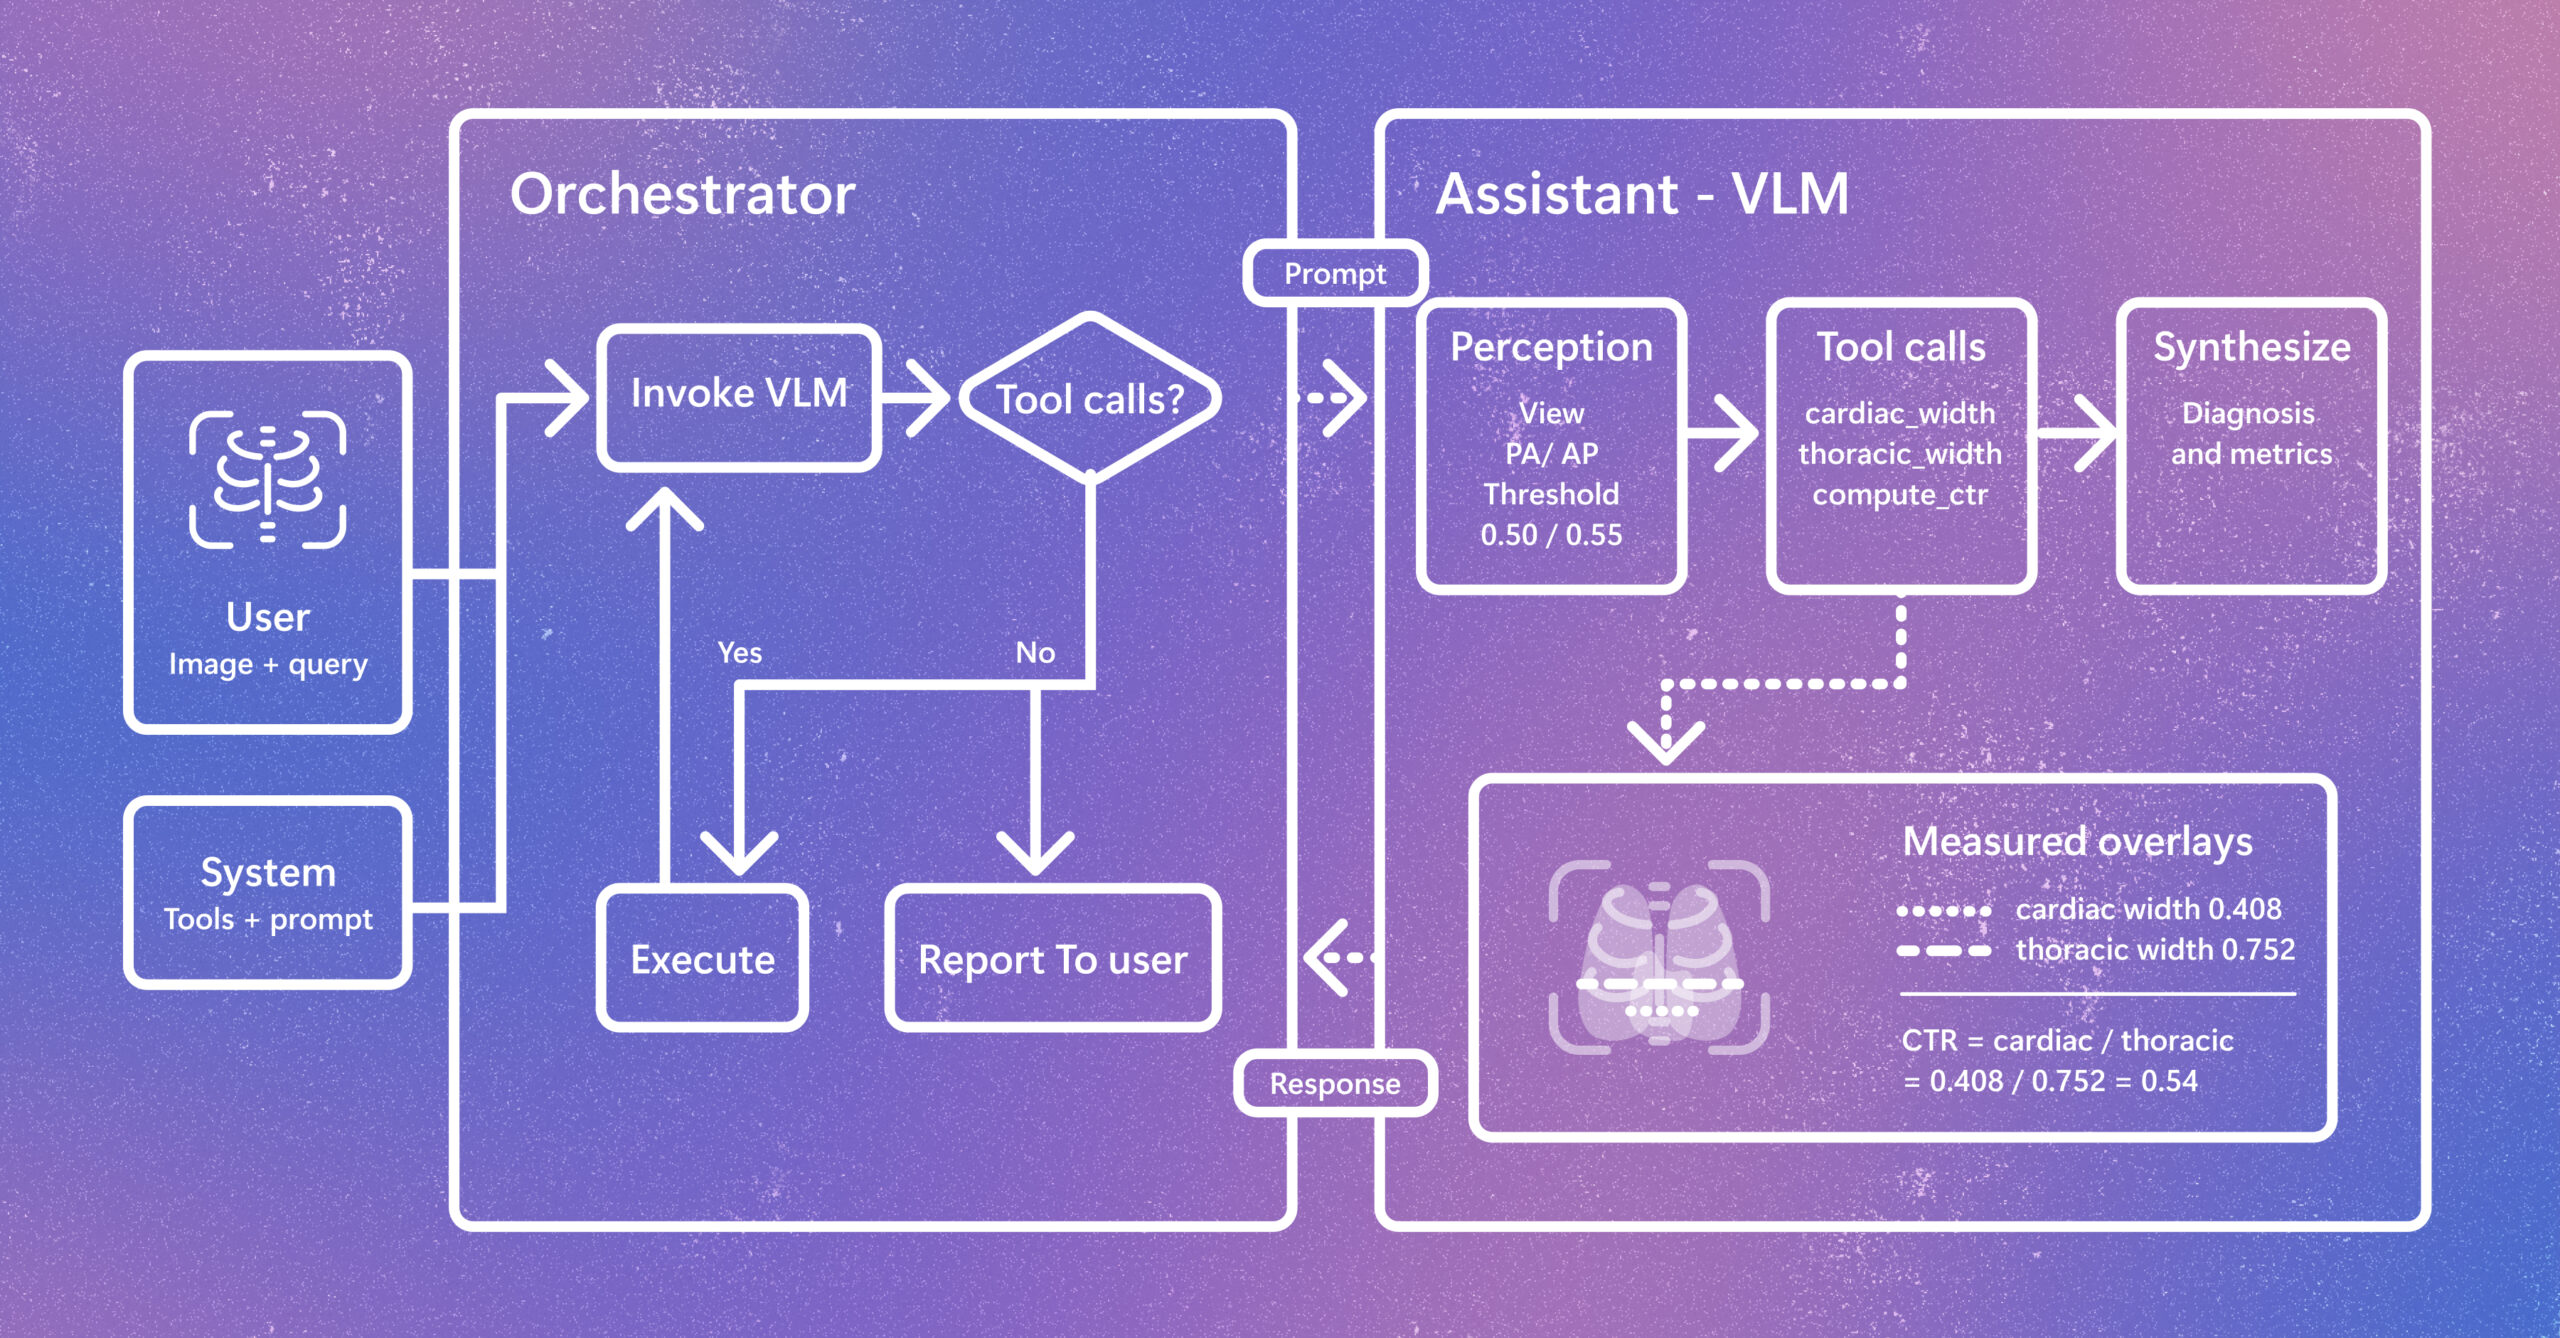
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.