DR-LabStack is designed and implemented, a React-Flask web system integrating four externally developed pretrained models: RuleFit, Pruned RuleFit, Elaborative XGBoost, and Two-level Ensemble, a reusable interaction and serving workflow for heterogeneous DR models.
Abstract
Pretrained diabetic retinopathy (DR) prediction models differ in their input fields, serialization formats, preprocessing requirements, and output semantics. Making these models accessible through a common clinical interface therefore requires explicit coordination between the user interface and the inference service. We designed and implemented DR-LabStack, a React-Flask web system integrating four externally developed pretrained models: RuleFit, Pruned RuleFit, Elaborative XGBoost, and Two-level Ensemble. A shared form retrieves ordered model features, renders model-specific numerical and categorical controls, and constructs a positional input vector. Backend adapters load heterogeneous artifacts and apply the ensemble's accompanying scaler, while a common JSON response supports binary classification display alongside method and source information. Functional evaluation on September 8, 2026 used copied application files and real model artifacts in a documented isolated environment. All four models loaded and exposed their 14-, 6-, 8-, and 25-field contracts. Sixty-two Flask test-client requests characterized service behavior; 12 limited-vector checks confirmed invocation-path and threshold consistency. Twenty-four browser-component scenarios with mocked transport verified input ordering and result rendering and characterized input-validation behavior. The resulting system demonstrates a reusable interaction and serving workflow for heterogeneous DR models. The contribution is web-system design, integration, and software functionality; clinical effectiveness and clinician usability require separate evaluation.
This single-workflow forensic case is an existence proof of a failure mode, not an estimate of its prevalence: existing human work supports an exploratory audit of synthetic proposals, but not LLM-judge operating characteristics, clinical validity, corpus prevalence, or robust inter-annotator agreement.
ViSTA is introduced, a compact adapter that incorporates irregular numerical measurements into a pretrained vision-language model's chart representations and extends pretrained language models to numerical prediction and temporal questions.
Jun-Yi Gao, Yu Shi, Ping-Zhao Hu et al.· 0 citations
The web is now the surface on which most human health information is aggregated, interpreted and acted upon. Hospital portals, national biobank workbenches, consumer wearable dashboards and clinician-facing decision support tools are all, architecturally, web systems that must turn heterogeneous biomedical evidence int...
Rohit Yadav· Natural Resources for Human...· 0 citations
Glaucoma requires continuous surveillance, sustained treatment adherence, and timely recognition of postoperative or treatment-related complications. Conventional outpatient follow-up provides structured clinical assessment but offers limited visibility of symptoms between appointments. This study describes TeleGlaukos...
Jeniffer Jesus, Pedro Cardoso-Teixeira, João Chibante Pedro et al.· Bioengineering· 0 citations
Medical models are judged not only on correctness, but on whether reported confidence matches actual accuracy. Generalist multimodal medical models have expanded what a single model can perceive, yet they still express bounded decisions such as diagnoses, findings or cell counts as generated text, so the reported proba...
Lu-Yao Tang, Cheng Chen· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
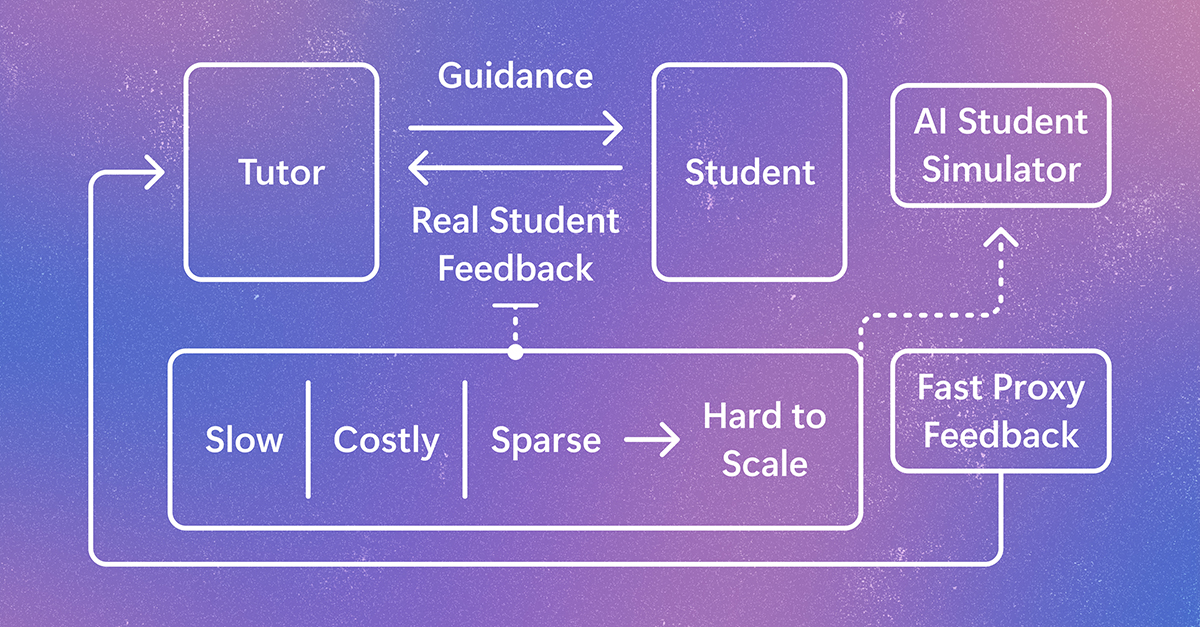
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.


