The audit dataset, the quantcheck acceptance-testing tool, and disclosure reports for every confirmed defect are released, and it is argued that model registries need the acceptance gate that package registries already run.
Abstract
Developers increasingly run large language models locally by pulling quantized GGUF artifacts from public registries, yet nothing in the distribution pipeline functionally tests these conversions before they reach users. We executed 327 quantized code-capable model artifacts: 305 from the official Ollama library, spanning 15 model lines at every eligible quantization level at or under 8 GB, and 22 from the most-downloaded community repositories on HuggingFace. Each ran a 15-task smoke suite calibrated so that healthy artifacts pass while a known-broken one fails; suspects then faced full 164-task evaluation, a second inference backend, an independent distributor's conversion of the same model and quantization as referee, and, for community files, re-testing under the artifact's own template. The official library carries five silently defective artifacts, a batch of four Qwen2.5-Coder-3B conversions and one phi3.5-mini conversion, that solve zero of 164 tasks and zero of the smoke suite on both backends while independent conversions of the same models work: 1.6% of official artifacts, 2 of 29 model-and-size conversion groups. The adjudication chain cleared small-model artifacts that a naive threshold would condemn as broken when they are merely collapsed by extreme quantization, and it exposed two older community conversions that degrade badly on CUDA yet pass on Metal: not defective files but backend-dependent failures, a third phenomenon no registry currently tests for. Two confirmed defects produce output whose surface statistics sit inside the healthy range, invisible to any low-noise heuristic short of execution. We release the audit dataset, the quantcheck acceptance-testing tool, and disclosure reports for every confirmed defect (https://github.com/aditi-p31/quantcheck), and argue that model registries need the acceptance gate that package registries already run.

Can coding agents restore software that no longer runs while preserving its underlying methods, and reconstruct industrial software engines from open specifications? Here we introduce ReviveBench, a benchmark with two task families evaluated by hidden verifiers calibrated against native execution environments, establis...
Tian-Yu Liu, Ding-Yuan Dai, Yu-Fan Du et al.· 0 citations
A minimal seven-field curatable record is derived and complementary responsibilities for model hubs, scholarly indexes, and digital libraries are derived, providing practical guidance for improving the preservation and bibliographic control of open LLM artifacts.
LLM-based code generation is now embedded in mission-critical pipelines, but defenses against vulnerable output remain post-hoc -- static analyzers, fine-tuned classifiers, or an LLM judge that screen completed code, ignoring the generating model's own internal state. We test a narrower, directly measurable question: w...
The results show that point accuracy alone is insufficient for characterizing LLM reliability in assertion generation and motivate robustness-aware evaluation for AI-assisted hardware verification.
GenIaC-SecBench is introduced, a benchmark of 100 deployment scenarios stratified by architectural complexity, evaluated across 12 model configurations from four vendors, producing 1,196 IaC artifacts scanned by three independent policy engines (Checkov, Trivy, KICS).
NoTB is introduced, an oracle-free triage framework that infers correctness from cross-model formal consensus and demonstrates that formal cross-model agreement provides a reliable basis for high-confidence triage without model-dependent oracles.
Elisavet Lydia Alvanaki, Je Yang, Biruk B. Seyoum et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
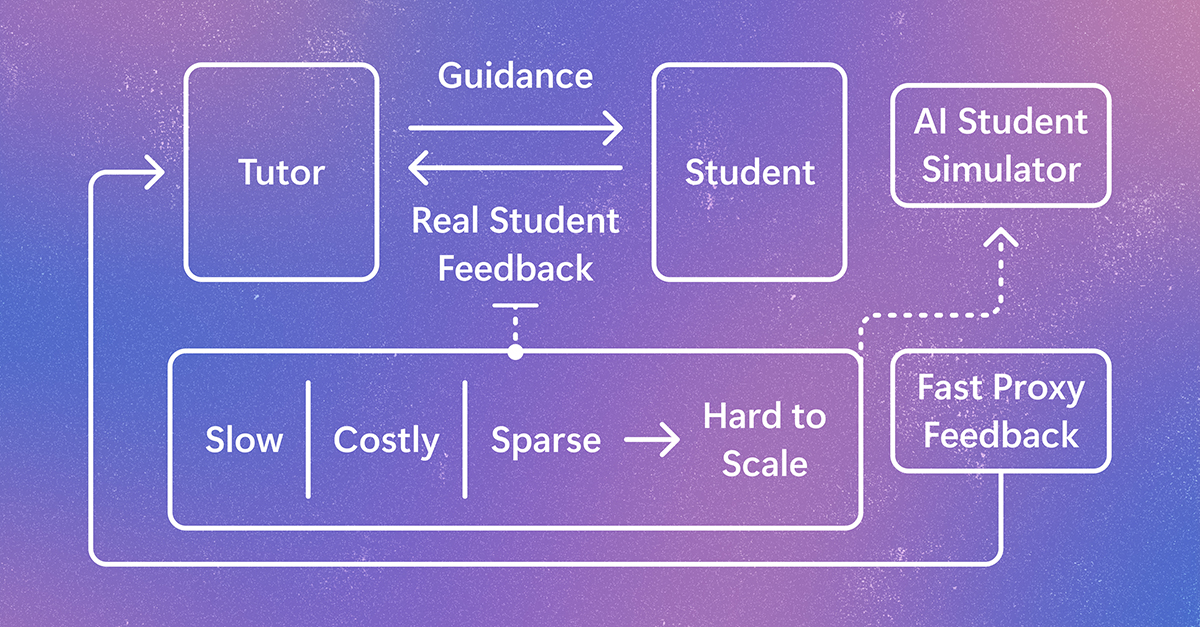
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.