Sep 2026· IEEE Internet of Things Journal· Vol 13, pp. 40282-40298· 0 citations· 33 references
Computer Science
Abstract
Visible light positioning (VLP), due to its widespread infrastructure deployment and high accuracy, has emerged as a highly promising key technology for Internet of Things (IoT). Current research mainly relies on either data-driven methods based on fingerprint features or model-driven methods based on geometric localization to estimate position. Although data-driven approaches can effectively cope with complex environmental disturbances, their performance is limited by insufficient exploitation of latent signal features on the one hand and strong dependence on training data on the other, resulting in limited generalization capability. In contrast, model-driven methods can adapt to different scenarios by leveraging physical models and geometric constraints, but they struggle to characterize complex interference patterns in dynamic environments. To address these issues, this article proposes a data-model jointly driven VLP framework that integrates the complementary strengths of both paradigms. First, at the framework level, a tightly coupled joint optimization scheme is constructed to integrate data-driven ranging with model-driven localization, preserving physical interpretability while leveraging the representation capability of deep learning. In contrast to conventional methods that discard harmonics as detrimental components, this article introduces a harmonic-enhanced ranging module that uses selected harmonic components as auxiliary structured spectral cues to improve the robustness of VLP ranging. The fundamental received signal strength (RSS) and selected harmonic RSS values of the modulation signal are incorporated into the ranging process, and a graph neural network (GNN)-based data-driven ranging model is developed to capture the structured relationships between the fundamental component and its harmonics, thereby improving ranging robustness in complex environments. Finally, to enable end-to-end optimization of the joint framework, a geometry-aware loss function is designed, allowing the model to jointly consider data fitting and physical geometric constraints during training, thereby coupling learned signal representations with model-driven geometric constraints.
SigMap is a multimodal foundation model that introduces two key innovations: a cycle-adaptive masking strategy that dynamically adjusts masking patterns based on channel periodicity characteristics to learn robust wireless representations and a novel"map-as-prompt"framework that integrates 3D geographic information thr...
Experimental results show that EMWM outperforms conventional neural network and large language model baselines in both CSI prediction and environment reconstruction, achieving a squared generalized cosine similarity (SGCS) of 0.9699 for CSI prediction while demonstrating robustness across different signal-to-noise rati...
Yizhu Zhao, Li Yu, Jian-Hua Zhang et al.· 0 citations
A deep Q-Learning (DQL) framework for resource optimisation in intelligent reflecting surfaces (IRS)-assisted VLC systems and results support the viability of learning-based, delay-aware optimisation for next-generation intelligent indoor VLC networks.
A. Hussen, Rashid Iqbal, A. Zoha et al.· Communications & Network...· 0 citations
A novel end-to-end causal Temporal Convolutional Network (TCN) framework for simultaneous three-dimensional position and single-axis orientation (azimuth) estimation for receivers moving on a fixed horizontal plane in indoor VLP systems is proposed.
Sunita Khichar, Sushank Chaudhary, Amir Parnianifard et al.· IEEE Access· 0 citations
Accurate quality of transmission (QoT) estimation, particularly generalized signal-to-noise ratio (GSNR) prediction, in newly deployed C+L-band optical networks is hindered by data scarcity and incomplete physical link information, leading to a cold-start problem for conventional deep learning methods. To address this...
The proposed IQ-MobNet DoA estimation model achieves this competitive performance with substantially lower computational complexity, requiring only 0.24 million parameters and 0.42 million Floating Point Operations (FLOPs), representing a reduction of over 96% compared to the recent neural network models.
Neeraja P. Kovilakam, Bindiya T. Sambasivan, Raghu C. Variyam· Electronics· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
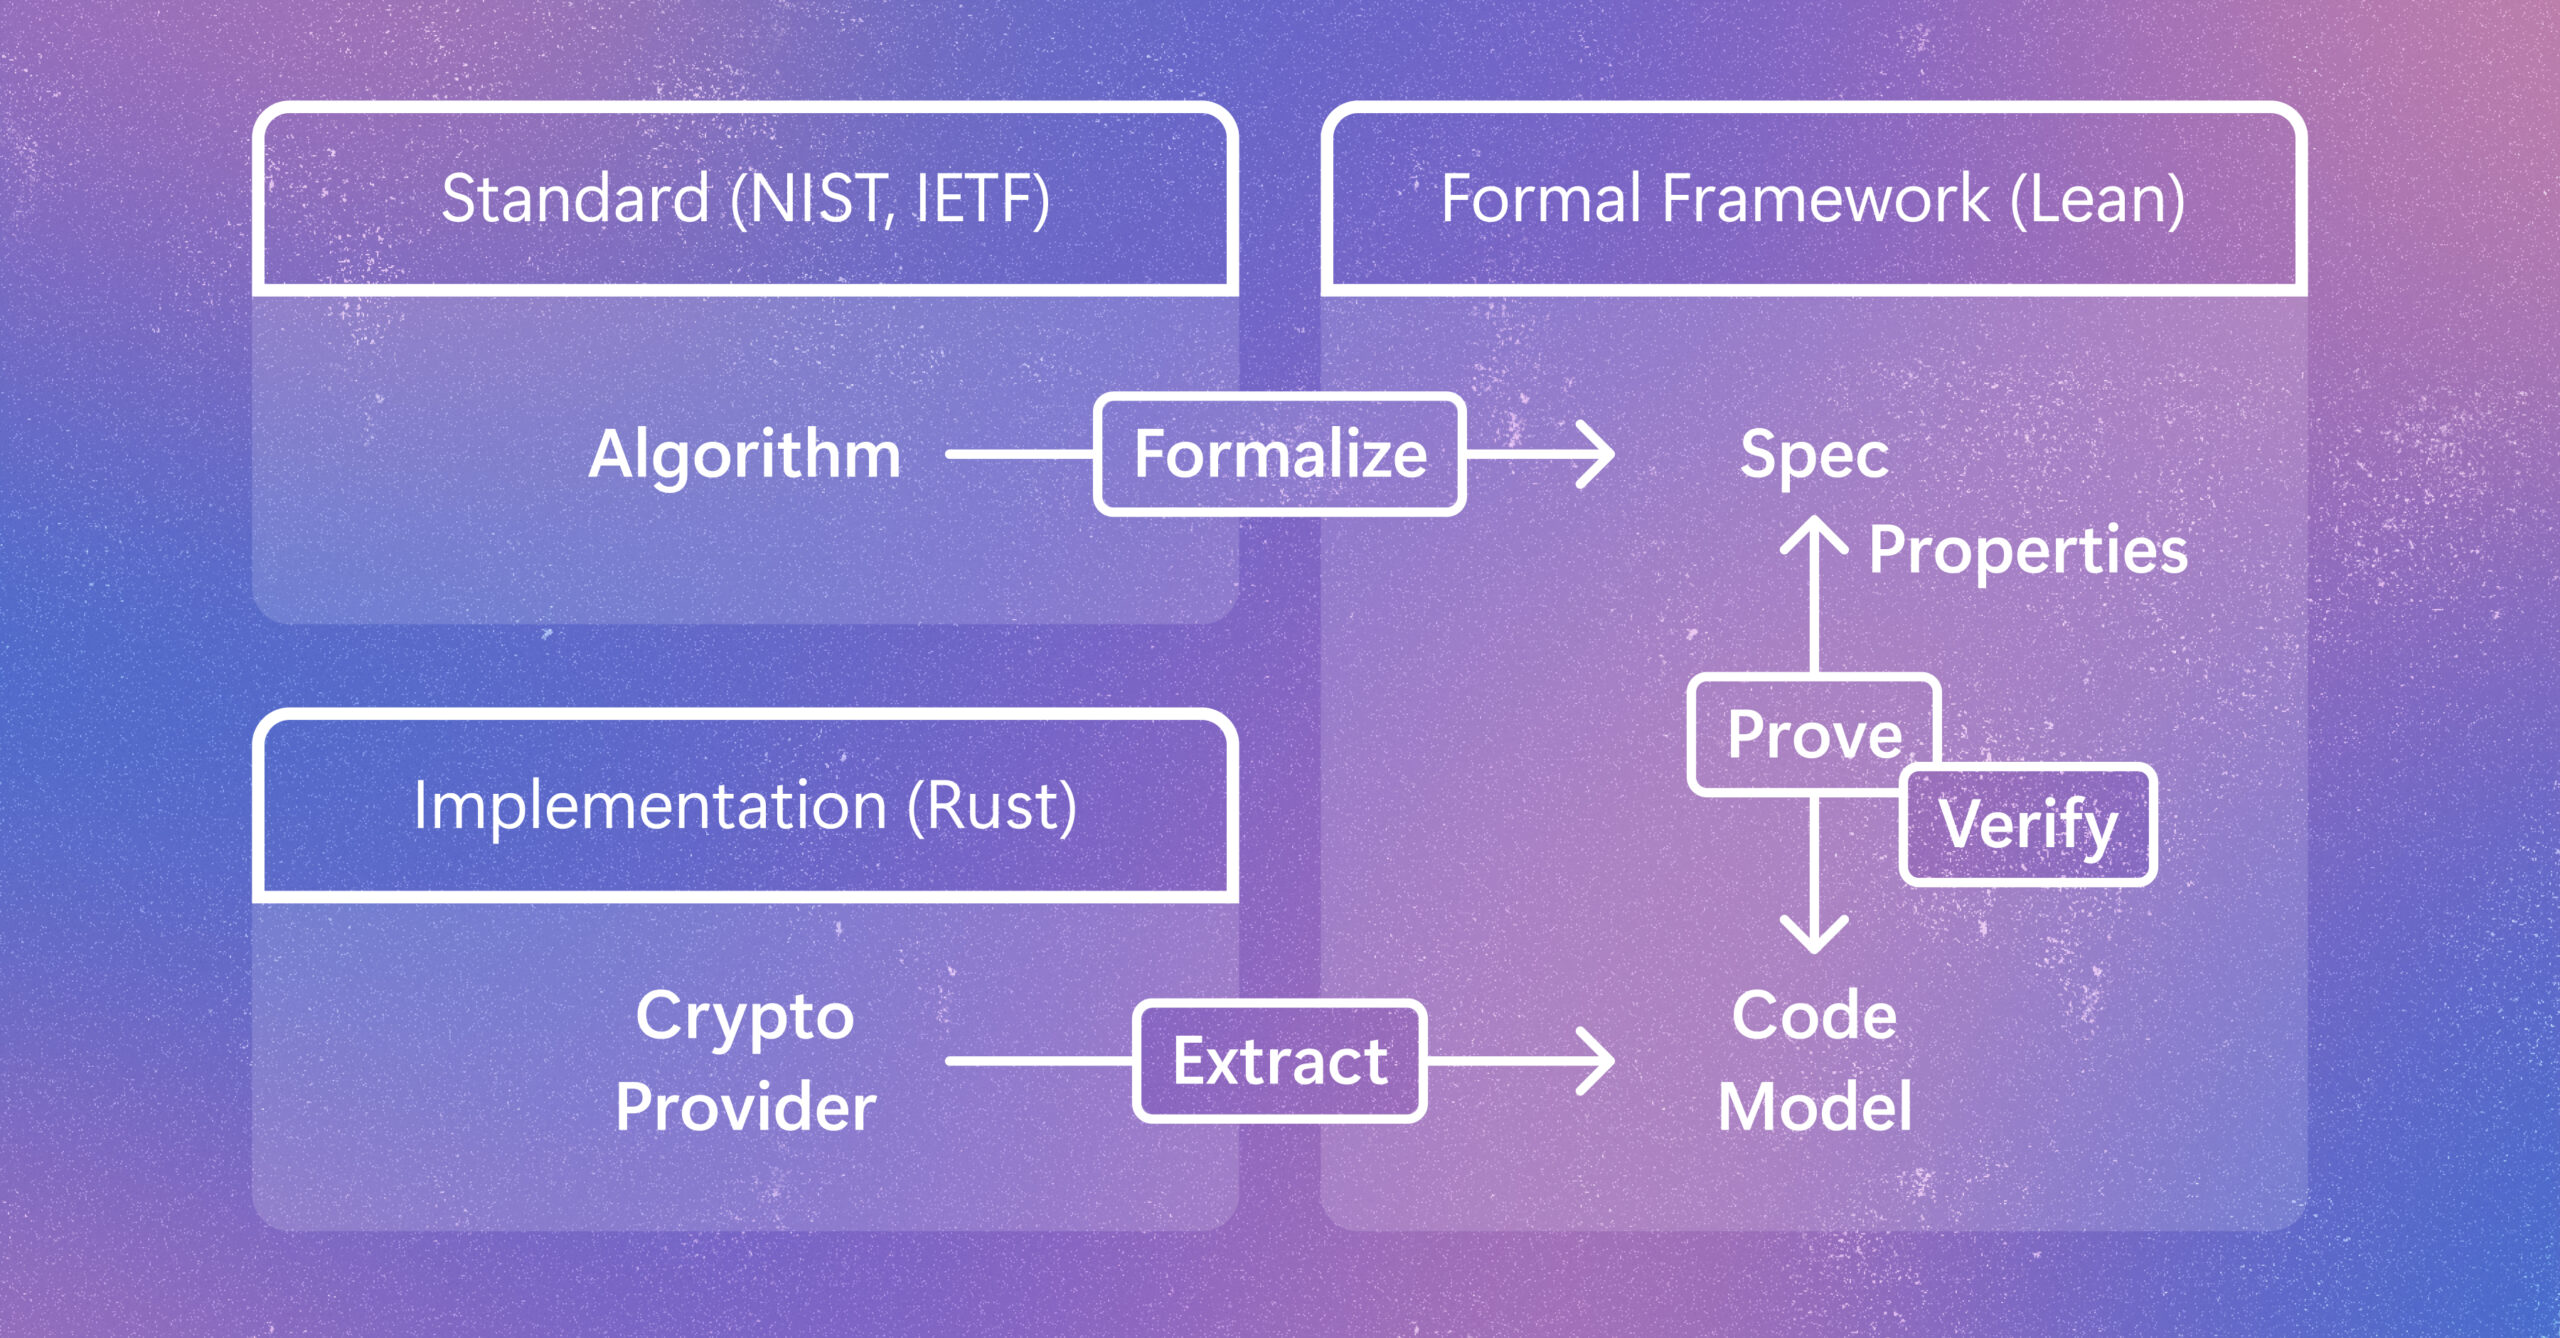
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.