Skip to content

Dynamic Entanglement-Weighted Pruning for Quantum Federated Unlearning in Supply-Chain Risk Prediction

Aug 2026 · 0 citations · 48 references
Physics Computer Science

TL;DR

Entanglement-Weighted Pruning (EWP), an unlearning procedure for quantum federated learning that scores every trainable circuit parameter with the product of two signals: the diagonal entry of the quantum Fisher information matrix estimated on the target client's data via the parameter-shift rule, and a structural entanglement weight associated with the parameter's gate.

Abstract

Federated deployments of variational quantum classifiers are attractive for cross-organisation risk prediction in supply chains, because raw data never leaves the client, yet data-protection regulations such as the GDPR grant clients a right to request that their contribution be removed from a trained model after the fact. Retraining a federated model from scratch to honour such a request is correct but wasteful, and it is not obvious which quantum circuit parameters actually carry a given client's influence. We introduce Entanglement-Weighted Pruning (EWP), an unlearning procedure for quantum federated learning that scores every trainable circuit parameter with the product of two signals: the diagonal entry of the quantum Fisher information matrix estimated on the target client's data via the parameter-shift rule, and a structural entanglement weight associated with the parameter's gate. Parameters with the lowest scores are pruned, optionally followed by a short fine-tuning pass on the retained clients. We implement the full pipeline in Qiskit for a four-qubit data-re-uploading ansatz trained with FedAvg across five simulated supply-chain-risk clients, and benchmark EWP against full retraining, fine-tuning alone, random pruning, Fisher-only pruning, and entanglement-only pruning, over three random seeds. EWP attains a mean post-unlearning accuracy statistically indistinguishable from the full-retraining oracle, while producing a lower forgetting score and requiring roughly 16 times less wall-clock time. Ablations over pruning threshold, client count, and non-IID strength show that combining the two signals is necessary, as entanglement-only and Fisher-only pruning each substantially degrade accuracy relative to EWP.

View source

Similar papers

Jul 2026

A Drift Stable Quantum Federated Learning for Intelligent Services

DUQFL-Prox is proposed, a drift-stable quantum federated learning framework based on deep-unfolded local optimization that improves stability, generalization, and client fairness compared with standard QFL baselines and is suggested to support more reliable and fair intelligent services in heterogeneous distributed env...

S. Nanayakkara, Shiva Raj Pokhrel · 0 citations
Conference Open access Sep 2026

FedEvoQ: Evolutionary Diversity Probing for Data-Quality-Aware Federated Aggregation

This work proposes a data-Quality-aware aggregation framework by introducing an Evolutionary-computation-inspired de-sign into Federated learning ( FedEvoQ), with a lightweight dual-branch architecture.

Le-Ming Wu, Yao-Chu Jin, Han Yu et al. · 0 citations
Open access Aug 2026

Revisiting Differentially Private Federated Learning for Tabular Data: A Matched-Accounting Benchmark of Boosting Versus DP-SGD

Gradient-boosted trees outperform neural networks on tabular data without privacy and off-path privatization and sequential noise accumulation explain the behavior; boosting’s main advantage is not accuracy but communication, achieving one to three orders of magnitude fewer values per client.

A. Alzahrani · 0 citations
Preprint Aug 2026

How Much Reconstruction Does Quantum Machine Learning Need? Late Fusion of Independently Trained Quantum Subcircuits

Late fusion is an efficient, noise-robust, self-characterizing alternative to reconstruction for circuit-cutting QML and claims advantage over classical machine learning - consistent with recent benchmarking, quantum offers no accuracy edge on these datasets.

Prabhjot Singh, A. Toosi, Rajkummar Buyya · 0 citations
Jul 2026

Federated Lightweight Fine-Tuning

Federated fine-tuning is bottlenecked by communication: FedAvg and pseudo-gradient schemes transmit a payload that scales with the model, and gradient compression shrinks it by only a constant factor. We take a different lever. Mapping networks generate a network's weights from a small trainable latent through a frozen...

R. Achanta, Will Reed · 0 citations

Related blog posts

MIT News · Artificial Intelligence Aug 27, 2026

Looking beyond natural sequences

A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.

Microsoft Research Blog Aug 20, 2026

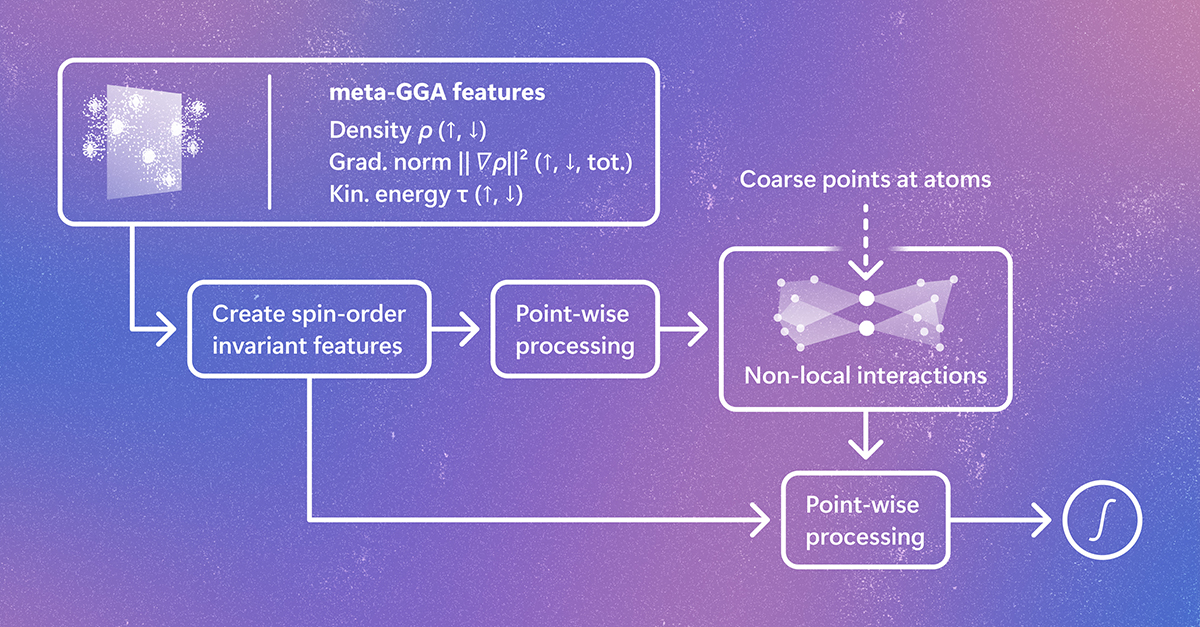
Broadening access to Skala creates a faster path to predictive DFT 

Skala 1.1, the updated deep-learning exchange-correlation functional from Microsoft Research, provides greater accuracy, expanded accessibility across the computational chemistry ecosystem, and a living benchmark to track computational performance. The post Broadening access to Skala creates a faster path to predictive DFT  appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.