This paper presents VocalCap, an institution-controlled, browser-based system for self-guided capture of voice and related acoustic signals by participants without technical training, and verify VocalCap's software behavior under the tested browser-engine conditions.
Abstract
Remote voice studies often retain a final audio file with limited evidence about how it was captured, transferred, processed, and accepted. This paper presents VocalCap, an institution-controlled, browser-based system for self-guided capture of voice and related acoustic signals by participants without technical training. A versioned protocol drives the workflow. Each accepted recording retains a browser-native object, a client-lossless Float32 WAV derived from the same MediaStream, and a server-canonical mono PCM16 WAV, linked to evidence of capture execution, technical quality, byte-level integrity, recovery, and transformation provenance. IndexedDB preserves accepted browser artifacts until server confirmation, while session completion requires successful verification of every task and artifact. Software tests challenged the acquisition contracts with malformed or altered objects, exact-zero interruptions, channel-topology variants, and interrupted or repeated operations. A post hoc technical audit of 39 consented pilot recordings found 25 sample-identical stereo files and 14 files with signal confined to the left channel. Topology-aware active-channel selection limited the canonical root-mean-square level difference to less than 0.001 dB in all 14 affected files; equal-weight stereo averaging would have introduced approximately 6.02 dB of attenuation. Production end-to-end verification completed two five-task profiles in Chromium and WebKit, yielding 10 accepted recordings and 30 retained artifacts that passed server-side integrity and format checks. The results verify VocalCap's software behavior under the tested browser-engine conditions. Device-level acoustic agreement, target-population usability, clinical validity, and biomarker performance remain subjects for separate studies.
Modern text-to-speech (TTS) systems are rarely deployed as unchanged pre-trained models. They are often adapted through supervised fine-tuning (SFT) or preference optimization such as DPO and GRPO. This raises a practical question for audio deepfake forensics: do fingerprints learned from a foundation generator remain...
Audio deepfake detectors are commonly evaluated on source audio under controlled data conditions, whereas realtime voice communication can introduce transmission-dependent distortions through browser-based delivery, packet loss, jitter, and packet-loss concealment. This paper investigates networkaware audio deepfake sc...
Gilhan Choi, Yonggang Kim· International Conference on...· 0 citations
Telecom fraud scripts evolve rapidly and are often designed to resemble routine service conversations, creating two key requirements for audio-based telecom-fraud evaluation. First, benchmarks must incorporate newly observed scam patterns without overwriting previously established test sets. Second, they must distingui...
Hui-Yuan Liu, Zhi-Ming Ma, Yan-Xing Liu et al.· 0 citations
Purpose: Conventional clinical acoustic analysis systems are confined to specialized clinical environments, which limits scalable and remote voice monitoring. This study aimed to validate LIS-N, a web-based prototype of a novel mobile application that uses the open-source Praat-Parselmouth library for acoustic feature...
Shrramana Ganesh Sudhakar, Sabrina Musteric, S. Watts et al.· medRxiv· 0 citations
Browser-based hearing tests offer a scalable alternative to clinic-based assessment, but most validated tools have been developed in English-speaking populations. The authors conducted a retrospective observational analysis of real-world use of a Japanese browser-based hearing test platform (April 2023–March 2026), com...
S. Minami, Marie N. Shimanuki, Takanori Nishiyama et al.· Frontiers in Audiology and O...· 0 citations
Interrupt and Silent Modeling (ISM), a model-agnostic paradigm that embeds proactive decisions into LLM decoding via two special tokens, is proposed, capturing four states: onset detection, sustained-relevance triggering, irrelevance suppression, and de-duplication.
Amit Kumar Singh Yadav, Ritvik Shrivastava, Xuan Zhang et al.· 1 citation
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
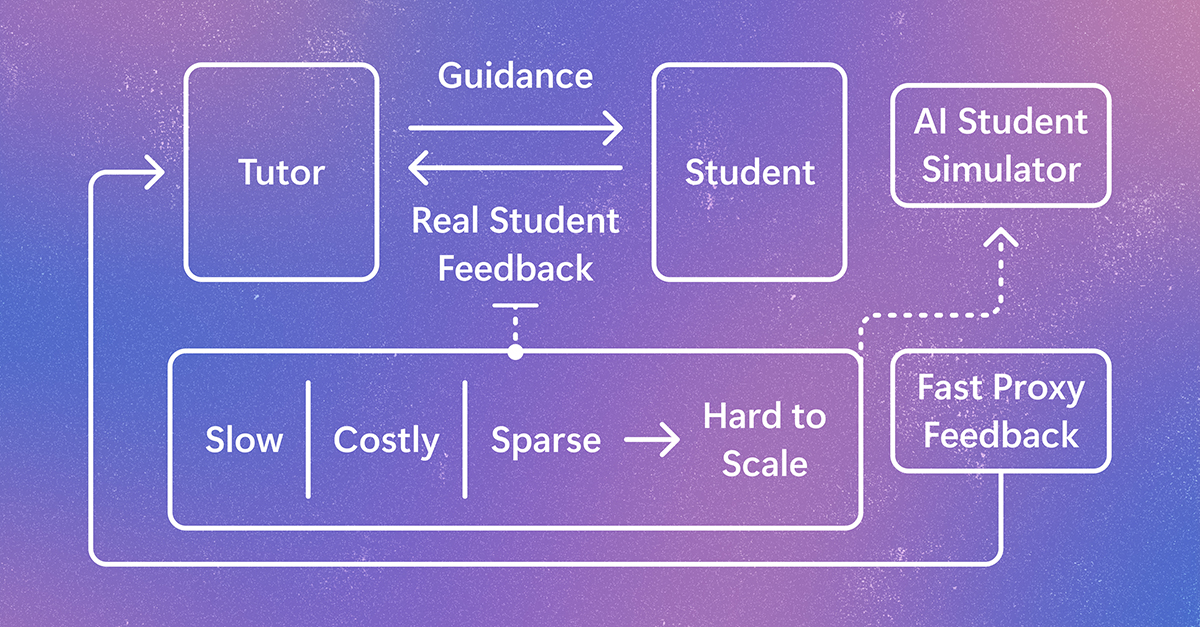
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.


