Skip to content

Can Capability Enhancement be Localized?

Oct 2026 · 0 citations · 33 references
Computer Science

Abstract

Transformer-based language models have shown strong capabilities across many tasks and domains. However, prior work shows that, for a given task, not all attention heads matter equally. Specifically, they suggest that many \textit{redundant} heads can be safely removed with little-to-no effect, while a small set of \textit{important} heads, when ablated, severely damages the model's performance on the given task. In this work, we investigate a complementary aspect, called \textit{Capability Enhancement Localization} (CEL): \textit{given a model and a task, does there exist a small set of heads whose removal improves the task performance?} We first investigate this question \textit{empirically} across models from different families. Using a simple two-stage routine that screens candidate heads and evaluates their joint ablations, we identify sparse head combinations whose removal improves task-specific performance without further fine-tuning. Motivated by these observations, we ask \textit{theoretically whether such a phenomenon can naturally arise from training dynamics, and under what conditions}. To this end, we construct a simplified multi-head softmax attention model and two tasks with conflicting features, and show that gradient descent from small random initialization provably concentrates the conflicting features into particular heads. We further show that ablating such heads improves performance on one task while harming the other, even though training converges to a global optimum of the joint objective. This establishes a possible training-induced theoretical explanation for CEL.


View source

Similar papers

#artificial intelligence Conference Open access Jun 2018

Gibson Env: Real-World Perception for Embodied Agents

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.

F. Xia, Amir Zamir, Zhi-Yang He et al. · 1,069 citations · ⚡112
#small language model Dataset Open access Oct 2026

Socratic guiding questions in synthetic arithmetic data: matched LoRA runs (revision v2)

Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...

O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al. · 465 citations
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 12, 2026

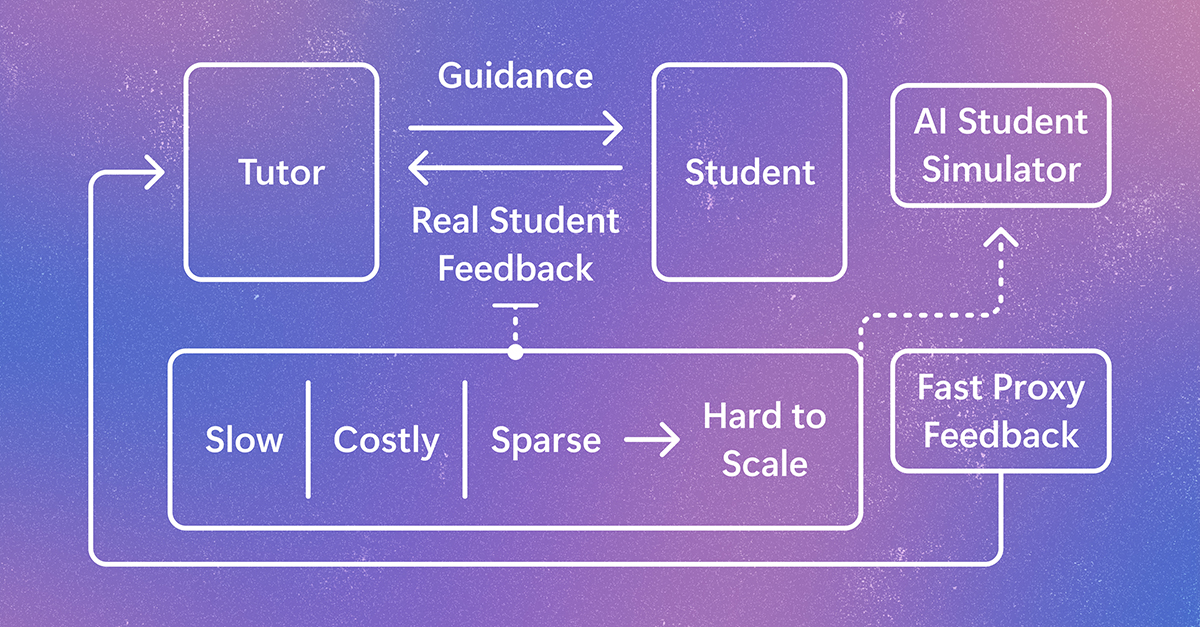
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.