CoRe-GNN is proposed, which performs both propagations in parallel at each layer: a coarsened inter-cluster term capturing long-range structure, and a local intra-cluster term preserving per-node discriminability.
Abstract
Training Graph Neural Networks on large graphs is challenged by the memory cost of storing all node representations across layers. We show that several existing scalable approaches can be written as structured modifications of the GNN propagation matrix, providing a unified perspective that exposes their respective limitations. In particular, graph coarsening replaces it by a low-rank approximation that enables spectral guarantees but assigns uniform representations to clustered nodes, while Cluster-GCN restricts the propagation matrix to intra-cluster connections that allow efficient batching but sever long-range information. These are complementary failures of the \emph{same} decomposition of the graph into groups of nodes. To obtain the best of both worlds, we propose \textbf{CoRe-GNN}, which performs both propagations in parallel at each layer: a coarsened inter-cluster term capturing long-range structure, and a local intra-cluster term preserving per-node discriminability. We prove that CoRe-GNN inherits analogous approximation guarantees to those of graph coarsening, and introduce a natural cluster-based \emph{batching scheme} that scales to graphs with millions of nodes. On node classification benchmarks spanning homophilic, heterophilic, large-scale, and long-range graphs, CoRe-GNN outperforms both graph coarsening and Cluster-GCN baselines. Notably, CoRe-GNN reaches competitive accuracy on \emph{long-range} tasks, while remaining memory-efficient through batching.
This work proposes a novel Adaptive Dual-level Collaborative GNN associated with an adaptive dual-level collaborative mechanism, and shows that the ADC-GNN can inject the learned high-level information back into the node level, forming a closed-loop, bidirectional optimization process.
Wan Tang, Lu Bai, Li-Xin Cui et al.· Proceedings of the Thirty-Fi...· 0 citations
DeltaGNN is introduced, to the best of the authors' knowledge, among the first scalable (featuring linear computational and memory complexity overhead) and generalizable (capable of effectively handling graphs with diverse homophily, density, and topology) architectures for long-range and short-range interaction detect...
Kevin Mancini, Islem Rekik· IEEE Transactions on Pattern...· 2 citations
SmartNIC-based in-network prediction is a practical complement to partitioning and compression techniques for communicationefficient full-graph GNN training at scale, and results indicate SmartNIC-based in-network prediction is a practical complement to partitioning and compression techniques for communicationefficient...
Guofan Yu, Si-Tian Chen, Zhenheng Tang et al.· IEEE International Conferenc...· 0 citations
The proposed DD-AG2m alternates between AG2m optimization on the original (global) graph and AG2m optimization on the partitioned graphs, and introduces a two-level variant that performs global optimization steps on a coarse graph obtained by randomly subsampling nodes within each subdomain.
Laurynas Varnas, Julien Herrmann, Alexander Heinlein et al.· 0 citations
Experimental results demonstrate that the coarsening technique significantly accelerates dynamic GNN training and inference without compromising predictive performance, offering a practical path toward scalable dynamic graph learning.
Hieu Vu, Rares-Mihail Neagu, Bijaya Adhikari· Proceedings of the 32nd ACM...· 0 citations
Subgraph Filtering for Fair Graph Neural Networks is proposed, a lightweight and architecture-agnostic framework that mitigates structural bias at its source and achieves consistent fairness improvements while maintaining competitive predictive performance, leading to a better fairness--accuracy trade-off than recent f...
Hao-Hui Lu, Ji-Yuan Tian, Fangyu Zhou et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
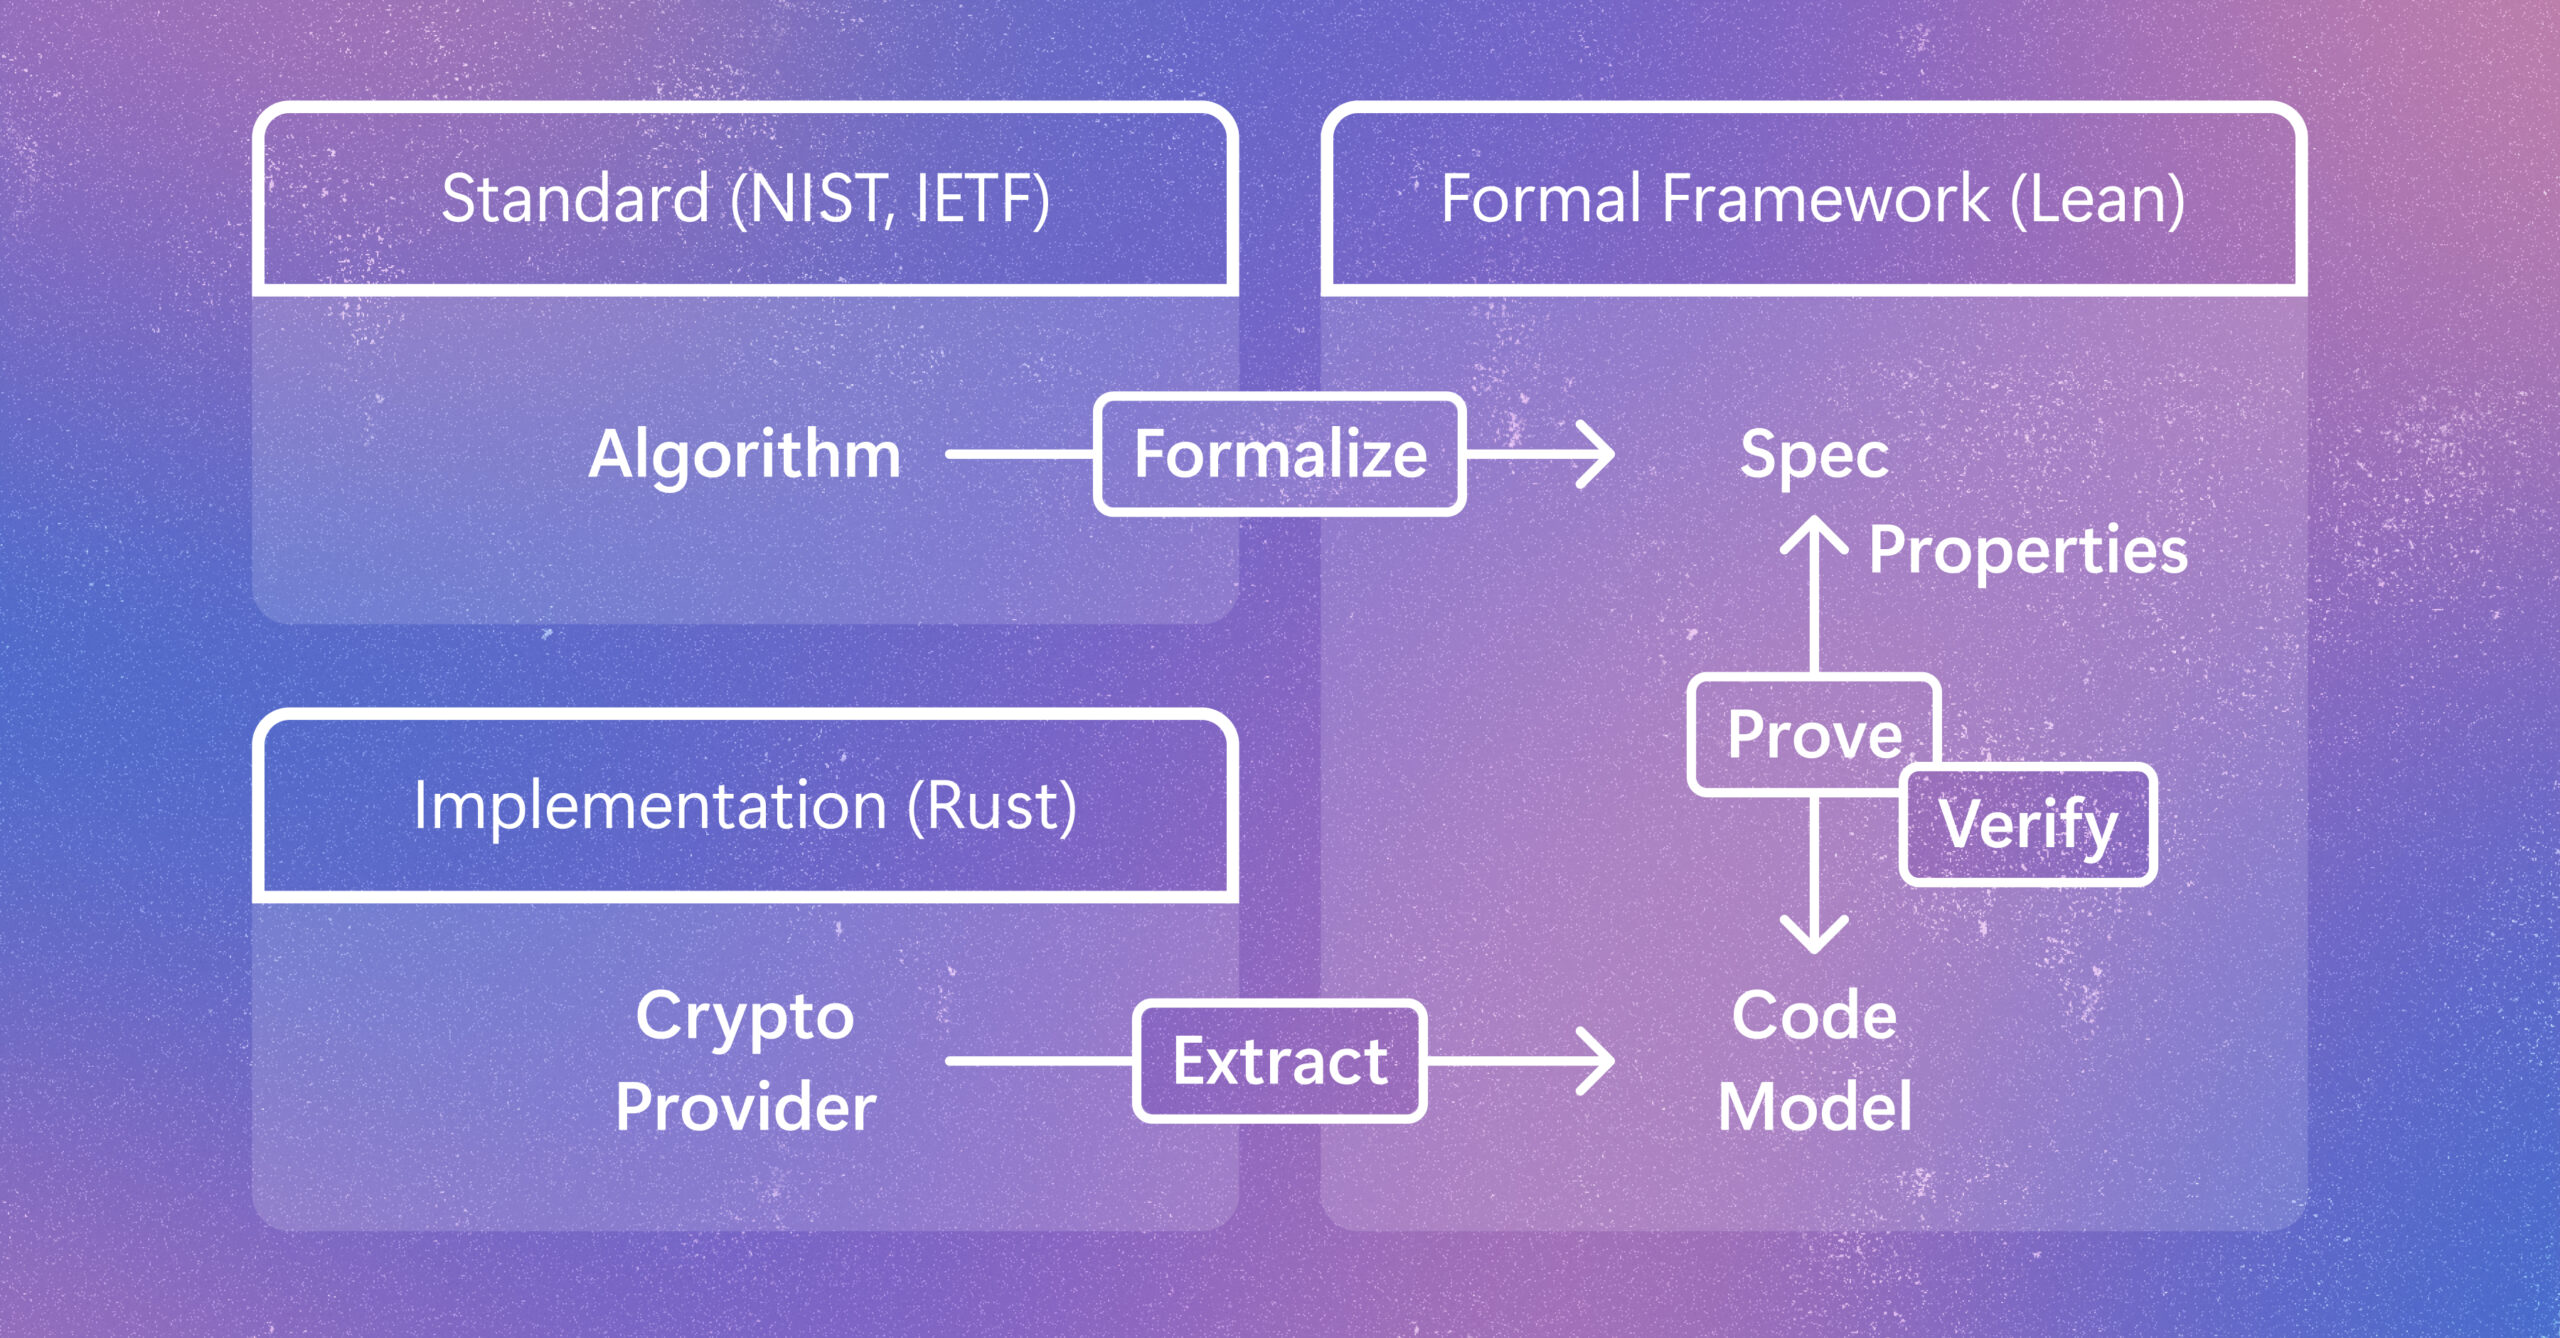
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.