Vision-Language-Action (VLA) models leveraging the native autoregressive paradigm of Vision-Language Models (VLMs) have demonstrated superior instruction-following and training efficiency. Central to this paradigm is action tokenization, yet its design has primarily focused on reconstruction fidelity, failing to address its direct impact on VLA optimization. Consequently, the fundamental question of \textit{what makes for good action tokenizers} remains unanswered. In this paper, we bridge this gap by establishing design principles specifically from the perspective of VLA optimization. We identify a set of best practices based on information-theoretic insights, including maximized temporal token overlap, minimized vocabulary redundancy, enhanced multimodal mutual information, and token independence. Guided by these principles, we introduce \textbf{ActionCodec}, a high-performance action tokenizer that significantly enhances both training efficiency and VLA performance across diverse simulation and real-world benchmarks. Notably, on LIBERO, a SmolVLM2-2.2B fine-tuned with ActionCodec achieves a 95.5\% success rate without any robotics pre-training. With advanced architectural enhancements, this reaches 97.4\%, representing a new SOTA for VLA models without robotics pre-training. We believe our established design principles, alongside the released model, will provide a clear roadmap for the community to develop more effective action tokenizers.
This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
GAOKAO-Bench is introduced, an intuitive benchmark that employs questions from the Chinese GAOKAO examination as test samples, including both subjective and objective questions that contribute a robust evaluation benchmark for future large language models and offers valuable insights into the advantages and limitations...
Xiaotian Zhang, Chun-yan Li, Yi Zong et al.· arXiv.org· 216 citations· ⚡17
An algorithm is proposed which leverages disentangled semantic factors to generate adversarial perturbation by altering controlled semantic attributes to fool the learner towards various "adversarial" targets.
Haonan Qiu, Chaowei Xiao, Lei Yang et al.· arXiv.org· 208 citations· ⚡17
This work proposes a HALO that directly maximizes the utility of generations instead of maximizing the log-likelihood of preferences, and suggests that the best loss depends on the inductive biases most appropriate for a given setting, an oft-overlooked consideration.
This work investigates the possibilities of using LLMs in a resume screening setting via a document retrieval framework that simulates job candidate selection and finds that the MTEs are biased, significantly favoring White-associated names in 85% of cases and female-associated names in only 11.1% of cases.
This work shows that orders of magnitude enhancement in performance could be obtained by a combination of hardware improvements and tight quantum-HPC integration and introduces high-performance architectures for quantum-probabilistic computing with custom-designed accelerators to tackle today's industry-scale classical...
Masoud Mohseni, Artur Scherer, K. Johnson et al.· arXiv.org· 121 citations· ⚡9
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduJul 30, 2026
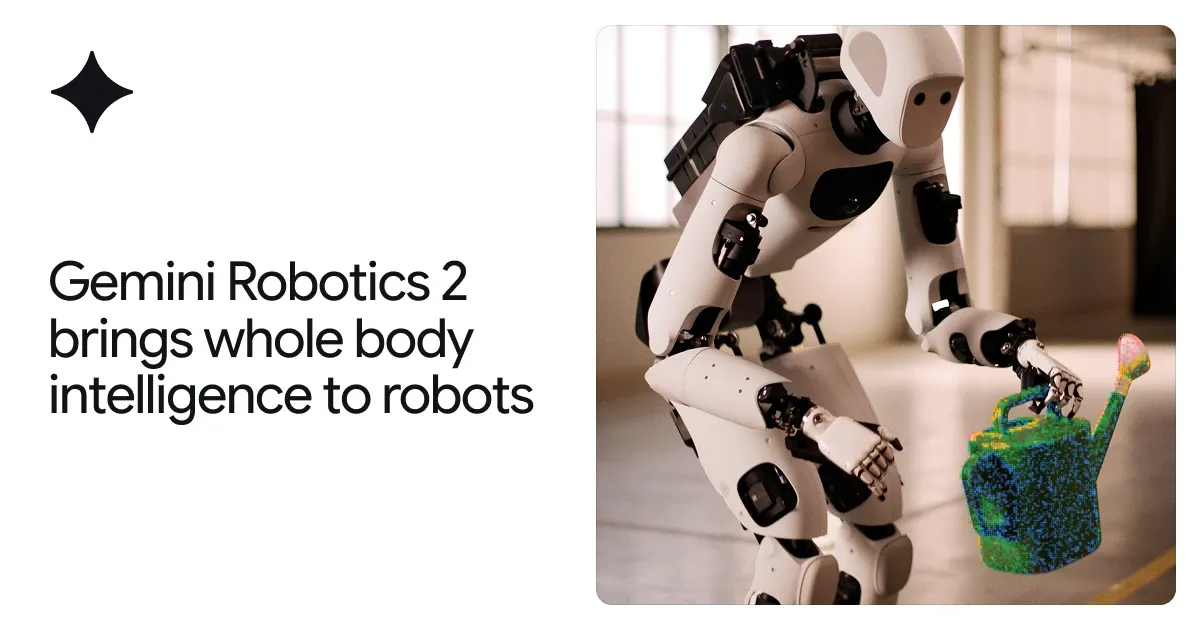
From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks.