What Does It Cost to Simulate a Quantum Sentence Classifier? An Energy and Compute Perspective on Near-Term QNLP
Kishlay KashyapSandipan Ganguly
Oct 2026
Machine LearningNatural Language ProcessingQuantum Computing
Abstract
Near-term quantum natural language processing (QNLP) experiments often run on classical simulators, so simulator cost is part of the field's practical compute burden, yet accuracy tables do not show it. We measure that cost for a variational quantum classifier (VQC) on binary SST-2 sentiment classification, using PennyLane's state-vector simulator over a controlled grid of 27 configurations: three balanced training-set sizes (N = 200, 500, 1000), three qubit counts (4, 6, 8), and three circuit depths. Each VQC is compared with logistic regression on the same PCA-reduced input; full TF-IDF logistic regression gives an uncompressed reference. The VQC beats its matched baseline in 6 of 27 single-seed comparisons. After reruns at two further seeds, only 1 of these 6 keeps a positive mean advantage larger than its paired seed-to-seed variability, and paired tests on the fixed validation set do not establish it. VQC training is 886-21,127 times slower in measured wall-clock time than the matched classical fit (median 3,158 times); going from 4 to 8 qubits roughly doubles simulator time, and within the tested range per-step cost is well approximated by a linear function of the parameter count. CodeCarbon energy and CO2 estimates are secondary: they imply an almost constant power of about 41 W, so they add little beyond runtime, and we do not build an energy ratio from them. The study is narrow (one dataset, representation, ansatz, simulator, and CPU environment) and is a reproducible feasibility measurement, not a general verdict on QNLP.

This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
A weeklong summer workshop brought higher education faculty to campus to explore how AI and machine learning materials can be adapted for their classrooms.
Microsoft Research Blog· microsoft.comAug 20, 2026
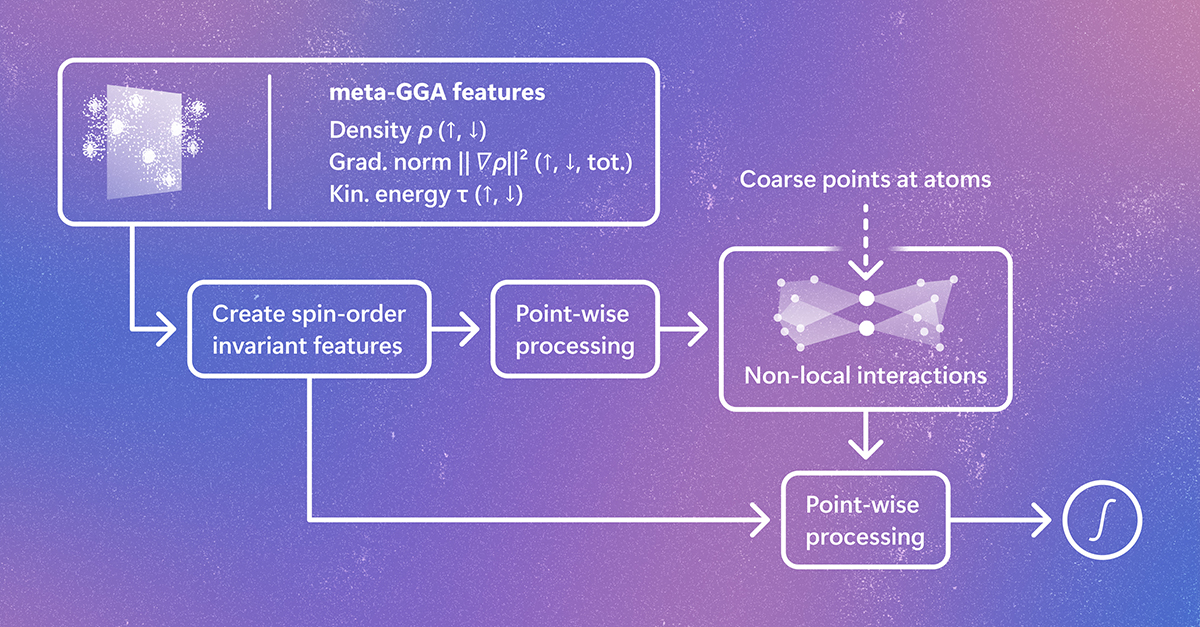
Skala 1.1, the updated deep-learning exchange-correlation functional from Microsoft Research, provides greater accuracy, expanded accessibility across the computational chemistry ecosystem, and a living benchmark to track computational performance. The post Broadening access to Skala creates a faster path to predictive DFT appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.