DeltaS is proposed, a query-agnostic, training-free method that retains video chunks inducing larger normalized state change, or state drift, in a controlled comparison with the budget and retention policy held fixed, which suggests that the two memories of hybrid architectures can work cooperatively.
Abstract
Recent video-language models increasingly adopt hybrid architectures that interleave linear and full attention layers for efficient long-context processing. While the recurrent state of linear attention remains fixed in size, the KV cache of full attention continues to grow with the video stream, making eviction necessary under a bounded memory budget. The key challenge in streaming is that eviction must occur before the question arrives, so what to retain has to be decided without the question. Existing eviction methods derive token scores from the KV cache itself, using position, attention, or key-value representations, and attention-based scores further require proxy queries or extra computation. Hybrid backbones offer another source of signal. In gated-delta linear attention, the recurrent state is updated by the residual between each input and what can already be retrieved from the state, so its change over a chunk of frames reflects how much new information the chunk brings. We propose DeltaS, a query-agnostic, training-free method that retains video chunks inducing larger normalized state change, or state drift. In a controlled comparison with the budget and retention policy held fixed, state drift outperforms position-, attention-, and key-value-based signals. With a signal costing only 1.9% of the forward pass, DeltaS surpasses the strongest query-agnostic bounded-memory baseline by 2.1 points on average across six long-video benchmarks and by 5.6 points on the longest benchmark. These results suggest that the two memories of hybrid architectures can work cooperatively. Code is available at https://github.com/MaumAI-Company/DeltaS.
DeltaLog is presented, a recurrent-state decoding scheme that reduces this overhead without changing the model semantics, and is implemented for GDN, KDA, and RWKV6 and integrated into a prototype serving stack.
Prefix-Steered Recurrent Memory (PREM), a memory-token-free framework for frozen vision-language models (VLMs) that separates video ingestion from query answering, consistently outperforms frozen baselines at every evaluated visual budget.
Si-Ru Zhong, Qiong-Yan Wang, Xiao-Hui Lv et al.· 0 citations
Decay-Aware State Compression (DASC), which derives retention horizons from model weights, selects long-horizon state units, and packs them into a ragged state checkpoint layout to integrate efficiently with tensor-parallel inference engines.
Yanzhi Yu, Ping-Wei Sun, Jian-Chao Tan et al.· 2 citations
KV-cache eviction can do more than compress. In long-context LLMs, keeping only some cached tokens sometimes matches or exceeds full-cache accuracy, because many redundant prefill tokens otherwise dilute attention away from the tokens that carry the answer. This benefit is not uniform, and evicting the wrong tokens can...
Long-context large language models (LLMs) have demonstrated strong capabilities across a wide range of tasks, but the growing KV cache introduces substantial memory and inference overhead. Existing one-shot KV cache compression methods typically commit to irreversible eviction immediately after prefill, before any sign...
Zhe Wang, Jia-Kai Li, Yu-Jia Sun et al.· 0 citations
Tail-Replay is presented, a prefix caching mechanism that enables unconstrained token-level prefix reuse in hybrid large language models and is evaluated on three Gated DeltaNet-based hybrid models using the LongBench and RULER benchmarks.
Yi-Rui Liu, Ruo-Ling Qi, Xuan'er Wu et al.· 1 citation
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
Microsoft Research Blog· microsoft.comAug 11, 2026
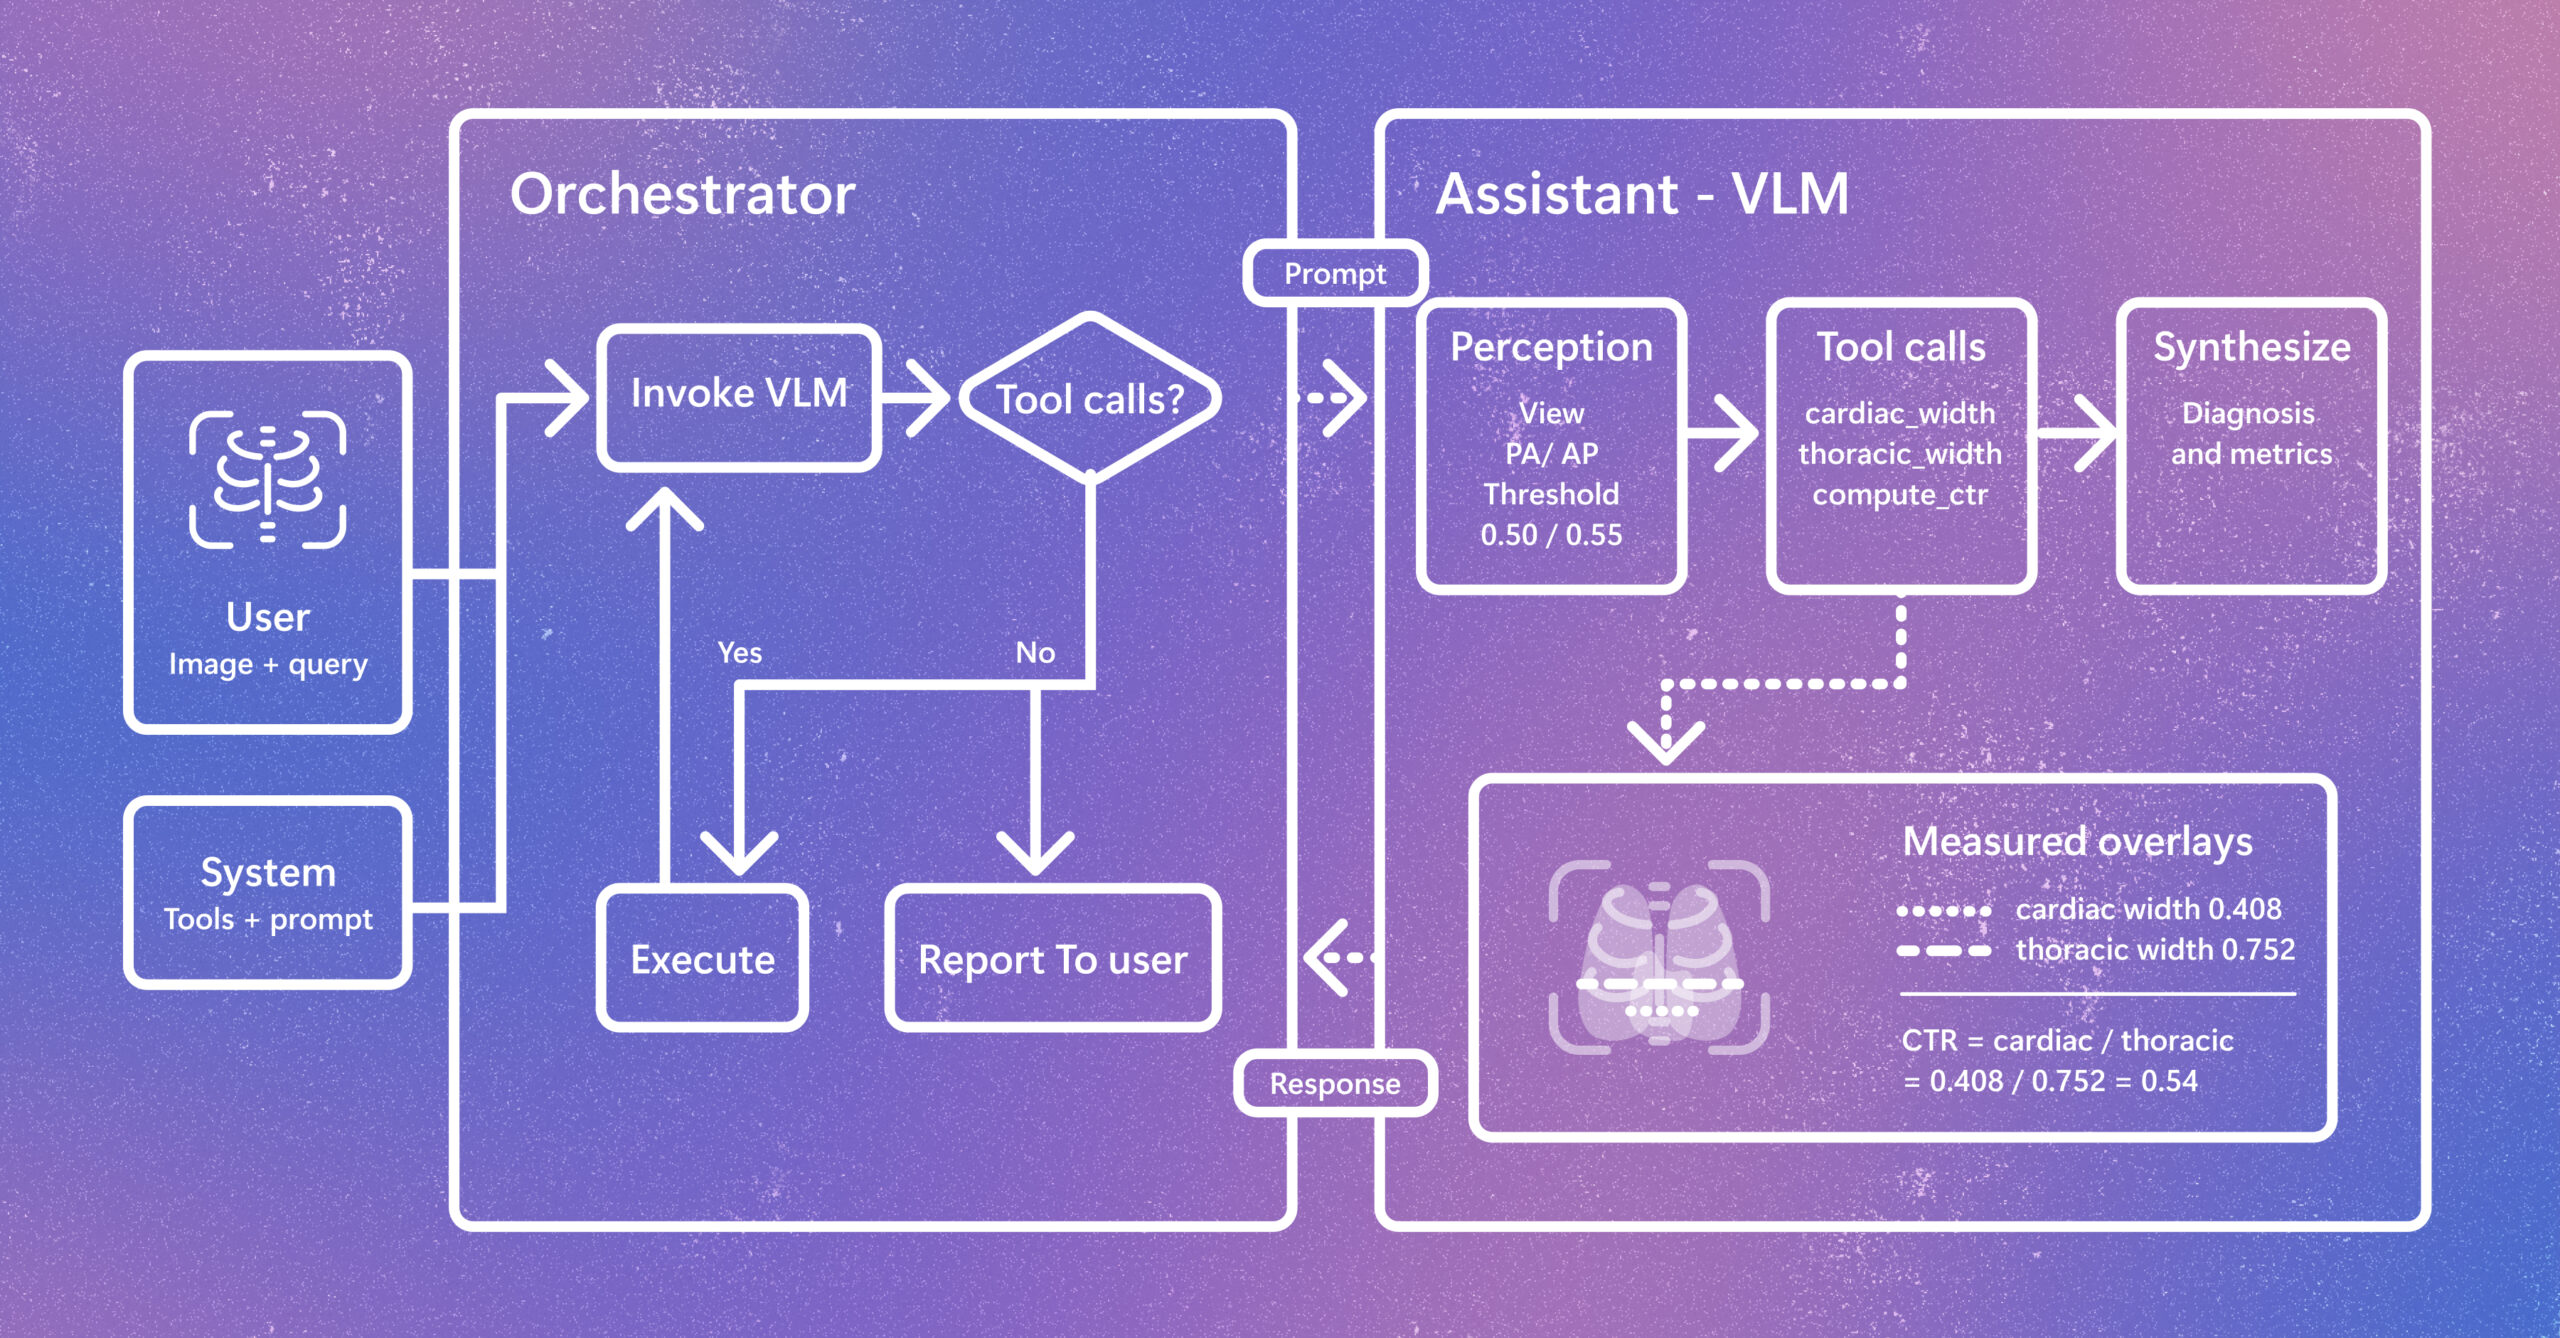
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.