Calibration Count Reuse: Validity Does Not Determine Efficiency
Rudra Chopra
Sep 2026
Machine LearningComputer Vision
Abstract
Calibration count reuse raises separate validity and efficiency questions. We give a validity criterion for general count-dependent nonconformity scores: transferring one count from another class to the scored class must not improve its conformity. A leave-self-out full conformal reference proves the criterion without requiring normalization or preservation of same-class score order. For a common separable transformation, universal exchangeable validity is equivalent to being nondecreasing in the count, provided $K\alpha \geq 1$; normalized multiplicative weights obey the complementary nonincreasing condition. Additive penalties are covered under the stated information restrictions. Efficiency has no parallel ordering: two iid constructions make the same valid rule improve or worsen expected size at unchanged coverage. An expanded 55-rule study finds no resolved advantage from selected live-count rules over uniform weights. Image studies identify undercoverage under iid resampling, including at numerical convergence. Separately, execution of the released Conf-OT pipeline on its DTD and Aircraft benchmark subsets produces near-nominal median coverage under fixed stratified counts. The native results are reported separately from the iid analyses, without treating a benchmark observation as a universal guarantee. The findings separate validity, classifier confidence, numerical convergence, and population-specific efficiency.
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
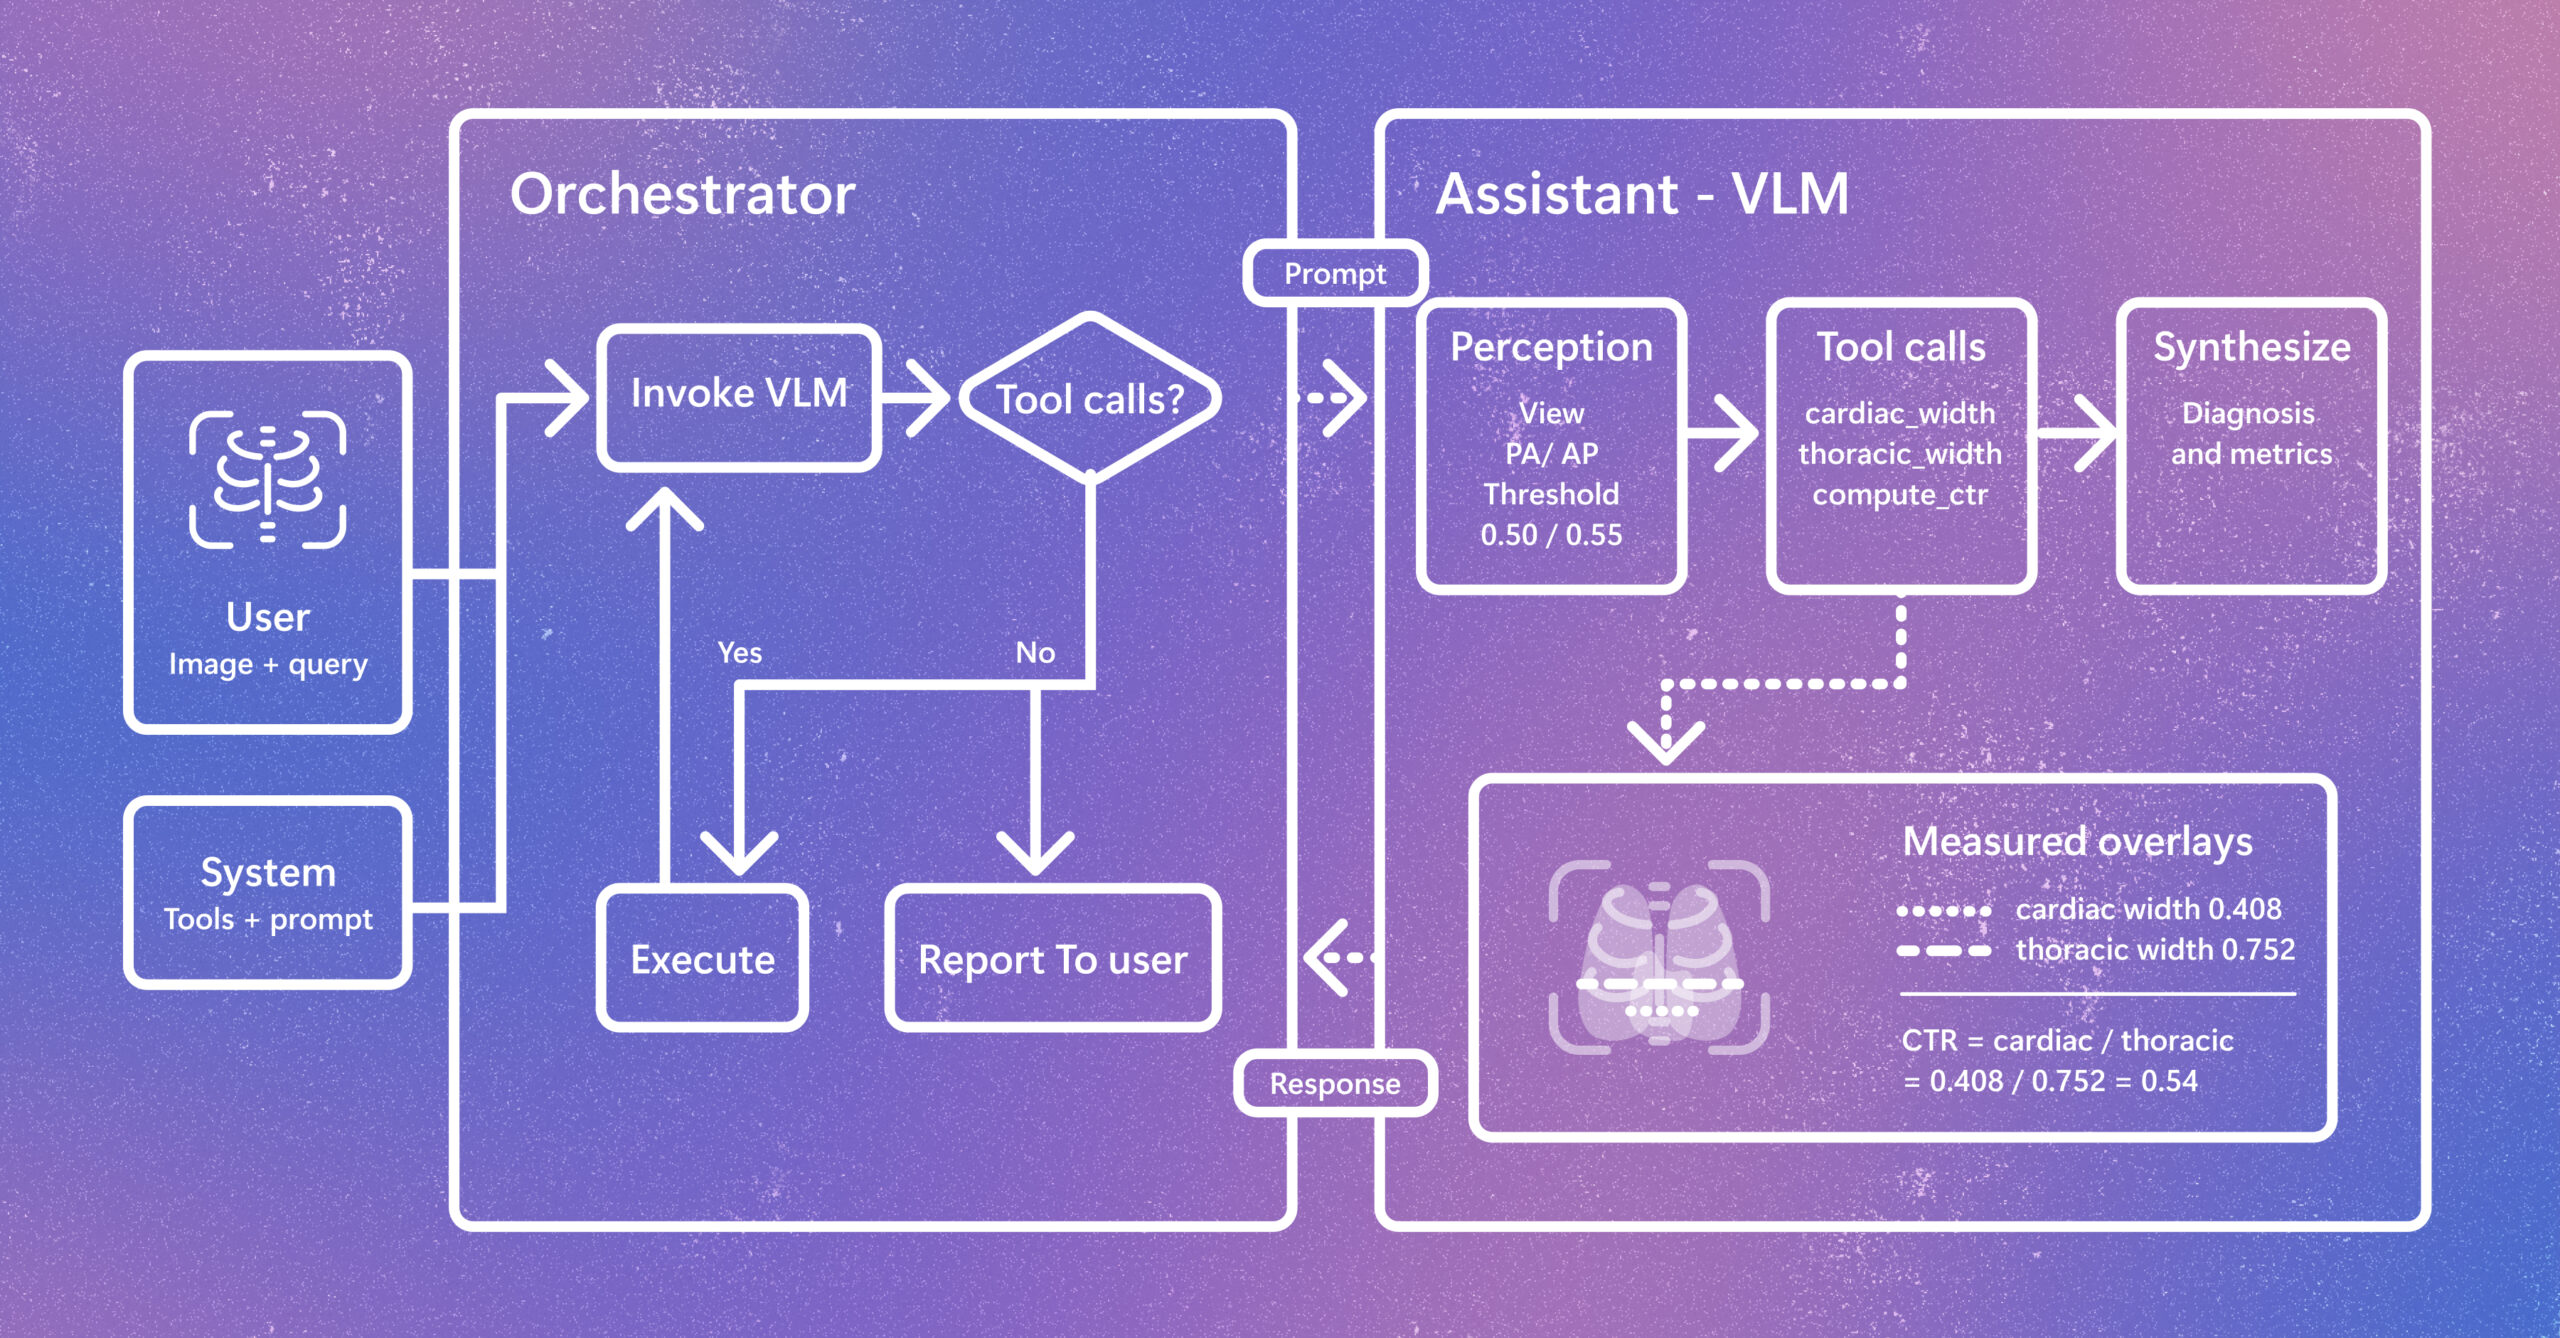
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.