SAGE (Scene-Adaptive Graph-Enhanced offloading), a task-offloading framework that combines a heterogeneous graph neural network (HeteroGNN) with a dueling double DQN meta-controller and a mixed-integer linear programming (MILP) solver, is proposed, demonstrating strong scene-adaptive decision-making capability.
Abstract
Efficient task offloading in UAV-assisted heterogeneous mobile edge computing (MEC) networks is increasingly challenged by the co-existence of operationally distinct workload scenarios—including high-demand bursts, resource-constrained periods, and balanced operational states—each demanding fundamentally different assignment strategies. In such networks, mobile executor nodes (e.g., UAVs or vehicle-mounted edge servers) must be dispatched to the vicinity of geographically distributed tasks, making assignment decisions jointly dependent on node mobility, the quality of sensing data, and dynamic resource availability. Conventional approaches based on combinatorial optimization with fixed parameters or greedy heuristics fail to adapt to these varying conditions, leading to resource depletion under sequential workloads or underutilization under high-demand bursts. To address these limitations, this paper proposes SAGE (Scene-Adaptive Graph-Enhanced offloading), a task-offloading framework that combines a heterogeneous graph neural network (HeteroGNN) with a dueling double DQN meta-controller and a mixed-integer linear programming (MILP) solver. At the state-representation level, a heterogeneous bipartite graph is constructed over mobile executor nodes and tasks, with type-specific projection layers encoding the semantic features of each node type and three-dimensional edge features—comprising task success probability, normalized service distance, and link quality—integrated via edge-gated message passing. At the decision level, the meta-controller perceives the current workload scenario through a seven-dimensional situational state vector fused with the graph embedding, selects an appropriate offloading strategy from a learned discrete action space, and drives the MILP solver to perform task-chain assignment under the selected configuration. Experiments on 60 fixed evaluation episodes spanning three representative workload scenarios demonstrate that SAGE achieves an overall reward improvement of 15.9% over the best fixed-strategy baseline, reduces the resource depletion rate to 16.7%, and maintains a high-priority task completion rate of 84.7%. Particularly under resource-constrained conditions, SAGE reduces the reward deficit by 72.3% relative to the best fixed strategy (from −0.531 to −0.147), demonstrating strong scene-adaptive decision-making capability.
A Graph-Embedded En-Route Reinforcement Learning (GEERL) framework that efficiently encodes network topology into compact graph representations by exploiting topological correlations between structure and traffic patterns, enabling fast per-hop decisions without centralized planning overhead.
Tiankuo Yu, Hui Yang, Q. Yao et al.· IEEE Open Journal of the Com...· 0 citations
Experimental evaluation on a heterogeneous synthetic benchmark demonstrates that the proposed DDQN scheduler reduces SLA violations by approximately 85% relative to Round Robin and 72% relative to the greedy baseline, while achieving superior energy efficiency.
Vishakha Makode, Taresh Ayaspure· Journal of Advances in Devel...· 0 citations
A two-timescale multi-layer deep reinforcement learning framework with a latent action space (2T-MDRL-LA) to jointly optimize service placement, user association, computational delegation, task offloading, and user transmit power and achieves near-optimal performance compared to branch-and-bound solutions.
V. Son, Van-Dinh Nguyen, Ngoc Hung Nguyen et al.· 0 citations
The emergence of 5G and 6G advanced ecosystems demands highly adaptive resource management to orchestrate the specialised requirements of eMBB, URLLC, and mMTC network slices. In dense multi-cell environments, capturing complex spatial interdependencies and mitigating dynamic interference is paramount for maintaining Q...
Aya Kh. Ahmed, Nadia Al-Aboody, Hamed S. Al-Raweshidy· International Conference on...· 0 citations
Routing optimization in cloud-edge collaborative networks faces a fundamental conflict between global strategic planning and local real-time responsiveness, further complicated by structural heterogeneity and stochastic traffic patterns. Traditional protocols lack adaptivity, while existing Deep Reinforcement Learning...
Bin Dai, Yun-Tao Wang, Jianhai Zheng· IEEE Transactions on Network...· 0 citations
A reinforcement learning-based computation offloading strategy using an improved Deep Deterministic Policy Gradient (IDDPG) algorithm that outperforms greedy offloading strategies and demonstrates improved efficiency in dynamic MEC environments.
S. Alam, Sami ud Din, Imtiaz Ali Shah et al.· International Journal of Inn...· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
Microsoft Research Blog· microsoft.comJul 13, 2026
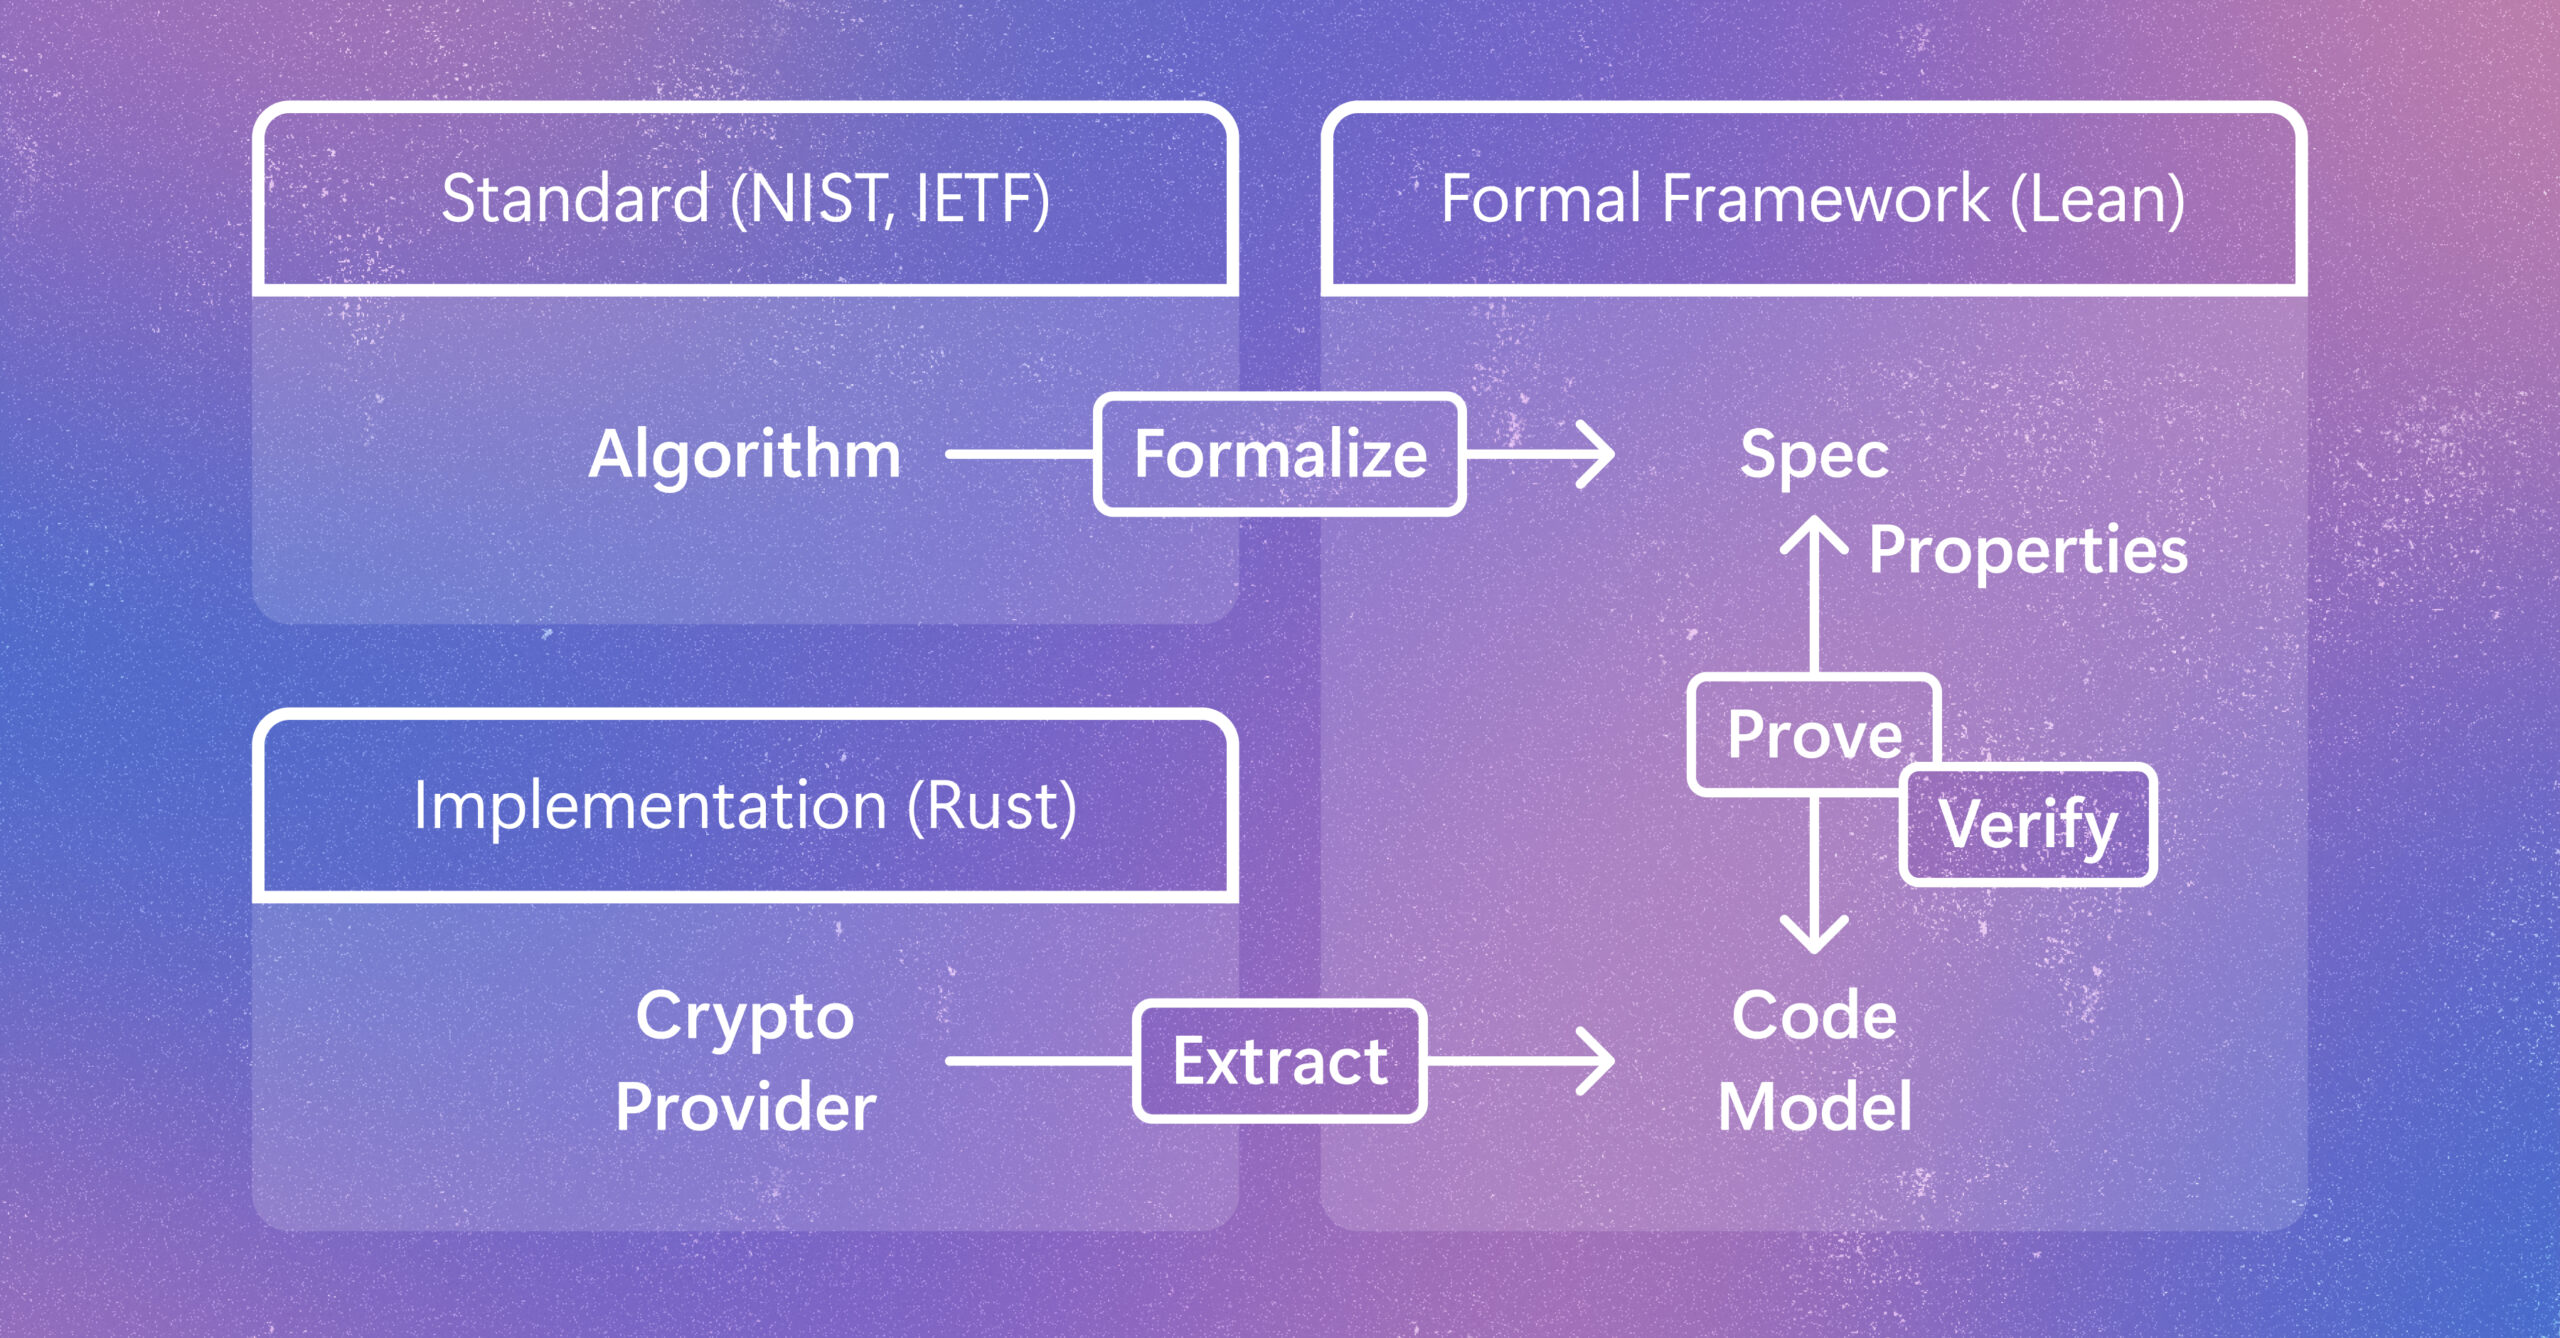
Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduJul 6, 2026
PhD student Rachel Sava, winner of the Envisioning the Future of Computing Prize, explores transformative improvements and dystopian risks of neural technology.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.