Test-time scaling can improve large language model reasoning by generating and combining multiple candidate responses. In sampling-based methods, the inference budget is often described by the number of generated candidates, N. However, N tells us how many candidates are generated, not how they are executed. The same candidate budget can be produced in one batched generation call or split across several sequential calls with smaller batch sizes. We first study the effect of increasing N on reasoning accuracy using Phi-3-mini and Qwen2.5-1.5B on 500 GSM8K prompts. As expected, increasing N from 1 to 8 improves accuracy by 8.4 percentage points for Phi-3-mini and 18.4 points for Qwen2.5-1.5B. However, accuracy alone does not show the systems cost of using a larger candidate budget. We therefore fix N = 8 and compare four generation schedules: 1x8, 2x4, 4x2, and 8x1, where axb denotes a generation calls with b candidates per call. We measure latency, throughput, GPU-hours, and gross GPU-device energy while keeping the total candidate count fixed. On A100 GPUs, eight serial calls use 4.64-4.86x as much gross GPU-device energy and have 5.77-6.12x the P95 latency of one batched call with eight candidates. The same pattern appears across three independently scheduled A100 nodes per model and in short-output SciQ/V100 experiments. These results show that candidate count alone is not enough to describe the systems cost of multi-candidate test-time scaling. When candidates are independent and memory allows it, fewer generation calls with larger batch sizes are more efficient. Evaluations should therefore report not only candidate count and accuracy, but also generation schedule and GPU-level systems metrics.

Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...
O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al.· Zenodo (CERN European Organi...· 465 citations
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.
What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduAug 18, 2026
A new method for surgically removing training examples from a model reveals that as datasets grow, the link between what a model learns and what it produces dissolves.
Microsoft Research Blog· microsoft.comJul 30, 2026
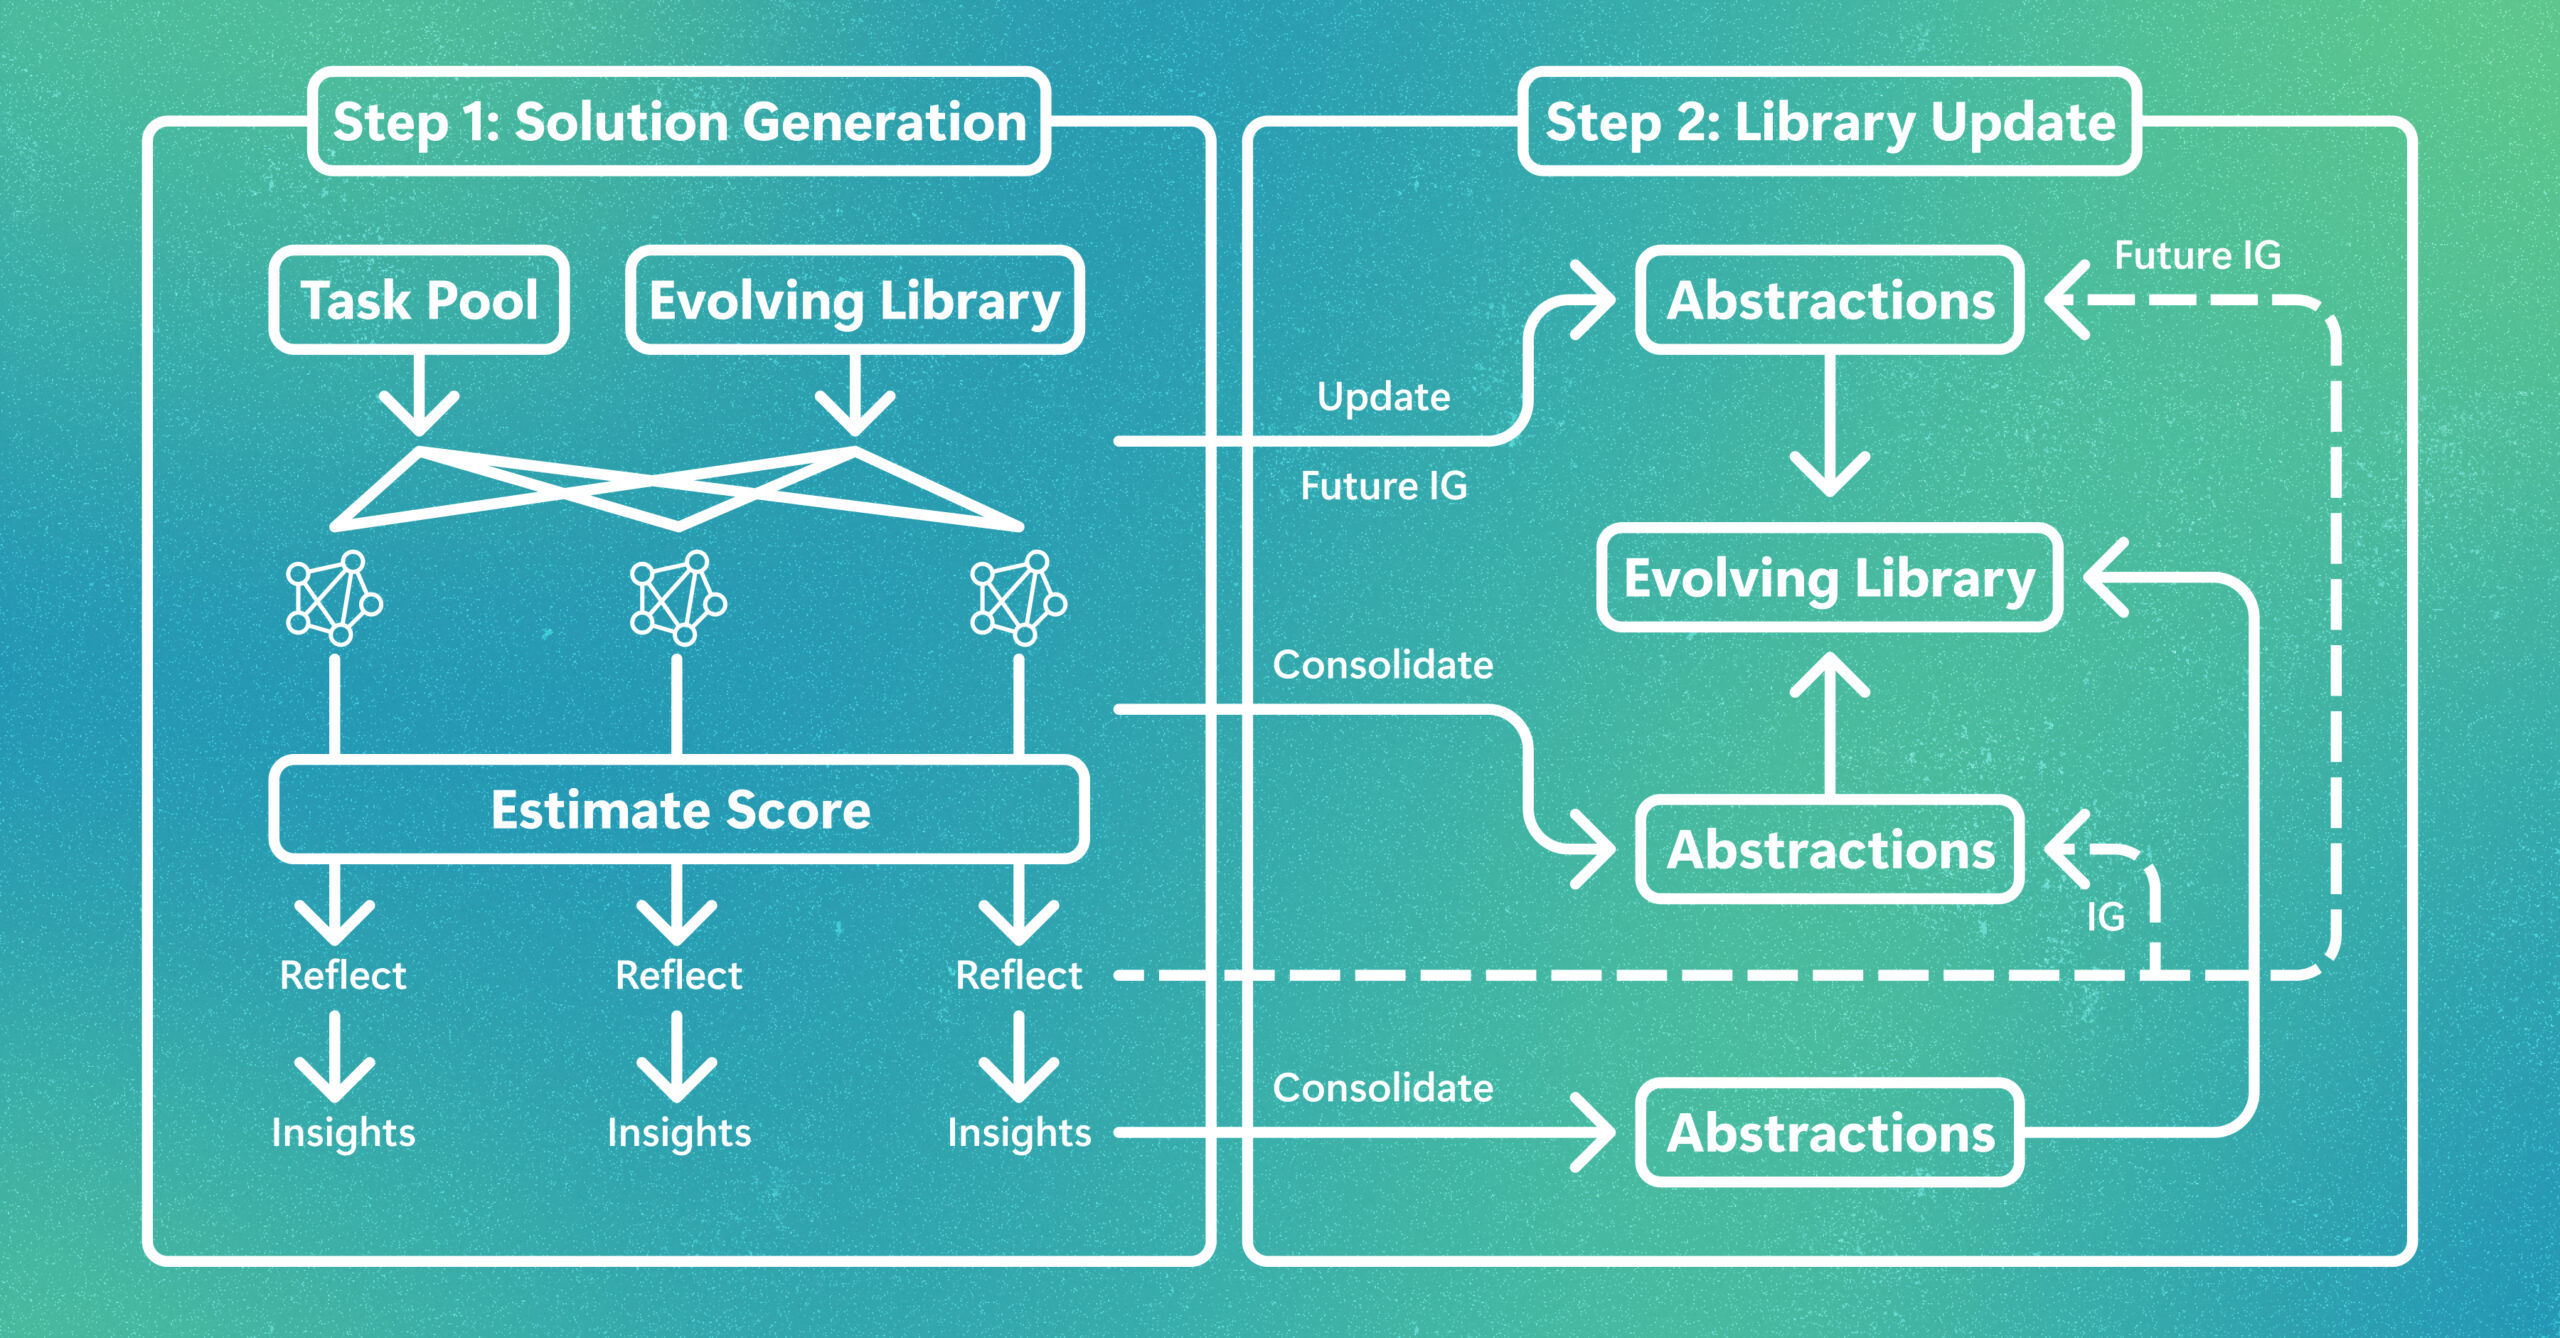
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.