Skip to content

GEM-Distill: Graph Ensemble Multi-Level Distillation for MLP-Based Graph Classification

Oct 2026 · IEEE Transactions on Knowledge and Data Engineering · Vol 38, pp. 6658-6671 · 0 citations · 66 references

Abstract

Graph Neural Networks (GNNs) achieve strong performance on graph learning tasks, but their message-passing computation hinders deployment in resource-constrained settings. GNN-to-MLP (G2M) knowledge distillation improves inference efficiency by transferring GNN knowledge to lightweight MLP students; however, existing methods mainly target node classification and generalize less effectively to graph classification, where supervision is sparse, teacher global semantics are difficult to transfer, and MLP students have limited structural expressiveness. This paper presents GEM-Distill, a graph ensemble multi-level distillation framework for MLP-based graph classification. GEM-Distill assigns graph-, subgraph-, and node-level objectives to granularity-specific MLP experts and coordinates them through a sequential coarse-to-fine training strategy, mitigating cross-granularity optimization conflicts while preserving complementary structural supervision. It further introduces Virtual-Neighbor Guided Graph Distillation (VNGD), a training-only graph-level distillation module that enriches global supervision by mixing semantically related training graphs. Experiments on standard and large-scale graph classification benchmarks show that GEM-Distill achieves competitive or stronger performance than existing G2M baselines while retaining efficient MLP-style inference. Additional analyses on robustness, parameter-aligned comparisons, efficiency, and teacher architectures further support the effectiveness and practicality of the framework.
View source

Similar papers

Conference Open access Sep 2026

ADC-GNN: Adaptive Dual-level Collaborative Graph Neural Networks for Graph Classification

This work proposes a novel Adaptive Dual-level Collaborative GNN associated with an adaptive dual-level collaborative mechanism, and shows that the ADC-GNN can inject the learned high-level information back into the node level, forming a closed-loop, bidirectional optimization process.

Wan Tang, Lu Bai, Li-Xin Cui et al. · 0 citations
Open access Sep 2026

GTAP: Graph Topology-Aware Pre-Training for Graph Classification

GTAP (Graph Topology-Aware Pre-training), a self-supervised initialization framework for within-dataset graph classification, improves over a matched GCN trained from scratch and achieves competitive accuracy against published baselines on most datasets with available results.

Chao-Chao Hu, Zhao-Hui Zhang · 0 citations
Conference Open access Sep 2026

HGOOD: Hypergraph-enhanced Graph Contrastive Learning for Graph Out-of-Distribution Detection

A Hypergraph-enhanced graph contrastive learning framework for Graph Out-Of-Distribution detection (termed HGOOD), which constructs two branches to hierarchically mine graph compact semantics in a comprehensive manner and introduces a cross-branch prototype contrast that aligns the captured graph patterns with their cr...

Xuan-Ting Fan, Chen-Yu Wang, Yue-Yue Gao et al. · 0 citations
#machine learning Preprint Sep 2026

PreGS: A Parameter-Transfer-Based Multi-Expert Graph Neural Network for Node Classification

This paper proposes PreGS, a parameter-transfer-based multi-expert graph neural network framework, and develops PreGSv2, which introduces source-level weighting and a structural gating mechanism for adaptive multi-source feature integration.

Zhi Cai, Yinglong Zhang, Xiao-Ying Hong et al. · 0 citations
Open access 2026

AUGKD: Adaptive Universal Graph Knowledge Distillation

Graph data distillation frameworks have shown great potential in compressing graph representations and improving learning efficiency. Nevertheless, their robustness and generalization remain limited when applied to different graph neural network architectures. To address these limitations, we propose Adaptive Universal...

Jun-Qi Liu, Yu Xie, Tian-Jun Ma et al. · 0 citations
#artificial intelligence Preprint Sep 2026

Scalable GNN-based Knowledge Graph Representation Learning with Efficient Message Passing

This work extends Relational Sparse Matrix Multiplication (RSPMM), originally designed to losslessly lower the space complexity of composition-based MP with pointwise composition functions, to support more expressive functions (e.g., 2x2 block-diagonal matrix multiplication, Givens rotation, circular correlation).

Huu Tan Mai, Cuong Xuan Chu, Heiko Paulheim et al. · 0 citations

Related blog posts

Microsoft Research Blog Jul 13, 2026

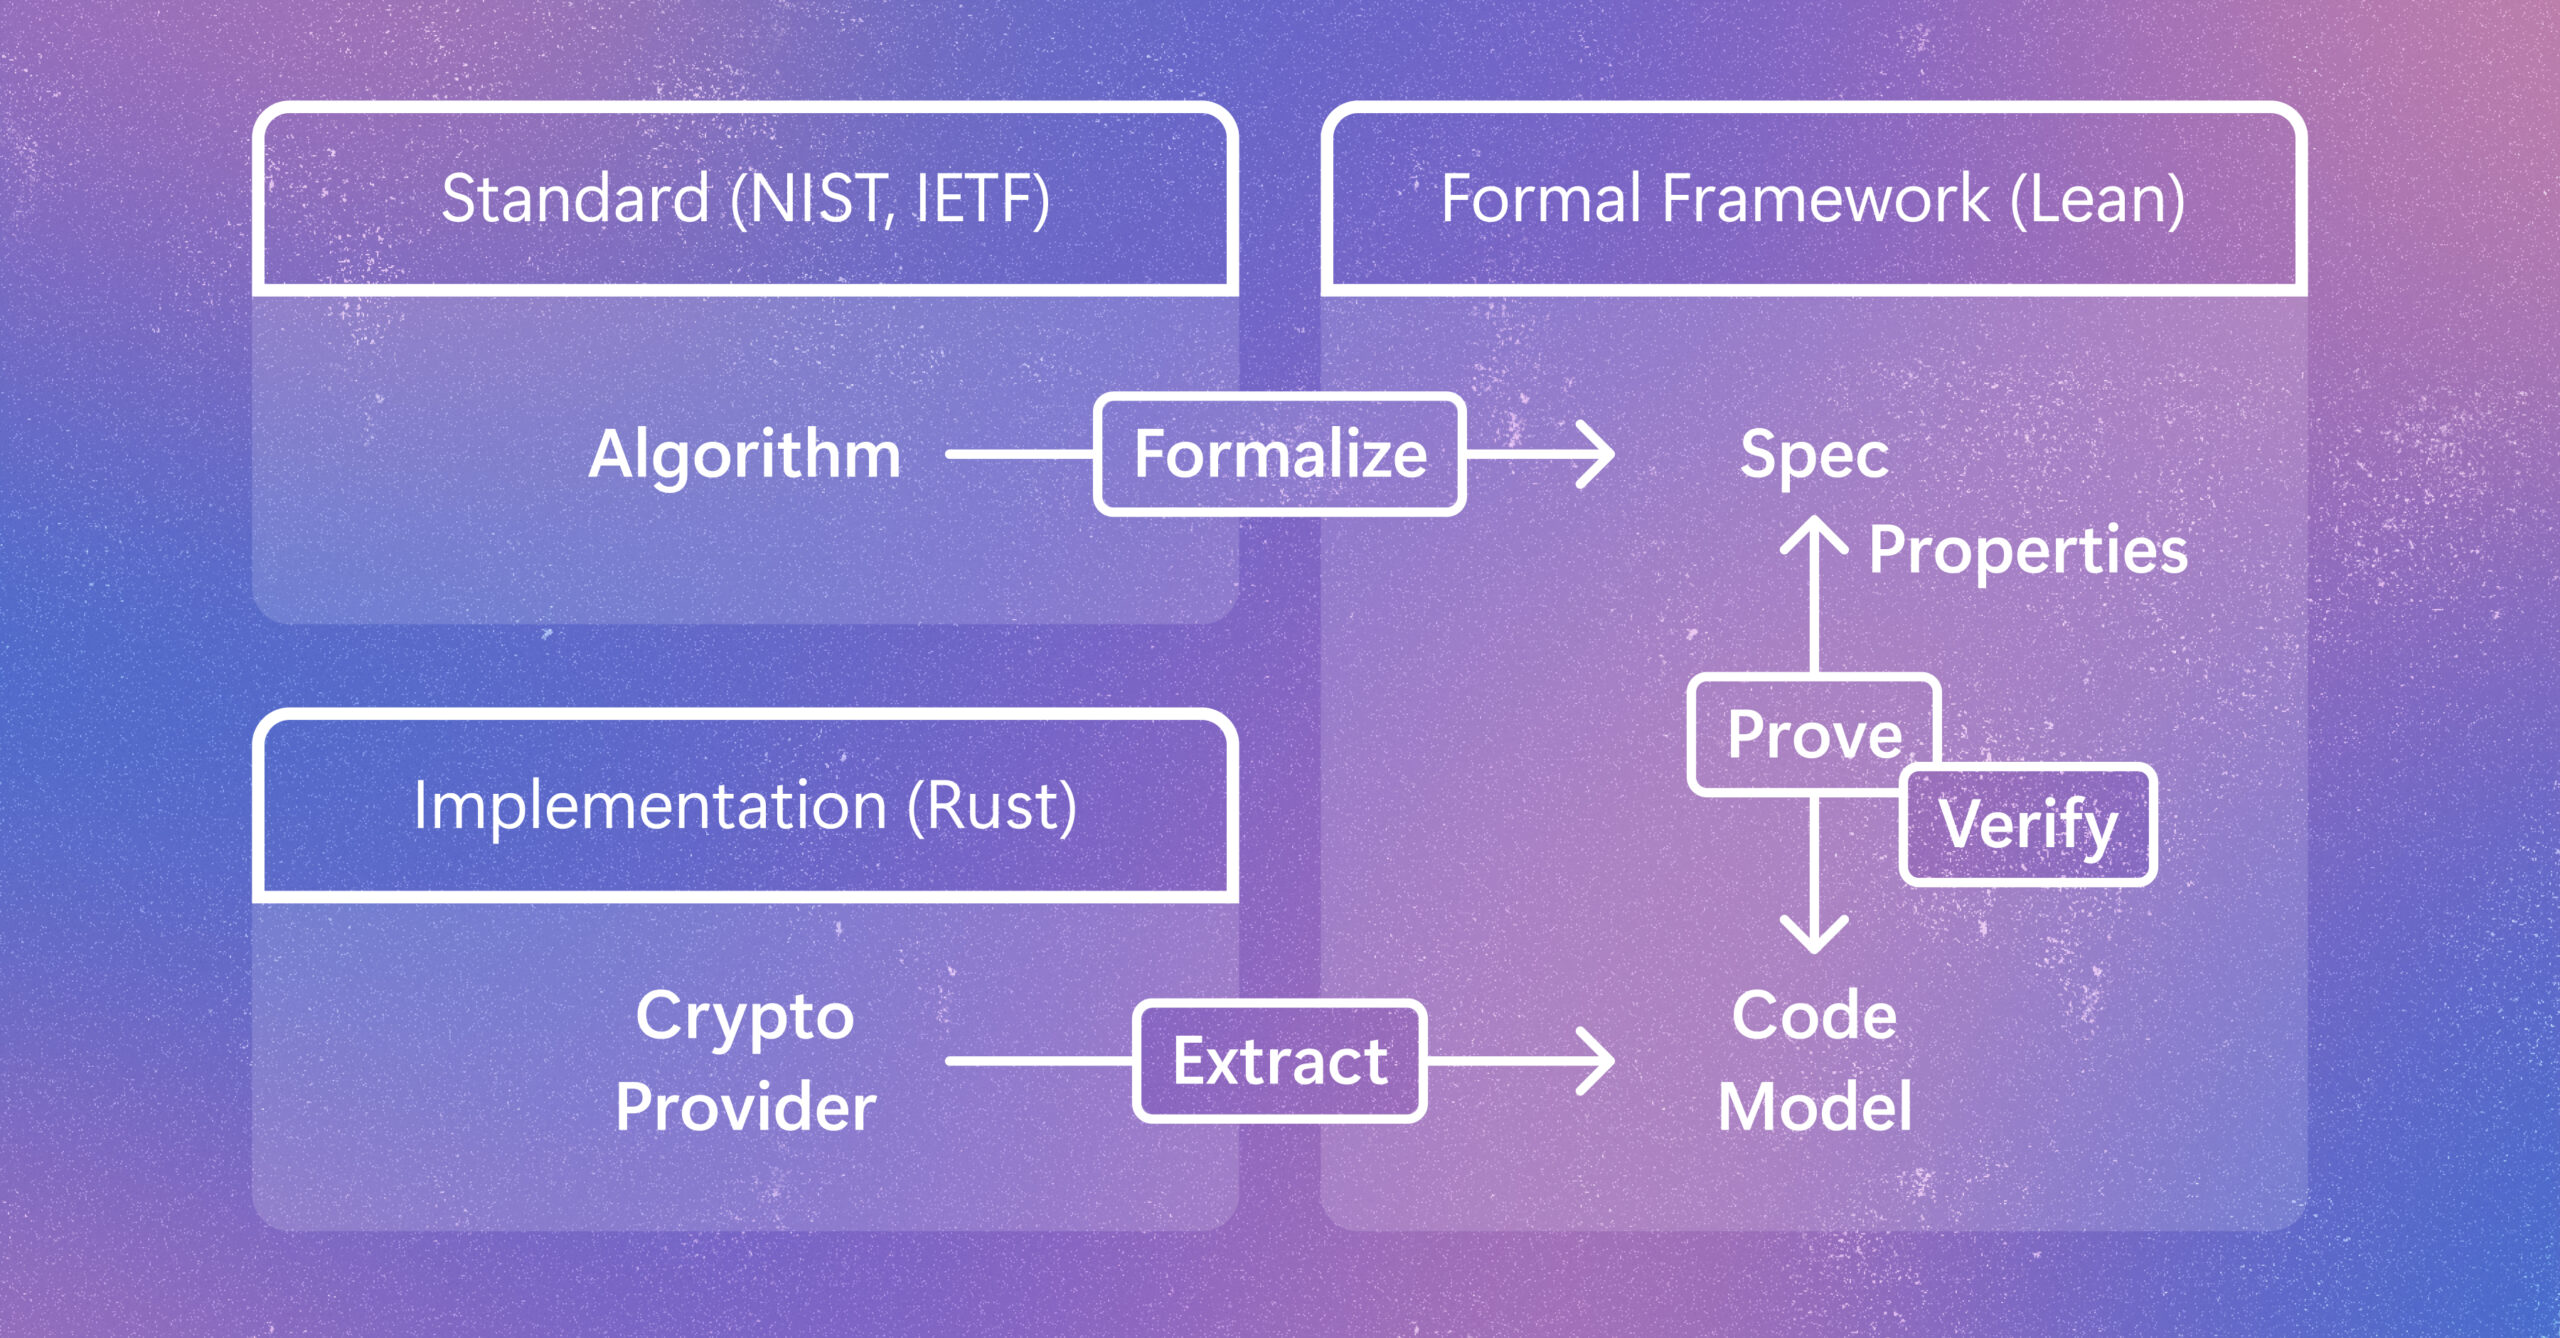
Verifying Rust cryptography in SymCrypt, from standards to code

Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.