A framework for this localization problem is developed by assigning to each observation its conditional or marginal contribution across random statistical contexts, which connects resampling diagnostics and data valuation to projection theory and event-level anomaly detection.
It is shown that, in the sample limit, I-FLOP recovers a DAG in the same interventional Markov equivalence class as the data-generating DAG, where it performs favorably in terms of both performance and run time.
It is shown that the MEM dual problem admits a reformulation as an expected risk minimization problem, thereby placing MEM within the modern framework of stochastic optimization and enabling scalable stochastic gradient algorithms for large-scale inverse problems.
Matthew King-Roskamp, Gabriel Rioux, R. Choksi et al.· 0 citations
A mathematical theory of superposition in neural networks using tools from frame theory and compressed sensing and a novel characterization of the distribution of signs in the Gram matrix is developed.
Michael I. Ivanitskiy, J. Jasper, Emily J. King et al.· 1 citation
Reach audiences
Advertise in front of researchers, engineers, and readers.
This paper examines the closed form of the Wasserstein distance in one dimension via node feature probability distributions, and shows how the transport plans of the Wasserstein and Gromov-Wasserstein distances visualize how mass is shifted to transform one network into another.
Generalized Gibbs Ensemble Weighting is developed, a probabilistic framework that treats forecasting models as experts and assigns ensemble weights using a Gibbs-style exponential transformation of normalized predictive loss and produces a family of related methods, including Stable Gibbs weighting, Directional Gibbs-N...
Prasen R. Nuthanakaluva, Nava K. Gaddam· 0 citations
This framework separates temporal alignment, plasticity, forgetting, and bounded rehearsal in recurrent sequence models, together with numerically stable positive-decay renormalization, to remain competitive in language modeling and improve length extrapolation on variable-digit addition.
Yi-Fan Zhang, Steve Ta, Jasper Zhang et al.· 0 citations
This work presents a systematic study of scale vectors in LLMs from the perspectives of expressivity, optimization, and architectural structure, and proposes three lightweight and complementary improvements to scale vectors: branch-specific heterogeneity, improved placement around linear mappings, and magnitude-directi...
This work proposes Mixture of Activations (MoA), a token-adaptive FFN design that mixes a dictionary of activation functions using lightweight input-dependent gates while sharing the same linear projections, suggesting that token-adaptive activation mixing is a simple and effective mechanism for improving FFN expressiv...
This paper designs Markov decision processes (MDPs) for different combinatorial problems and proposes to train conditional GFlowNets to sample from the solution space and demonstrates that GFlowNet policies can efficiently find high-quality solutions.
Dinghuai Zhang, H. Dai, Esmeralda S. Whitammer et al.· Advances in Neural Informati...· 59 citations· ⚡8
A general framework for synthetic-augmented inference across a population of related tasks is developed, which characterizes synthetic augmentation by the number of synthetic observations and their weight and specifies a size-weight frontier that specifies, for each weight, the largest synthetic sample size for which a...
It is shown, through a theoretical study of the dynamics and numerical experiments, that a finite privacy budget can outperform non-private estimation in the long term when the feedback loop between leakage and participation is sufficiently strong.
Uddalak Mukherjee, Edwige Cyffers, Y. Chevaleyre· 0 citations
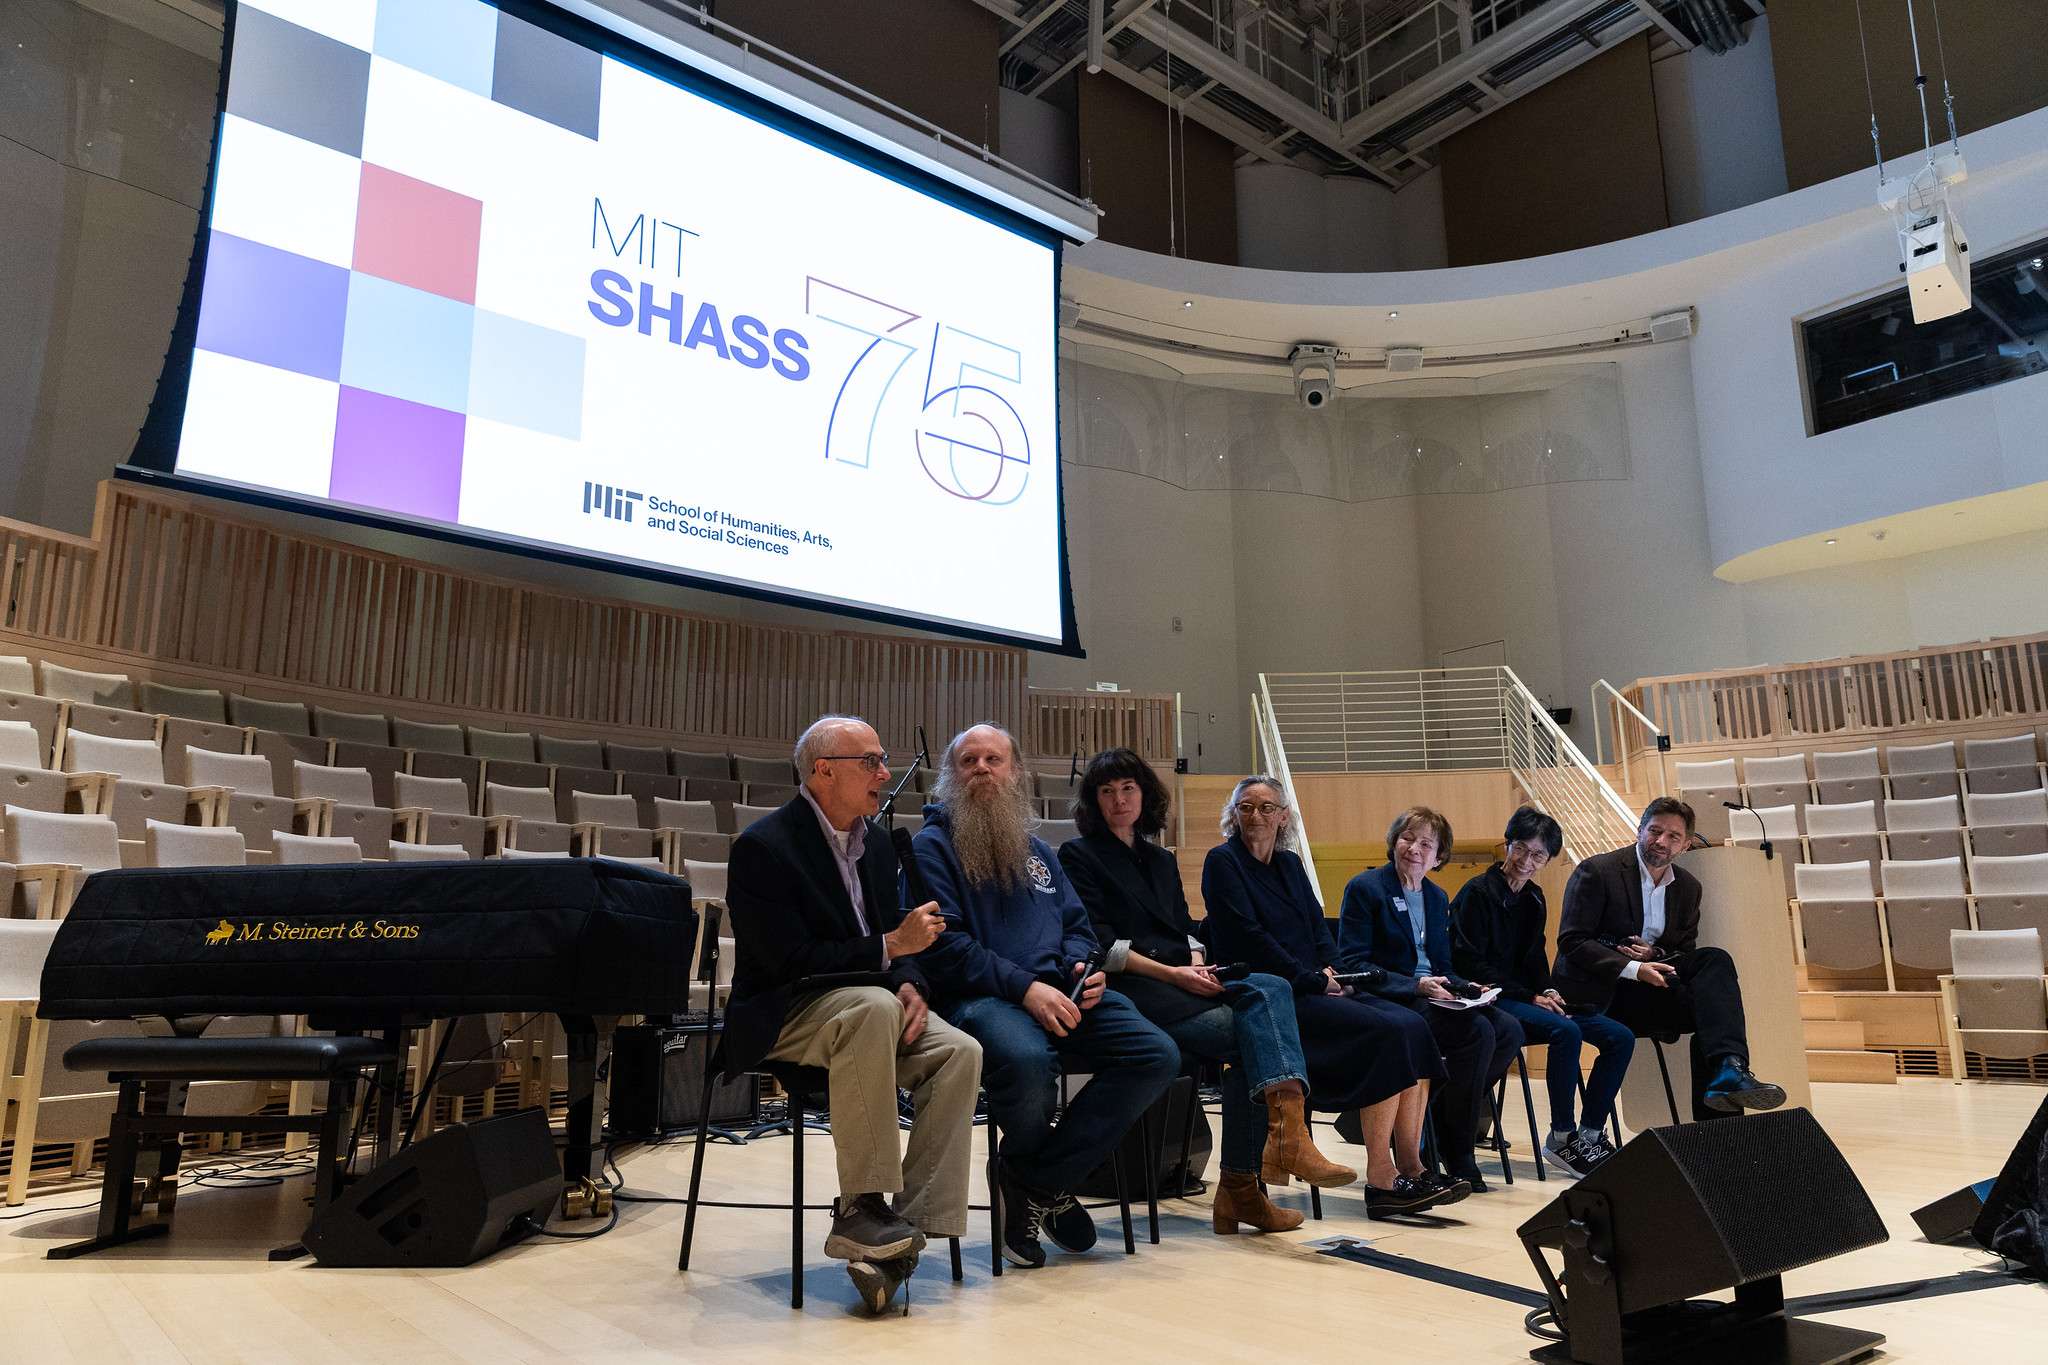
During the School of Humanities, Arts, and Social Sciences’ 75th Anniversary Symposium, President Sally Kornbluth said “MIT has never needed your particular insight and guidance more than we do now.”
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.