Mar 2026· arXiv.org· Vol abs/2603.26747· 1 citation· 16 references
Computer Science
TL;DR
Comparing diffusion and rectified flow objectives within the MotionGPT3 framework suggests that several known benefits of rectified flow objectives do extend to continuous-latent text-to-motion generation, highlighting the importance of the training objective choice in motion priors.
Abstract
Recent text-driven motion generation methods span both discrete token-based approaches and continuous-latent formulations. MotionGPT3 exemplifies the latter paradigm, combining a learned continuous motion latent space with a diffusion-based prior for text-conditioned synthesis. While rectified flow objectives have recently demonstrated favorable convergence and inference-time properties relative to diffusion in image and audio generation, it remains unclear whether these advantages transfer cleanly to the motion generation setting. In this work, we conduct a controlled empirical study comparing diffusion and rectified flow objectives within the MotionGPT3 framework. By holding the model architecture, training protocol, and evaluation setup fixed, we isolate the effect of the generative objective on training dynamics, final performance, and inference efficiency. Experiments on the HumanML3D dataset show that rectified flow converges in fewer training epochs, reaches strong test performance earlier, and matches or exceeds diffusion-based motion quality under identical conditions. Moreover, flow-based priors exhibit stable behavior across a wide range of inference step counts and achieve competitive quality with fewer sampling steps, yielding improved efficiency-quality trade-offs. Overall, our results suggest that several known benefits of rectified flow objectives do extend to continuous-latent text-to-motion generation, highlighting the importance of the training objective choice in motion priors.
This work proposes FlashMo, a frequency-aware sparse motion diffusion model that prunes low-frequency tokens to enhance efficiency without custom kernel design, and introduces MotionSiT, a scalable diffusion transformer based on a joint-temporal factorized interpolant with Lie group geodesics over SO(3) manifolds, enab...
Zeyu Zhang, Yiran Wang, Danning Li et al.· Neural Information Processin...· 11 citations
Text-to-motion generation aims to synthesize semantically consistent and naturally coherent motion sequences from natural language descriptions. Given the continuous nature of human motion, diffusion models operating in a continuous latent space offer inherent advantages over vector quantization-based methods, particul...
Zhaowu Li, Rui Liu, Deheng Zhu et al.· Visual Computing for Industr...· 0 citations
Video motion transfer aims to animate a target object using dynamics from a reference video. Existing formulations largely rely on fixed structural correspondence, which becomes ill-defined when reference and target objects differ substantially in morphology, articulation, or deformation mechanisms. We introduce Motion...
Zhixue Fang, Zhimin Zhang, Bi'an Du et al.· 0 citations
Text-to-motion generation must produce motions that are semantically correct, temporally coherent, and physically plausible. A natural approach is to first project motion data into a structured semantic space and then train a generative model within that space. Such a paradigm has been highly successful in image genera...
Yifei Zhu, Mingyi Shi, Yangyang Cai et al.· 0 citations
Diffusion-based text-to-motion models synthesize realistic human motions but often exhibit semantic drift from the input text. Motion is inherently temporal, especially in compositional and long-duration sequences that require semantic consistency across multiple action segments and smooth kinematic transitions through...
Sakuya Ota, Qing Yu, Kent Fujiwara et al.· 0 citations
Generation in video diffusion or flow models is computationally expensive due to the slow and iterative sampling process. Current state-of-the-art (SOTA) acceleration methods heavily rely on variational score distillation (VSD) and adversarial losses to distill diffusion models into few-step generators. Albeit achievin...
Neta Shaul, Chao Liu, Arash Vahdat et al.· 0 citations
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
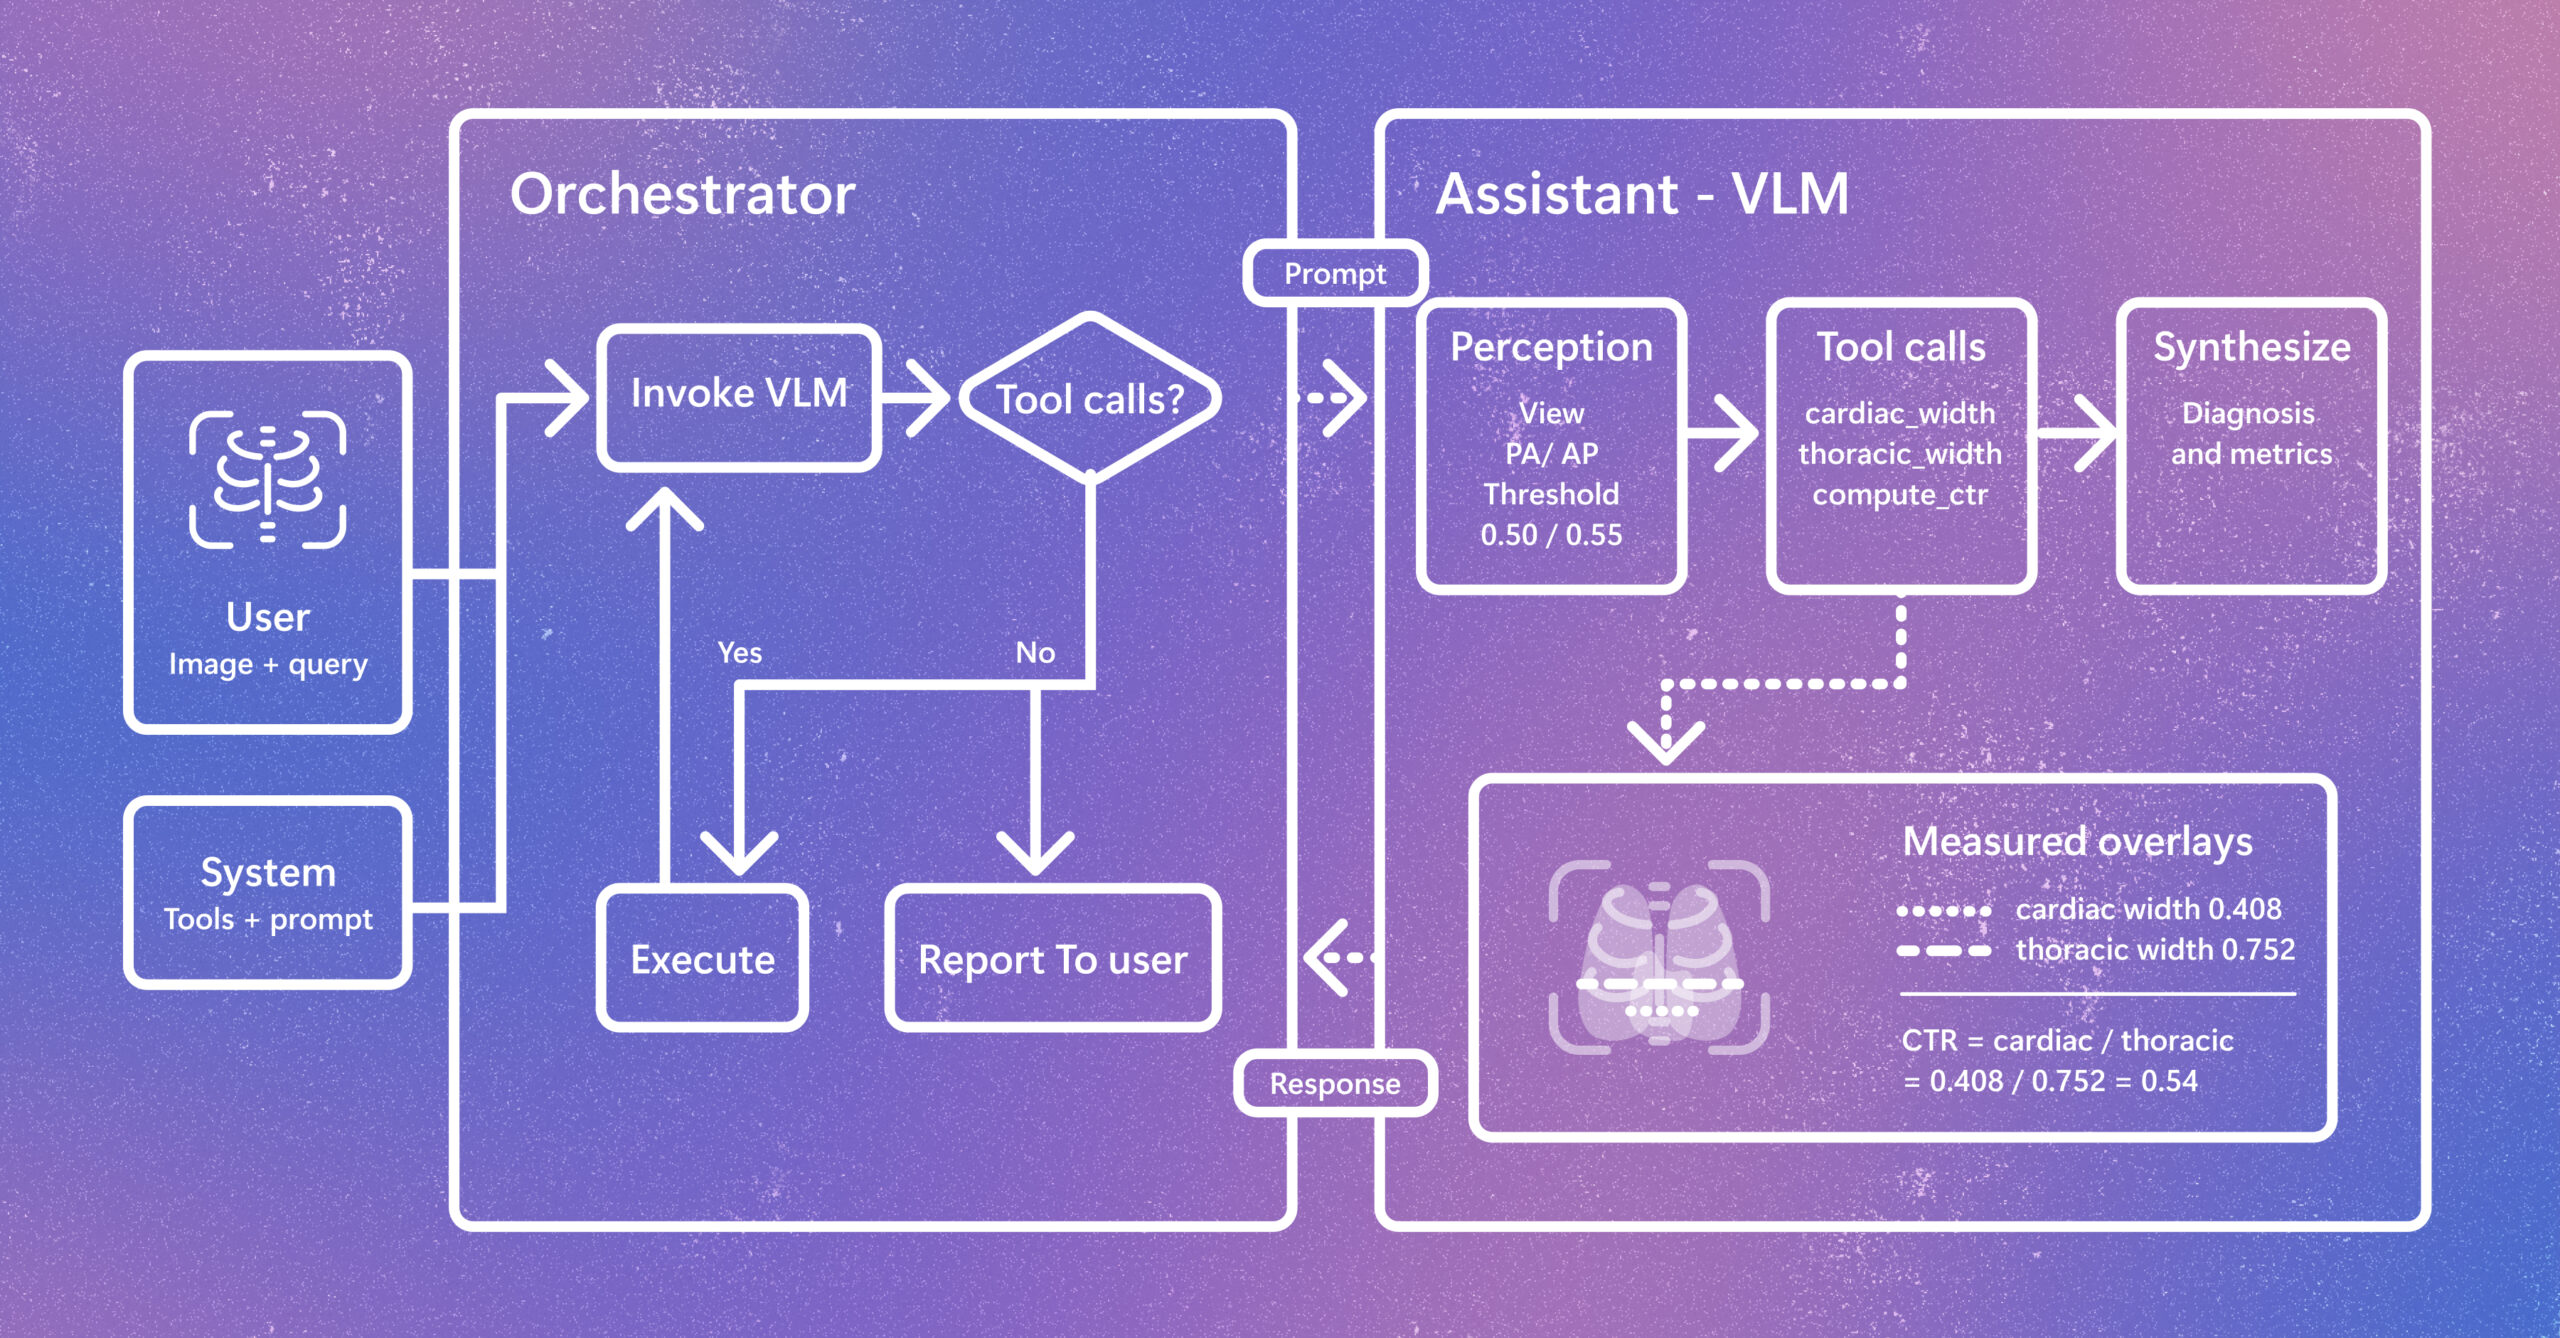
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
