An Implicit Cultural Alignment Reward Model built upon a lightweight 4.2-billion-parameter Multimodal Large Language Model (MLLM) integrated with a Skip-connection Cross-Attention mechanism, enabling late-stage semantic features to directly attend to early-stage visual representations and better preserve culturally salient details.
Abstract
As Text-to-Image (T2I) systems rapidly advance, evaluating the cultural authenticity of synthesized content has become increasingly important for fair and trustworthy generative AI. Existing T2I evaluation metrics and multimodal judges often rely on visual-semantic representations that underrepresent implicit cultural norms, leading to biased preference judgments and the omission of fine-grained cultural cues. In addition, visual question answering (VQA)-based evaluators typically depend on autoregressive text generation, which limits their scalability for real-time reward modeling. To address these limitations, we introduce an Implicit Cultural Alignment Reward Model built upon a lightweight 4.2-billion-parameter Multimodal Large Language Model (MLLM). Our framework integrates an Implicit Cultural Probe with a Skip-connection Cross-Attention (SkipCA) mechanism, enabling late-stage semantic features to directly attend to early-stage visual representations and better preserve culturally salient details. Evaluations on 3,323 challenging and carefully curated image pairs from the CulturalFrames benchmark show that our approach achieves 82.12% pairwise accuracy, with Pearson and Kendall correlation coefficients of 0.585 and 0.412, respectively, outperforming representative vision-language metrics and MLLM-based evaluators. Moreover, by bypassing autoregressive text generation, our model processes each evaluation in 0.21 seconds under our local inference setup, achieving a $10\times$ speedup over standard VQA-based evaluators. These results suggest that the proposed reward model can provide an efficient and culturally aware scalar signal for preference optimization pipelines such as Reinforcement Learning from Human Feedback and Direct Preference Optimization. Additional resources are available on our project page at https://bensonch1214.github.io/Implicit_Cultural_Alignment/.
This work proposes Snap2Review, a novel framework that harmonizes cross-modal retrieval with fine-grained preference learning, and introduces Tri-DPO, which employs a stratified negative sampling strategy with varying difficulty levels to force the model to discern fine-grained user preferences.
Honggyan Xu, Lei Zou, De-Xiang Zhao et al.· Proceedings of the Thirty-Fi...· 0 citations
A Multi-dimensional Evaluation-Verification Reward (EVR) decomposes evaluation into distinct visual criteria; for each criterion, an MLLM Evaluator generates multiple candidate hypotheses, and a Verifier grounds each claim in concrete visual evidence to accept or reject it, producing reliable and fine-grained reward si...
This work introduces SON-1K, a comprehensive benchmark for text-to-image generation, and proposes a new approach, the enhanced LMDpp, enhancing the performance of the novel two-stage Large Language Model (LLM)-grounded diffusion model pipeline (LMD).
Weiyue Li, Yi Li, Xiaoyue Wang et al.· 0 citations
VLTok is a novel 1D hybrid tokenizer that unifies V isual and L anguage representations in a shared Tok en space through a self-prompted training paradigm, and achieves state-of-the-art performance in both image reconstruction and image generation.
Hualiang Wang, Siming Fu, Wei-Nan Jia et al.· 0 citations
Results show that although current models achieve strong semantic adherence and visual quality, they often fail to faithfully capture fine-grained cultural details, particularly for underrepresented regions, rituals, and multimodal cultural cues.
Xian-Jing Han, Yuhan Su, Yang Deng et al.· 2 citations
MonkeyOCRv2, a visual-text pretrained model for document AI, is presented, and a pretraining strategy that jointly learns image-to-text generation and pixel-level document reconstruction is proposed: the former aligns visual representations with textual content, while the latter preserves character strokes and layout d...
Yuliang Liu, Zhang Li, Ziyang Zhang et al.· 3 citations
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
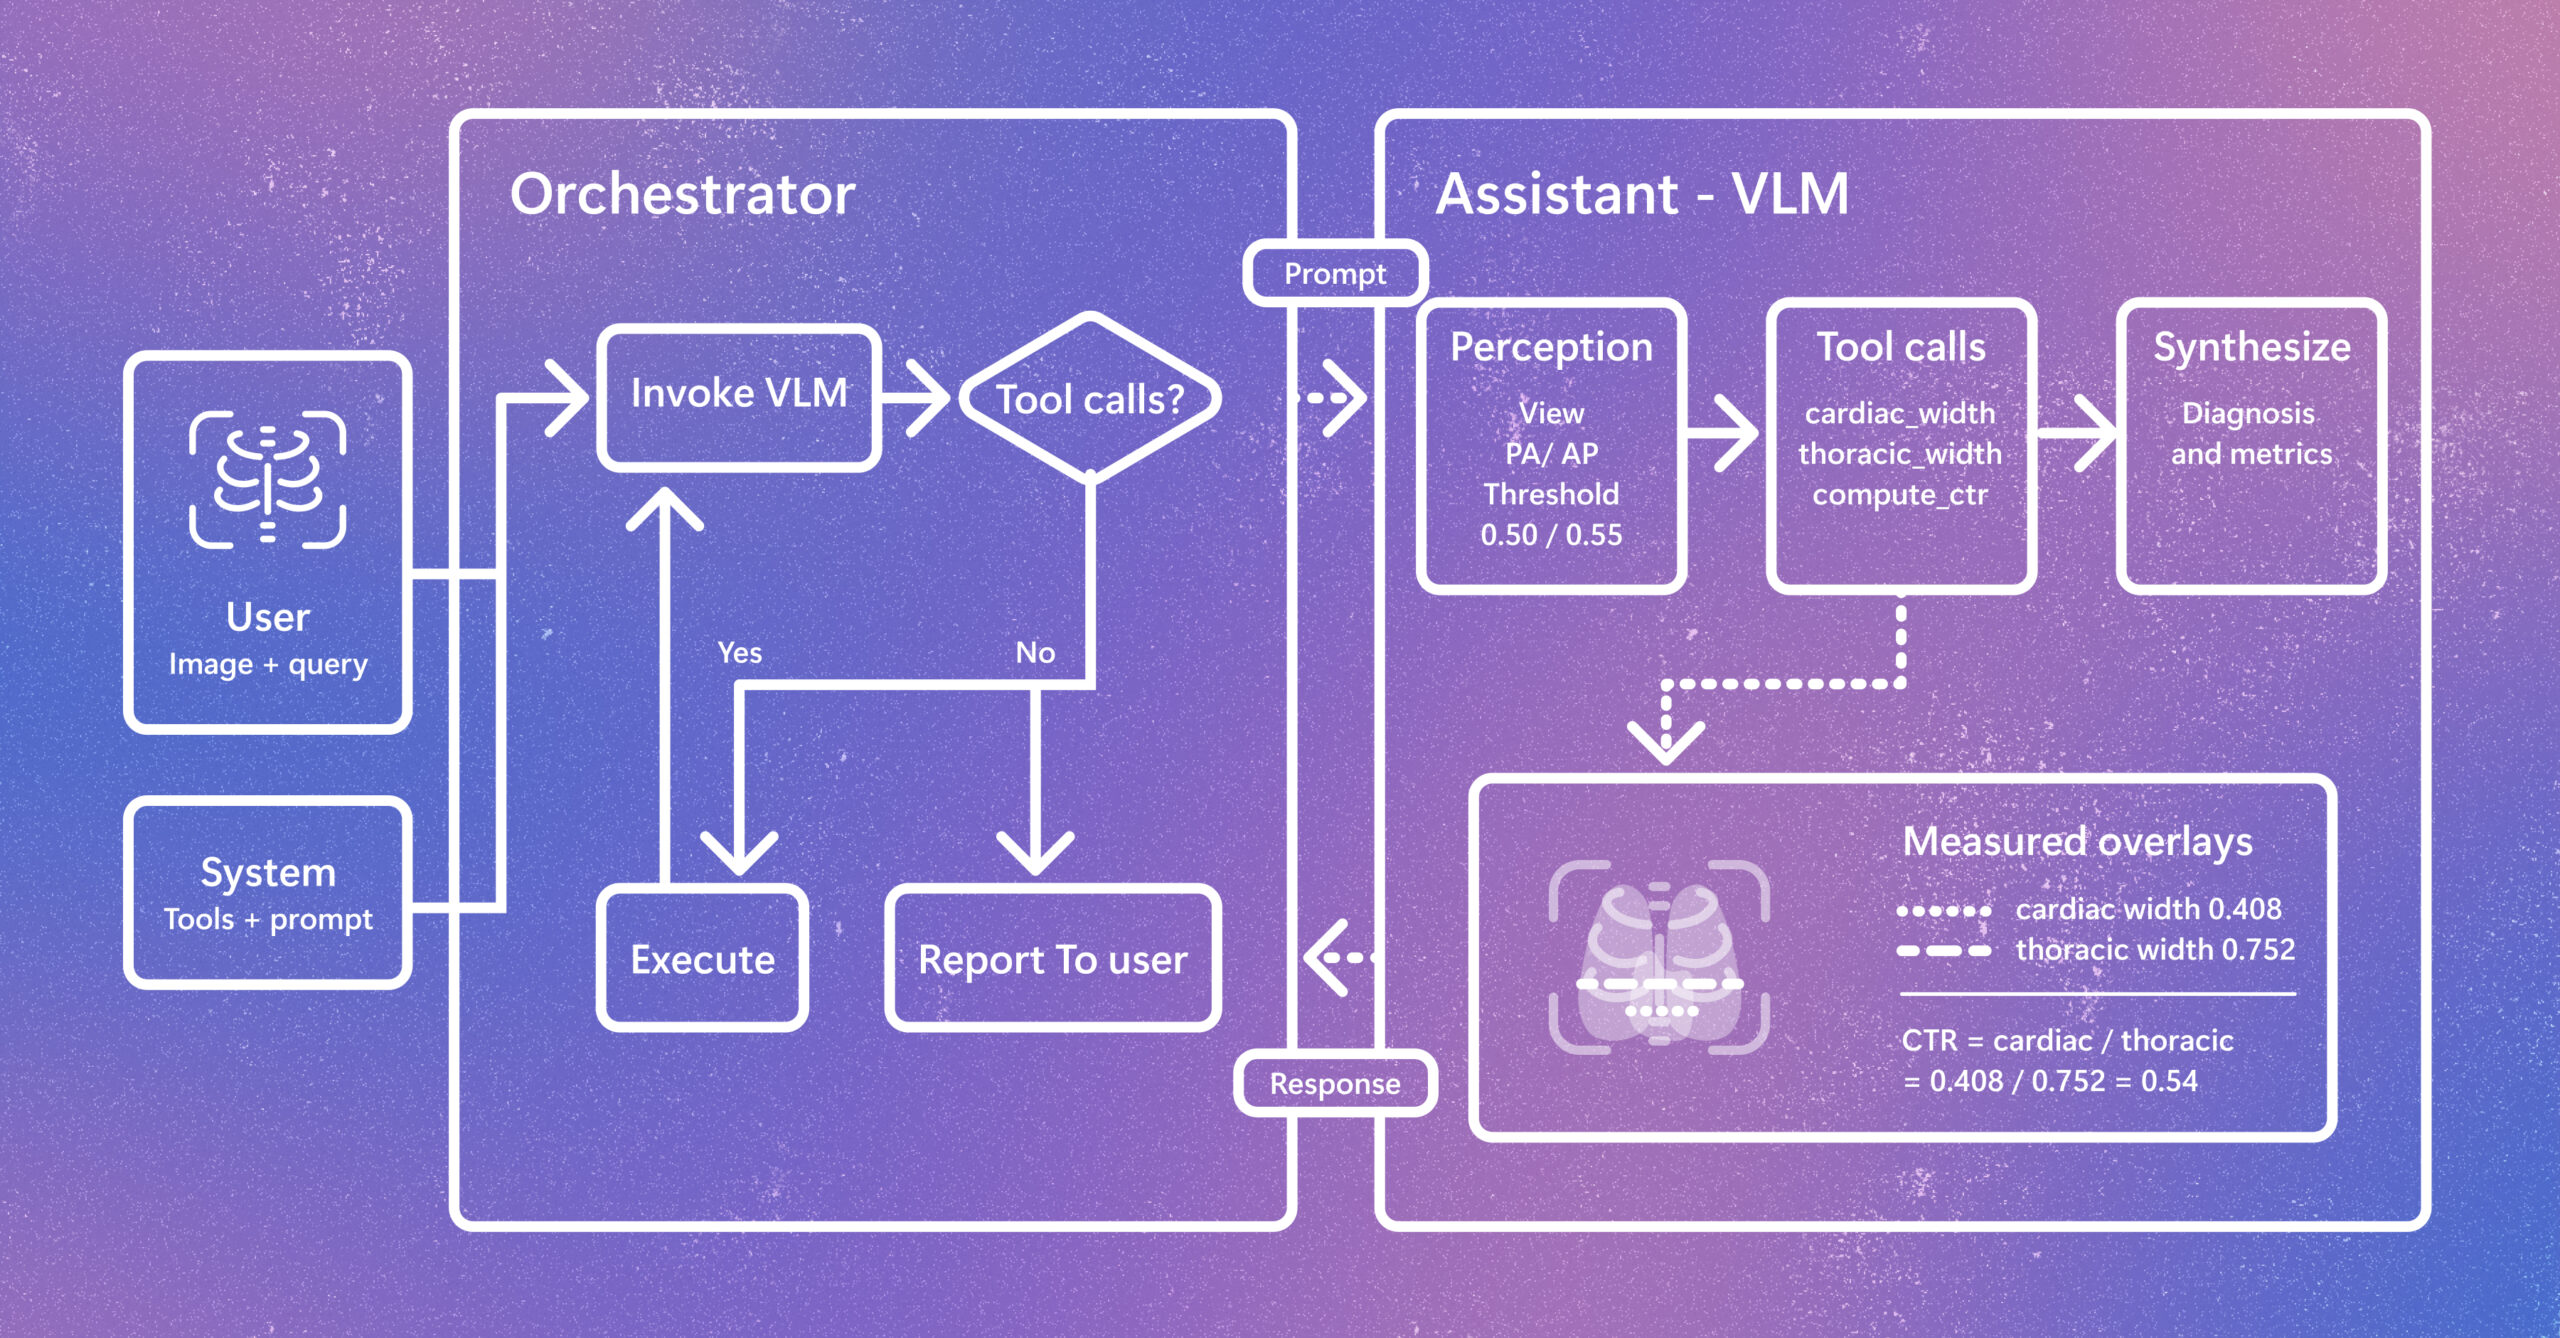
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.