Skip to content

Looking Beyond the Scale: Do Surgical Skill Models Learn Transferable Representations Across Assessment Rubrics?

Aug 2026 · 0 citations · 33 references
Computer Science

TL;DR

Results indicate the visual component is dominant but not solely responsible for skill prediction; further work is needed to conclusively disentangle transferable skill features from those bound to a specific visual domain.

Abstract

Vision-based surgical skill assessment has shown strong in-domain results, yet a fundamental question remains unasked: do these models learn transferable representations of surgical proficiency, or do they merely encode dataset-specific visual patterns? This paper systematically analyzes what limits cross-domain skill transfer between the GOALS and OSATS assessment scales using the LASANA and JIGSAWS datasets. Each evaluated method serves a targeted diagnostic purpose: end-to-end training to test whether supervised skill learning transfers directly, Adaptive Sharpness-Aware Minimization (ASAM) to probe whether flatter loss landscapes improve generalization, and augmentation-based self-supervised and contrastive learning to assess whether domain-invariant pretraining decouples skill from visual context. Transfer is evaluated in both directions using a disjoint-participant held-out test set for JIGSAWS. Results reveal an asymmetry: backbones pretrained on JIGSAWS achieve CCC values of 0.77 to 0.80 on LASANA, closely matching the end-to-end baseline, showing cross-rubric transfer is feasible when the target domain provides consistent supervision. Transfer to JIGSAWS fails across all methods, likely due to annotation inconsistencies. Control experiments with a Kinetics-pretrained backbone suggest task-specific heads carry the majority of the skill prediction burden, while the backbone need only provide adequate spatiotemporal features. These findings offer a new perspective on vision-based skill assessment: the central question of whether skill representations transfer across scoring systems has not been previously investigated. Results indicate the visual component is dominant but not solely responsible for skill prediction; further work is needed to conclusively disentangle transferable skill features from those bound to a specific visual domain.

View source

Similar papers

Open access Aug 2026

Multimodal AI for automated assessment of surgical performance

Accurate and objective assessment of surgical skill is crucial for improving training outcomes, ensuring patient safety, and enabling scalable evaluation across clinical and simulation contexts. Current approaches often depend on subjective human ratings or unimodal analysis, limiting reliability and applicability in r...

Shekhar Madhav Khairnar, H. Nguyen, Sofia Garces-Palacios et al. · 0 citations
#artificial intelligence Preprint Aug 2026

Do Medical Vision Models Reason About Anatomy? Probing the Spatial Inductive Biases of Learned Visual Representations

The results suggest medical vision encoders carry a map of where organs usually lie, and little of the machinery for comparing structures within a particular patient, in addition to five architectural configurations and three medical foundation models, frozen and finetuned.

Naren Akash, Neeraja Ramanan · 0 citations
Preprint Jul 2026

Self-Supervised Visual Representation Learning: Pretrain-Finetuning or Joint Training?

This work systematically investigate whether jointly optimizing the self-supervised and supervised objectives during training provides a better alternative, and finds that JT consistently improves data and training efficiency while being robust in low-label settings, while PFT is more reliable in more specialized domai...

Nusrat Munia, Tyler Ward, Nishat Nayla et al. · 0 citations
#computer vision Preprint Aug 2026

LookBack: Where and How to Score LVLM Responses via Visual Reference Usage

LookBack, a training-free LVLM response scoring method that augments token likelihood with visual lookback score, a lightweight measure of how strongly each response token refers to image tokens, consistently improves Best-of-$N$ selection over existing baselines with negligible additional overhead.

Beomsik Cho, Jin-Ha Kim, Dongseok Lee et al. · 0 citations
Preprint Aug 2026

ToolVision: Learning When and How to Use Visual Tools with Capability-Aligned Supervision

ToolVision is introduced, a model that improves over its base on all seven main benchmarks, surpasses Thyme-7B, CodeVision-8B, and CodeDance-7B on all three high-resolution benchmarks, and outperforms Qwen3-VL-32B-Thinking on V* and HRBench 8K.

Delin Mao, Cheng-Hao Sun, Jing-Wei Song et al. · 1 citation
Preprint Jul 2026

Learning How Much, Not Just What: Cross-Patient Burden Order for CT Vision-Language Pretraining

Volumetric CT vision-language pretraining learns 3D representations from scan-report pairs, but global and anatomy-aware objectives supervise only correspondence: they establish what is present and leave how much unconstrained. Nothing separates a mild from an extensive case of the same finding along a consistent direc...

Guo-Liang You, Haifan Gong, Xiaomeng Chu · 0 citations

Related blog posts

Microsoft Research Blog Aug 11, 2026

Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

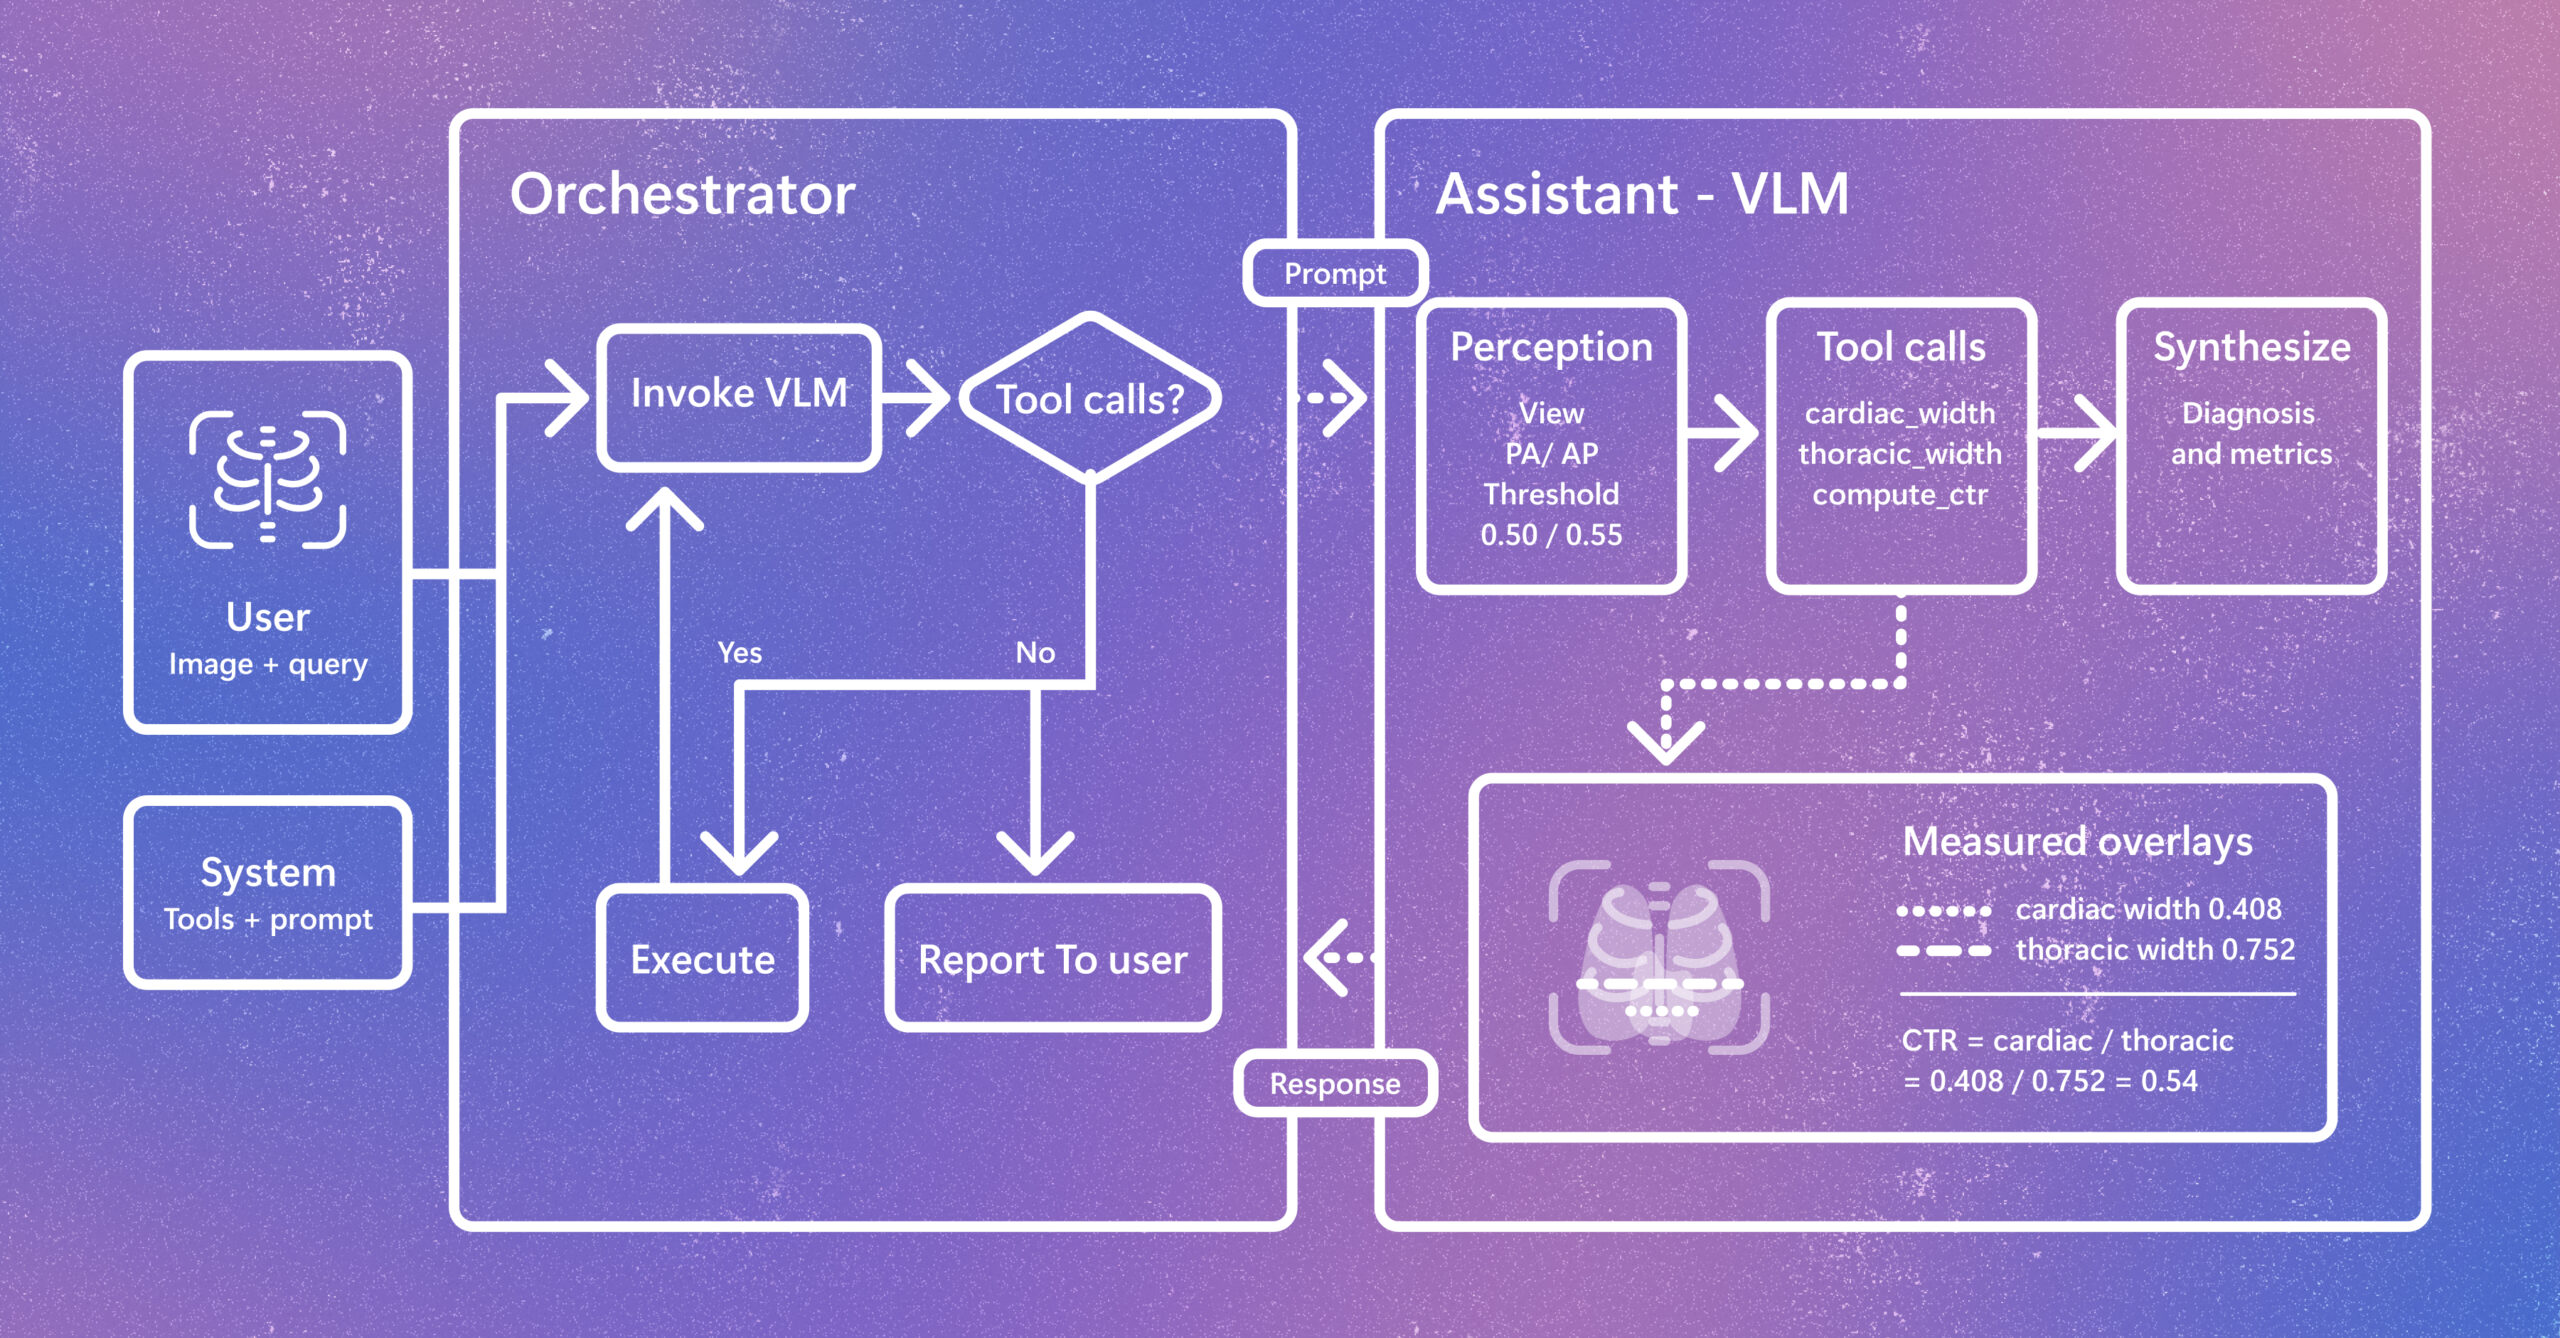
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.