Capsule Lens is introduced, a framework that matches the region a concept occupies with a simple, trackable geometric form, a capsule, defined by several interpretable parameters, fitted in closed form to each concept's geometry and validated on held-out samples.
Abstract
Understanding how concepts are encoded in the internal representations of machine learning models is a central problem in mechanistic interpretability, essential both for the science of deep learning and for the trustworthy deployment of increasingly capable models. Existing approaches to interpret model representations mainly map representations onto more interpretable spaces and do not directly characterize how concepts occupy representation space; various hypotheses have been proposed, but often lack of rigorous validation and largely focus on static representations. In this work, we introduce Capsule Lens, a framework that matches the region a concept occupies with a simple, trackable geometric form, a capsule, defined by several interpretable parameters, fitted in closed form to each concept's geometry and validated on held-out samples. We apply Capsule Lens in two major settings: static and dynamic representations. On static representations, we demonstrate how to locate concept geometry across various models, and how the span and norm curves uncover important geometric characteristics. On dynamic representations, we present three case studies tracking representation drifts induced by distinct training settings, CLIP pretraining, RL post-training on visual question answering, and RL post-training on mathematical reasoning. These analyses reveal qualitatively different geometric dynamics, ranging from broad network-wide restructuring in CLIP pretraining to localized and concept-specific changes in RL post-training. Our results include findings aligned with existing literature as well as novel observations. We believe Capsule Lens stands as a promising tool for locating, analyzing, and tracking concept geometry in both static and dynamic representations.

Concept-based vision models represent images through an intermediate layer of human-inspectable concepts, so what a model relies on can be traced to those concepts. However, those models are often limited to fixed categories or depend on language to define their concepts. We introduce DisParQ (Discrete Parts with Quant...
Adam Pardyl, Siddhartha Gairola, Sukrut Rao et al.· 0 citations
This work repurposes pretrained video generative models as a unified and data-efficient framework for geometry estimation, formulated innovatively as a next-frames prediction task, and inherits naturally structured knowledge and richer priors from the video model, enabling more data efficient and effective learning of...
Haosen Yang, Ji-Fei Song, Zhensong Zhang et al.· 1 citation
Perceiving and remembering the visual world is fundamental to navigating and interacting with our environment. Current 4D foundation models, such as camera-controllable video models or 4D reconstruction models, can perceive and reconstruct dynamic environments, but how well they remember what they have perceived remain...
How do we tell a world model what information to preserve? We study this question through the lens of spectral representation learning. We introduce SpecWM, a JEPA framework that explicitly specifies desired relationships between observations through a target similarity kernel and trains the encoder to reproduce those...
Holger Molin, William Peng, M. Bagatella et al.· 0 citations
This paper examines the role of Novel View Synthesis (NVS) in geometric representation learning. In principle, NVS should reason about 3D scene structure, thereby enabling transferable multi-view geometric representations. Yet, existing encoder-based NVS methods yield poor representations. This is not because of a lack...
Keerthi Kaashyap, D. Anthony, Akshay Krishnan et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
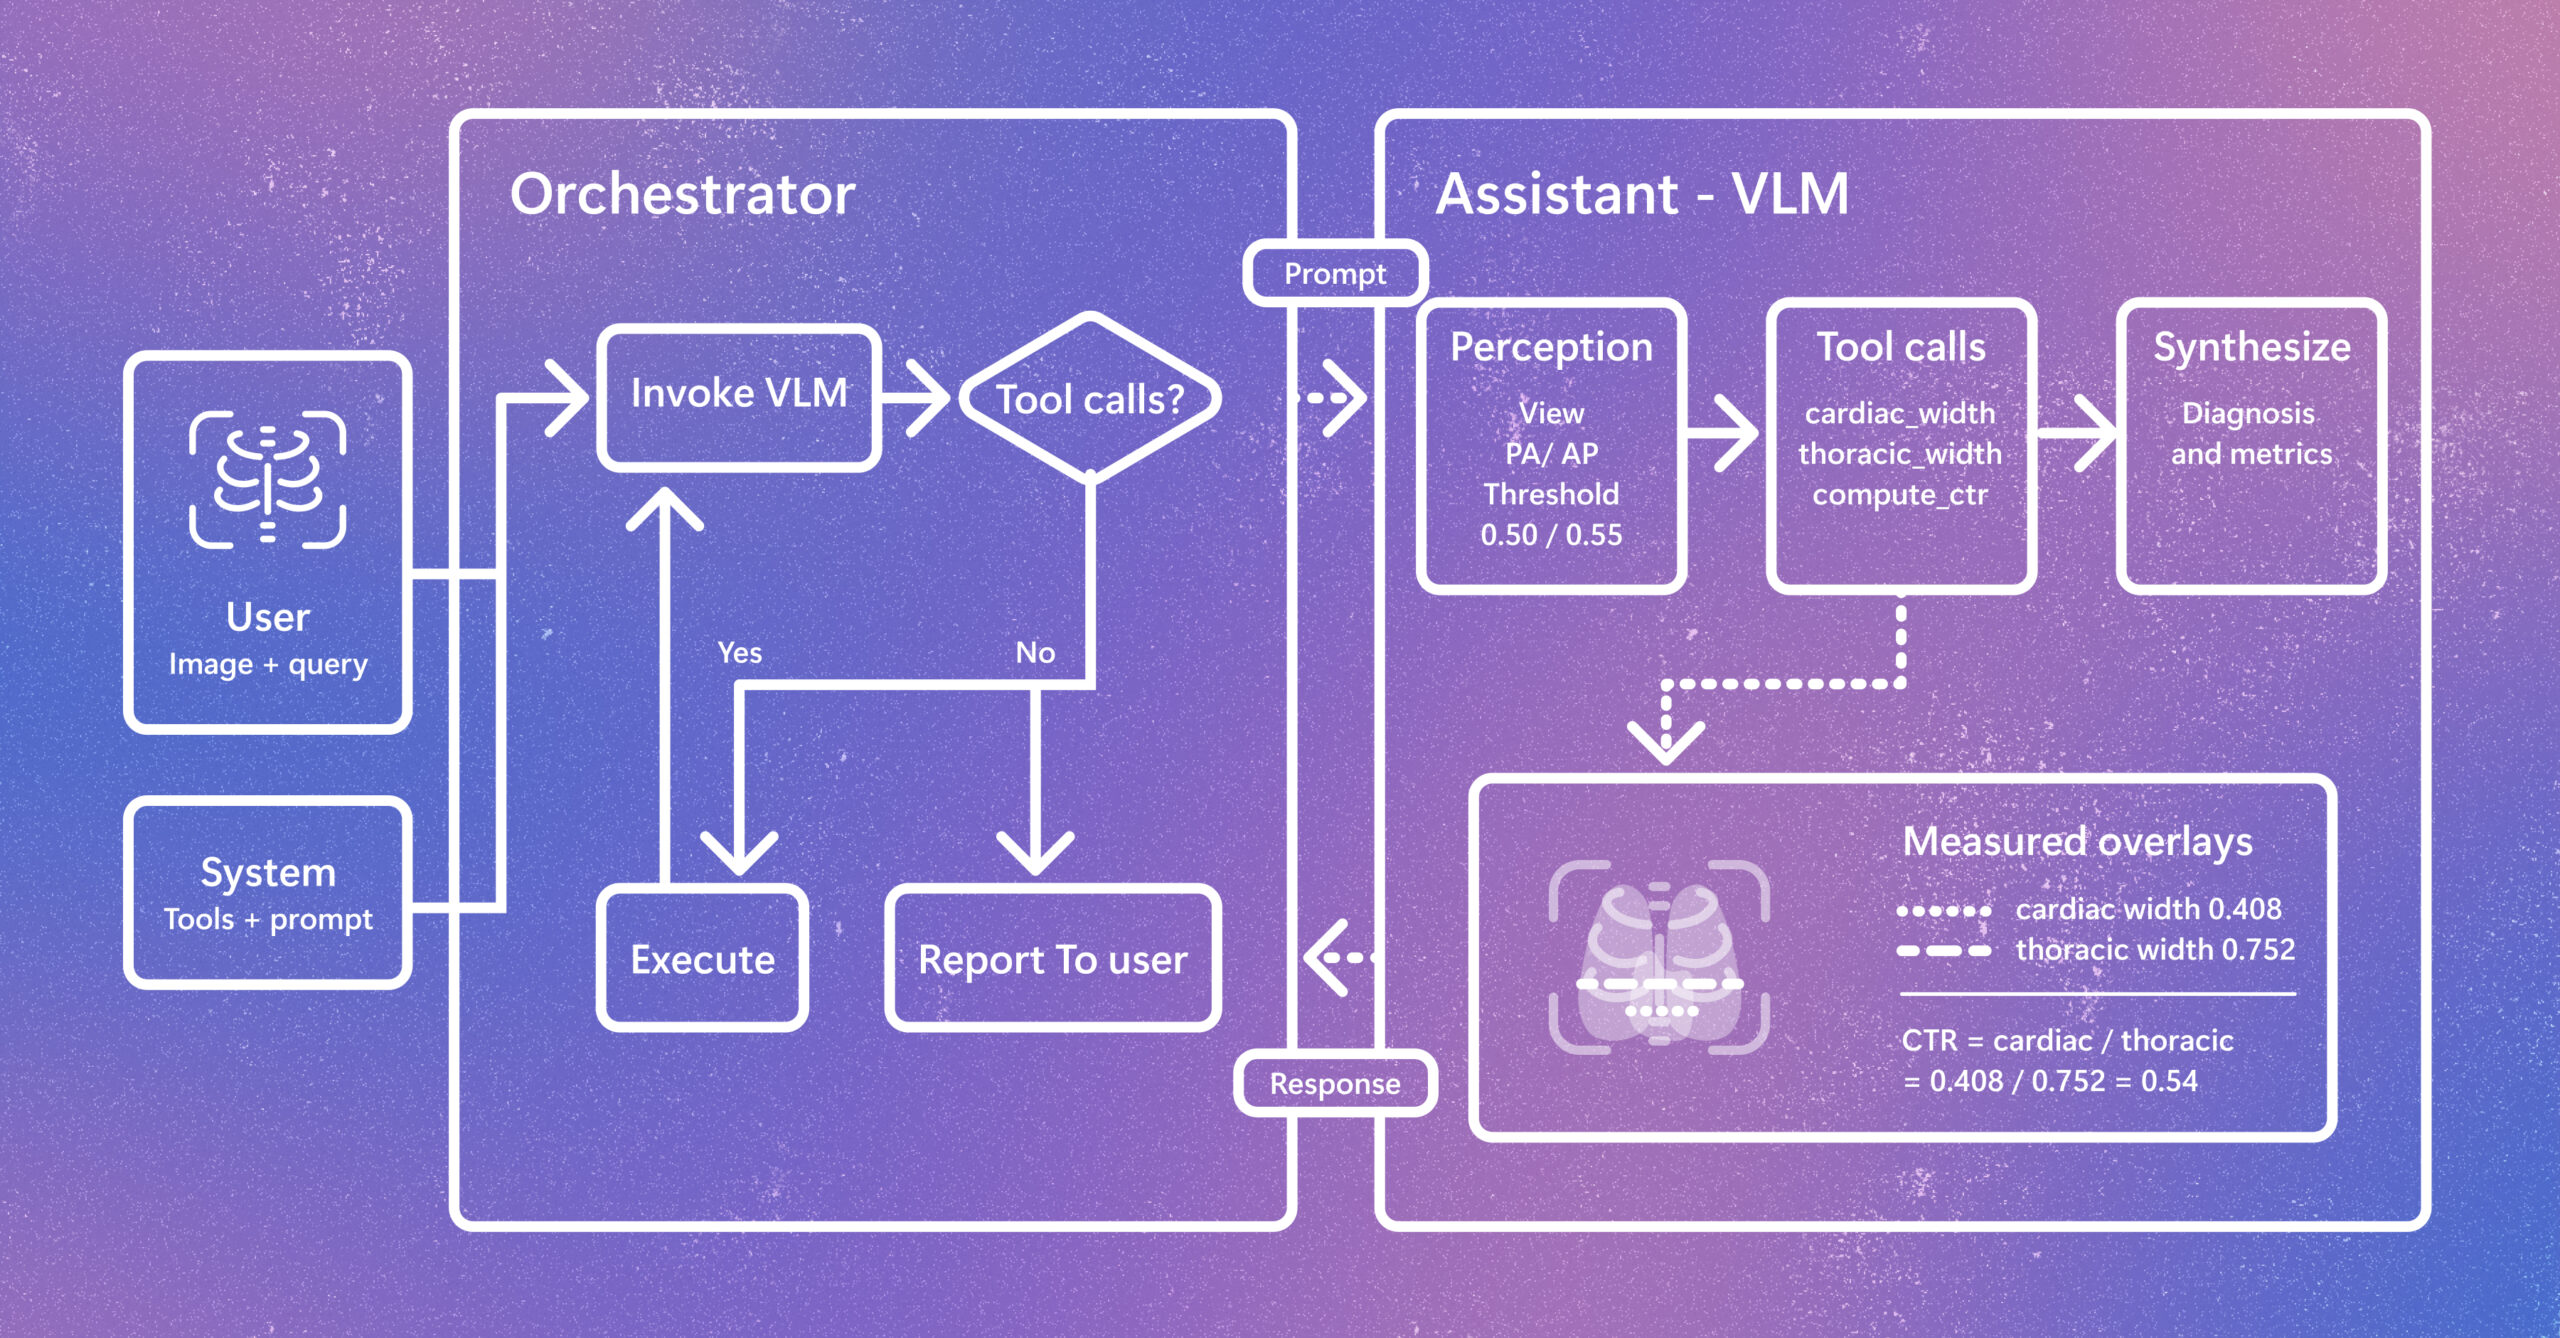
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.