Nov 2026· Proceedings of the 35th ACM International Conference on Information and Knowledge Management· pp. 3917-3927· 0 citations· 6 references
Machine Learning and Data Classification
Abstract
How can we accurately train a binary node classifier on heterophilic graphs when only positive and unlabeled nodes are available? This setting commonly arises in real-world applications such as fraud detection, where only detected fraudsters are labeled as positive, while the remaining users are unlabeled and may include both normal users and undetected fraudsters. The key challenge is that heterophilic edges connect nodes from different classes, causing conventional graph-based PU methods to propagate label-inconsistent information. At the same time, simply suppressing such edges discards useful higher-order homophilic information connected through heterophilic paths. This creates a trade-off between reducing negative transfer and preserving structural information, which is further complicated by the absence of negative labels. We propose Sipu, an accurate graph-based PU learning method for heterophilic graphs. Sipu models the given unsigned graph as a latent signed graph, where positive and negative signs correspond to homophilic and heterophilic relations, respectively. Through sign-aware propagation, Sipu mitigates negative transfer from heterophilic neighbors while preserving higher-order homophilic information through positive paths. To accurately estimate unobserved edge signs, Sipu iteratively refines the classifier and the edge-sign estimates using node-label and edge-homophily marginals computed via graphical inference as soft targets. Extensive experiments on multiple datasets demonstrate that Sipu gives state-of-the-art performance, consistently outperforming existing graph-based PU learning methods.
How do we classify nodes accurately on heterophilic graphs when training labels are infected by neighbors' majority classes? In many real-world applications, annotators lack sufficient evidence for each node in isolation and thus rely on its neighborhood context, causing labels to drift toward the neighborhood majority...
Hoyoung Yoon, J. Kim, U. Kang· Proceedings of the 35th ACM...· 0 citations
HeteGCD is proposed, a new statistics-aware dual-prototype learning perspective for generalized category discovery on heterophilous graphs that combines feature-based similarity with distribution-based consistency to support category discovery.
Xi Xu, Tong-Ze Zhang, Zhi-Li Qin et al.· 0 citations
An affinity-guided rewiring method that estimates the graph and the node representation together and alternates, in the spirit of expectation maximisation, between training a lightweight graph neural network on the current graph and re-weighting candidate edges under a modularity objective with a pseudo-label homophily...
Harshit Kumar, Sujan Chakraborty, Priyanka Saha et al.· arXiv.org· 0 citations
Graph neural networks are widely used for transductive node classification, with accuracy typically measured on randomly drawn train/validation/test splits. Reported accuracy has been shown to shift substantially across different random splits of the same dataset, making published comparisons between architectures unre...
Naga Venkata Sai Jitin Jami, Thomas R. Altstidl, S. Hoefler et al.· arXiv.org· 0 citations
Detecting fraud on financial transaction networks is difficult for three reasons that tend to appear together: fraudulent users deliberately disguise their behavior, their activity is linked to other entities through several distinct relation types, such as a shared merchant, a shared rating or a short time window, and...
Experimental results on real-world datasets demonstrate that SHEAR significantly outperforms existing methods in fake news detection, showcasing the benefits of incorporating behavioral semantic patterns with network motifs for enhanced classification performance.
Shuo Yu, Yu-Peng Gao, Jing Ren et al.· IEEE Transactions on Neural...· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
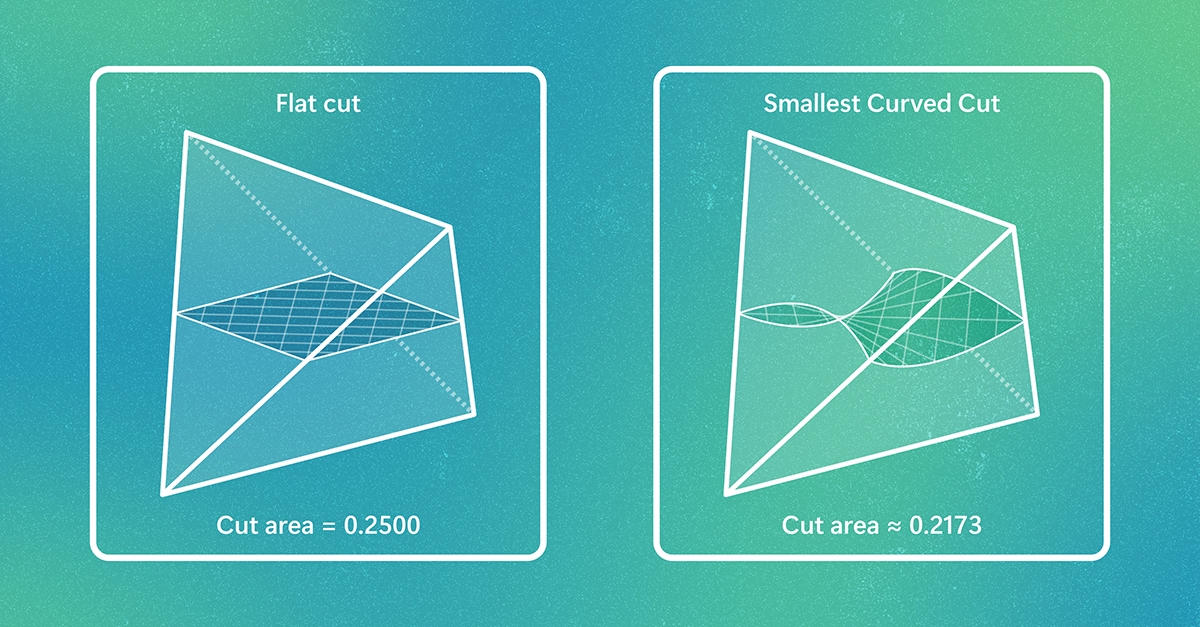
For decades, a fundamental question about the difficulty of computing in high-dimensional spaces has resisted proof. New research resolves this question, removing a major theoretical obstacle to understanding the efficiency of randomized algorithms used across science and computing. The Kannan–Lovász–Simonovits (KLS) conjecture was proposed in 1995. It asks whether, for a broad class of high-dimensional […] The post Solving a 31-year-old grand challenge in mathematics – the KLS conjecture appear…
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.