Skip to content
#federated learning Open access

Federated Medical Image Segmentation under Real-World Label Noise: A Benchmark Suite for Noisy Label Learning Method Selection

Aug 2026 · Journal of Imaging Informatics in Medicine · 57 references
Machine Learning and Data Classification

Abstract

Abstract While federated learning (FL) enables collaborative medical image segmentation without centralizing sensitive data, real-world deployment is frequently complicated by cross-site label imperfections such as contour disagreement, missing or additional structures, and confused labels. Federated noisy label learning (FNLL) aims to mitigate these effects, yet remains underused in practice as existing evidence is largely based on synthetic noise, simplified settings, and limited real-world noisy evaluation. We address this gap by introducing a benchmark suite that combines diverse real-world noisy datasets, deployment-relevant client-noise scenarios, and label-noise-targeted evaluation to support systematic FNLL assessment and informed method selection. The suite combines curated real-world noisy medical image segmentation datasets from diverse sources with a comprehensive federated segmentation framework including various client-noise scenarios and noise-targeted evaluation. To demonstrate its capabilities, we compare representative FNLL methods across approaches, including noise-aware aggregation, robust personalization, label correction, and sample selection. In-depth data analysis shows that real-world segmentation label noise occurs both in isolation and in combination of characterized noise types. The benchmark shows that FedSelect performs strongest within noise-targeted evaluation, underlines FedAvg as a competitive baseline, and provides a practically informed decision guide for FNLL method selection based on label-noise type, client-noise scenario, and technical-cost considerations. The presented suite provides a realistic and discriminative basis for FNLL evaluation in medical image segmentation and establishes a reusable foundation for fair benchmarking, dataset-specific label-noise characterization, and future method development under realistic federated settings. Code is available at https://github.com/MIC-DKFZ/FedSegNoiseBench .
View source

Similar papers

#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54
#machine learning Review Open access Jun 2014

Why Early-Stage Software Startups Fail: A Behavioral Framework

This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.

Carmine Giardino, Xiaofeng Wang, P. Abrahamsson · 175 citations · ⚡19
#machine learning Review Open access Oct 2016

“Failures” to be celebrated: an analysis of major pivots of software startups

This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.

Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al. · 127 citations · ⚡15
#machine learning Review Open access May 2016

Key Challenges in Software Startups Across Life Cycle Stages

It is found that what perceived as biggest challenges by software startups do vary across different life cycle stages, even though its significance decreases when the learning focuses of the startups move from problem to solution and their products mature.

Xiaofeng Wang, Henry Edison, Sohaib Shahid Bajwa et al. · 62 citations · ⚡6

Related blog posts

Microsoft Research Blog Sep 30, 2026

Forecasting space weather risks on power grids

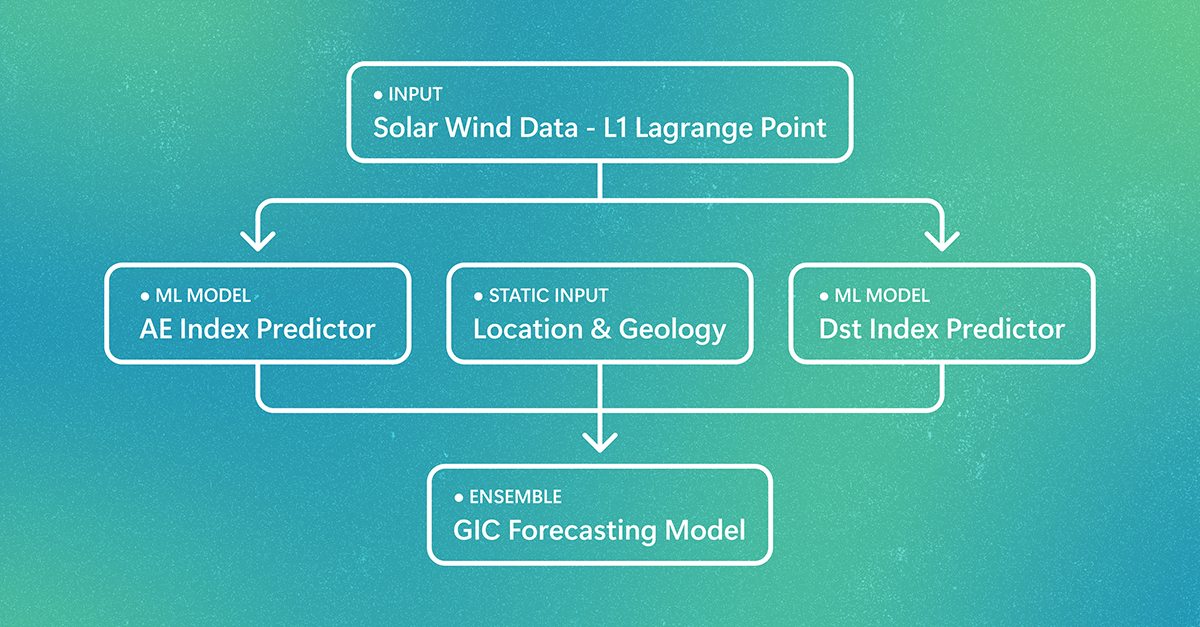
Extreme space-weather events can damage power systems on Earth and degrade GPS accuracy and satellite operations. A new machine learning system can predict where damage is likely to occur 30-60 minutes before a storm arrives. The post Forecasting space weather risks on power grids appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.