Mar 2026· arXiv.org· Vol abs/2603.12824· 1 citation· 45 references
Computer Science
TL;DR
NanoVDR exploits query--document asymmetry by decoupling the two encoding paths: a frozen 2B VLM teacher indexes documents offline, while a distilled text-only student as small as 69M parameters encodes queries at inference, and the resulting NanoVDR-S-Multi (DistilBERT, 69M) retains 95.1% of teacher quality.
Abstract
Vision-Language Model (VLM) based retrievers have advanced visual document retrieval (VDR) to impressive quality. They require the same multi-billion parameter encoder for both document indexing and query encoding, incurring high latency and GPU dependence even for plain-text queries. We observe that this design is unnecessarily symmetric: documents are visually complex and demand strong visual understanding, whereas queries are just short text strings. NanoVDR exploits this query--document asymmetry by decoupling the two encoding paths: a frozen 2B VLM teacher indexes documents offline, while a distilled text-only student as small as 69M parameters encodes queries at inference. The key design choice is the distillation objective. Through systematic comparison of six objectives across three backbones and 22 ViDoRe benchmark datasets, we find that pointwise cosine alignment on query text consistently outperforms ranking-based and contrastive alternatives, while requiring only pre-cached teacher query embeddings and no document processing during training. Furthermore, we identify cross-lingual transfer as the primary performance bottleneck, and resolve it cheaply by augmenting training data with machine-translated queries. The resulting NanoVDR-S-Multi (DistilBERT, 69M) retains 95.1\% of teacher quality and outperforms DSE-Qwen2 (2B) on v2 and v3 with 32$\times$ fewer parameters and 50$\times$ lower CPU query latency, at a total training cost under 13 GPU-hours.
ColNanoVDR is presented, to the authors' knowledge the first framework to bring this document-free distillation to multi-vector VDR, and it is proved that the resulting alignment cost bounds the MaxSim score difference on every page.
Zhu Liu, Zi-Yi Wang, Yao Zhang et al.· arXiv.org· 1 citation
This work introduces EVIE (Evidence-Vector-Informed Embeddings), a family of native visual document retrievers integrating three key innovations: evidence-judged data governance, which uses a multimodal judge to identify answer-bearing positives and filter unreliable negatives, and Hierarchical agglomerative index comp...
RenderRank is introduced, a reranker that learns query-dependent relevance scoring from compressed visual document representations instead of the text token sequences used by conventional text-based rerankers.
Seongtae Hong, Youngjoon Jang, Jungseob Lee et al.· 0 citations
ViSAR (Visual Semantic Activation Retrieval), a training-free adaptive-$k$ retrieval method for late-interaction visual document retrieval, is introduced and it is shown that the similarity matrix structure correlates with answer accuracy, suggesting future directions for retrieval quality-aware document understanding.
Adrien Mialland, Marc Plantevit, Julien Gallois et al.· 2 citations
SEER is presented, a framework that learns to select query-relevant images through visual scanning and retrieve textual content only where needed, combining the efficiency of visual compression with the precision of text-based reasoning.
Jiawei Xu, Zhilin Zhai, Jinrui Fang et al.· 3 citations
This work proposes DocPC, a document-level visual retrieval framework based on Representative Page Composition, and introduces DocViRe, a benchmark with multi-positive relevance annotations that combines multi-positive contrastive learning with sparsely scheduled listwise optimization.
Chengcheng You, Qi Jiang, Junyi Zhou et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
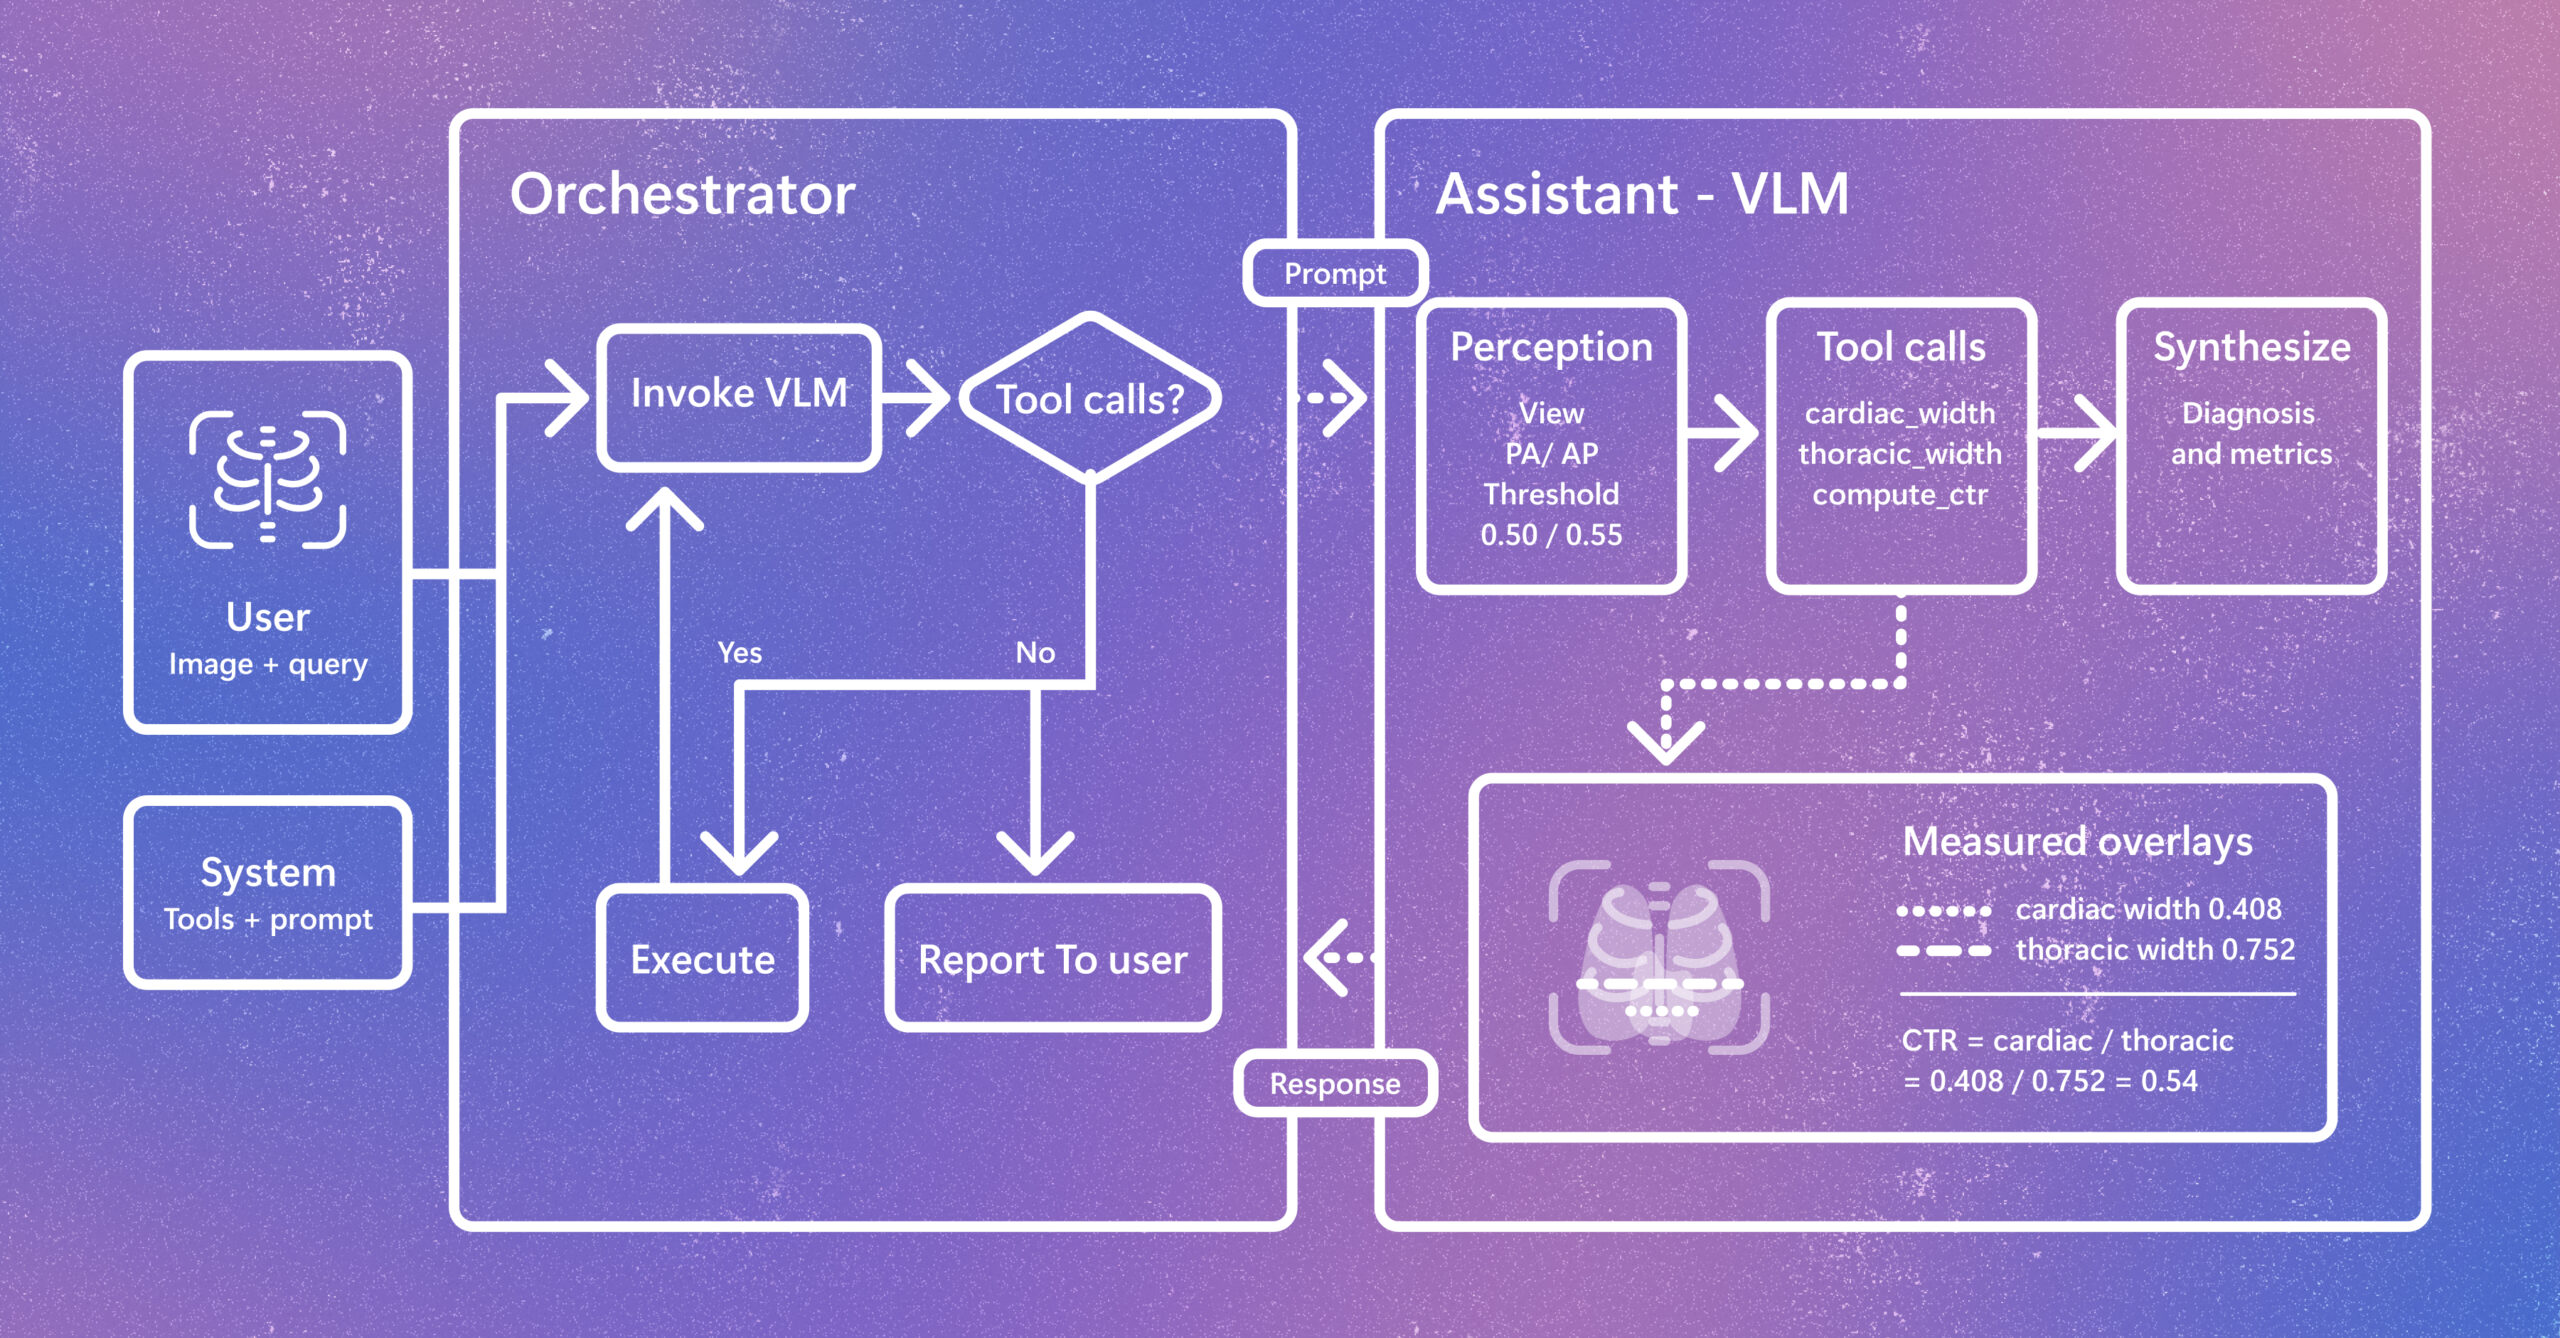
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.