VisER is proposed, a training-free two-sided metric for object-level hallucination detection that improves AUROC and AUPR over a range of baselines and measures whether object-context compatibility is backed by object-specific evidence from image tokens.
Abstract
Object hallucination remains a persistent reliability issue in large vision-language models, where generated object mentions may sound plausible but lack visual grounding. Recent training-free detectors use internal signals such as token likelihood, attention, visual confidence, or image-text similarity to identify hallucinated objects. These signals are useful, but they are often source-confounded. They measure how strongly an object is supported inside the model without distinguishing whether that support comes from object-specific visual evidence or the generated text prefix. In difficult cases, a hallucinated object can still receive high internal support because it fits the scene, is associated with nearby visual cues, or follows naturally from the generated text prefix. We propose VisER, a training-free two-sided metric for object-level hallucination detection. VisER evaluates each generated object mention from two complementary views. Visual Evidence measures whether object-context compatibility is backed by object-specific evidence from image tokens. Visual Reliance measures whether the object is supported more by the image than by the generated prefix. Combining these views gives a more source-aware grounding score, while avoiding additional object-level verification generations. Across multiple LVLMs and benchmarks, VisER improves AUROC and AUPR over a range of baselines.

ReWEIGH is a training-free decoding intervention that aggregates vocabulary ranks across visual positions and compares each candidate with a token-specific reference estimated from unlabeled images and applies a bounded penalty only to candidates that fall below their reference.
Multiple object hallucination, where large vision-language models (LVLMs) generate objects not supported by the visual input, is a persistent challenge caused by visual uncertainty during decoding. Existing methods reduce hallucinations using contrastive signals, but they rely on heuristics and lack principled control...
CADMP is proposed, a lightweight object hallucination detection framework that combines adjacent-layer cross-modal attention drift with prediction sensitivity to targeted visual masking, and achieves consistently competitive detection performance.
Attribute hallucination---where vision-language models (VLMs) correctly identify an object but mischaracterize its properties---is prevalent yet mechanistically poorly understood. The dominant explanation, language-prior dominance, has motivated prior-suppression methods, but this explanation has not been directly test...
A diagnosis-to-intervention pipeline for object hallucination is presented, and a controlled account of what acting on the diagnostic signal actually does is presented: it localizes intervention sites with real, non-random leverage, reported as a behavioral profile rather than a single score.
TruthLens is a self-evaluation framework that teaches the LM head to expose a per-object truthfulness signal without any auxiliary model or additional inference cost, and generalizes effectively to benchmarks with substantially larger label spaces.
Yan-Qi Wu, Run-He Lai, Xin-Hua Lu et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
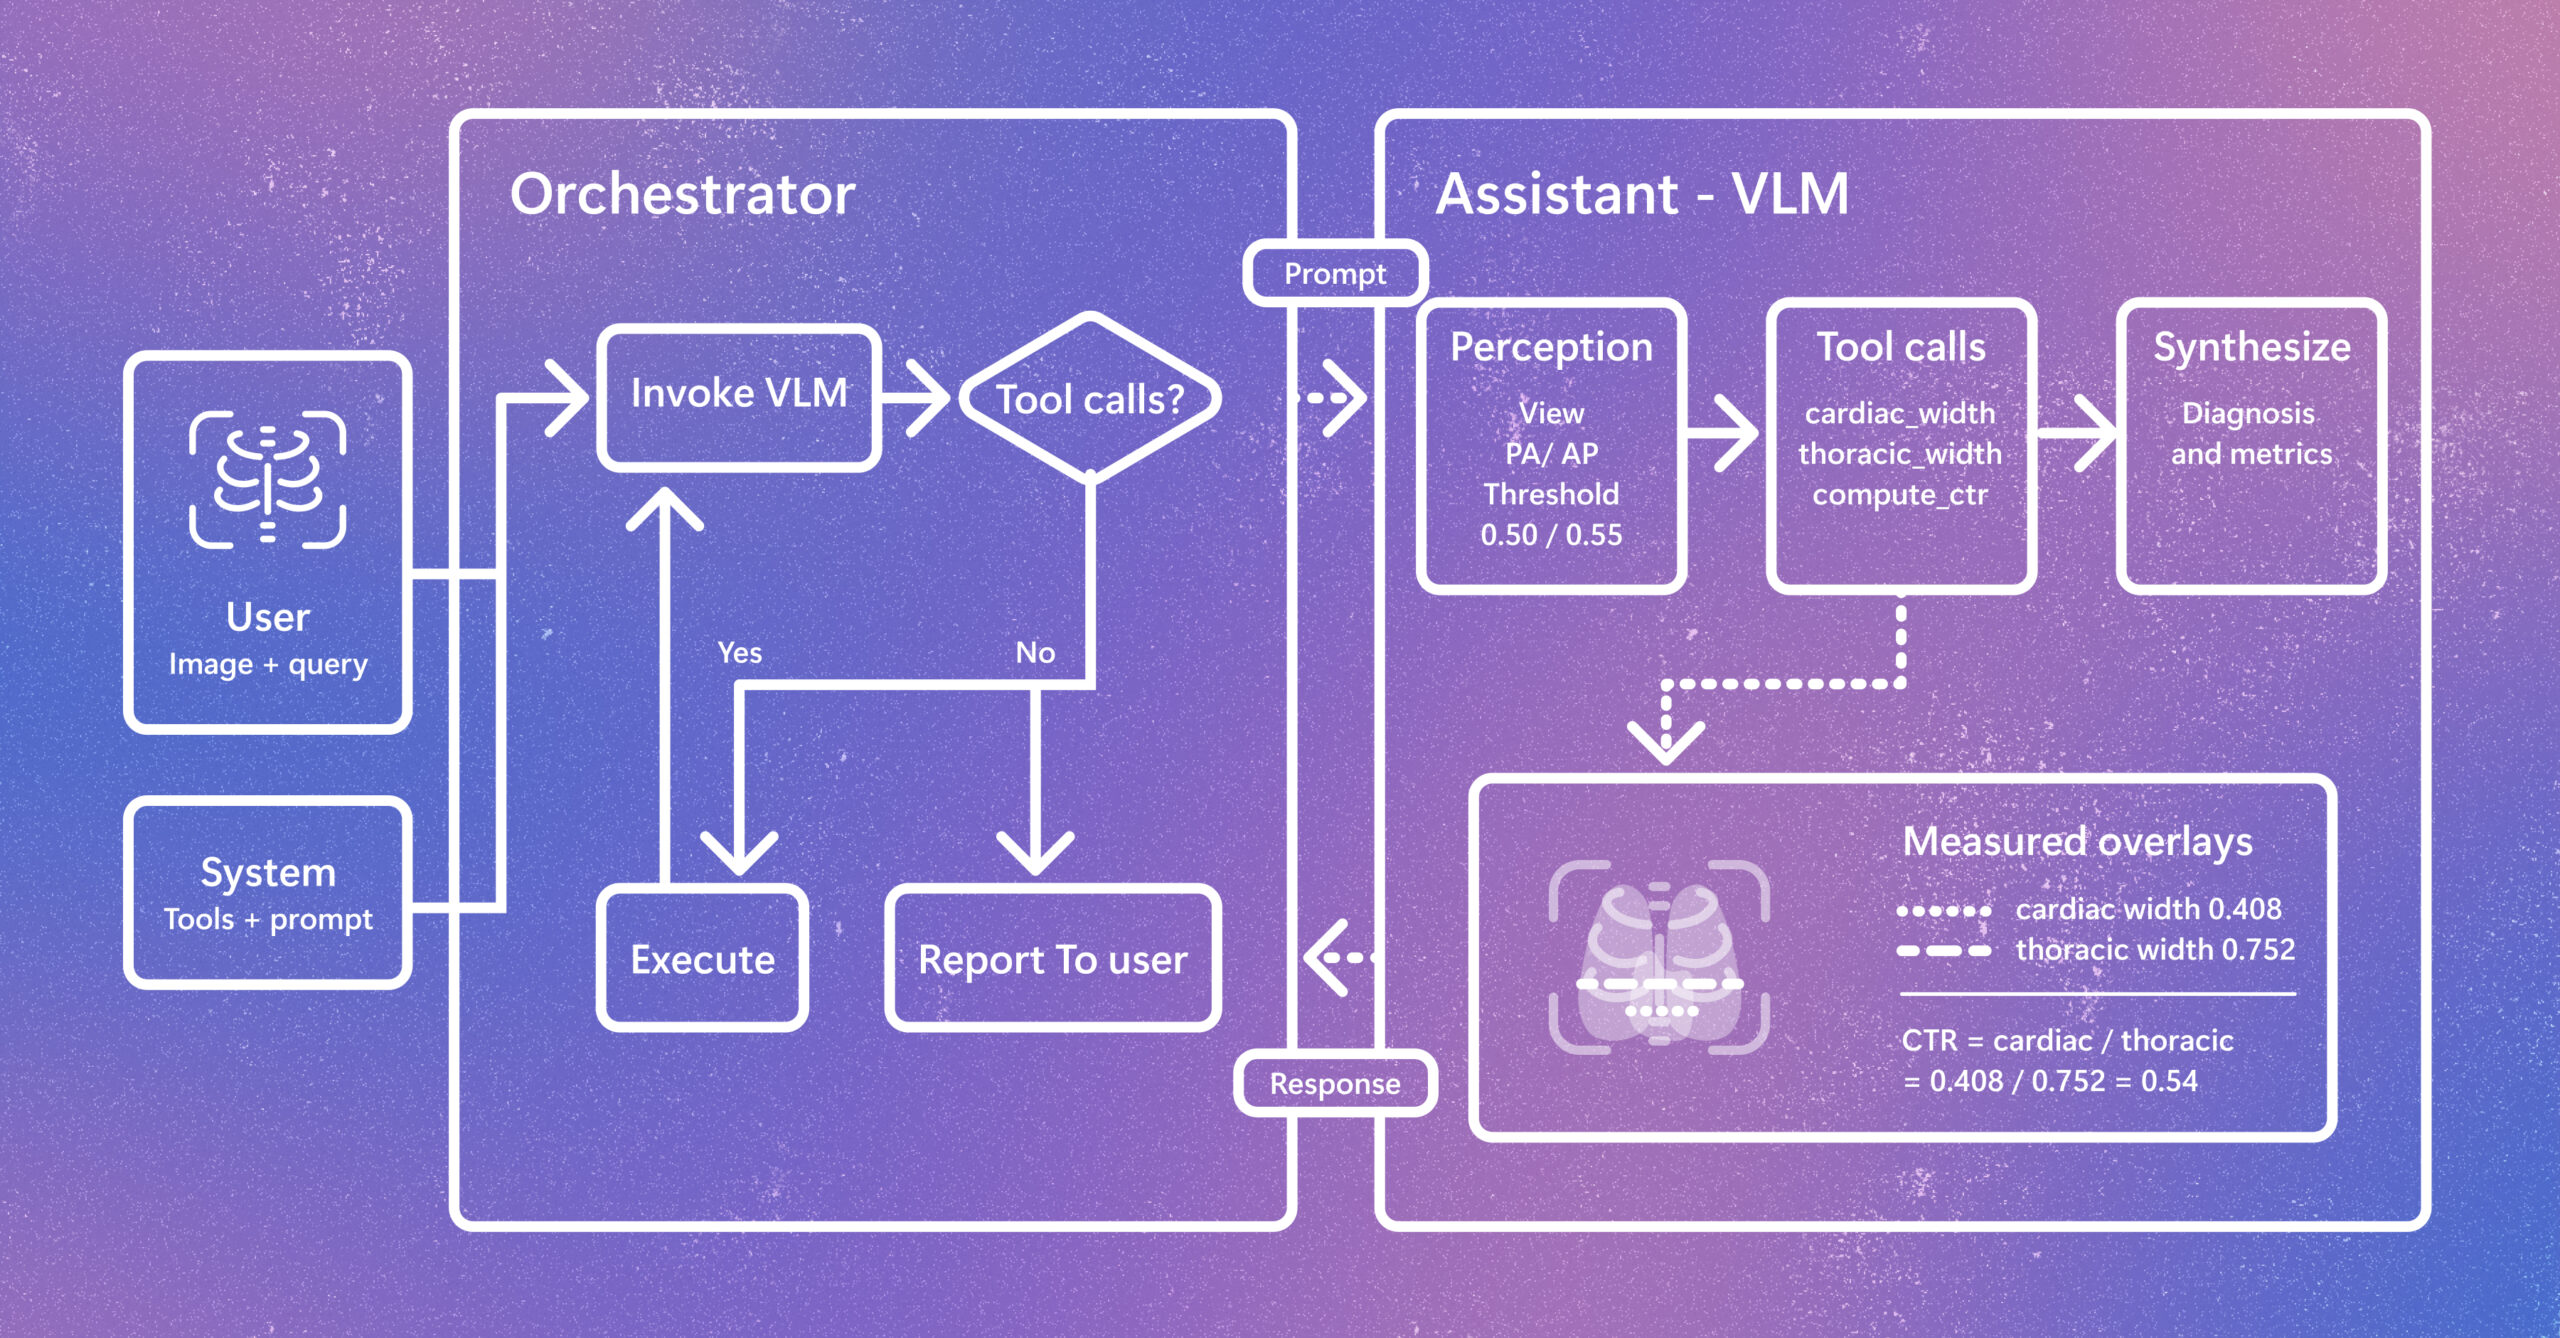
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.