Skip to content

An Integrated Vision-and-Language Pretraining (VLP) and Visual Question Answering (VQA) model to Automate Nondestructive Evaluation Image Analysis

Aug 2026 · 0 citations · 22 references
Computer Science

Abstract

An AI-based approach called ChatNDE Figure to Caption is introduced, which aims to automate the interpretation of NDE images using deep learning and natural language processing (NLP). A Vision-and-Language Pretraining (VLP) strategy is developed to help the model learn how to connect visual features with meaningful language. Basically, we built a large NDE image dataset, trained the model using annotated examples, and then evaluated how well it performed using BLEU scores to compare its output to expert written descriptions. So, the system combines a ResNet50 model to extract important features from the images and a GPT2 language model to turn those features into natural sounding text. Even though the accuracy of the model has been low the generated caption results have been solid so far, the captions were shorter but mentioned some important features of images what human experts would say, which shows the model is learning to pick up on key details. Also, a Visual Question Answering (VQA) model is used as part of the system. VQA models are designed to take an image and a question about that image (like Is there a crack? or Where is the defect located?) and generate a useful answer. By adding this layer, the platform will not just describe what it sees, it can also respond to specific questions, making it even more interactive and helpful for inspectors in the field. This whole approach is a big step toward speeding up NDE workflows, reducing human error, and making the technology more accessible.


View source

Similar papers

Preprint Aug 2026

UC-VLM: Consistency-Driven Learning for AI-Generated Image Detection with Vision-Language Large Models

UC-VLM is a unified multi-stage binary-supervised framework that consistently reuses the same authenticity labels for visual adaptation and label-conditioned text generation, while leveraging automatically optimized instructions to reduce prompt sensitivity without requiring human-written rationales or hand-crafted pro...

Lei Tan, Shuwei Li, Mohan S. Kankanhalli et al. · 0 citations
Sep 2026

Making Large Vision–Language Models Better Few-Shot Learners

Few-shot classification (FSC) aims to emulate the human ability to rapidly learn new concepts from a handful of examples. Large Vision-Language Models (LVLMs), with their rich prior knowledge and powerful visio-linguistic understanding capabilities, are emerging as a highly promising paradigm for FSC. This paper invest...

Chuan-Yi Zhang, Fan Liu, Yi Xu et al. · 0 citations

Related blog posts

MIT News · Artificial Intelligence Oct 28, 2026

Making machines that can listen

Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.

Microsoft Research Blog Aug 11, 2026

Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

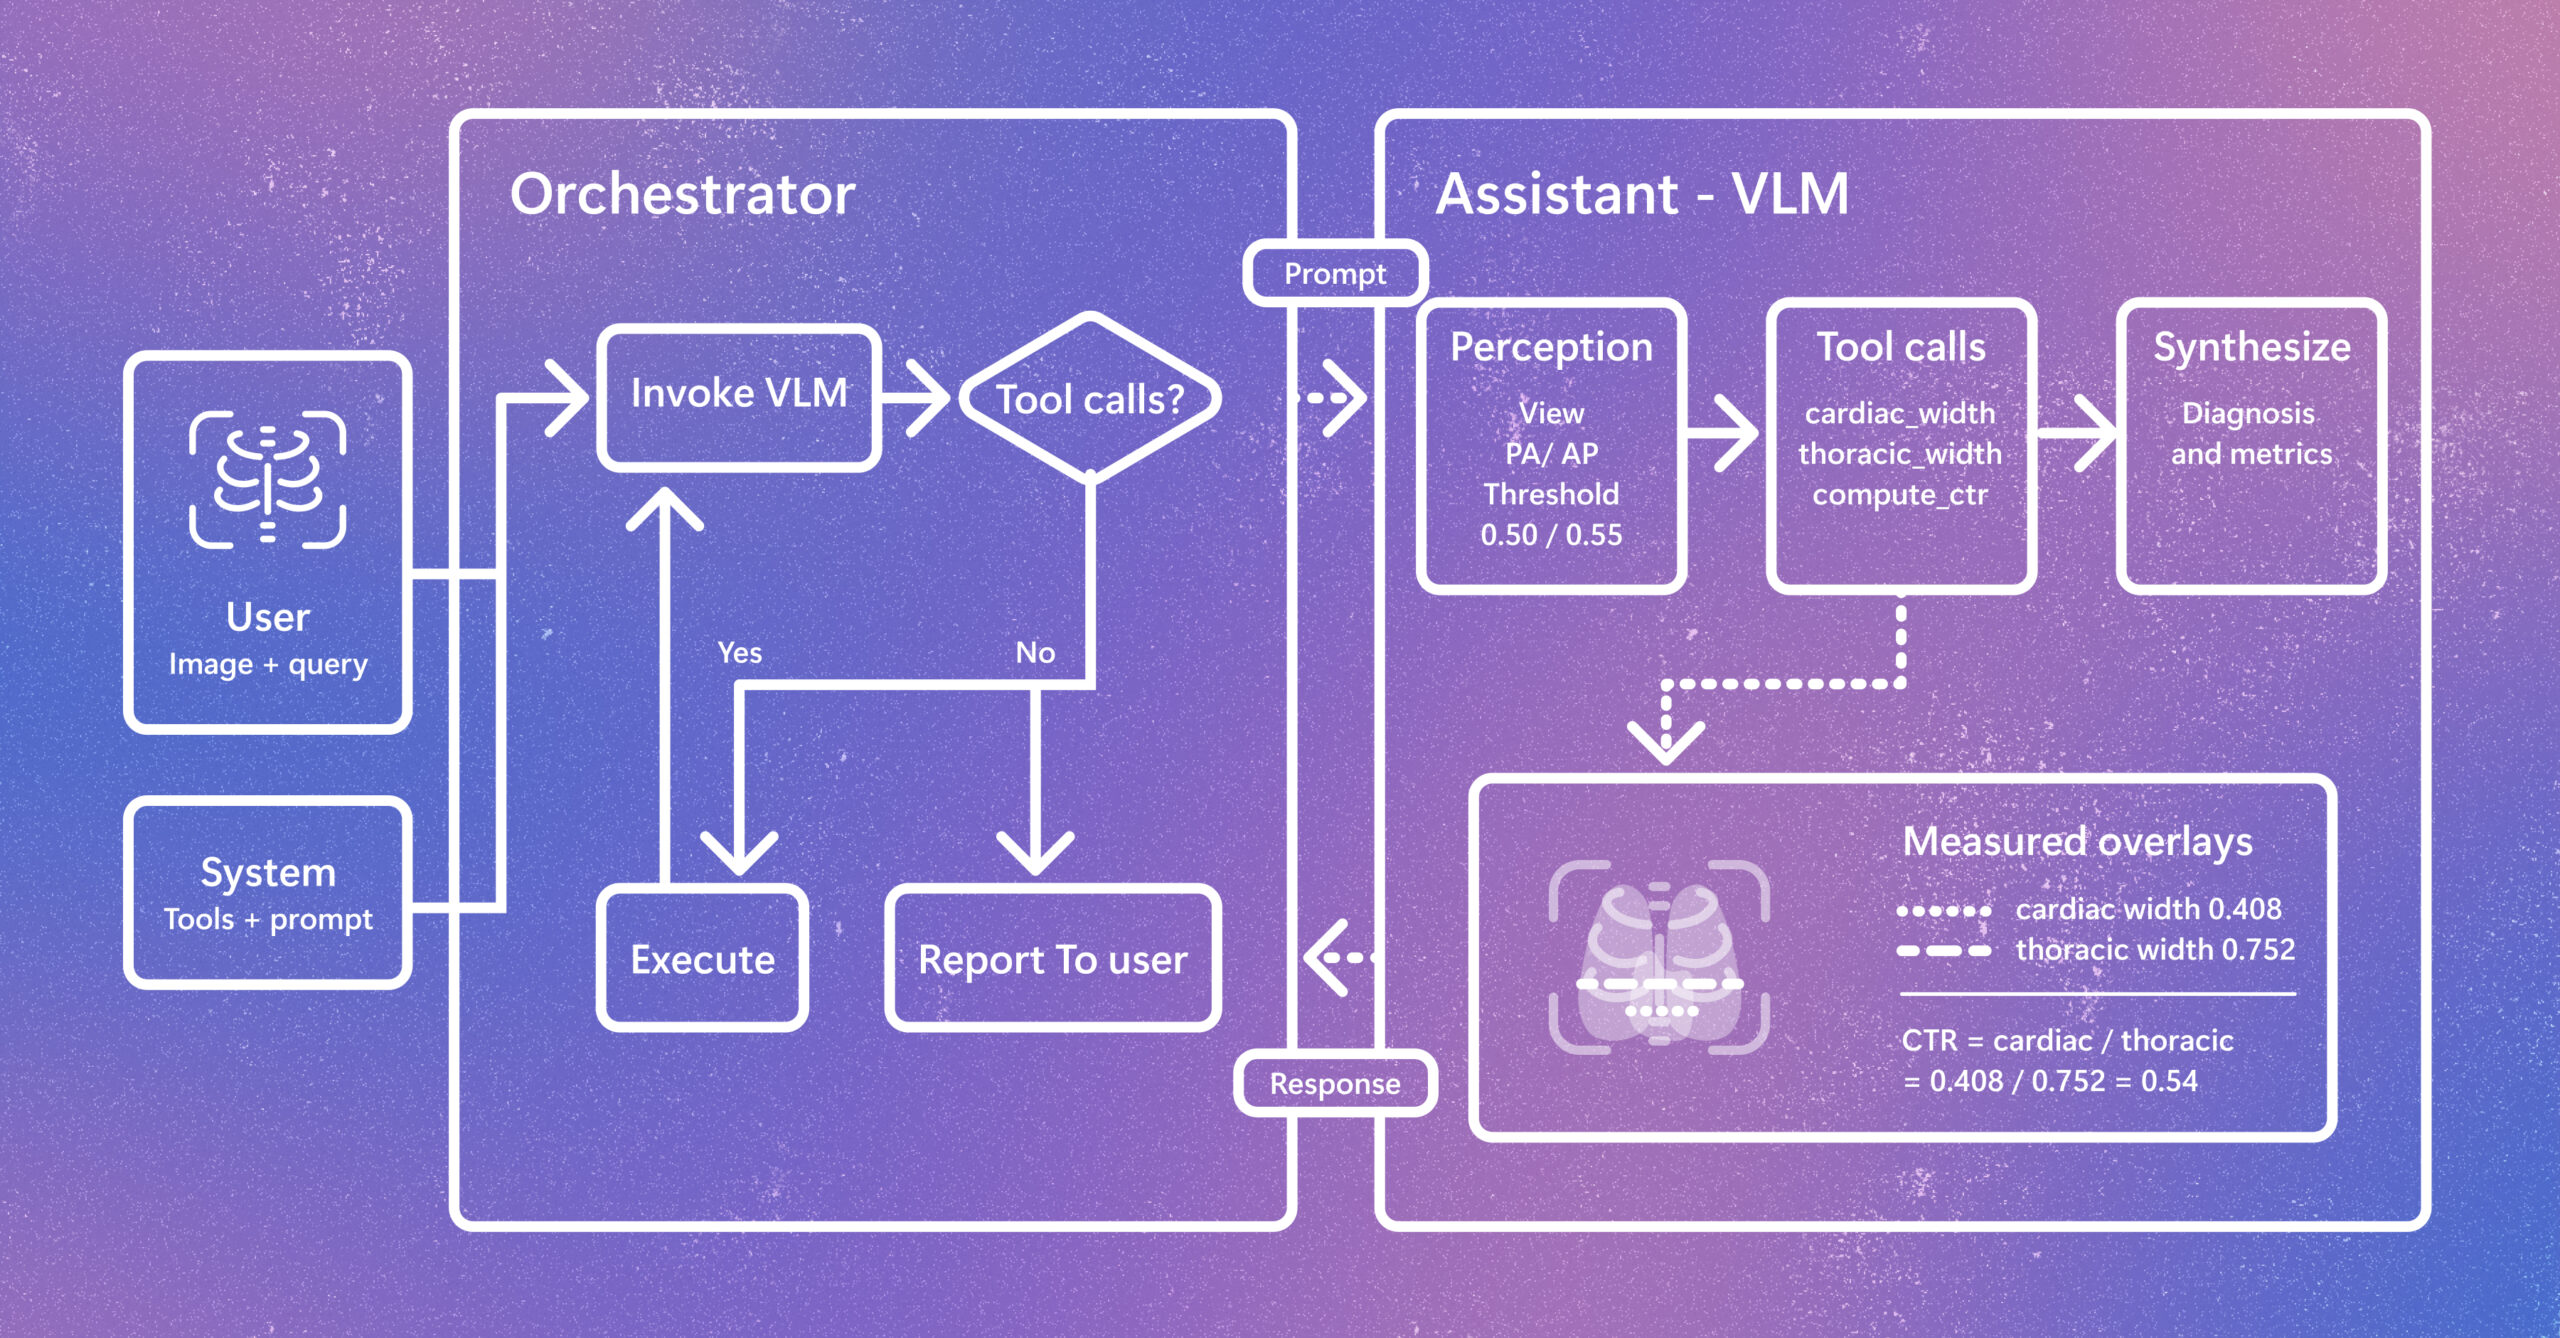
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.