The effectiveness of the proposed source codecs are demonstrated by achieving state-of-the-art performance in distributed semantic segmentation at below 0.2 bits per pixel, measured using the mean intersection-over-union metric on ADE20K (Cityscapes).
Abstract
Distributed deep neural networks (DNNs) for dense perception tasks such as semantic segmentation execute an encoder DNN on edge devices, and a decoder DNN typically on a large-scale cloud platform with a particular constraint on transmission bitrate. Recent works employ source codecs to enable bitrate-efficient transmission between the edge device and the cloud. However, as these approaches are typically bound to a particular type of source codec and alternative network architectures are often not explored, this results in a suboptimal rate-distortion (RD) trade-off in the low-bitrate regime. In this work, we propose two novel source codecs that \textit{enable extremely low bitrates, while improving RD performance}. We demonstrate the effectiveness of our proposed source codecs by achieving state-of-the-art performance in distributed semantic segmentation at below 0.2 (0.03) bits per pixel, measured using the mean intersection-over-union metric on ADE20K (Cityscapes).

This paper proposes BinRVR, a binarized RAW video restoration framework that reduces computation and parameters by approximately 96% while incurring only about 4% performance degradation, and develops a Distribution-Aware Binarized Convolution (DAB-Conv) that leverages the statistics of full-precision activations to mi...
Tianyu Zhu, Ying Fu, He-Song Li et al.· IEEE Transactions on Pattern...· 0 citations
This work systematically study MoE designs for vision encoder scaling and finds that fine-grained MoE topologies yield substantial gains over both dense and standard MoE counterparts, and proposes an auxiliary-loss-free balancing variant for better expert utilization, and designs a specialized MoE kernel to mitigate in...
Bonan Zhang, Shiyu Dong, Quan Hung Tran et al.· 1 citation
OASIS, a distributed in-sensor vision framework that uses a lightweight encoder to generate compact, task-relevant representations before off-chip transmission, is presented, demonstrating a practical hardware-algorithm co-design path for communication-efficient in-sensor vision.
Cheng-Wei Zhou, Abu Masum, Xu-Ming Chen et al.· 0 citations
The Channel-wise Token-balanced Output-Aware Clipping (CTOAC) method, which learns per-input-channel clipping bounds by minimizing a token-balanced reconstruction loss on the corresponding linear outputs, is proposed.
It is found that for FFN and lm_head the time cost of quantization/dequantization is compensated for by the use of integer arithmetic, while for short context lengths, the opposite holds true for Attention: an additional step of quantization slows execution down.
A. Safronov· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
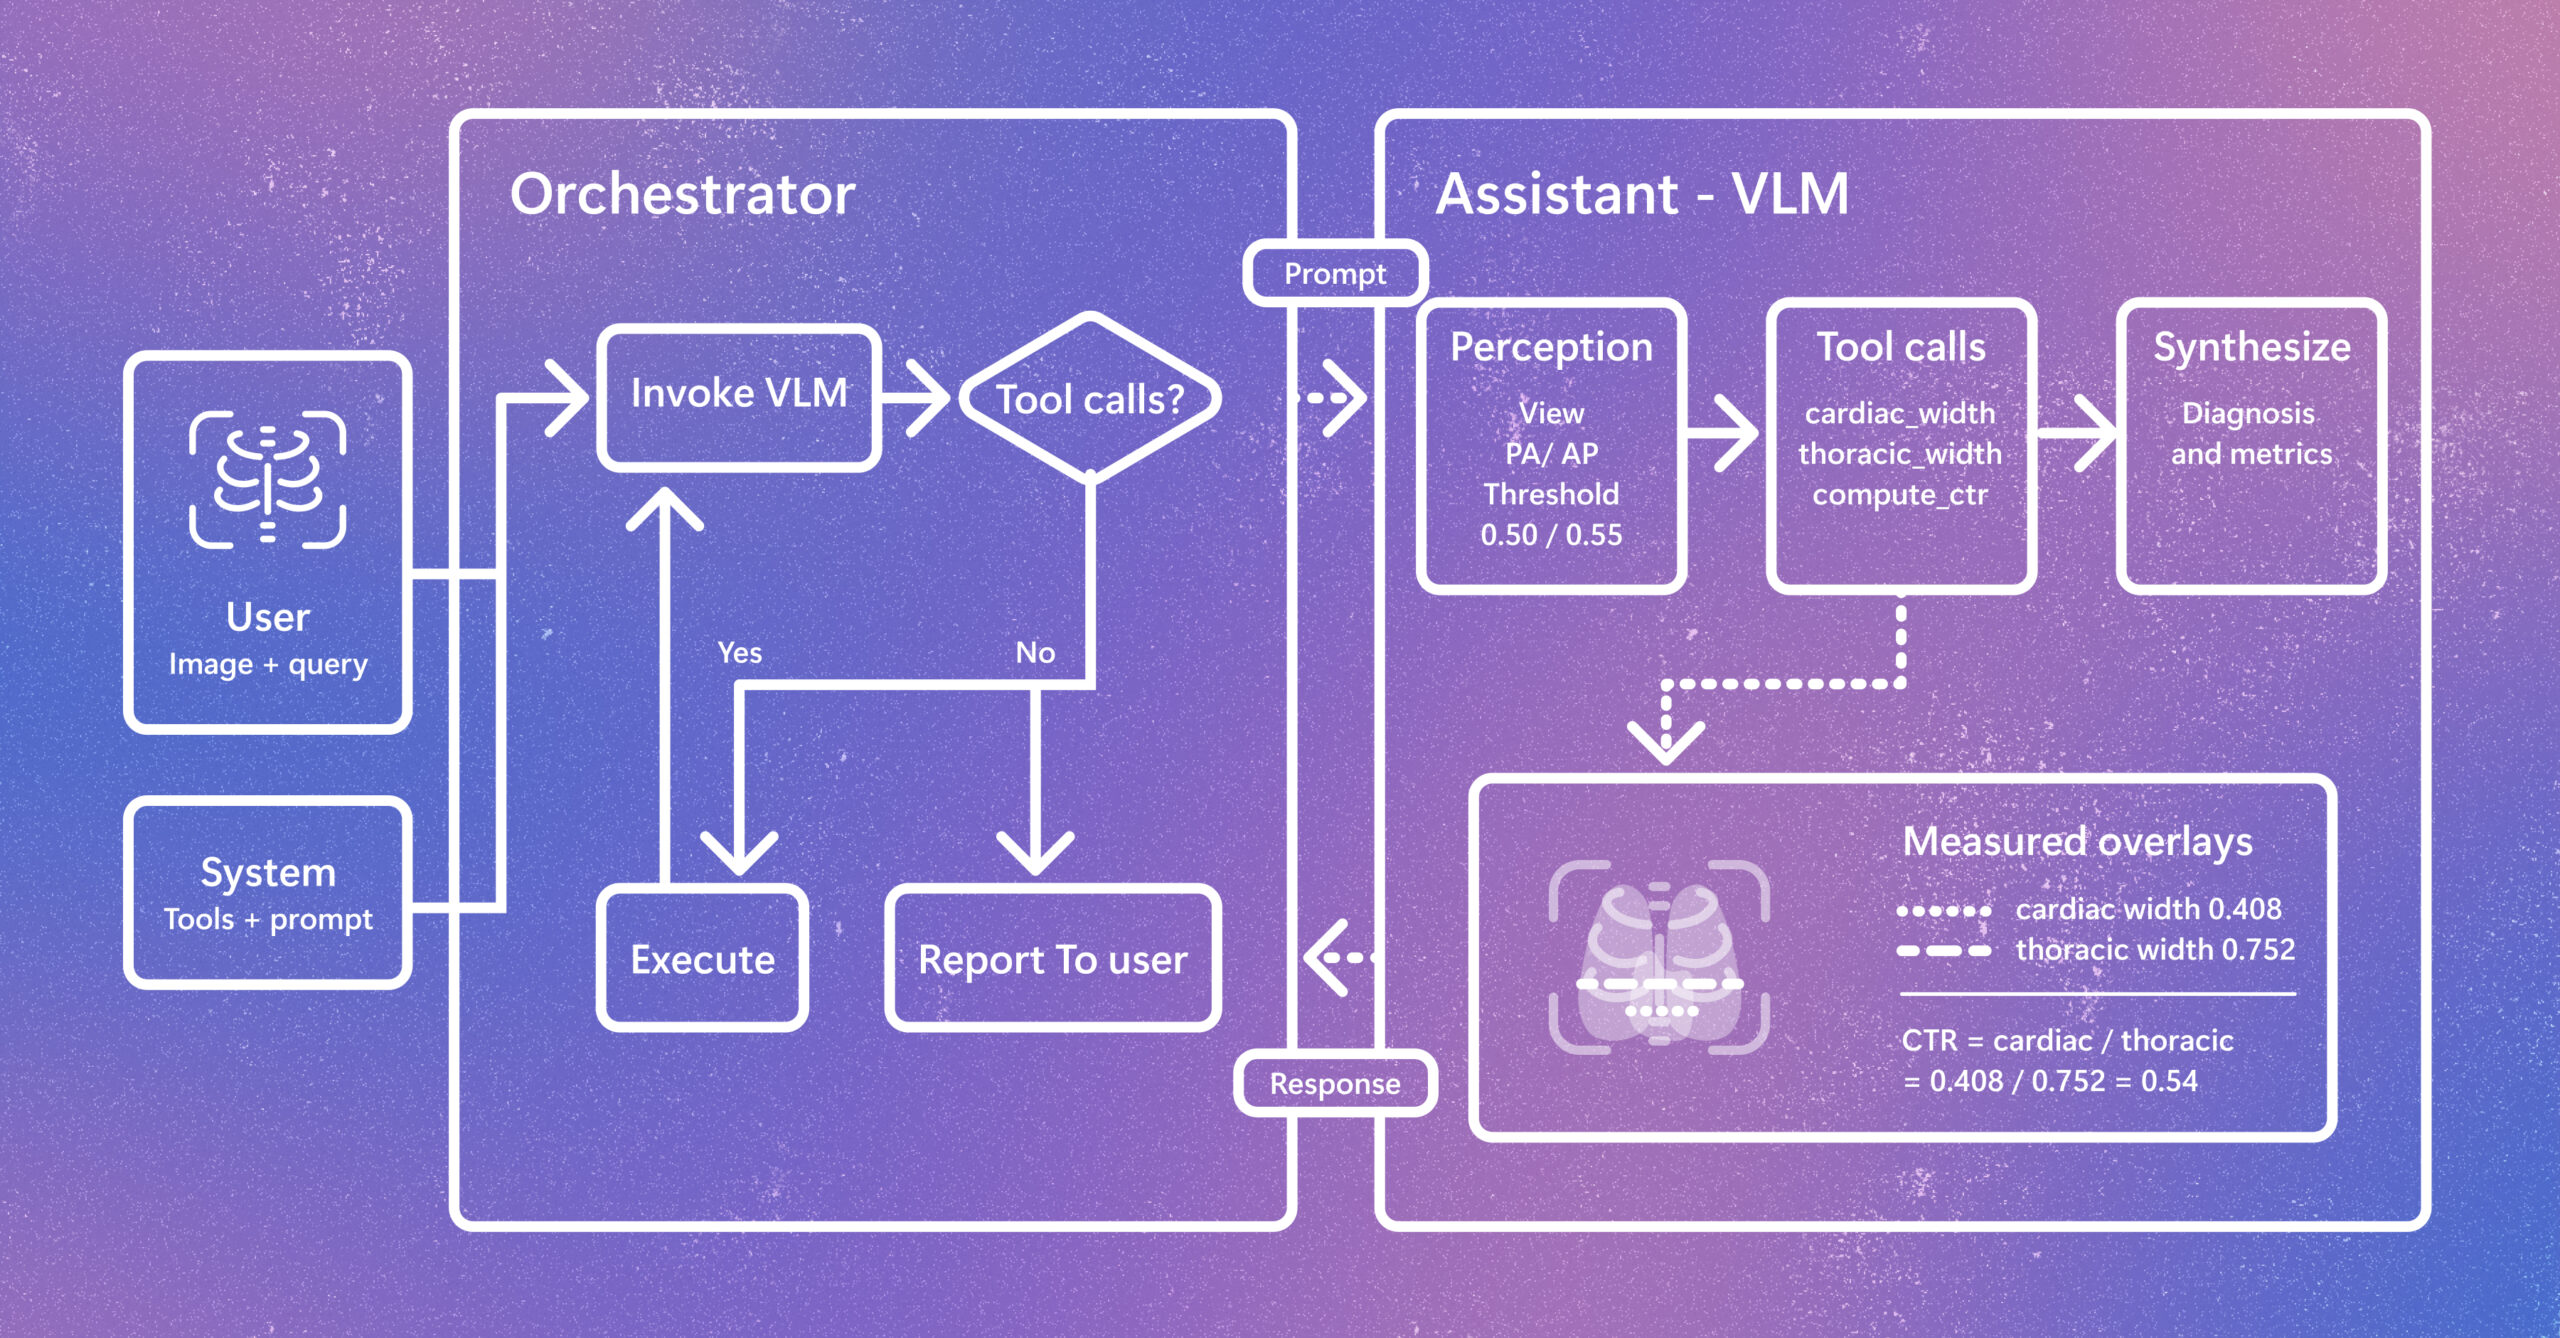
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.