Audio-visual dataset distillation aims to synthesize a small dataset from a large paired audio-visual dataset, while nearly preserving the training utility for neural networks. Existing approaches such as DM and AVDD face two critical limitations: 1) they are memory-intensive, making them difficult to scale to complex architectures and higher samples-per-class (SPC) settings, and 2) they often fail to preserve strong cross-modal semantic correspondence. To tackle these issues, we propose X-AVDD, a cross-attention-based distillation method that explicitly captures inter-modal relationships during synthesis. By decoupling cross-modal alignment from joint optimization, X-AVDD is substantially more memory-efficient, reducing end-to-end synthesis cost by $\sim 8\times$ GPU-hours, while producing highly aligned synthetic data. Empirically, X-AVDD significantly outperforms other audio-visual distillation methods. On VGGSound, an audio-visual dataset of short YouTube clips, X-AVDD improves top-1 test accuracy from $8.2\%\rightarrow24.0\%$ at SPC=$10$ and $9.8\%\rightarrow26.5\%$ at SPC=$20$. Furthermore, X-AVDD improves cross-architecture generalization (e.g., $25.5\%\rightarrow35.3\%$ for a ViT target on AVE dataset at SPC $=50$) and successfully scales to complex architectures such as AudioCLIP, achieving $62.3\%$ accuracy using only $5.65\%$ of the full dataset, against the full dataset accuracy of $72.4\%$ while completing in $9\times$ lower training time compared to the full dataset.
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
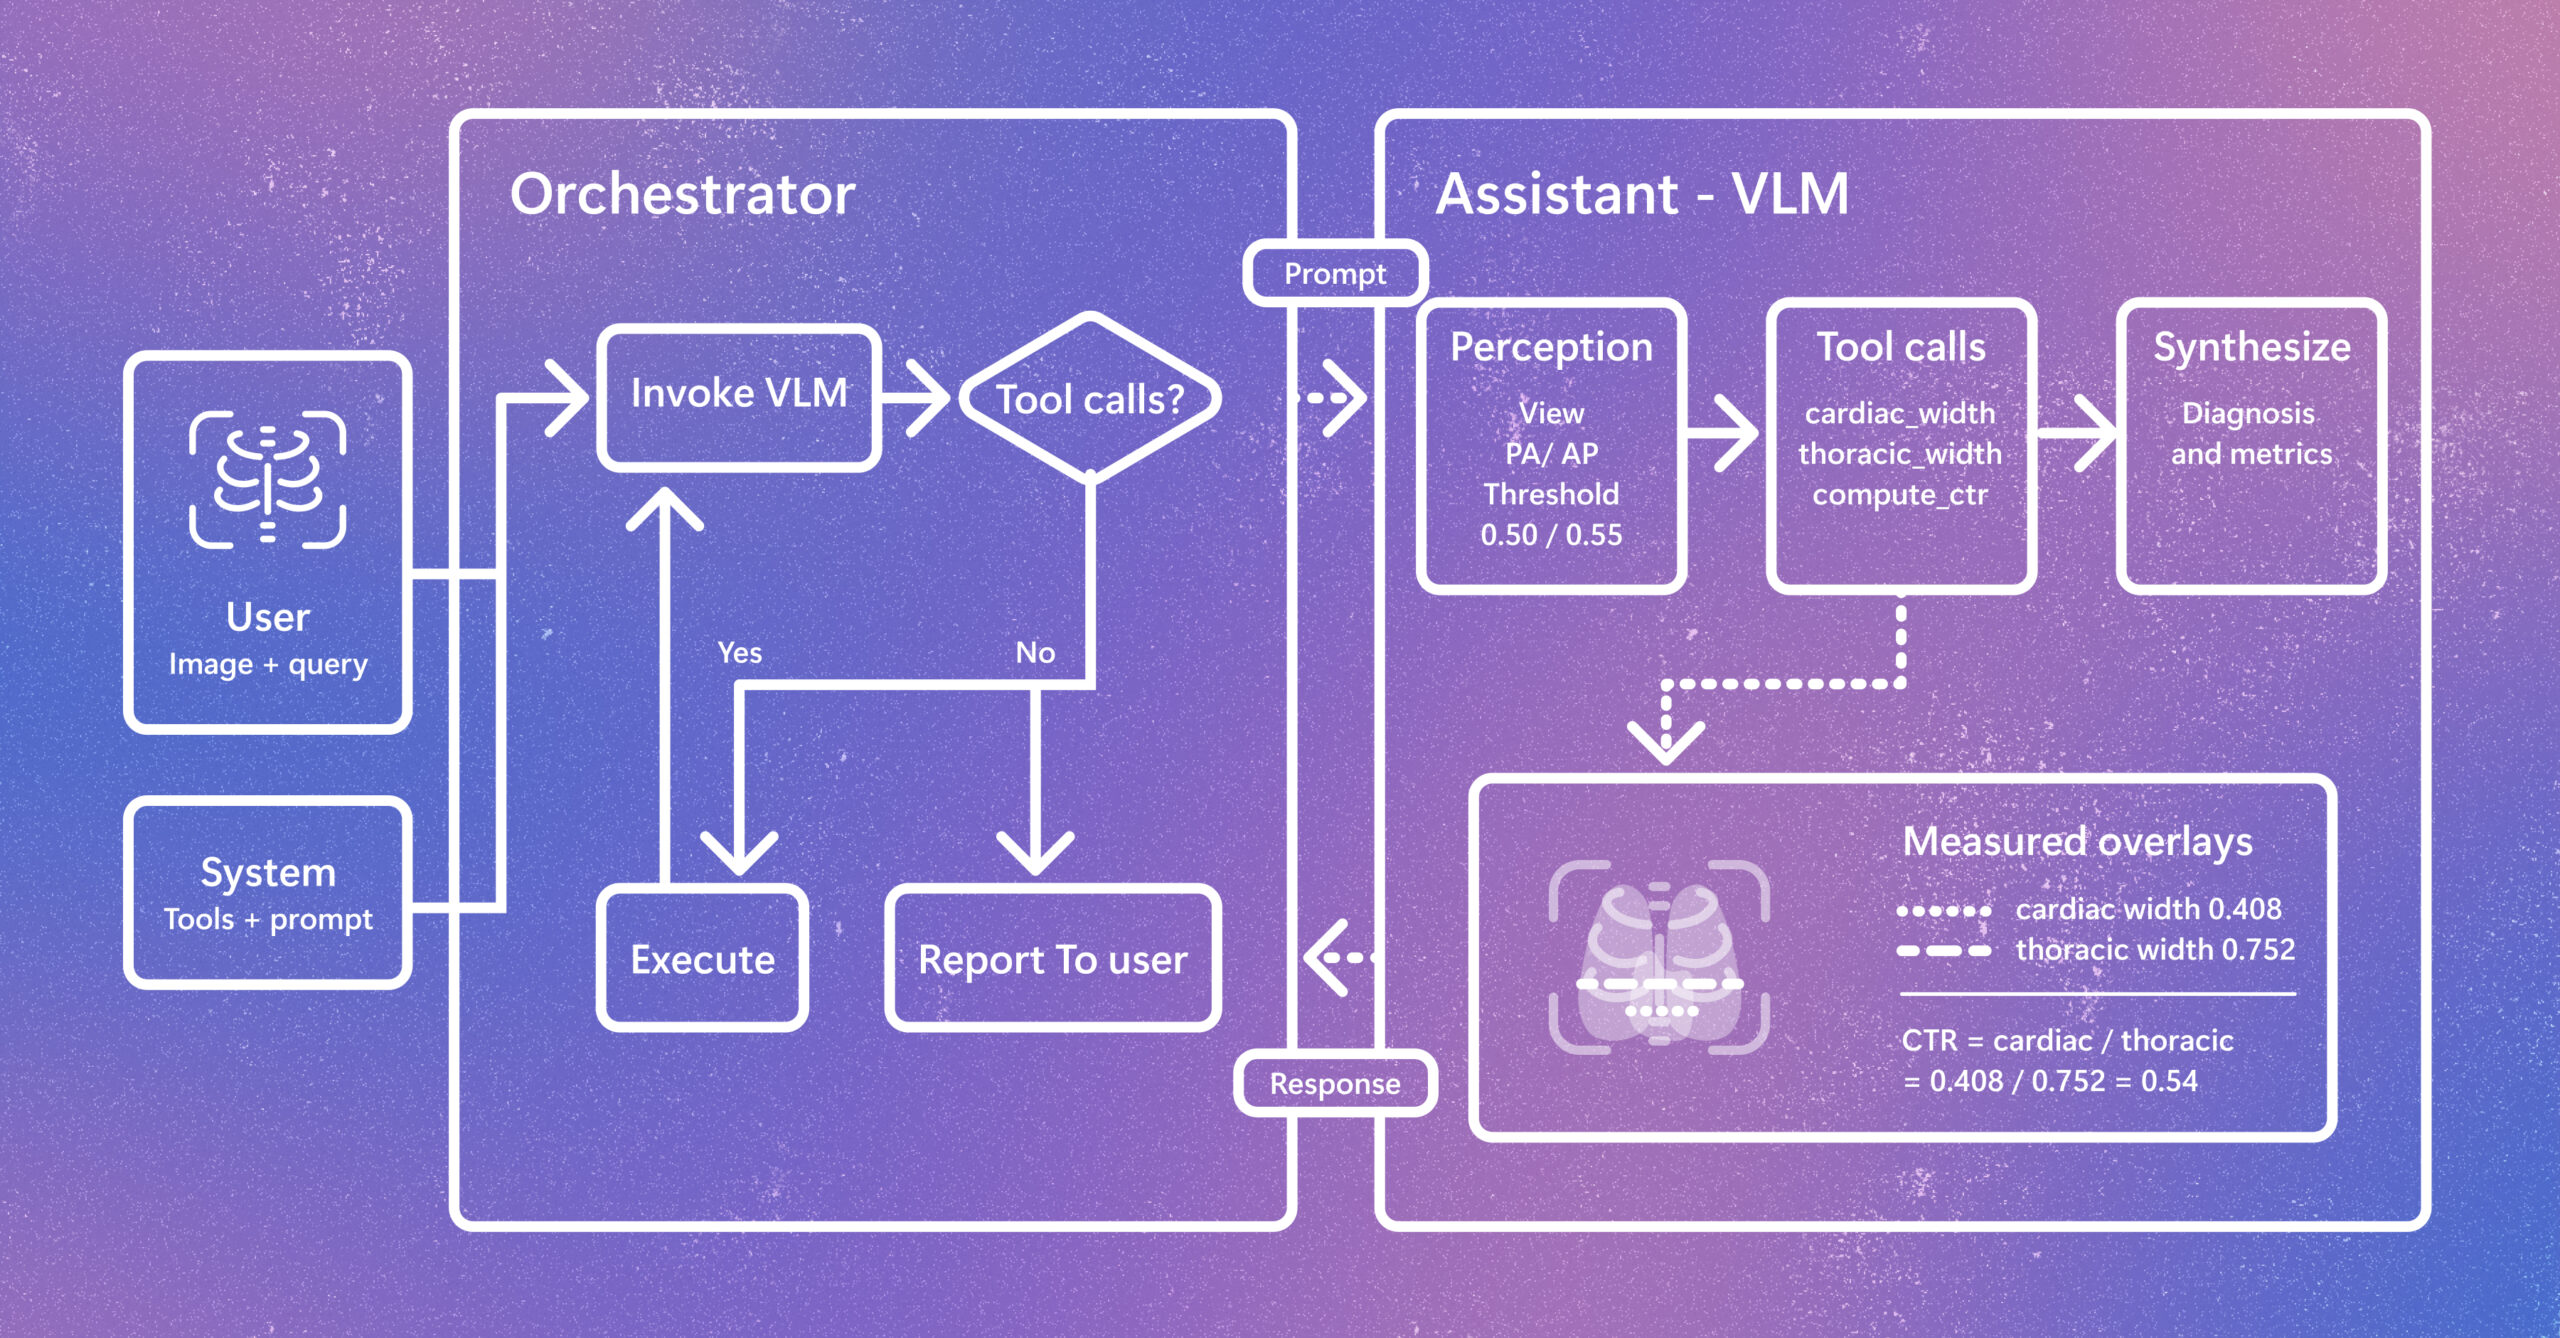
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.