Skip to content
#machine learning #computer vision Preprint Open access

Omni-Diffusion-Distill: Few-Step Distillation of Unified Multimodal Diffusion Large Language Models

Hong Huang Chenhongyi Yang Junzhe Sun Animesh Sinha Wuyang Chen Yifan Jiang
Oct 2026
Machine Learning Computer Vision

Abstract

Unified multimodal diffusion large language models (dLLMs) offer a single architecture for both image generation and multimodal understanding, but their iterative decoding requires tens to hundreds of forward passes. Existing few-step distillation methods largely focus on either image generation or text generation, making it unclear how to compress a fully discrete multimodal dLLM into a single efficient student while preserving both generation and understanding. We introduce Omni-Diffusion-Distill, a unified two-stage distillation framework that retains strong generation and understanding capabilities while substantially reducing the inference cost of a unified multimodal dLLM. Omni-Diffusion-Distill aligns the distillation of both generation and understanding, for both images and text, in the discrete token space. In the first stage, the student is trained to skip decoding steps by replaying cached teacher trajectories, and in the second stage the student is refined on intermediate states along its own rollouts. We further remedy two sources of degradation in unified distillation with a pairwise collision penalty that reduces repetition under parallel text decoding, and entropy-matched guidance that prevents entropy collapse caused by fitting the sharpened teacher distribution in image generation. Omni-Diffusion-Distill achieves state-of-the-art trade-offs between decoding efficiency and generation and understanding performance for multimodal dLLMs, reducing image generation from 128 to 8 decoding steps and multimodal understanding from 512 to 64, giving 18.2x and 21.2x wall-clock speedups. Under these budgets, it scores 0.828 on GenEval and 83.0 on DPG-Bench for text-to-image generation, while reaching GPT judge scores of 20.0 on MM-Vet and 57.2 on COCO captioning (twice the teacher's 28.4 at the same steps) for multimodal understanding.

View source

Similar papers

#computer vision Review Sep 2017

Agile Software Development Methods: Review and Analysis

This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.

P. Abrahamsson, O. Salo, Jussi Ronkainen et al. · 727 citations · ⚡54
#computer vision Jun 2008

The impact of agile practices on communication in software development

The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.

M. Pikkarainen, Jukka Haikara, O. Salo et al. · 401 citations · ⚡48
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Related blog posts

Microsoft Research Blog Aug 11, 2026

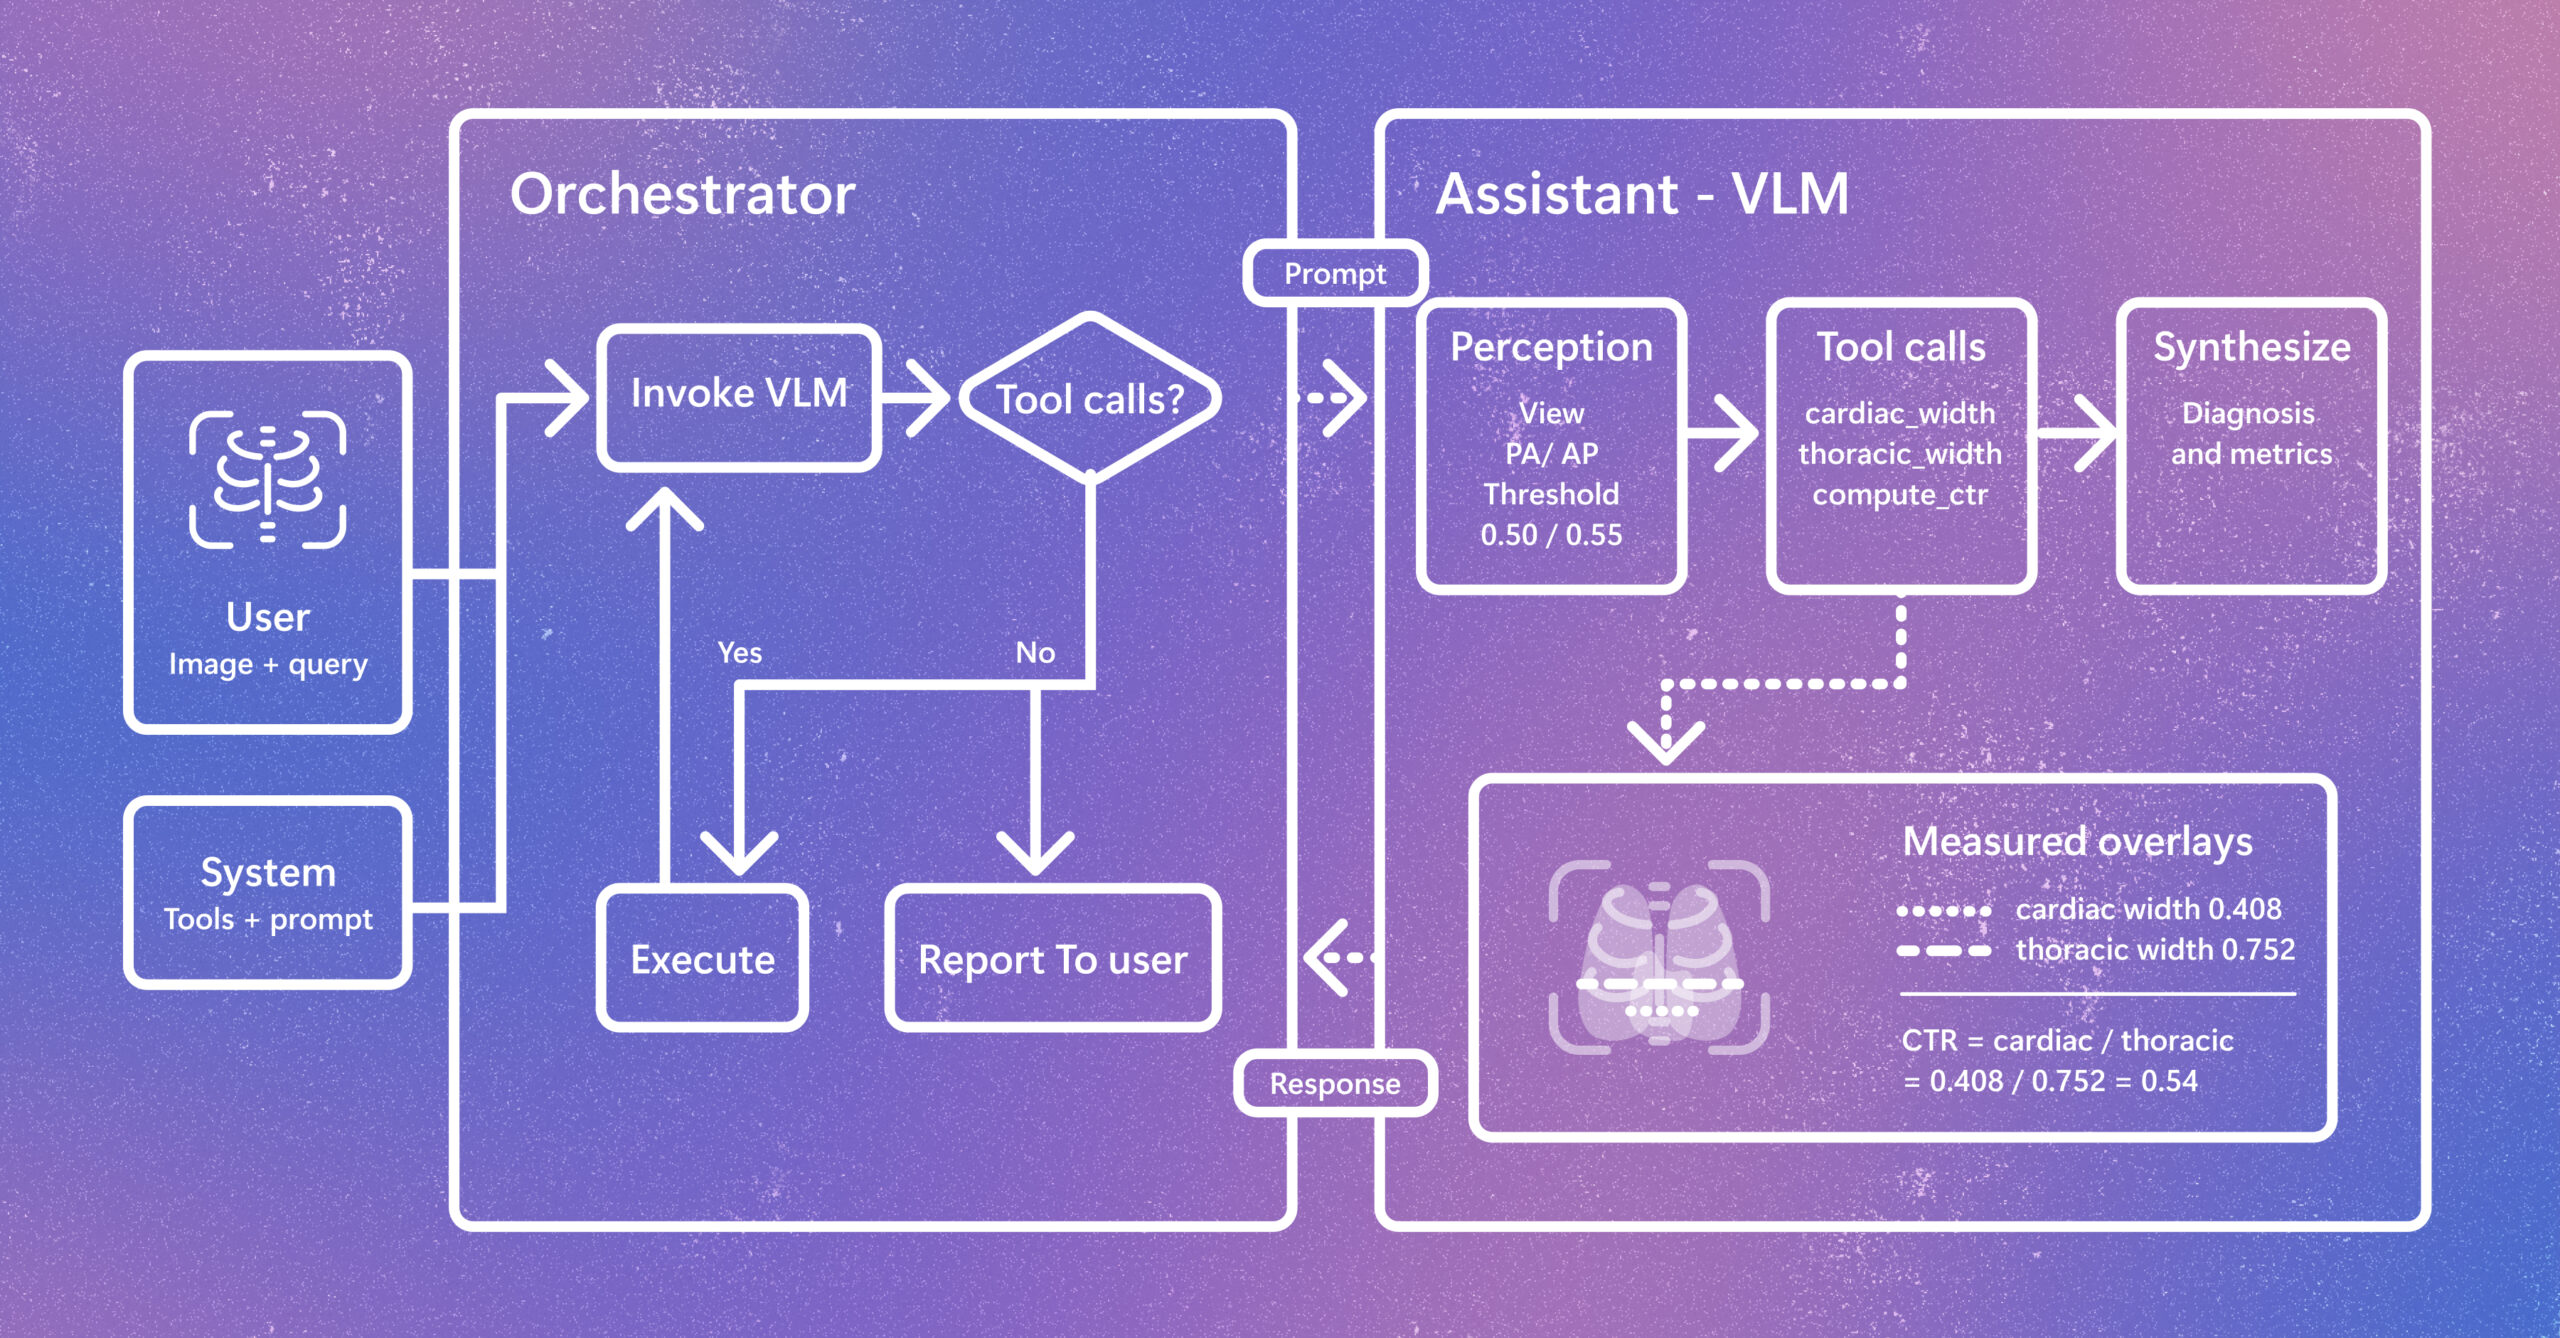
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 7, 2026

Discovering the value of humanistic inquiry

Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.
