Skip to content
#machine learning #computer vision Preprint Open access

ORCA: Hunting Compositional Failures in Text-to-Image Diffusion

Arshia Hemmat Amirhossein Vahidi Amitis Shidani Mohammad Vali Sanian Hesam Asadollahzadeh Aryan Yazdan Parast Mohammad Lotfollahi
Oct 2026
Machine Learning Computer Vision

Abstract

Text-to-image diffusion models fail predictably on compositional prompts: attributes bind to the wrong objects, spatial relations invert, and multi-object scenes lose count. Recent architectures already augment CLIP with a T5 encoder precisely because CLIP's contrastive embedding loses compositional structure, yet these failures persist. We argue the binding problem is therefore not one of missing information but of misaligned information: a text encoder preserves compositional structure, but in a representation space shaped by language modelling rather than vision, and the denoising objective does not directly reward aligning the two. We show this correspondence can be supplied as an explicit training signal, that the relevant cross-modal information is concentrated in a low-rank subspace of self-supervised visual features, and that supplying it can be folded into diffusion training as a single auxiliary loss. Our method, ORCA (Orthogonal Residual Compositional Alignment), aligns the latent of a diffusion transformer with a low-rank target derived from a frozen visual encoder, through a predictor whose orthogonal basis is parameterised by a learned residual between T5 and CLIP embeddings, which provides a prompt-dependent signal for selecting the visual readout subspace. We prove that the cross-modal information recoverable at a given rank is bounded by the spectral mass of the visual encoder's covariance in the top components. Across three diffusion-transformer backbones (DiT-B/2, DiT-L/2, U-ViT-L), ORCA improves FID and GenEval over both vanilla and REPA baselines at zero inference-time cost; on DiT-L/2 it reaches FID 16.65 and GenEval 0.291 at 200K steps, exceeding the strongest 400K baseline at half the training cost, with the largest gains concentrated on attribute binding, spatial relations, and multi-object prompts.

View source

Similar papers

#computer vision Review Sep 2017

Agile Software Development Methods: Review and Analysis

This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.

P. Abrahamsson, O. Salo, Jussi Ronkainen et al. · 727 citations · ⚡54
#computer vision Jun 2008

The impact of agile practices on communication in software development

The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.

M. Pikkarainen, Jukka Haikara, O. Salo et al. · 401 citations · ⚡48
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60

Related blog posts

Microsoft Research Blog Aug 11, 2026

Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

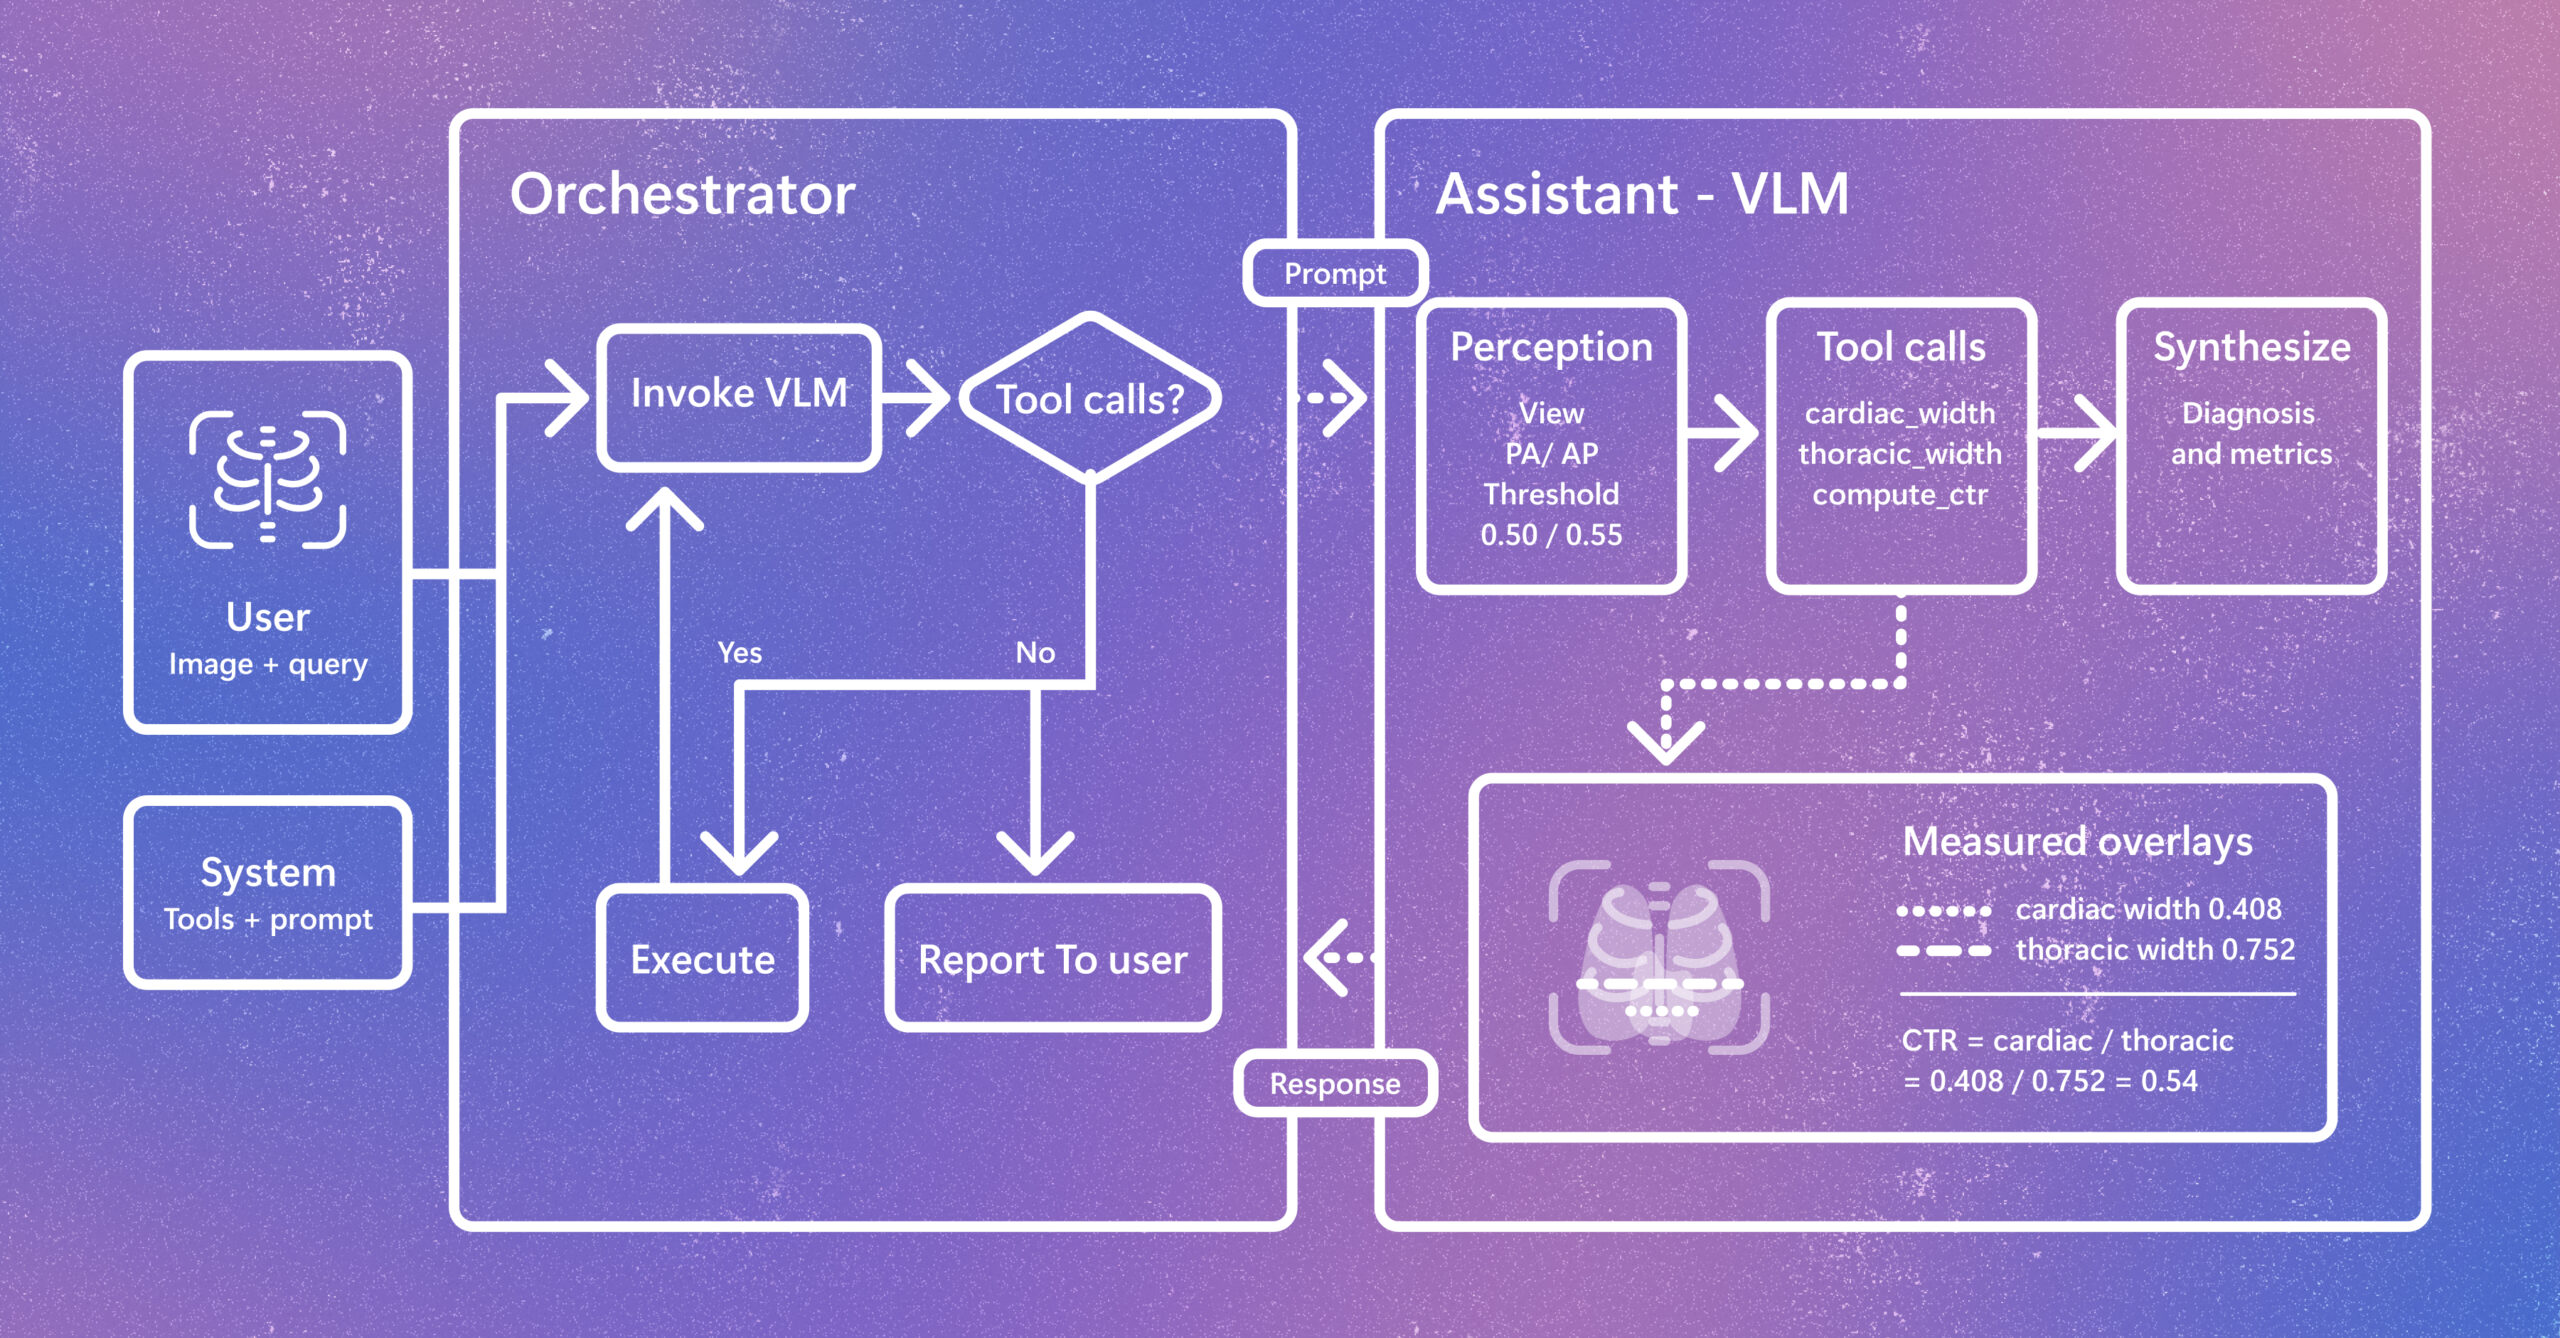
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 7, 2026

Discovering the value of humanistic inquiry

Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.
